
#Mixture-of-Experts
4 posts
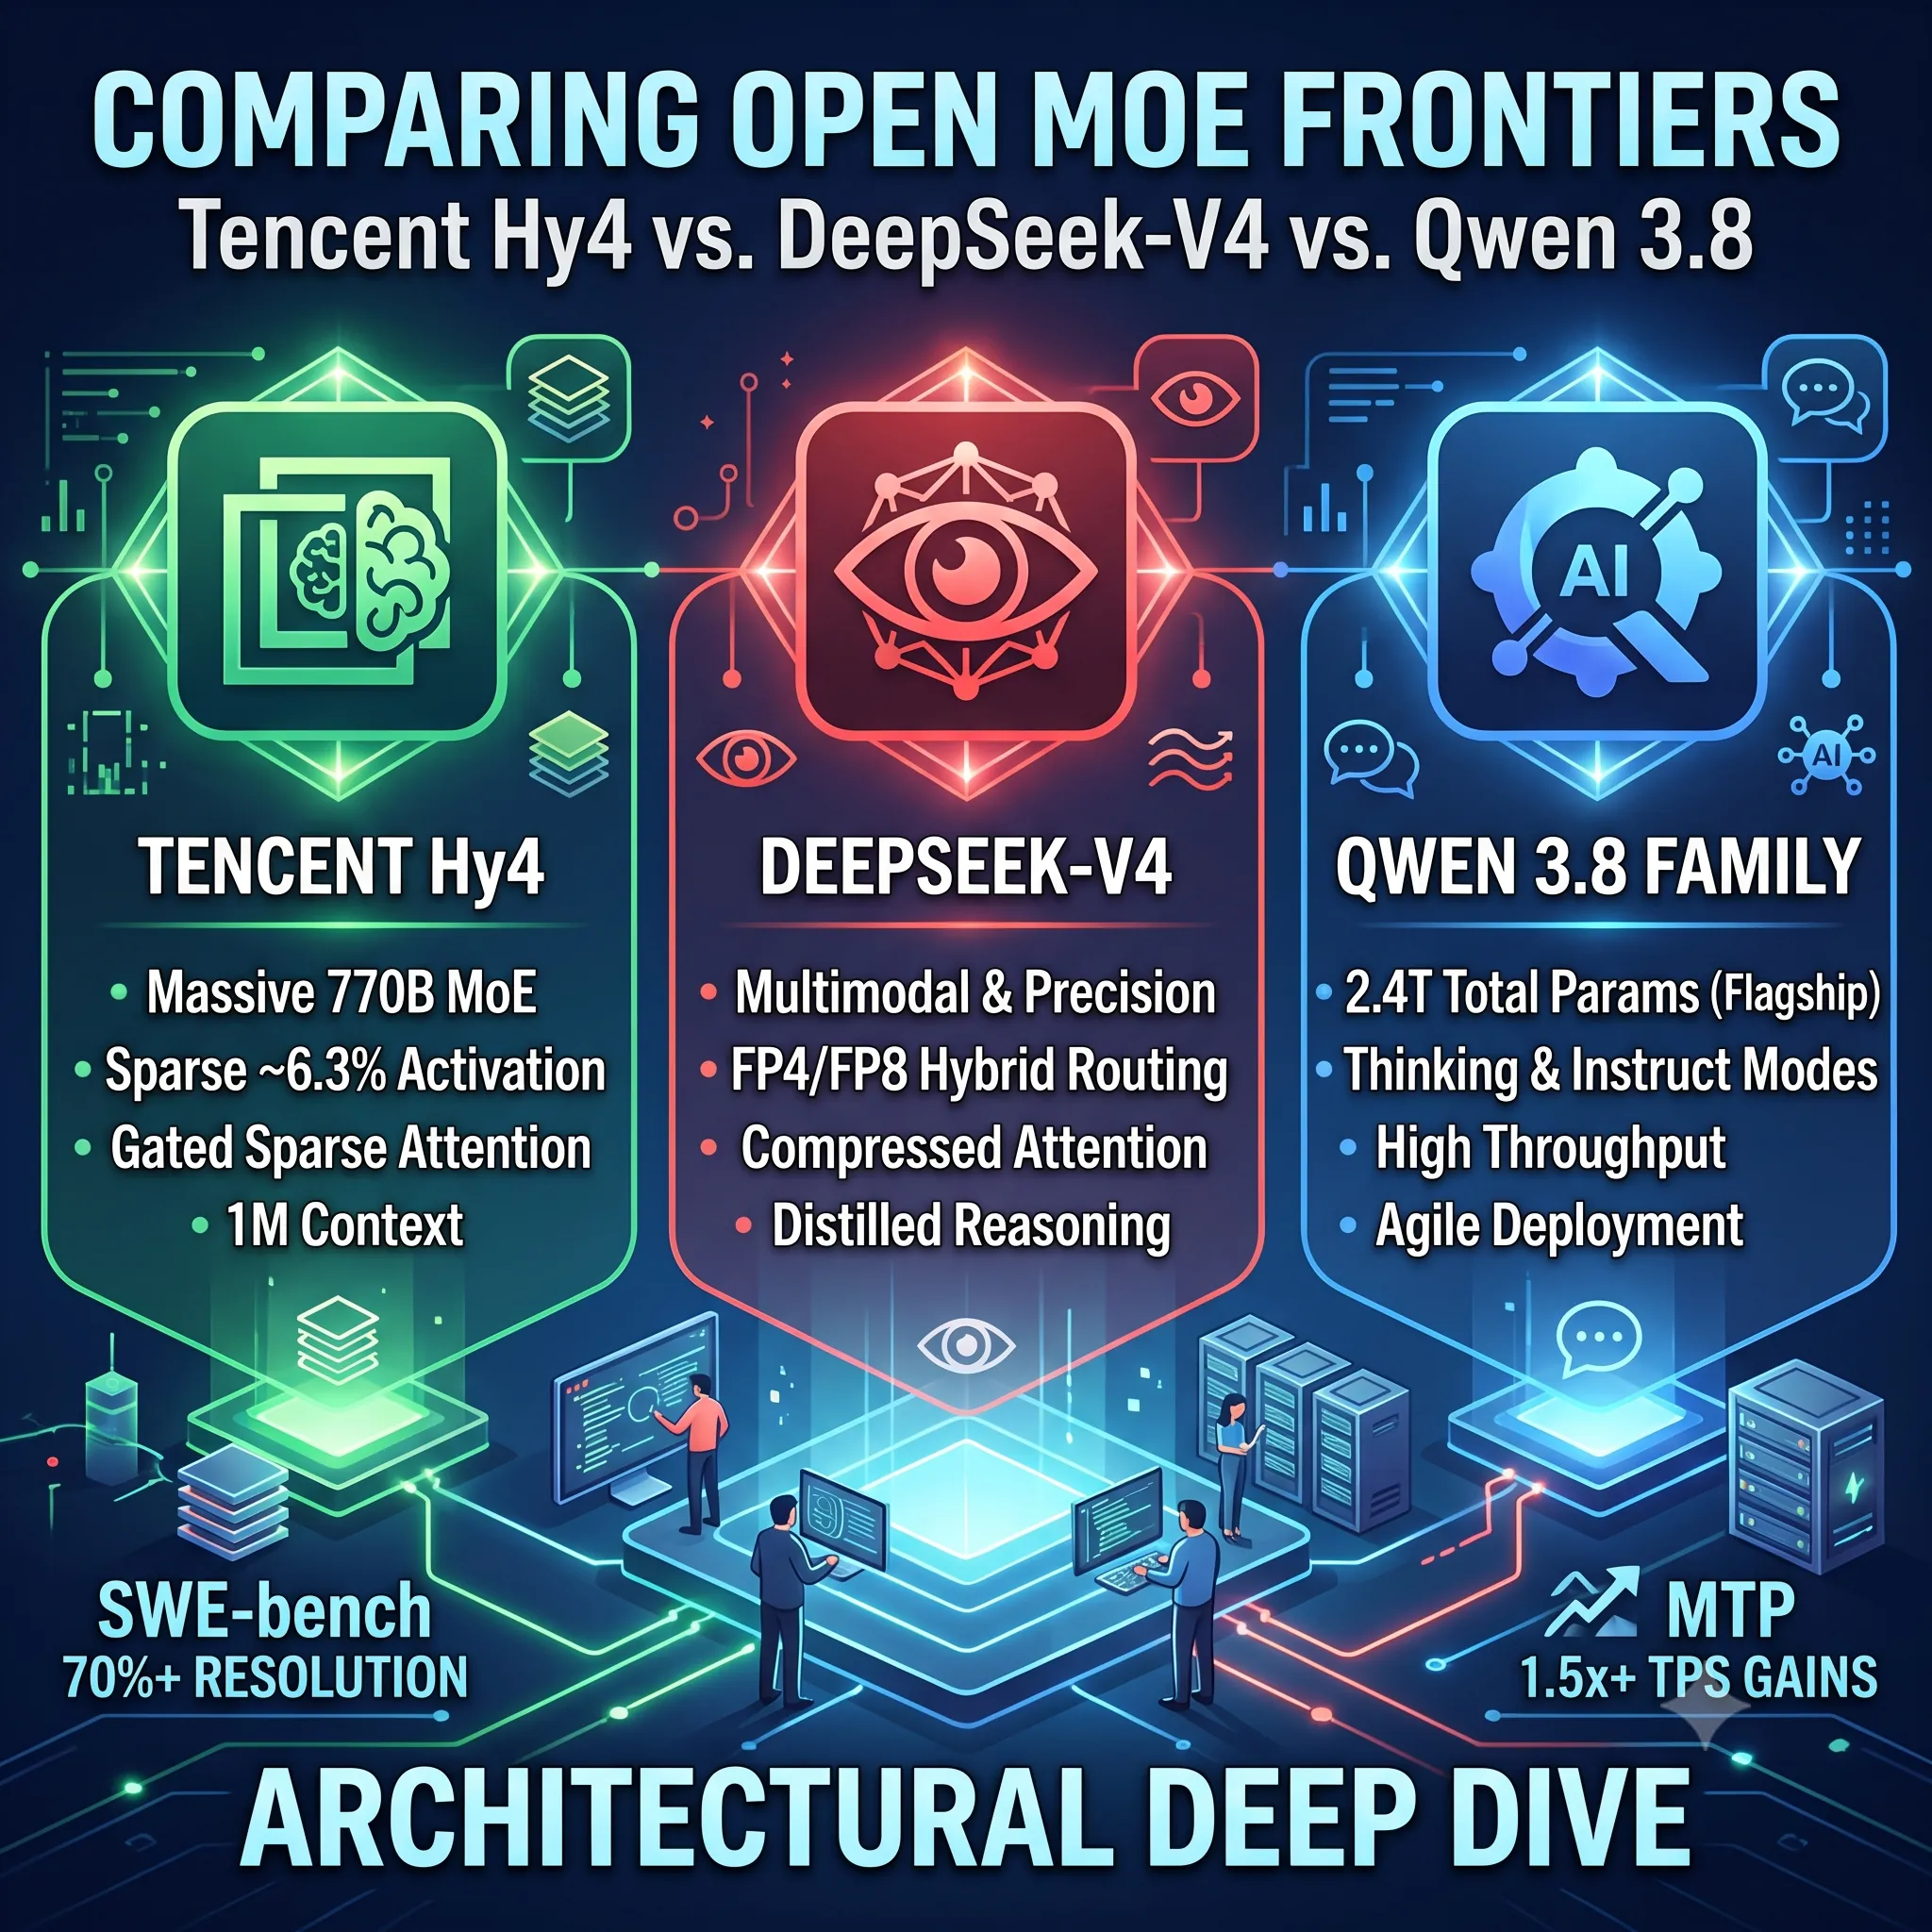
Comparative Analysis: Architectural Foundations of Tencent Hy4, DeepSeek-V4, and Qwen 3.8 MoE Models
A deep dive into the architectural foundations, sparse activation strategies, and performance benchmarks of Tencent Hy4, DeepSeek-V4, and Qwen 3.8 MoE models.
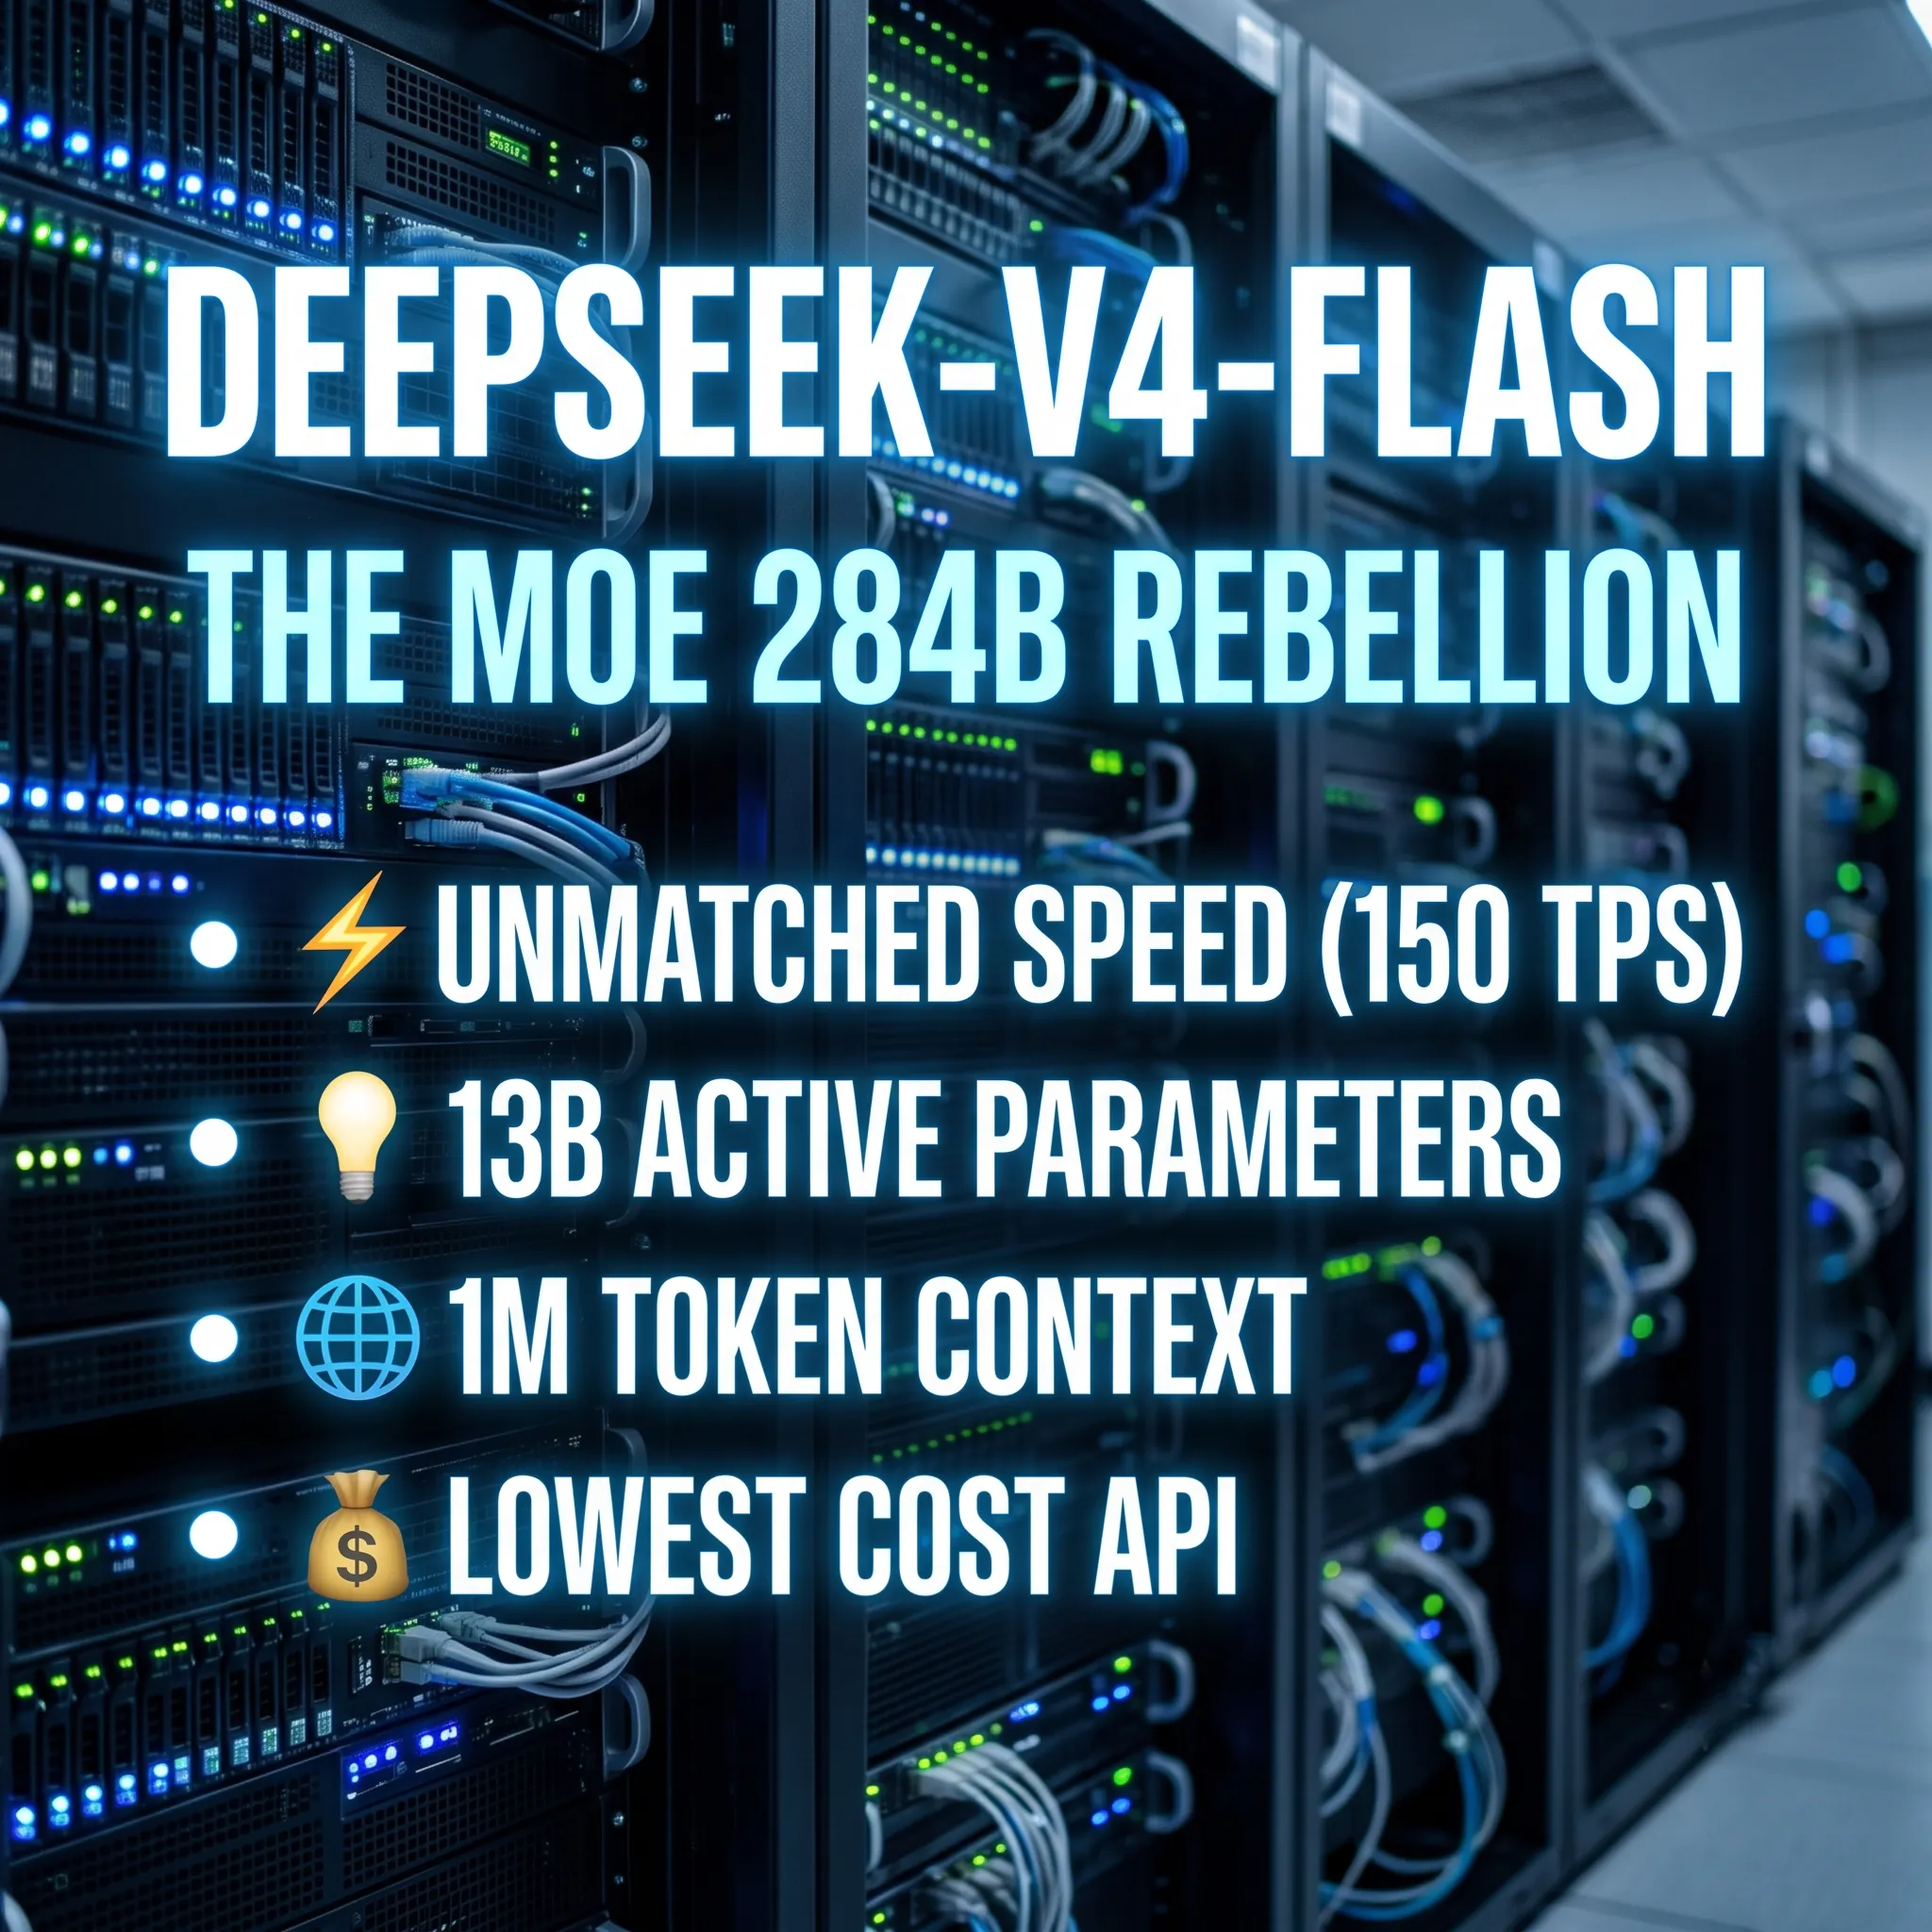
DeepSeek-V4-Flash: Revolutionizing AI with 284B MoE, 1M Context & Unprecedented Efficiency on DeepInfra
DeepSeek-V4-Flash: The 284B MoE LLM revolutionizing AI with 1M context, extreme efficiency, speed, and competitive DeepInfra pricing.
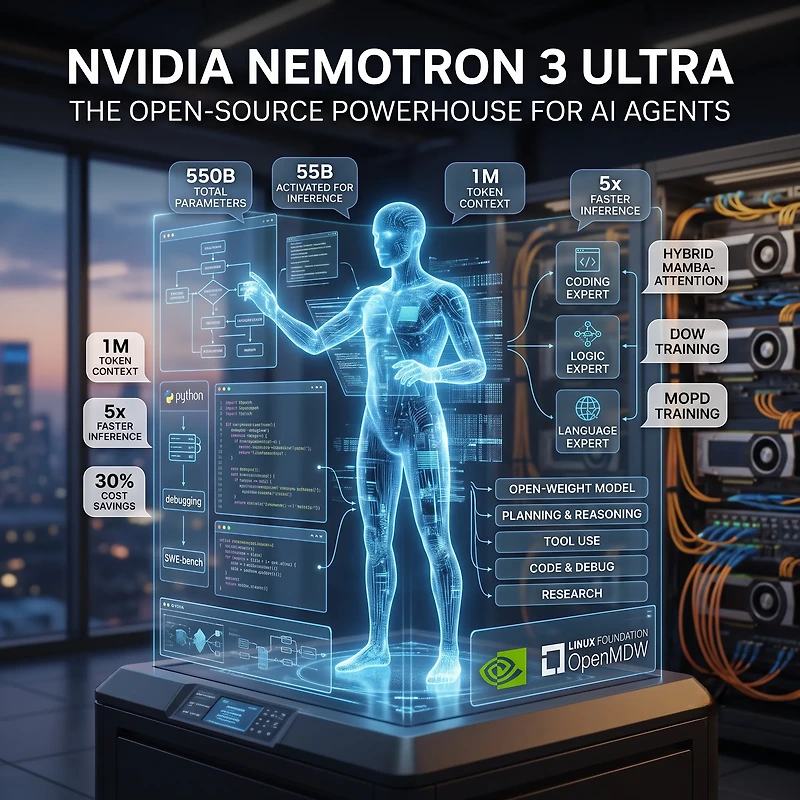
NVIDIA Nemotron 3 Ultra: Open-Source LLM Empowers Next-Gen AI Agents with 5x Faster Inference & Advanced Reasoning
NVIDIA Nemotron 3 Ultra is a new open-source, open-weight Mixture-of-Experts (MoE) model designed for AI agents to perform complex, long-duration tasks. It...
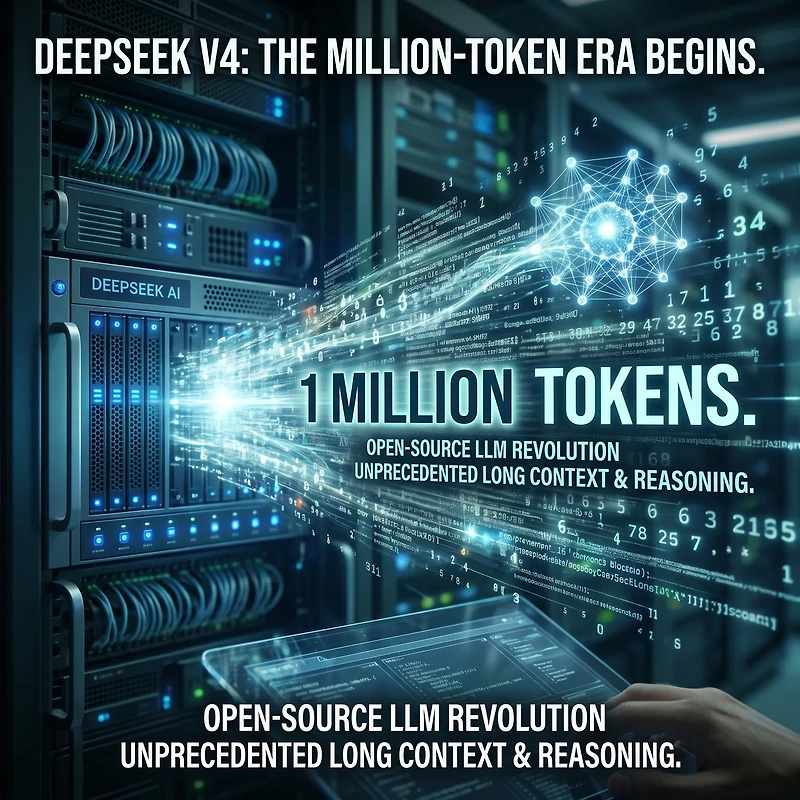
DeepSeek V4 Pro & Flash: Unveiling the 1 Million Token Era – Architecture, Efficiency, and Real-World Performance Nuances
DeepSeek-V4 revolutionizes the AI landscape by officially launching its open-source V4-Pro and V4-Flash models, spearheading the "1 Million Token Era" with...