
DeepSeek-V4-Flash: Revolutionizing AI with 284B MoE, 1M Context & Unprecedented Efficiency on DeepInfra
🚀 Key Takeaways
- DeepSeek-V4-Flash is an efficiency-focused Mixture-of-Experts (MoE) model designed for fast inference and high-throughput use cases.
- It features a sparse MoE design, balancing a large total parameter count with highly efficient active parameters per token.
- The DeepSeek-V4 series, including Flash, supports an industry-leading one million token context length.
- DeepSeek-V4-Flash delivers exceptional speed, achieving 100 to 150 Tokens Per Second (TPS) in real-world scenarios.
- Despite its focus on speed and efficiency, DeepSeek-V4-Flash maintains strong performance on complex reasoning and coding tasks.
- The model incorporates advanced architectural and optimization upgrades like a Hybrid Attention Architecture and the Muon optimizer.
- DeepSeek-V4-Flash offers a highly competitive price-performance ratio, disrupting the market for high-capability, cost-effective LLMs.
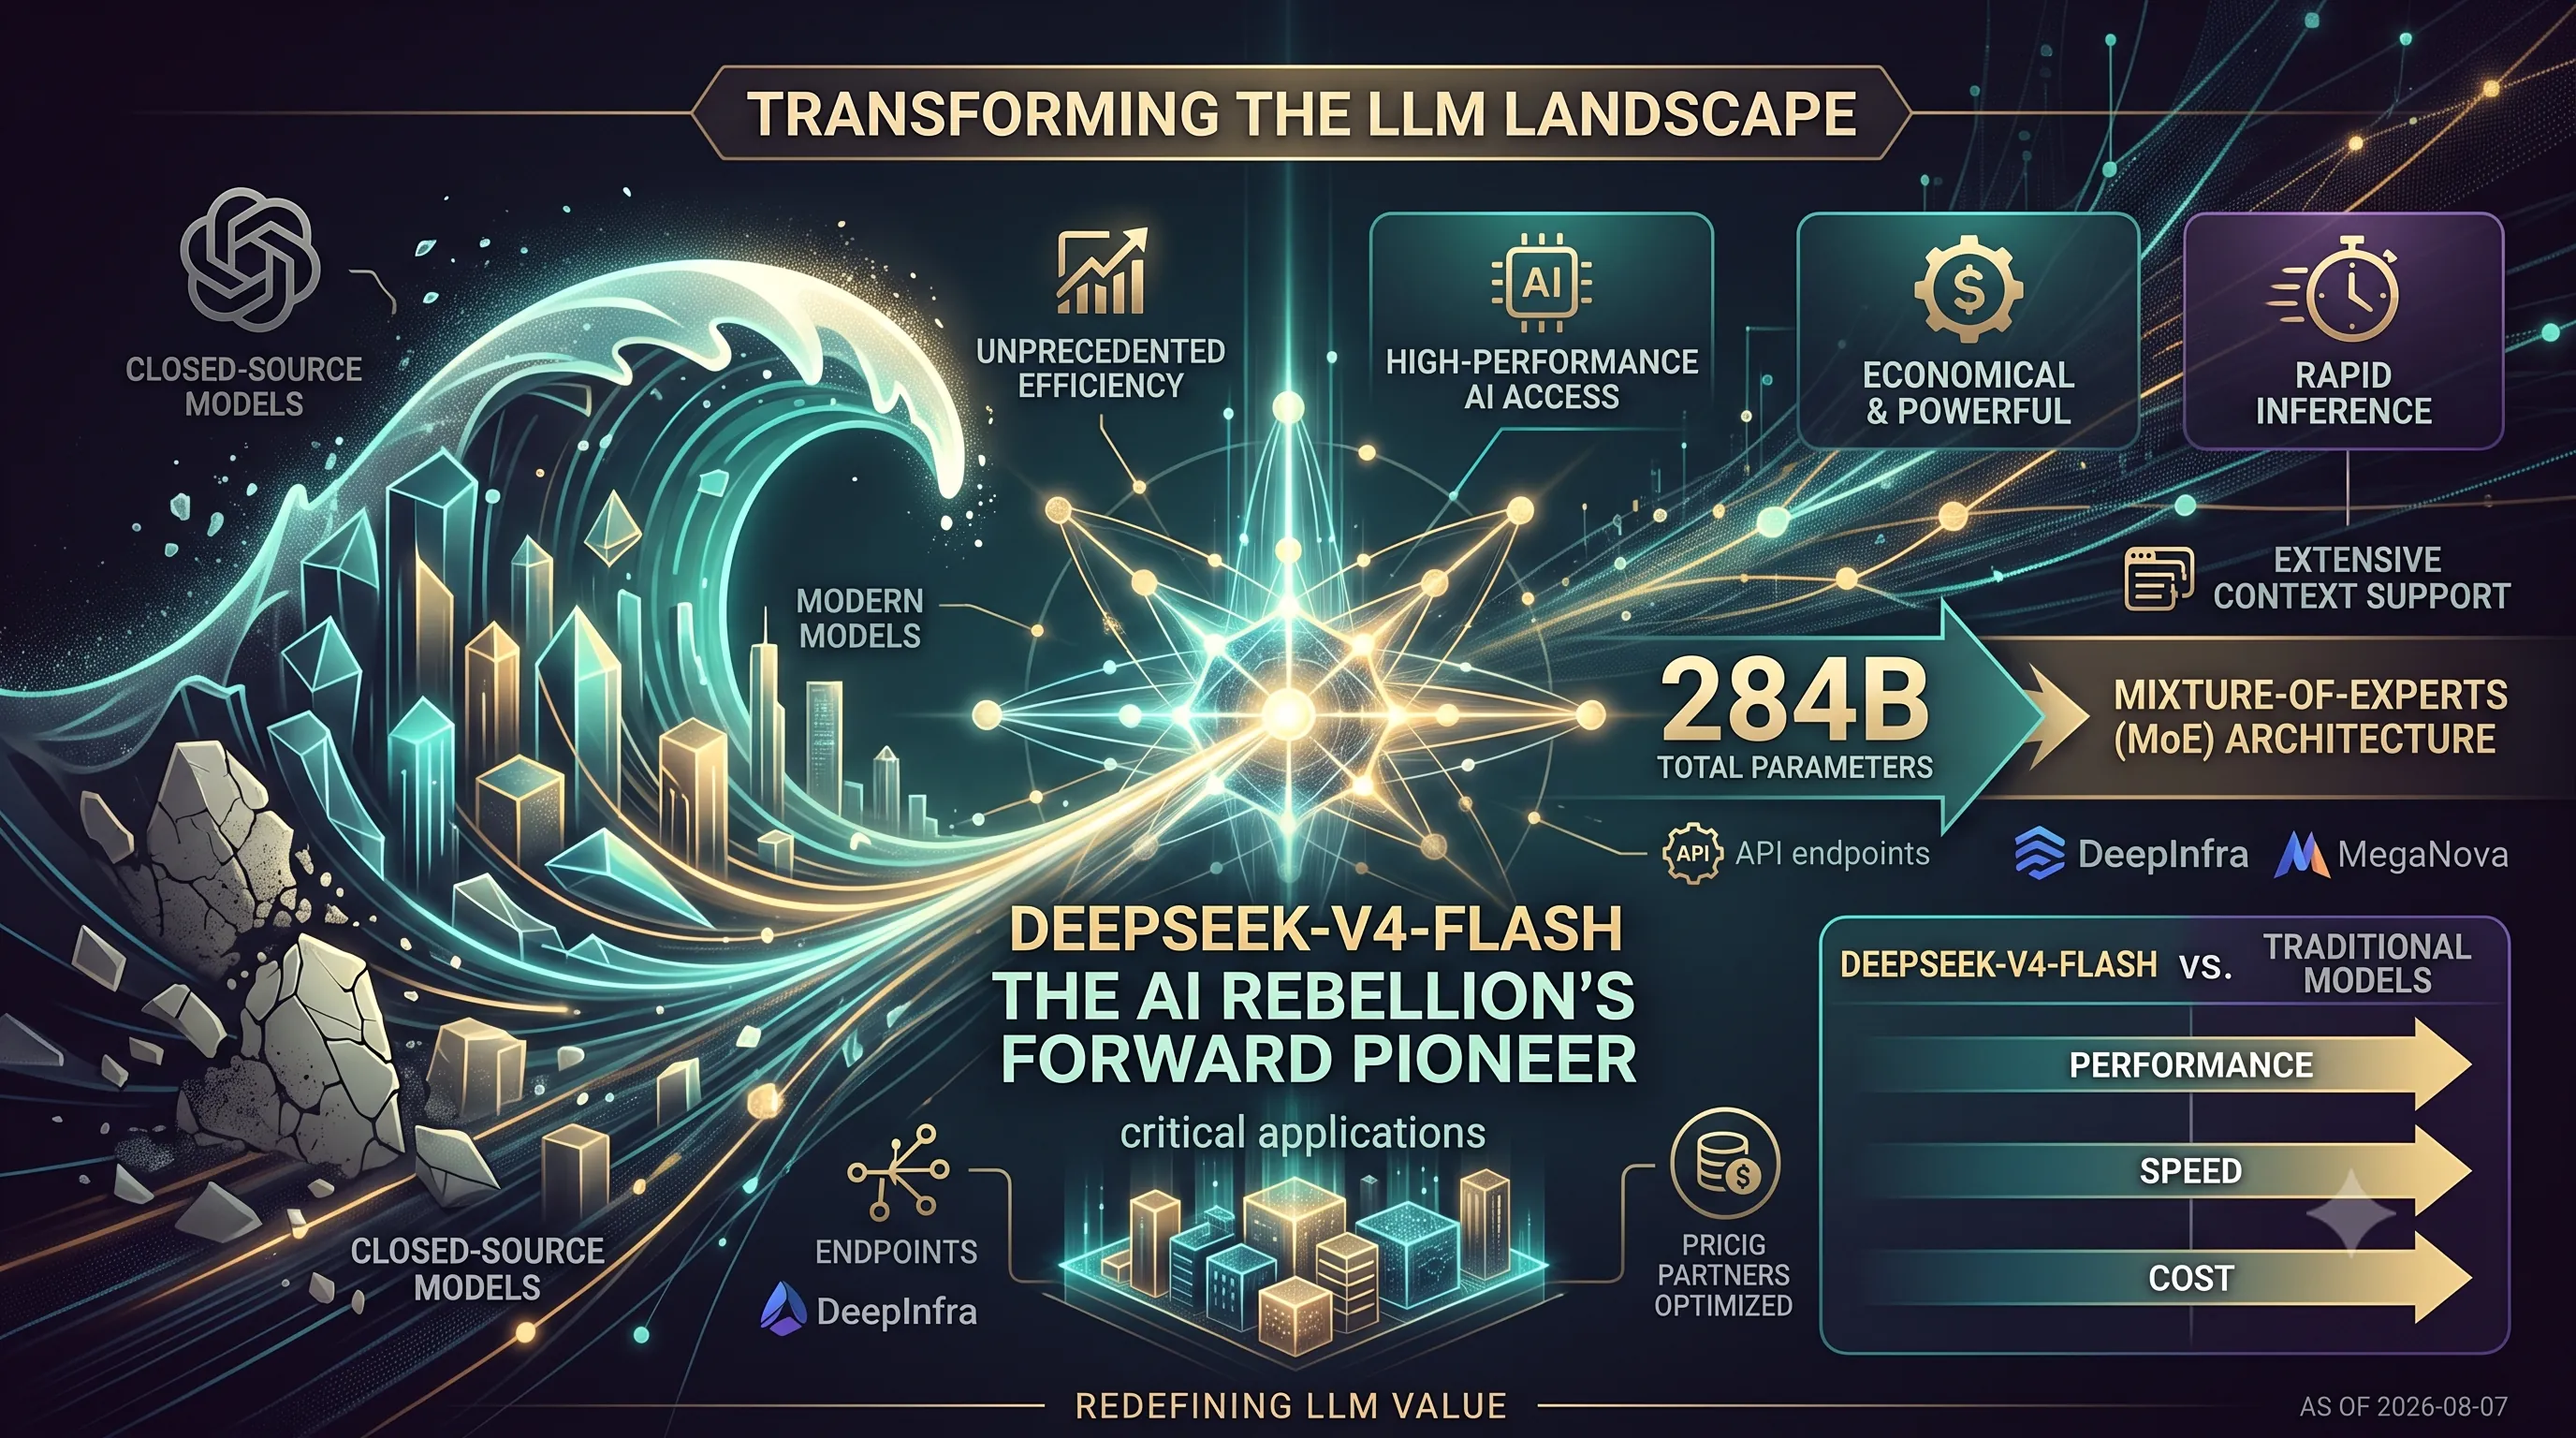
The landscape of large language models is undergoing a significant transformation, and at the forefront of this "rebellion" is DeepSeek-V4-Flash. This innovative model, with its 284B total parameters, is not just another addition to the rapidly expanding AI toolkit; it represents a strategic shift towards combining immense capability with unprecedented efficiency. Its emergence signals a new era where high-performance AI is accessible and practical for a broader range of applications.
DeepSeek-V4-Flash has quickly become a pivotal player, particularly for enterprises and developers seeking powerful yet economical solutions. Built upon a sophisticated Mixture-of-Experts (MoE) architecture and optimized for rapid inference, it challenges the traditional trade-offs between model size, speed, and cost. This model's ability to handle extensive contexts while delivering lightning-fast results makes it a game-changer for critical applications.
As of 2026-08-07, DeepSeek-V4-Flash is redefining expectations for what an efficient AI model can achieve. Its robust API support, competitive pricing through platforms like DeepInfra and MegaNova, and benchmark-validated performance position it as a formidable contender in the global AI race, fundamentally altering perspectives on value and performance in the LLM ecosystem.
DeepSeek-V4-Flash has quickly become a pivotal player, particularly for enterprises and developers seeking powerful yet economical solutions. Built upon a sophisticated Mixture-of-Experts (MoE) architecture and optimized for rapid inference, it challenges the traditional trade-offs between model size, speed, and cost. This model's ability to handle extensive contexts while delivering lightning-fast results makes it a game-changer for critical applications.
As of 2026-08-07, DeepSeek-V4-Flash is redefining expectations for what an efficient AI model can achieve. Its robust API support, competitive pricing through platforms like DeepInfra and MegaNova, and benchmark-validated performance position it as a formidable contender in the global AI race, fundamentally altering perspectives on value and performance in the LLM ecosystem.
1. DeepInfra's Infrastructure: Powering AI Innovations
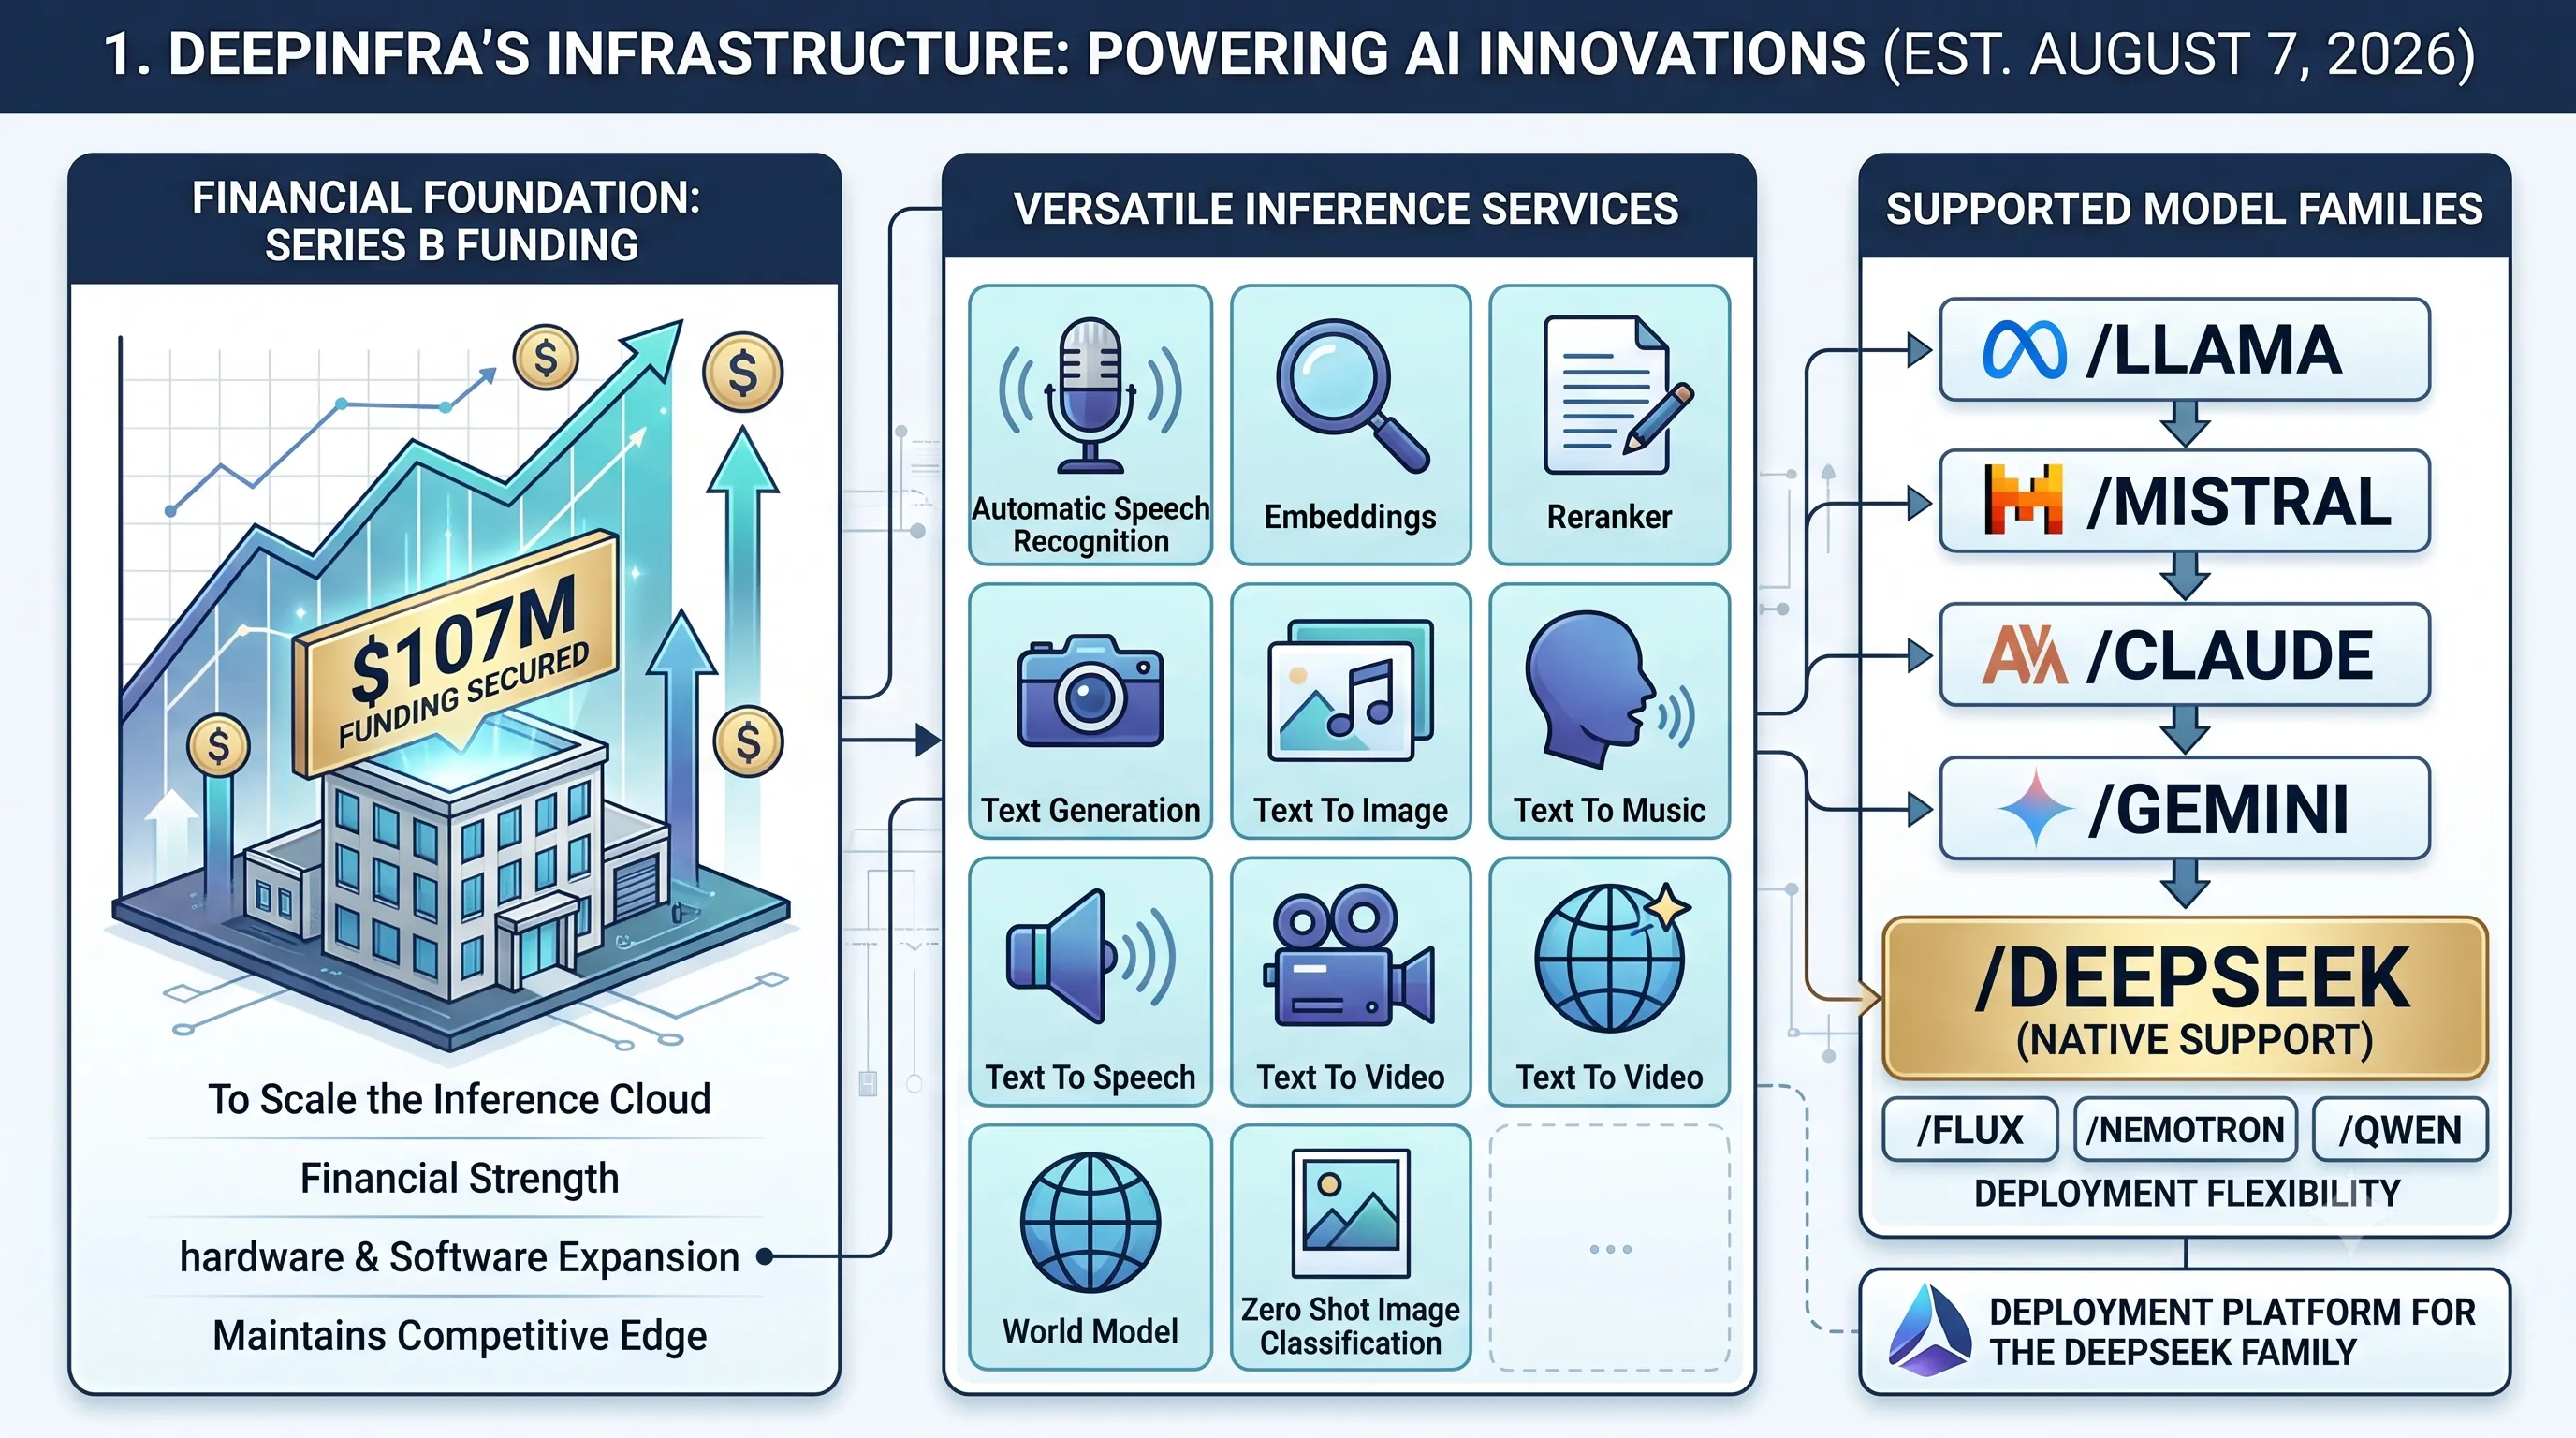
Before diving into the specifics of the DeepSeek-V4-Flash model and its API, it's essential to understand the robust infrastructure that powers its deployment. This section examines DeepInfra, the specialized inference cloud whose financial strength and expansive model offerings provide the foundation for developers to access and scale state-of-the-art models like those from the DeepSeek family.DeepInfra's $107M Funding Round
A significant indicator of DeepInfra's market position and future potential is its successful Series B funding round, which secured $107M.This capital infusion, as highlighted by the company's announcement to "scale the inference cloud," directly supports the expansion and enhancement of the hardware and software systems necessary to serve demanding AI models.
Such financial backing is critical for maintaining a competitive edge in the fast-paced AI infrastructure landscape, ensuring reliability and performance for its users.
Comprehensive AI Model Categories
DeepInfra's platform is not limited to a single modality but offers a wide spectrum of AI capabilities.This versatility allows developers to build complex, multi-faceted applications without needing to integrate multiple specialized providers.
The available service categories demonstrate this breadth, including: Automatic Speech Recognition, Embeddings, Reranker, Text Generation, Text To Image, Text To Music, Text To Speech, Text To Video, World Model, and Zero Shot Image Classification.
This comprehensive suite makes it a one-stop shop for a diverse range of AI inference tasks.
Supported Language Model Families
Central to its service is the support for a broad array of prominent model families, giving developers the flexibility to choose the best tool for their specific use case.The platform hosts models from industry-leading developers, ensuring access to the latest advancements.
Supported families include major players such as /Llama, /Mistral, /Claude, and /Gemini.
Crucially for this article's focus, DeepInfra provides native support for the /DeepSeek family, alongside other powerful models like /Flux, /Nemotron, and /Qwen, positioning it as a key deployment platform for the models under discussion.
2. The DeepSeek-V4 Series: Introducing Next-Gen MoE Language Models
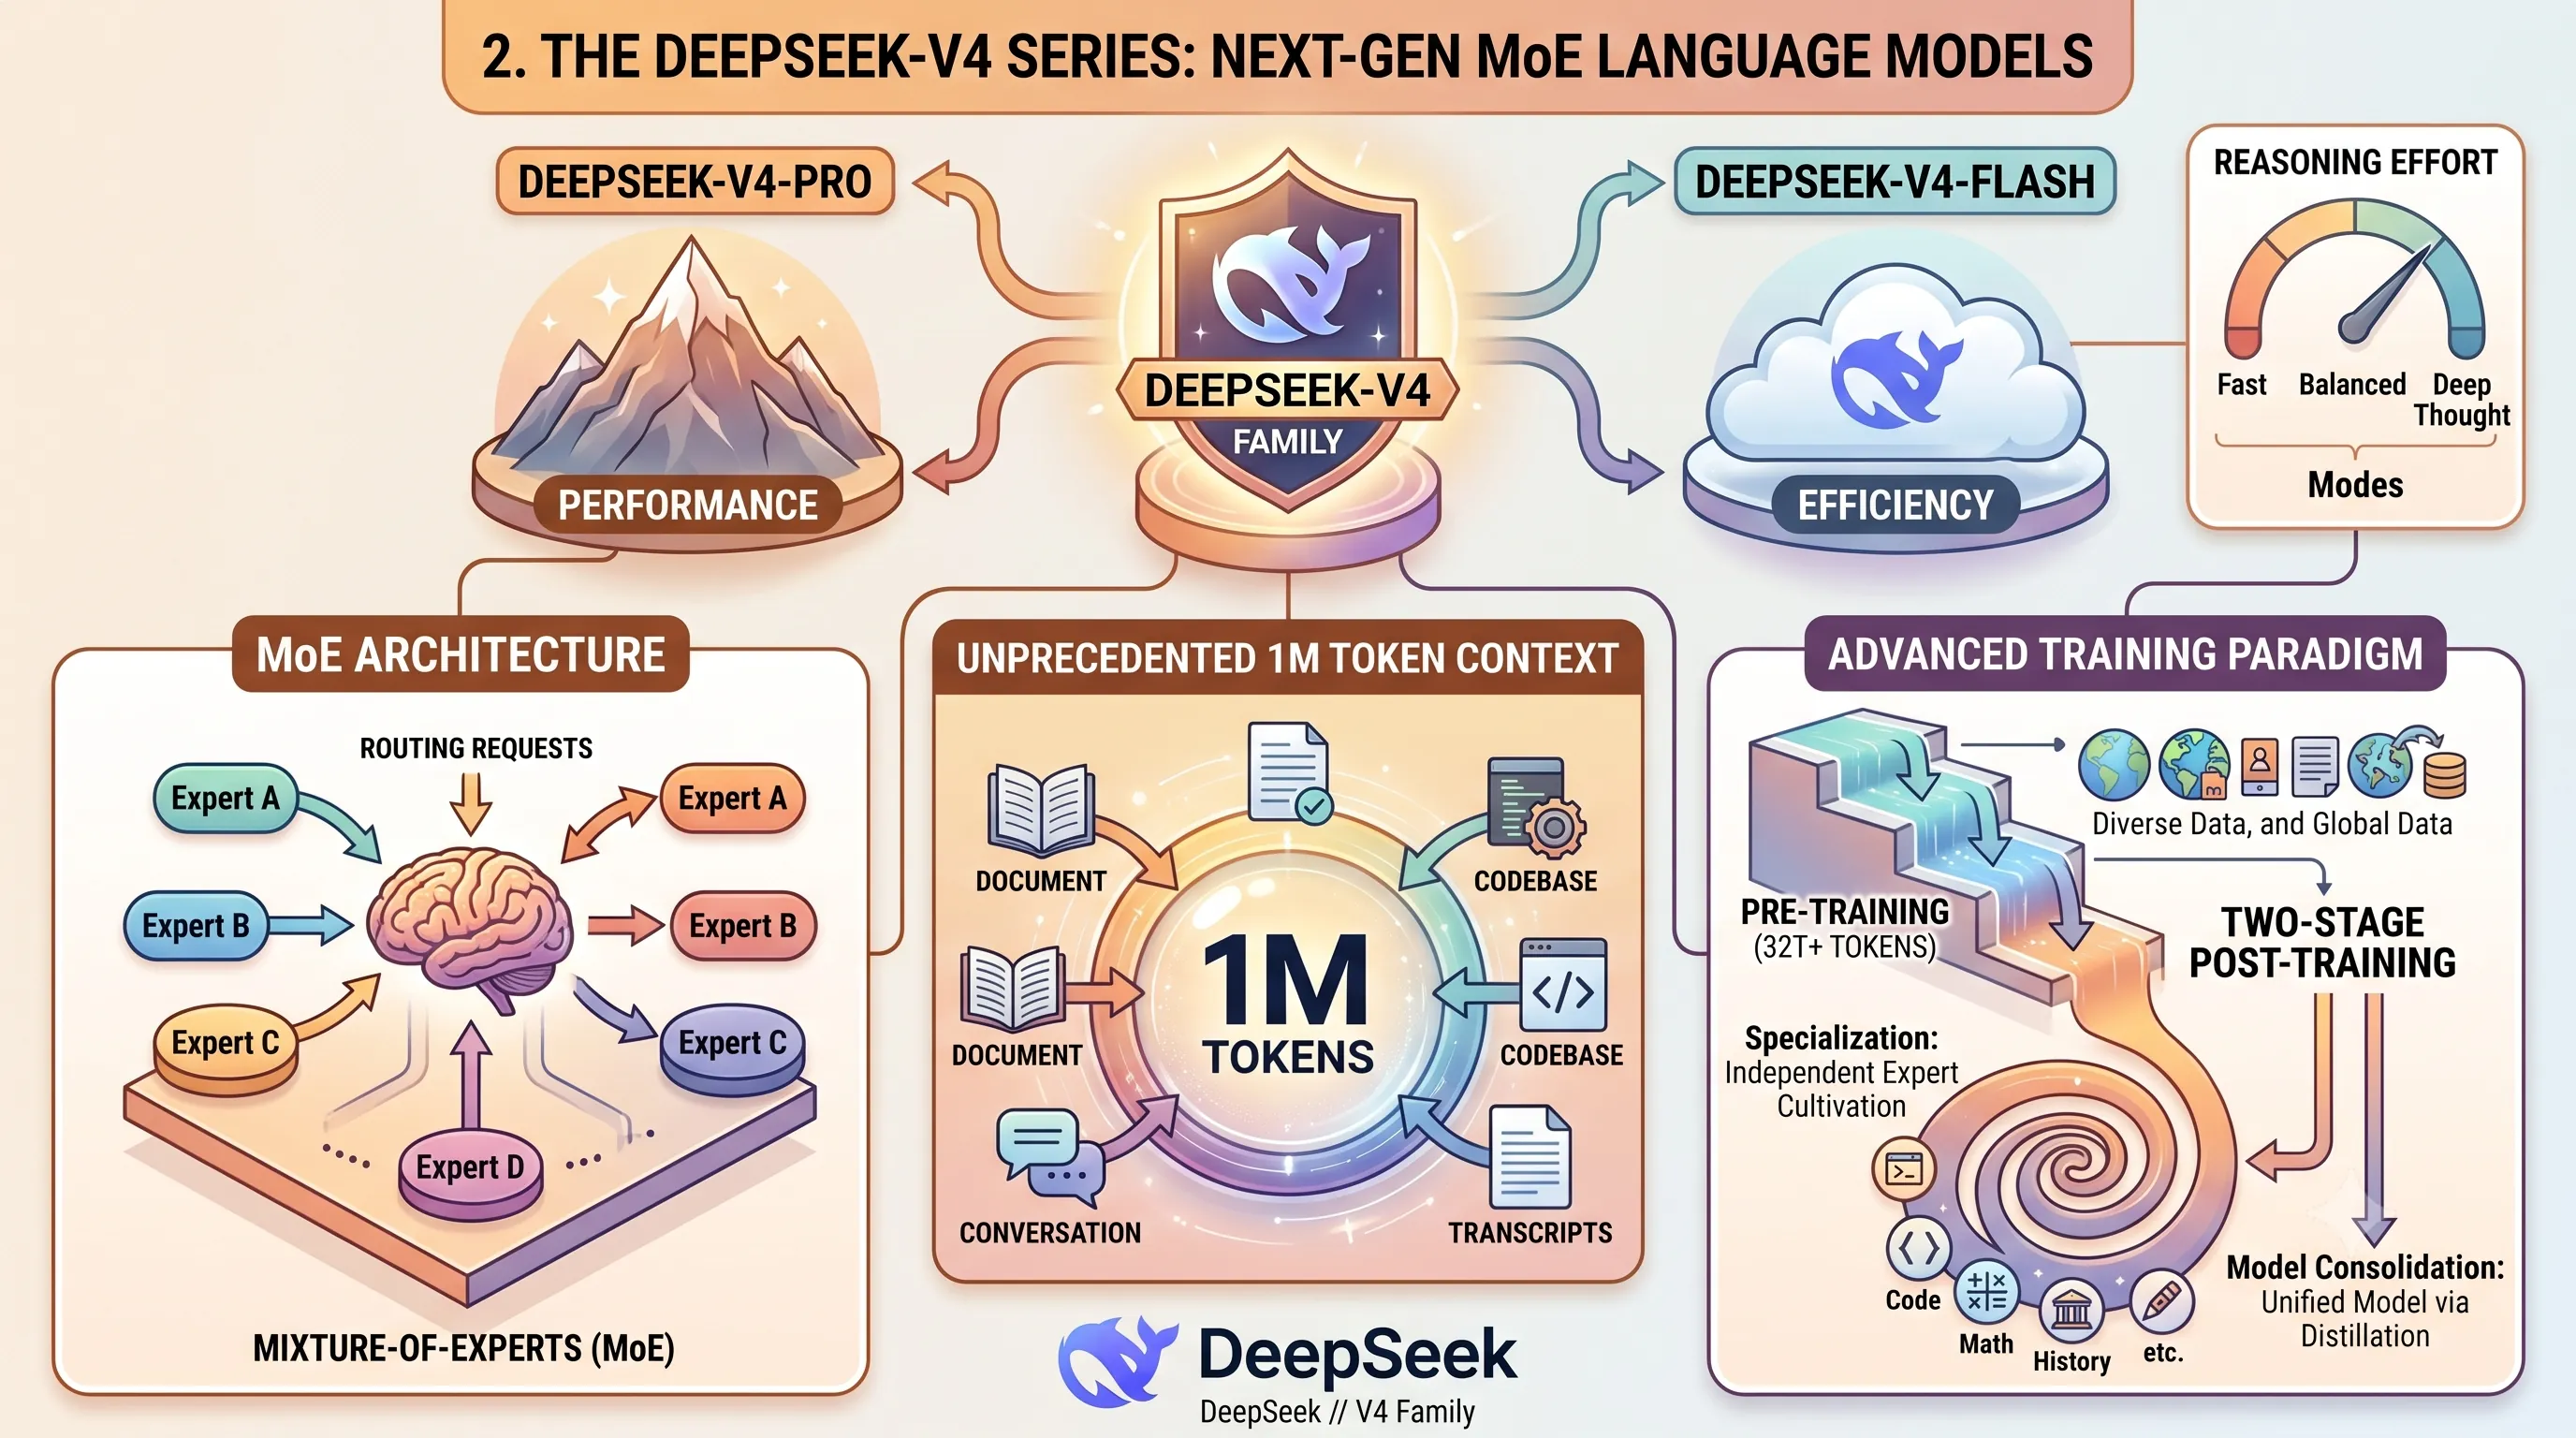
This section provides a foundational overview of the entire DeepSeek-V4 family, detailing the shared architectural innovations and training methodologies that underpin the entire series.Understanding these core principles is essential context for the main article's specific focus on the DeepSeek-V4-Flash model and its API integration.
Dual MoE Models: Pro and Flash
The DeepSeek-V4 series is built upon a Mixture-of-Experts (MoE) architecture, introducing two distinct models to serve different needs: DeepSeek-V4-Pro and DeepSeek-V4-Flash.This dual-model approach allows users to choose between different points on the performance-efficiency spectrum.
The entire series benefits from significant architectural and optimization upgrades, representing a notable advancement in language model design.
Unprecedented 1M Token Context
A standout feature across the entire series is the universal support for an exceptionally large context window.Both DeepSeek-V4-Pro and DeepSeek-V4-Flash support a context length of one million tokens.
This massive context capacity enables the models to process and reason over extensive documents, codebases, or conversation histories in a single pass, unlocking new potential for complex, long-form tasks.
Advanced Pre-training and Post-training Paradigm
The capabilities of the DeepSeek-V4 series are rooted in a sophisticated training regimen.The models were pre-trained on a vast and carefully curated dataset of more than 32T diverse and high-quality tokens.
Following this, a comprehensive two-stage post-training pipeline was implemented to further refine their abilities.
This advanced paradigm first involves the independent cultivation of domain-specific experts, allowing for deep specialization in various fields.
Subsequently, the process employs unified model consolidation via on-policy distillation, integrating these specialized skills into a cohesive and powerful final model.
Multiple Reasoning Effort Modes
Flexibility is a key design principle for the series.Both the DeepSeek-V4-Pro and DeepSeek-V4-Flash models support three distinct reasoning effort modes.
This feature provides developers with granular control over the model's computational resource allocation, allowing them to balance performance, cost, and latency based on the specific requirements of their application.
3. DeepSeek-V4-Flash: Unleashing Efficiency and High-Throughput Performance
This section details the core specifications and performance profile of DeepSeek-V4-Flash, providing the technical foundation for understanding its role in the "MoE 284B Rebellion" discussed throughout this article.Core Specifications and Active Parameters
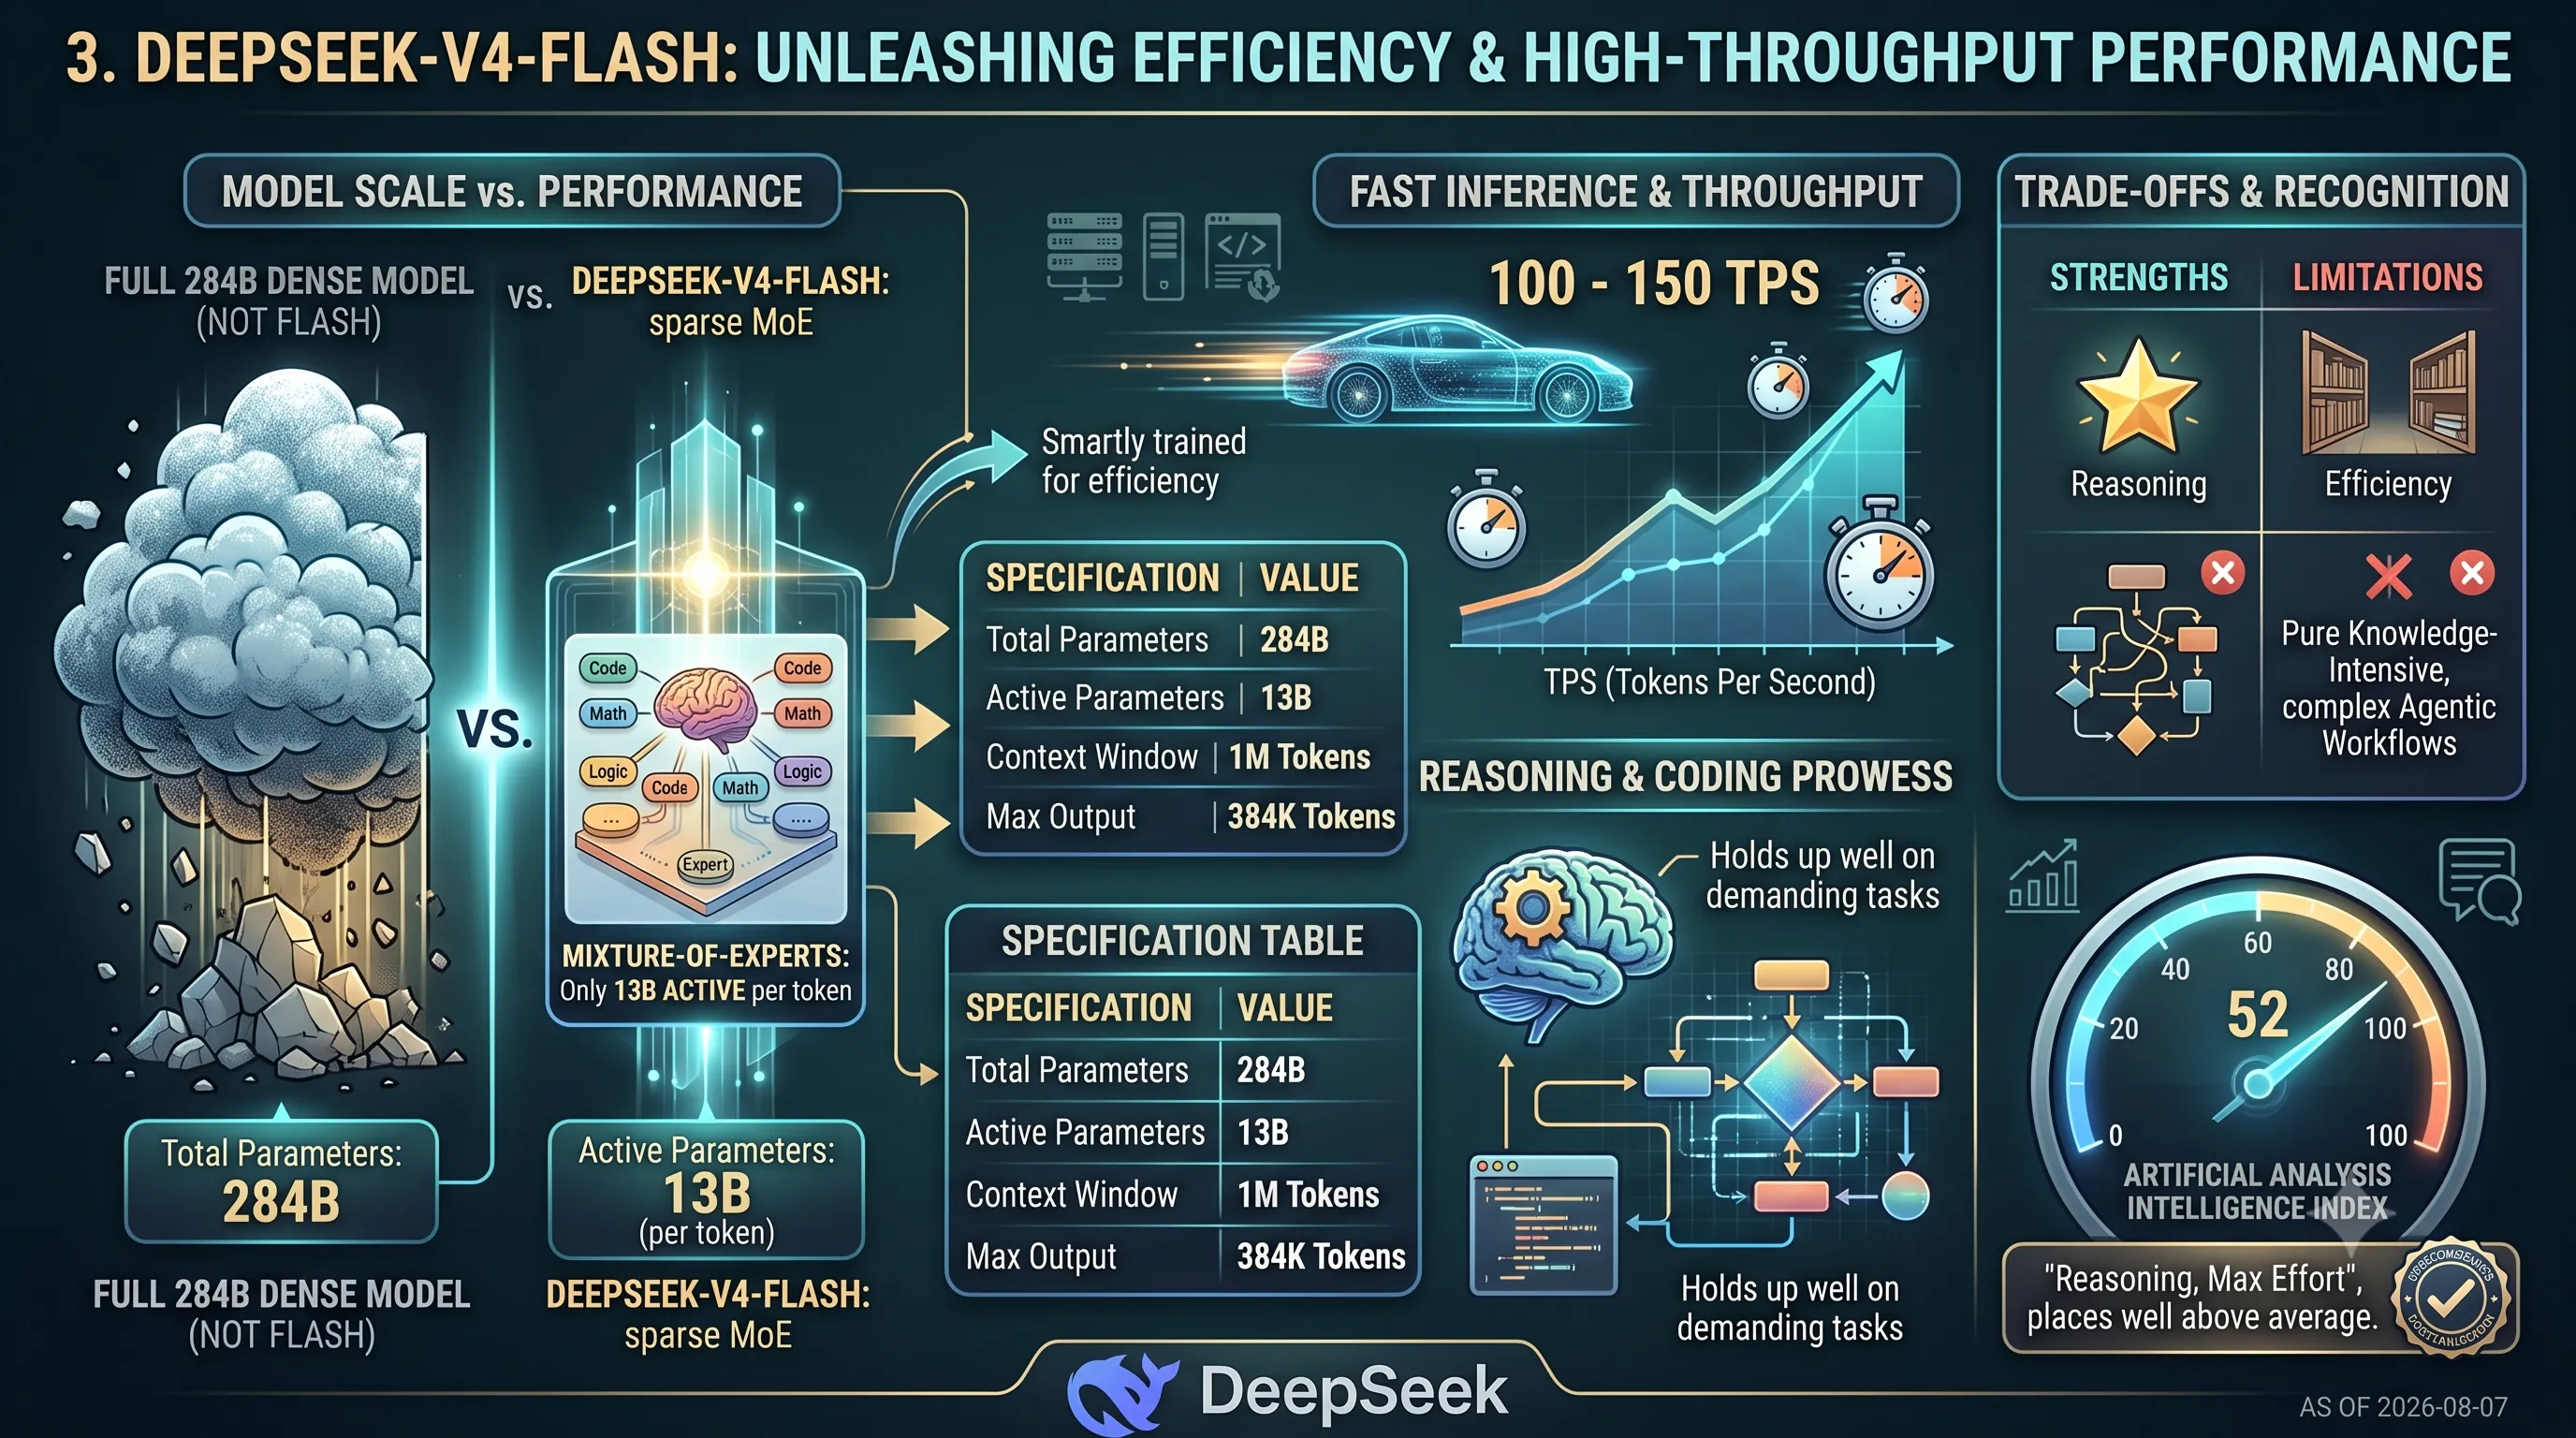
DeepSeek-V4-Flash is an efficiency-focused Mixture-of-Experts (MoE) model built on a sparse architecture.While it boasts an impressive 284B total parameters, its key innovation lies in its operational efficiency.
For any given token, the model activates only 13B parameters, allowing it to deliver performance far beyond what a dense 13B model could achieve while maintaining a fraction of the computational cost of a full 284B model.
As one source noted, "The architecture didn't change. Same 284B parameters, same sparse MoE design with only 13B active per token. They just trained it smarter ...".
This intelligent training is complemented by a massive 1M-token context window and a remarkably large maximum output capacity of 384K tokens, enabling it to handle extensive documents and generate lengthy, coherent responses.
| Specification | Value |
|---|---|
| Total Parameters | 284B |
| Active Parameters (per token) | 13B |
| Context Window | 1M tokens |
| Maximum Output | 384K tokens |
Optimized for Fast Inference and Throughput
As its name implies, DeepSeek-V4-Flash is engineered for speed.It is both smaller and faster than its larger sibling, DeepSeek-V4-Pro, making it ideal for high-throughput use cases where response latency is critical.
The model can achieve remarkable inference speeds of 100 to 150 Tokens Per Second (TPS).
This swift performance has been noted by developers, with one user describing it as, "Crazy fast, 100 to 150 TPS, super good."
Reasoning and Coding Prowess
Despite its focus on speed and efficiency, DeepSeek-V4-Flash maintains strong capabilities in complex domains.The model holds up well on demanding reasoning and coding tasks.
Furthermore, the DeepSeek-V4-Flash-Max variant demonstrates that with a larger "thinking budget," it can achieve reasoning performance comparable to the more resource-intensive Pro version, showcasing the architecture's flexibility.
Limitations in Knowledge-Intensive Tasks
The efficiency of the Flash model comes with certain trade-offs.Due to its smaller active parameter scale, the DeepSeek-V4-Flash-Max variant is slightly behind larger models on tasks that rely on pure, stored knowledge.
Similarly, it can be less effective when deployed in the most complex agentic workflows that require deep, multi-step reasoning across a vast knowledge base.
Artificial Analysis Intelligence Index Score (52)
The model's strong reasoning capabilities are quantified by third-party benchmarks.The "DeepSeek V4 Flash 0731 (Reasoning, Max Effort)" version scored 52 on the Artificial Analysis Intelligence Index.
According to Artificial Analysis, this score "placing it well above average among comparable models," confirming its competitive standing in the market for efficient, high-performance models.
4. DeepSeek-V4-Pro: The Apex of Open-Source Reasoning and Knowledge
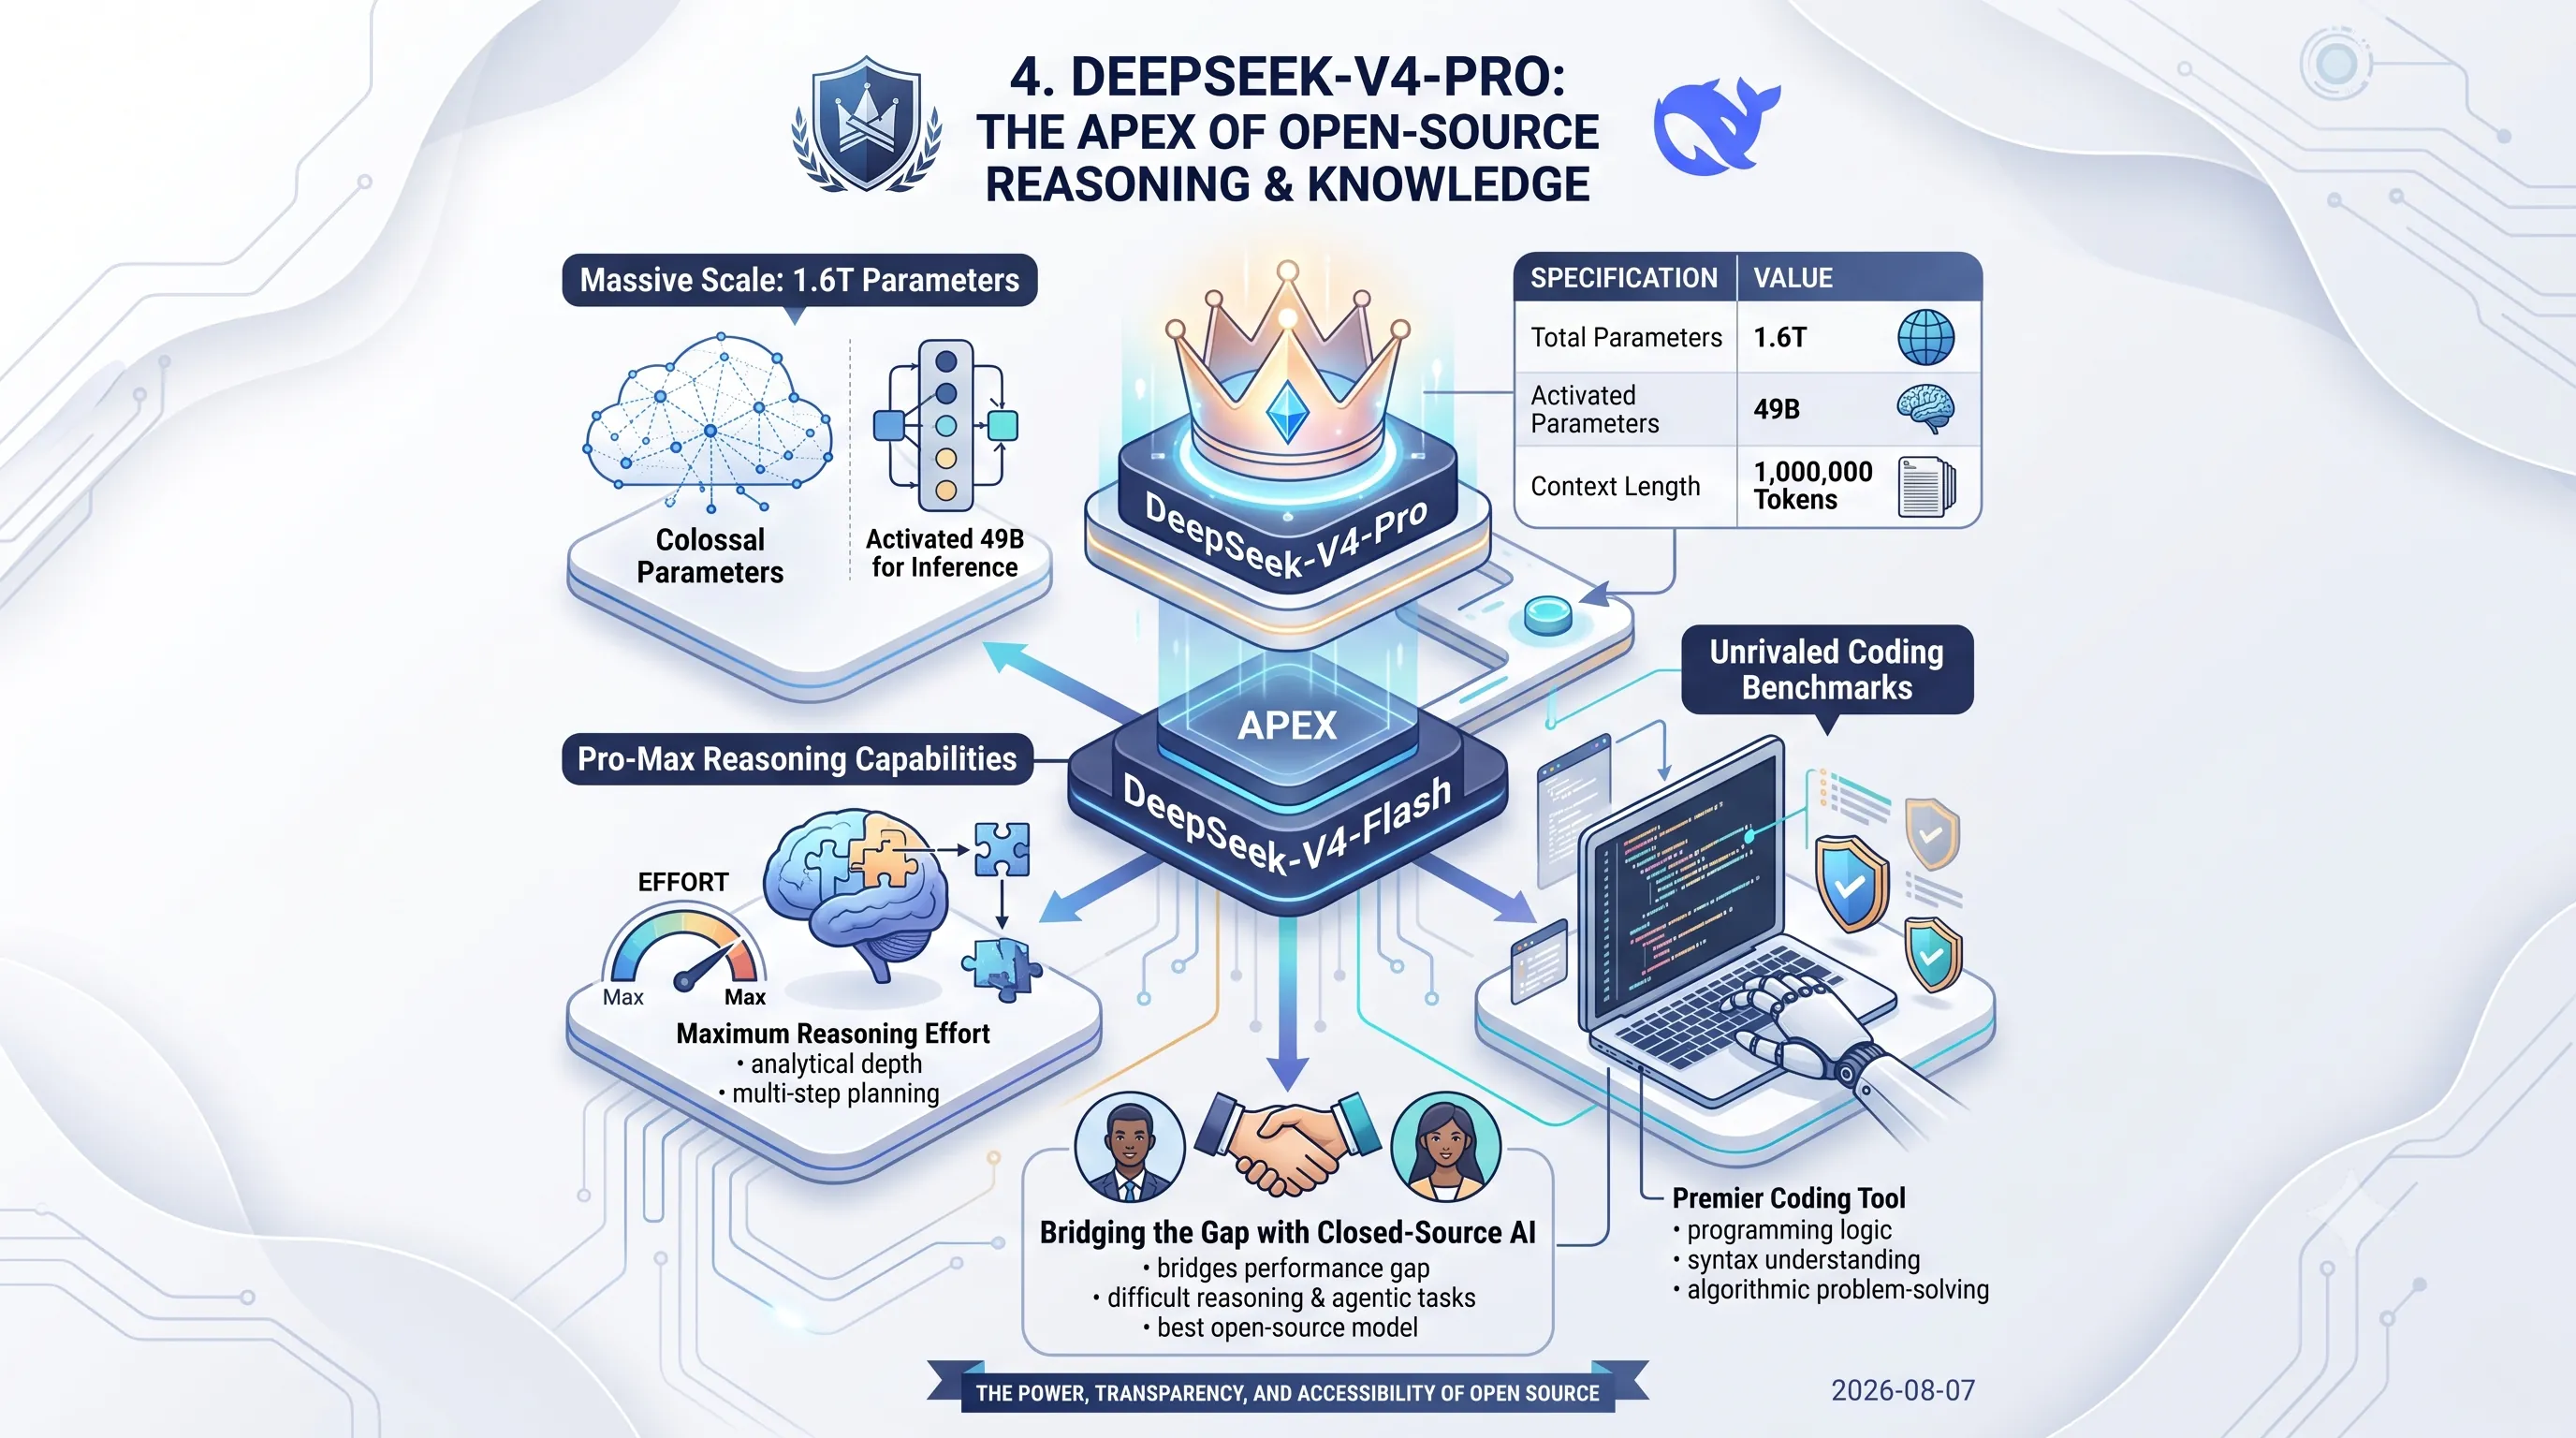
While this article's primary focus is the highly efficient DeepSeek-V4-Flash, understanding its more powerful counterpart, DeepSeek-V4-Pro, is essential for appreciating the full spectrum of capabilities within the DeepSeek-V4 series.The Pro model sets the performance ceiling, showcasing the maximum potential of this architecture and providing a crucial benchmark against which the Flash model's speed and efficiency trade-offs can be measured.
| Specification | Value |
|---|---|
| Total Parameters | 1.6T |
| Activated Parameters | 49B |
| Context Length | One million tokens |
Massive Scale: 1.6T Parameters
DeepSeek-V4-Pro operates on a colossal scale, built with a total of 1.6 trillion parameters.This immense size provides a vast repository for world knowledge and complex pattern recognition.
However, during inference, it efficiently utilizes a Mixture-of-Experts (MoE) architecture, activating only 49 billion parameters for any given task, balancing immense capability with computational feasibility.
Furthermore, the model supports a massive context length of one million tokens, enabling it to process and reason over extensive documents, codebases, and conversations in a single pass.
Pro-Max Reasoning Capabilities
For tasks demanding the highest level of analytical depth, DeepSeek-V4-Pro offers a specialized "Pro-Max" mode.This mode is specifically engineered for maximum reasoning effort, pushing the model's computational resources to their limit to derive more accurate and nuanced conclusions.
The activation of Pro-Max significantly advances the knowledge capabilities available within the open-source ecosystem, allowing developers to tackle problems that were previously the exclusive domain of proprietary systems.
Unrivaled Coding Benchmarks
The Pro-Max mode also establishes DeepSeek-V4-Pro as a premier tool for software development and code generation.In its maximum effort configuration, the model achieves top-tier performance in coding benchmarks.
This demonstrates a profound understanding of programming logic, syntax across various languages, and complex algorithmic problem-solving, making it an invaluable asset for developers.
Bridging the Gap with Closed-Source AI
Ultimately, the performance of DeepSeek-V4-Pro-Max represents a major milestone for open-source AI.It significantly bridges the gap with leading closed-source models, particularly on difficult reasoning and agentic tasks that require multi-step planning and execution.
This achievement has firmly established DeepSeek-V4-Pro as the best open-source model available today, providing a powerful, transparent, and accessible alternative to the industry's top proprietary offerings.
5. Under the Hood: DeepSeek-V4 Series Architectural Innovations
This section delves into the core architectural advancements that power the DeepSeek-V4 series, enabling its combination of high performance and remarkable efficiency, which is central to models like DeepSeek-V4-Flash.Hybrid Attention for Long-Context Efficiency
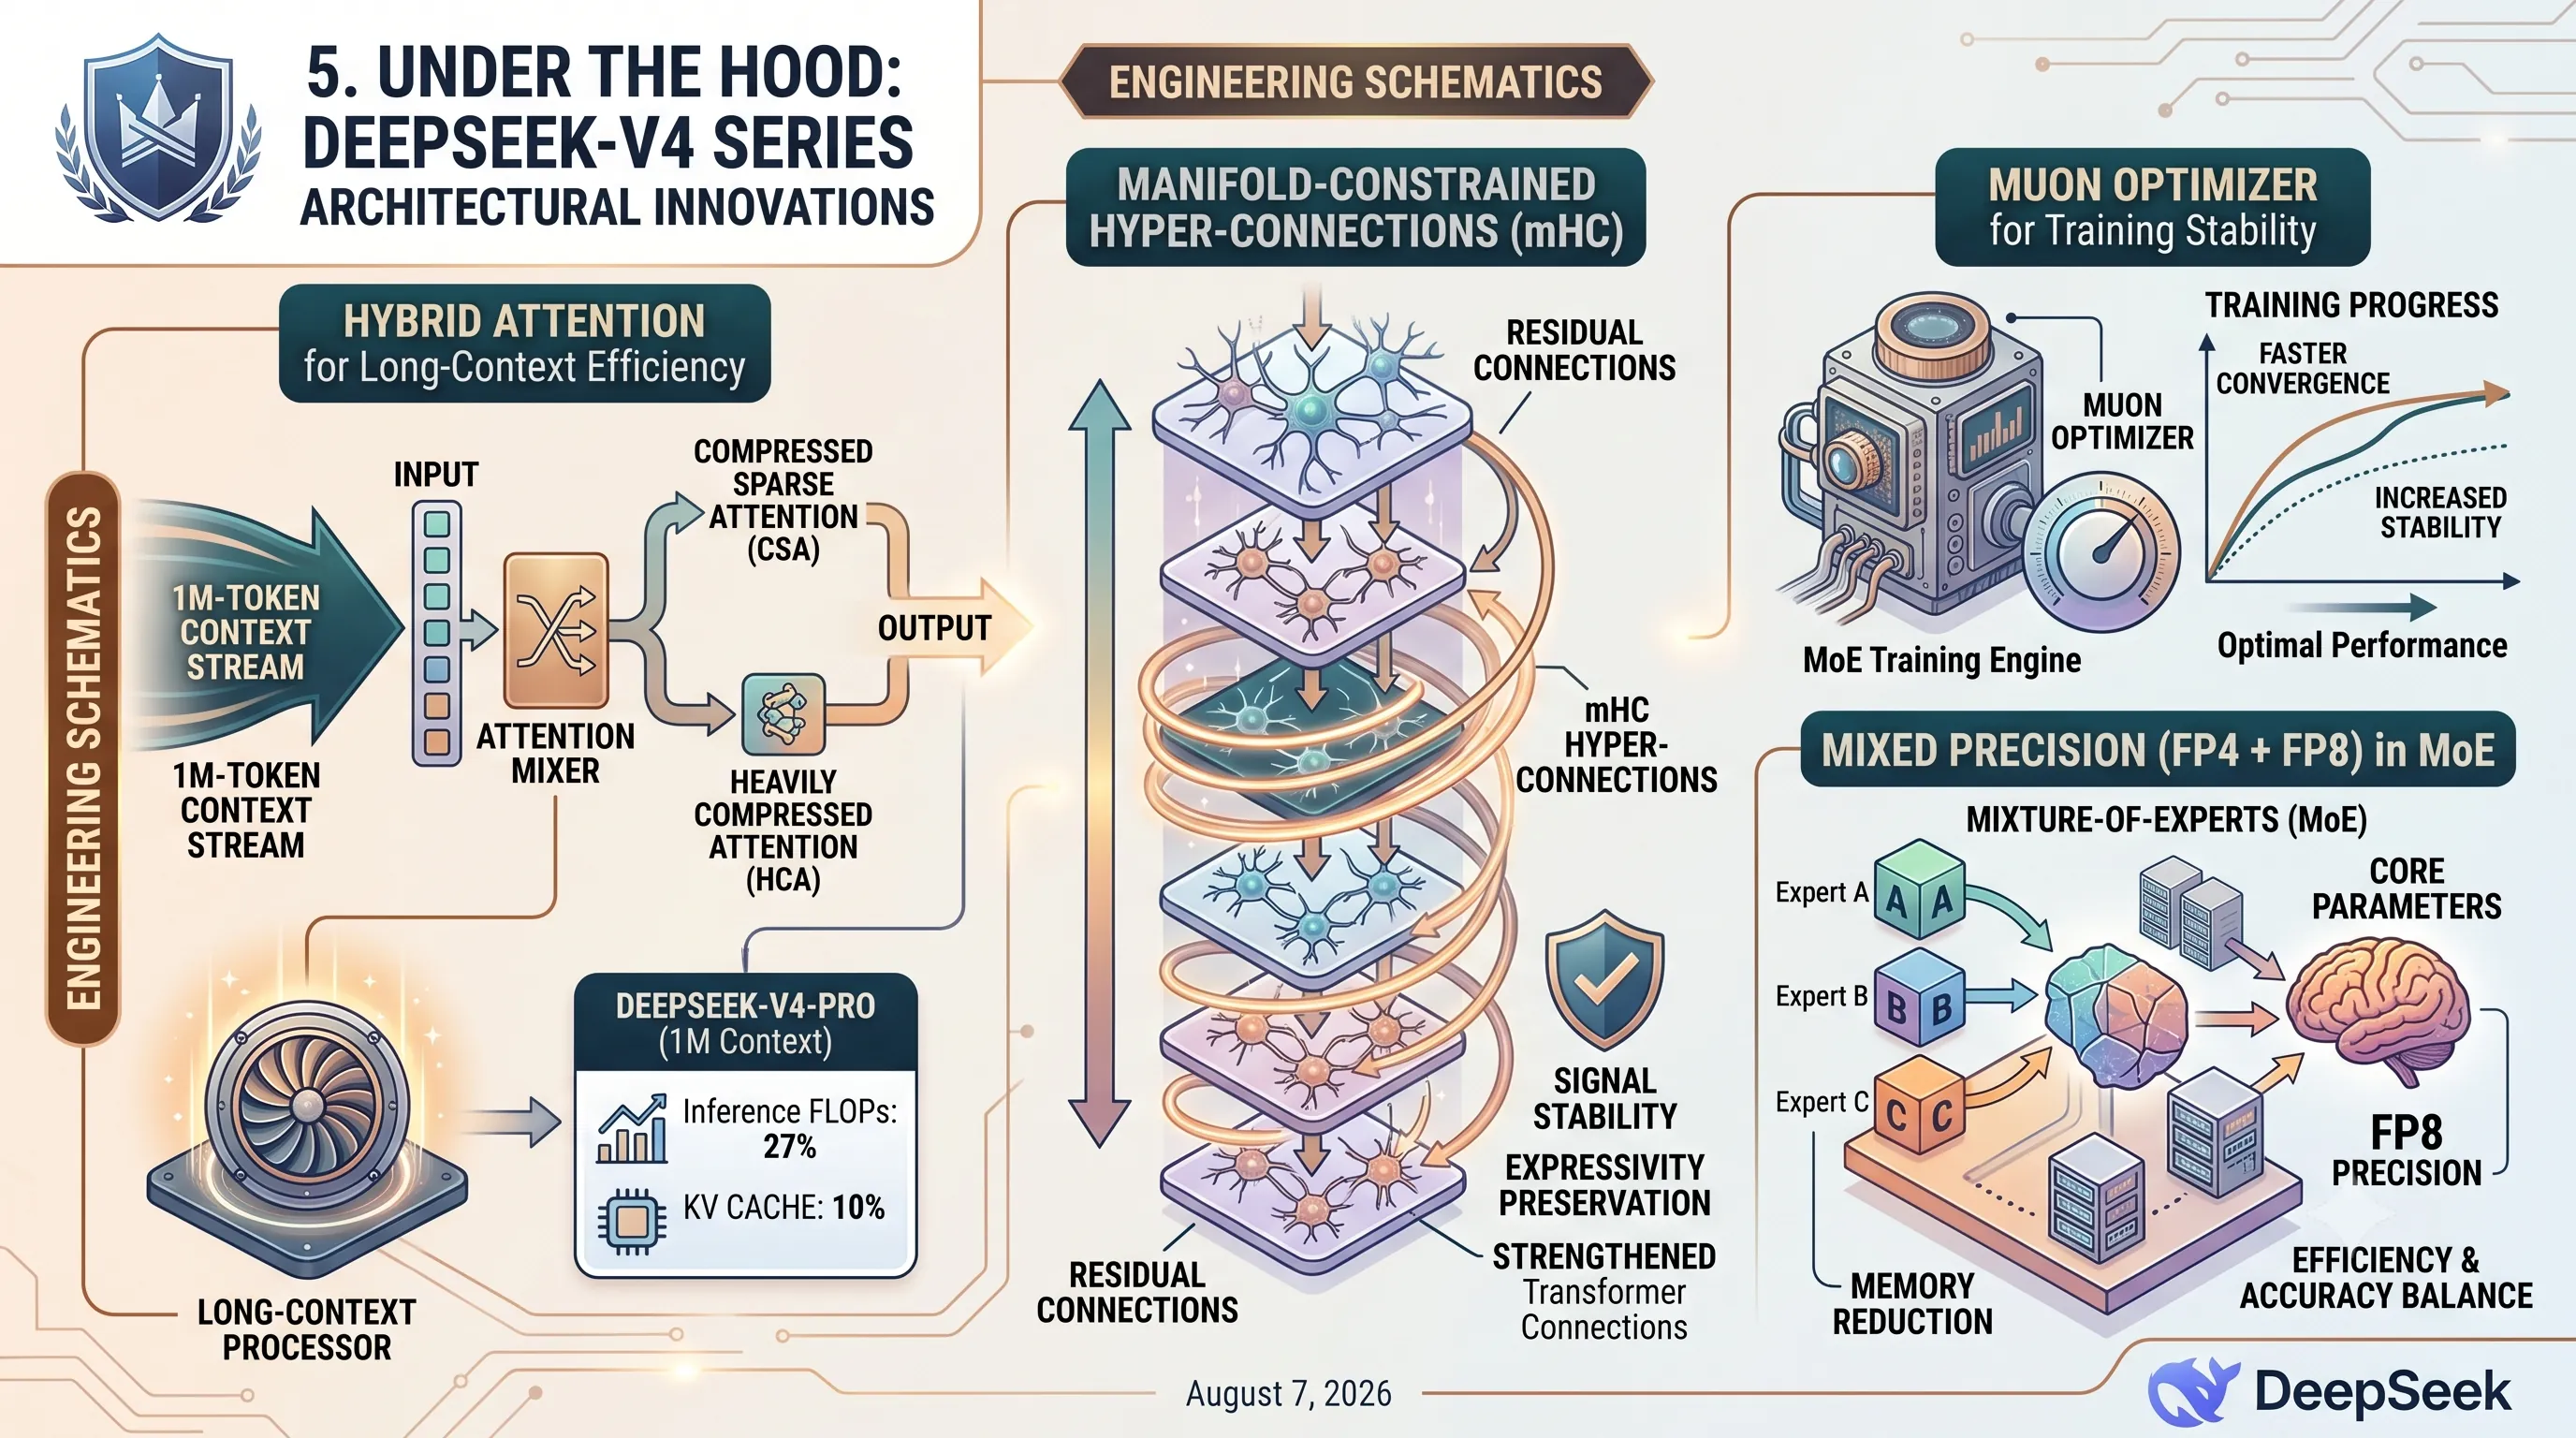
The DeepSeek-V4 series implements a novel Hybrid Attention Architecture to handle vast contexts with unprecedented efficiency.This architecture is not a single mechanism but a combination of two specialized techniques: Compressed Sparse Attention (CSA) and Heavily Compressed Attention (HCA).
The integration of these methods dramatically improves long-context processing performance.
The results are tangible: in a 1M-token context setting, DeepSeek-V4-Pro requires only 27% of the single-token inference FLOPs and a mere 10% of the KV cache when compared to its predecessor, DeepSeek-V3.2.
Manifold-Constrained Hyper-Connections (mHC)
To ensure robust performance across its deep neural network, the V4 series incorporates Manifold-Constrained Hyper-Connections (mHC).This technique is designed to strengthen the conventional residual connections that are standard in transformer architectures.
By doing so, mHC enhances the stability of signal propagation across the model's many layers.
Crucially, this improvement in stability is achieved while simultaneously preserving the model's essential expressivity, preventing degradation of its reasoning and generation capabilities.
Muon Optimizer for Training Stability
The training process for the DeepSeek-V4 models was powered by the Muon optimizer.This choice was instrumental in overcoming common challenges in large-scale model training.
The Muon optimizer is employed specifically for its ability to achieve faster convergence, reducing the time and resources needed to reach optimal performance.
Furthermore, it provides greater training stability, a critical factor when working with complex architectures like Mixture-of-Experts (MoE).
Mixed Precision (FP4 + FP8) in MoE
A key element of the model's efficiency, particularly within its MoE structure, is the strategic use of mixed-precision data types.The parameters for the MoE experts are stored using FP4 precision, an extremely low-precision format that significantly reduces memory footprint.
Meanwhile, most other parameters in the model utilize FP8 precision.
This combined FP4 + FP8 Mixed precision approach allows the model to achieve a fine-tuned balance between computational efficiency and performance accuracy.
6. Harnessing DeepSeek-V4: Comprehensive API and SDK Integration Guides
Building upon the introduction of the DeepSeek-V4-Flash model and its specifications, this section provides a practical guide for developers to integrate this powerful technology into their applications.We will detail the robust API and SDK support that facilitates seamless implementation across various development environments and frameworks.
Python SDK for Seamless Integration
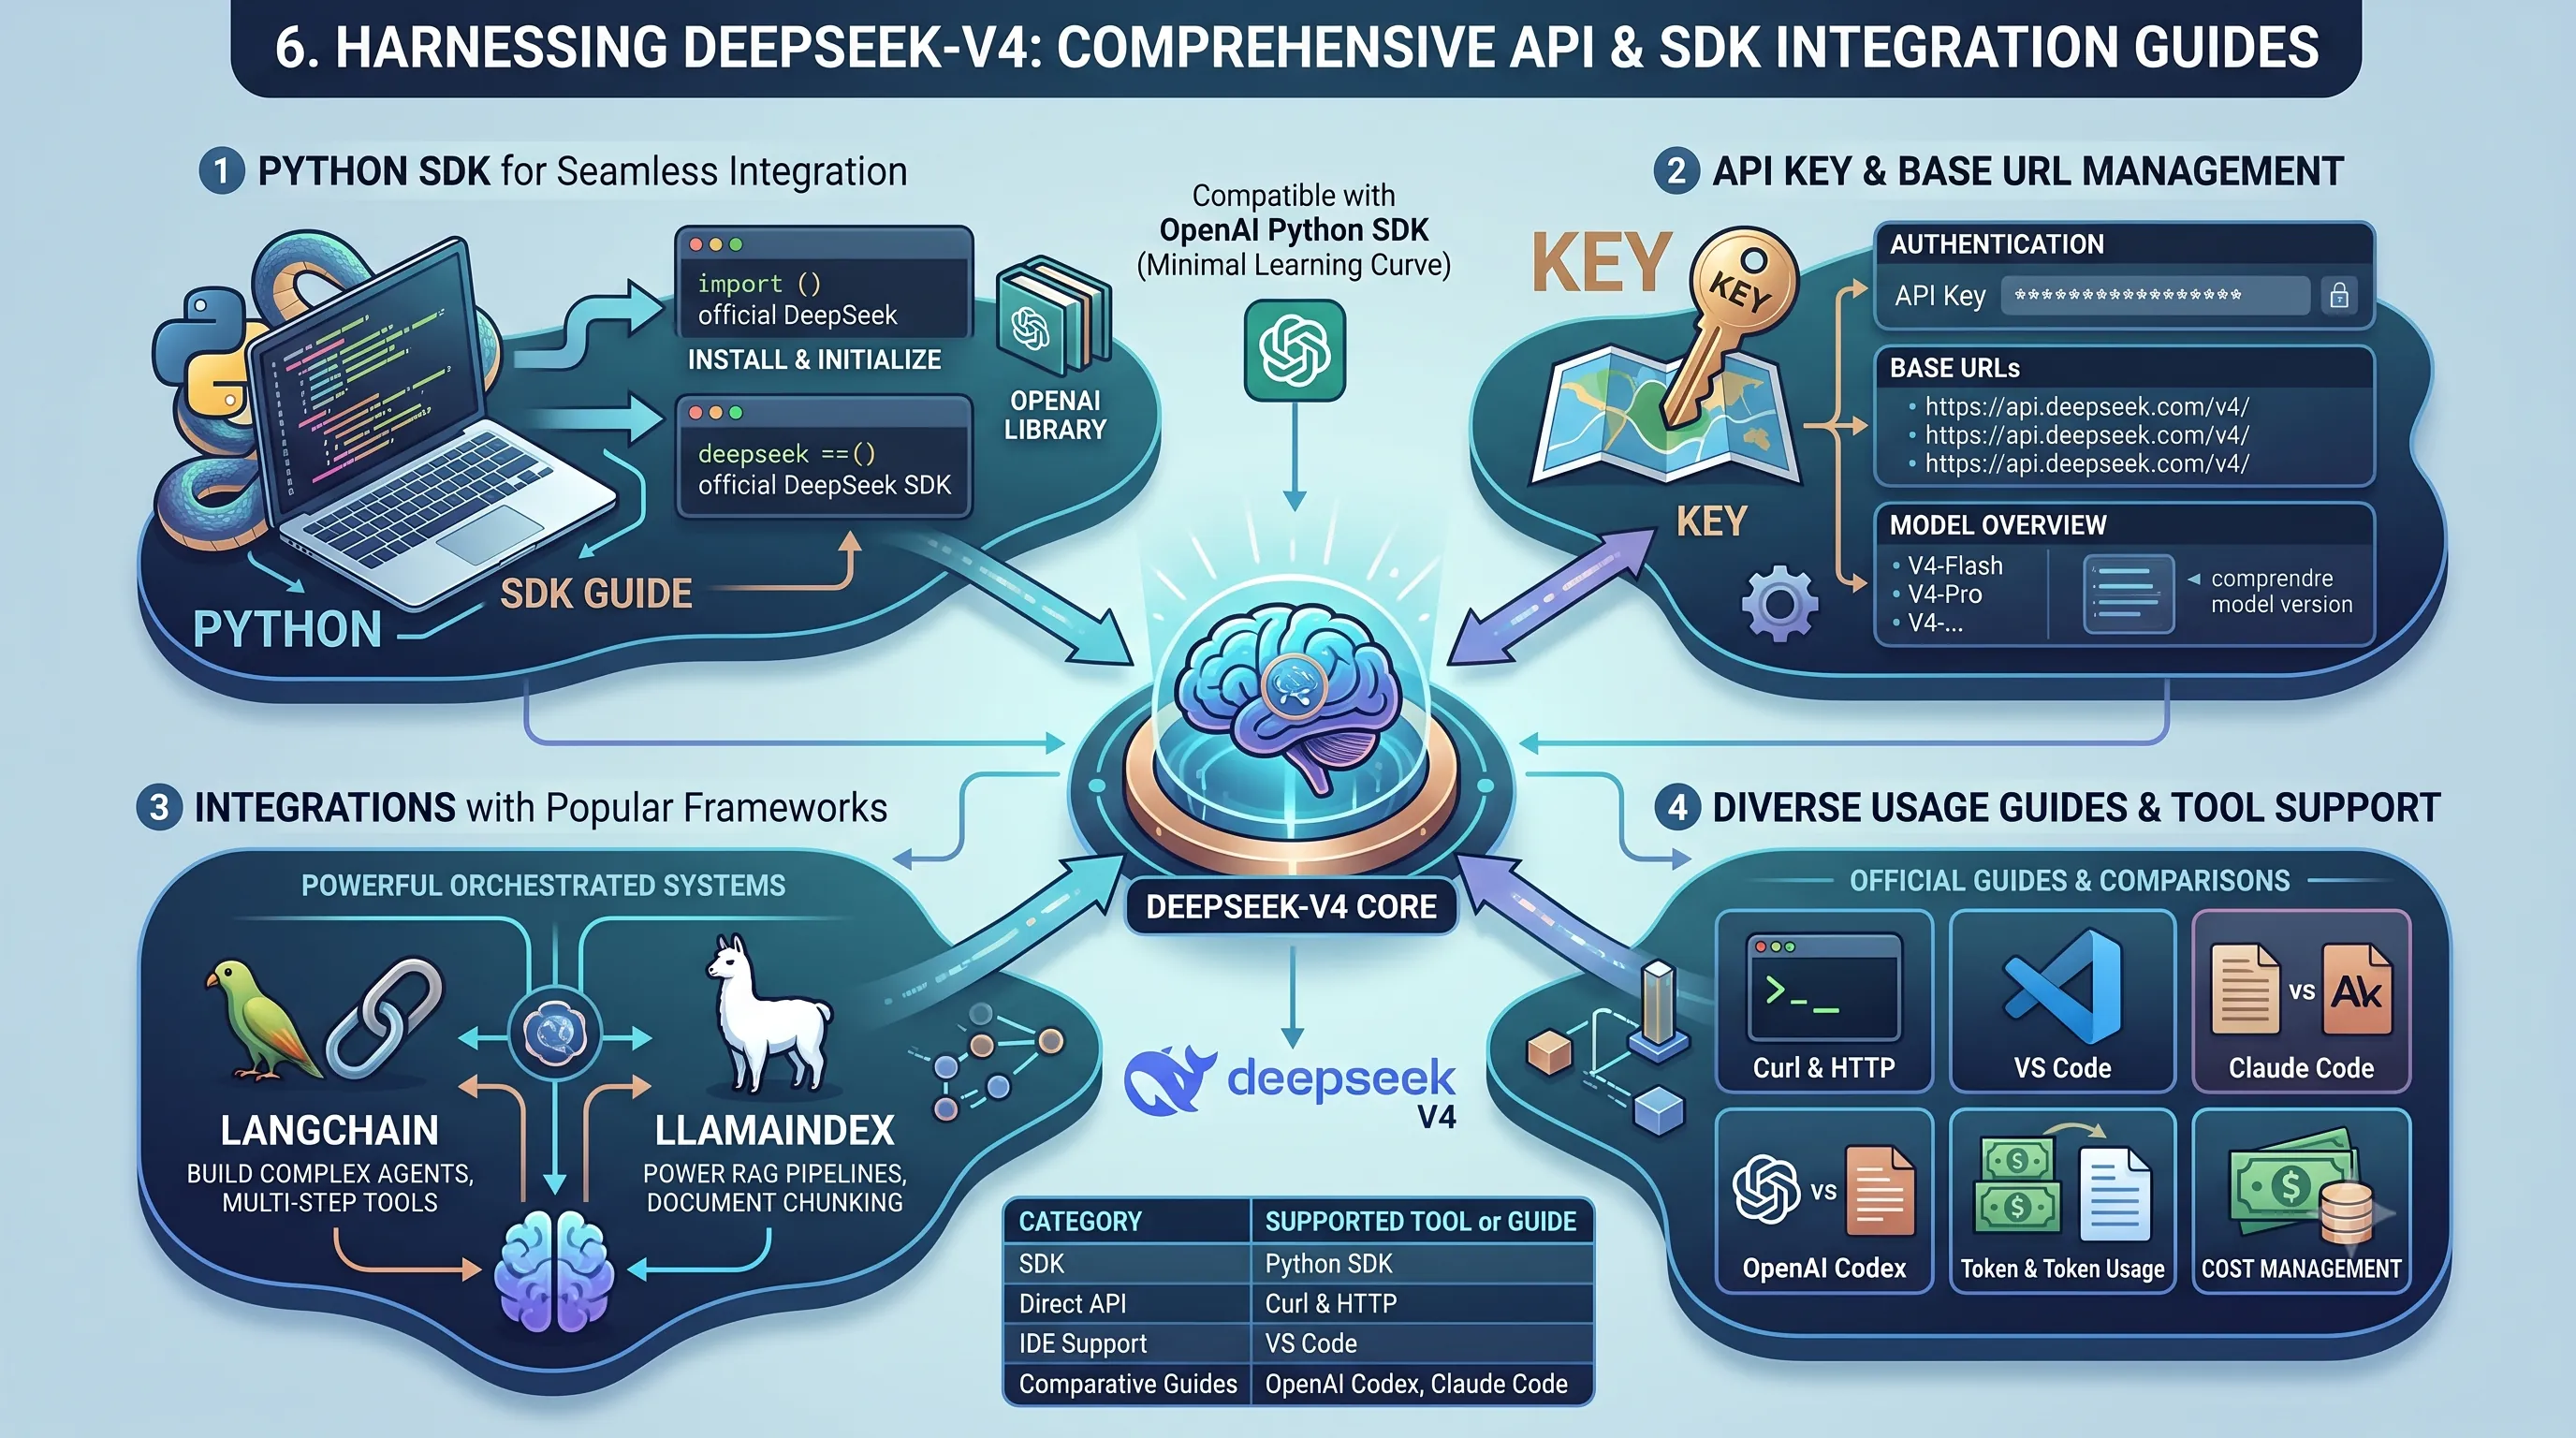
DeepSeek ensures that developers can get up and running quickly by providing comprehensive support for Python, the lingua franca of AI development.An official Python SDK guide is available, offering clear instructions and code samples to streamline the integration process into new or existing Python applications.
Furthermore, to lower the barrier to entry for developers already working within the OpenAI ecosystem, the DeepSeek V4 API is compatible with the official OpenAI Python SDK.
This allows developers to leverage familiar tools and code structures by simply installing the OpenAI library and pointing it to the DeepSeek API endpoint, minimizing the learning curve.
API Key and Base URL Management
Fundamental to any API integration is proper configuration, and DeepSeek provides a clear path for this initial setup.The official DeepSeek API guide serves as the central resource for all essential information.
This documentation details the process for obtaining API keys, which are necessary for authenticating requests.
It also provides the correct base URLs for API endpoints and includes a model overview, helping developers understand and select the appropriate model version for their specific use case.
Integrations with Popular Frameworks (LangChain, LlamaIndex)
To support the development of sophisticated AI applications, DeepSeek V4 offers out-of-the-box integrations with leading large language model (LLM) frameworks.Official support for both LangChain and LlamaIndex is available.
This compatibility is critical for developers building complex systems like Retrieval-Augmented Generation (RAG) pipelines, agents, or multi-step tool-using applications, as it allows them to incorporate DeepSeek V4 as a core reasoning engine within these established and powerful orchestration tools.
Diverse Usage Guides and Tool Support
DeepSeek provides a wealth of documentation to support developers across various platforms and with different levels of expertise.A crucial resource is the official Token & Token Usage guide, which is essential for managing costs and understanding the input/output mechanics of the model.
Beyond token management, the platform offers a wide array of specific usage guides catering to different workflows and tools.
These guides cover everything from basic API calls using Curl & HTTP to integration within popular code editors like VS Code.
For developers transitioning from other platforms, comparative guides for OpenAI Codex and Claude Code are also provided.
| Category | Supported Tool or Guide |
|---|---|
| SDK | Python SDK |
| Direct API | Curl & HTTP |
| IDE Support | VS Code |
| Comparative Guides | OpenAI Codex, Claude Code |
7. DeepSeek Model Economics: Unpacking Pricing and Availability
This section delves into the crucial economic aspects of adopting DeepSeek-V4-Flash, providing a detailed cost-benefit analysis for developers and organizations.As a key component of the larger "MoE 284B Rebellion" article, understanding the pricing and platform availability is fundamental to leveraging the model's powerful capabilities effectively and affordably.
DeepInfra Pricing Structure
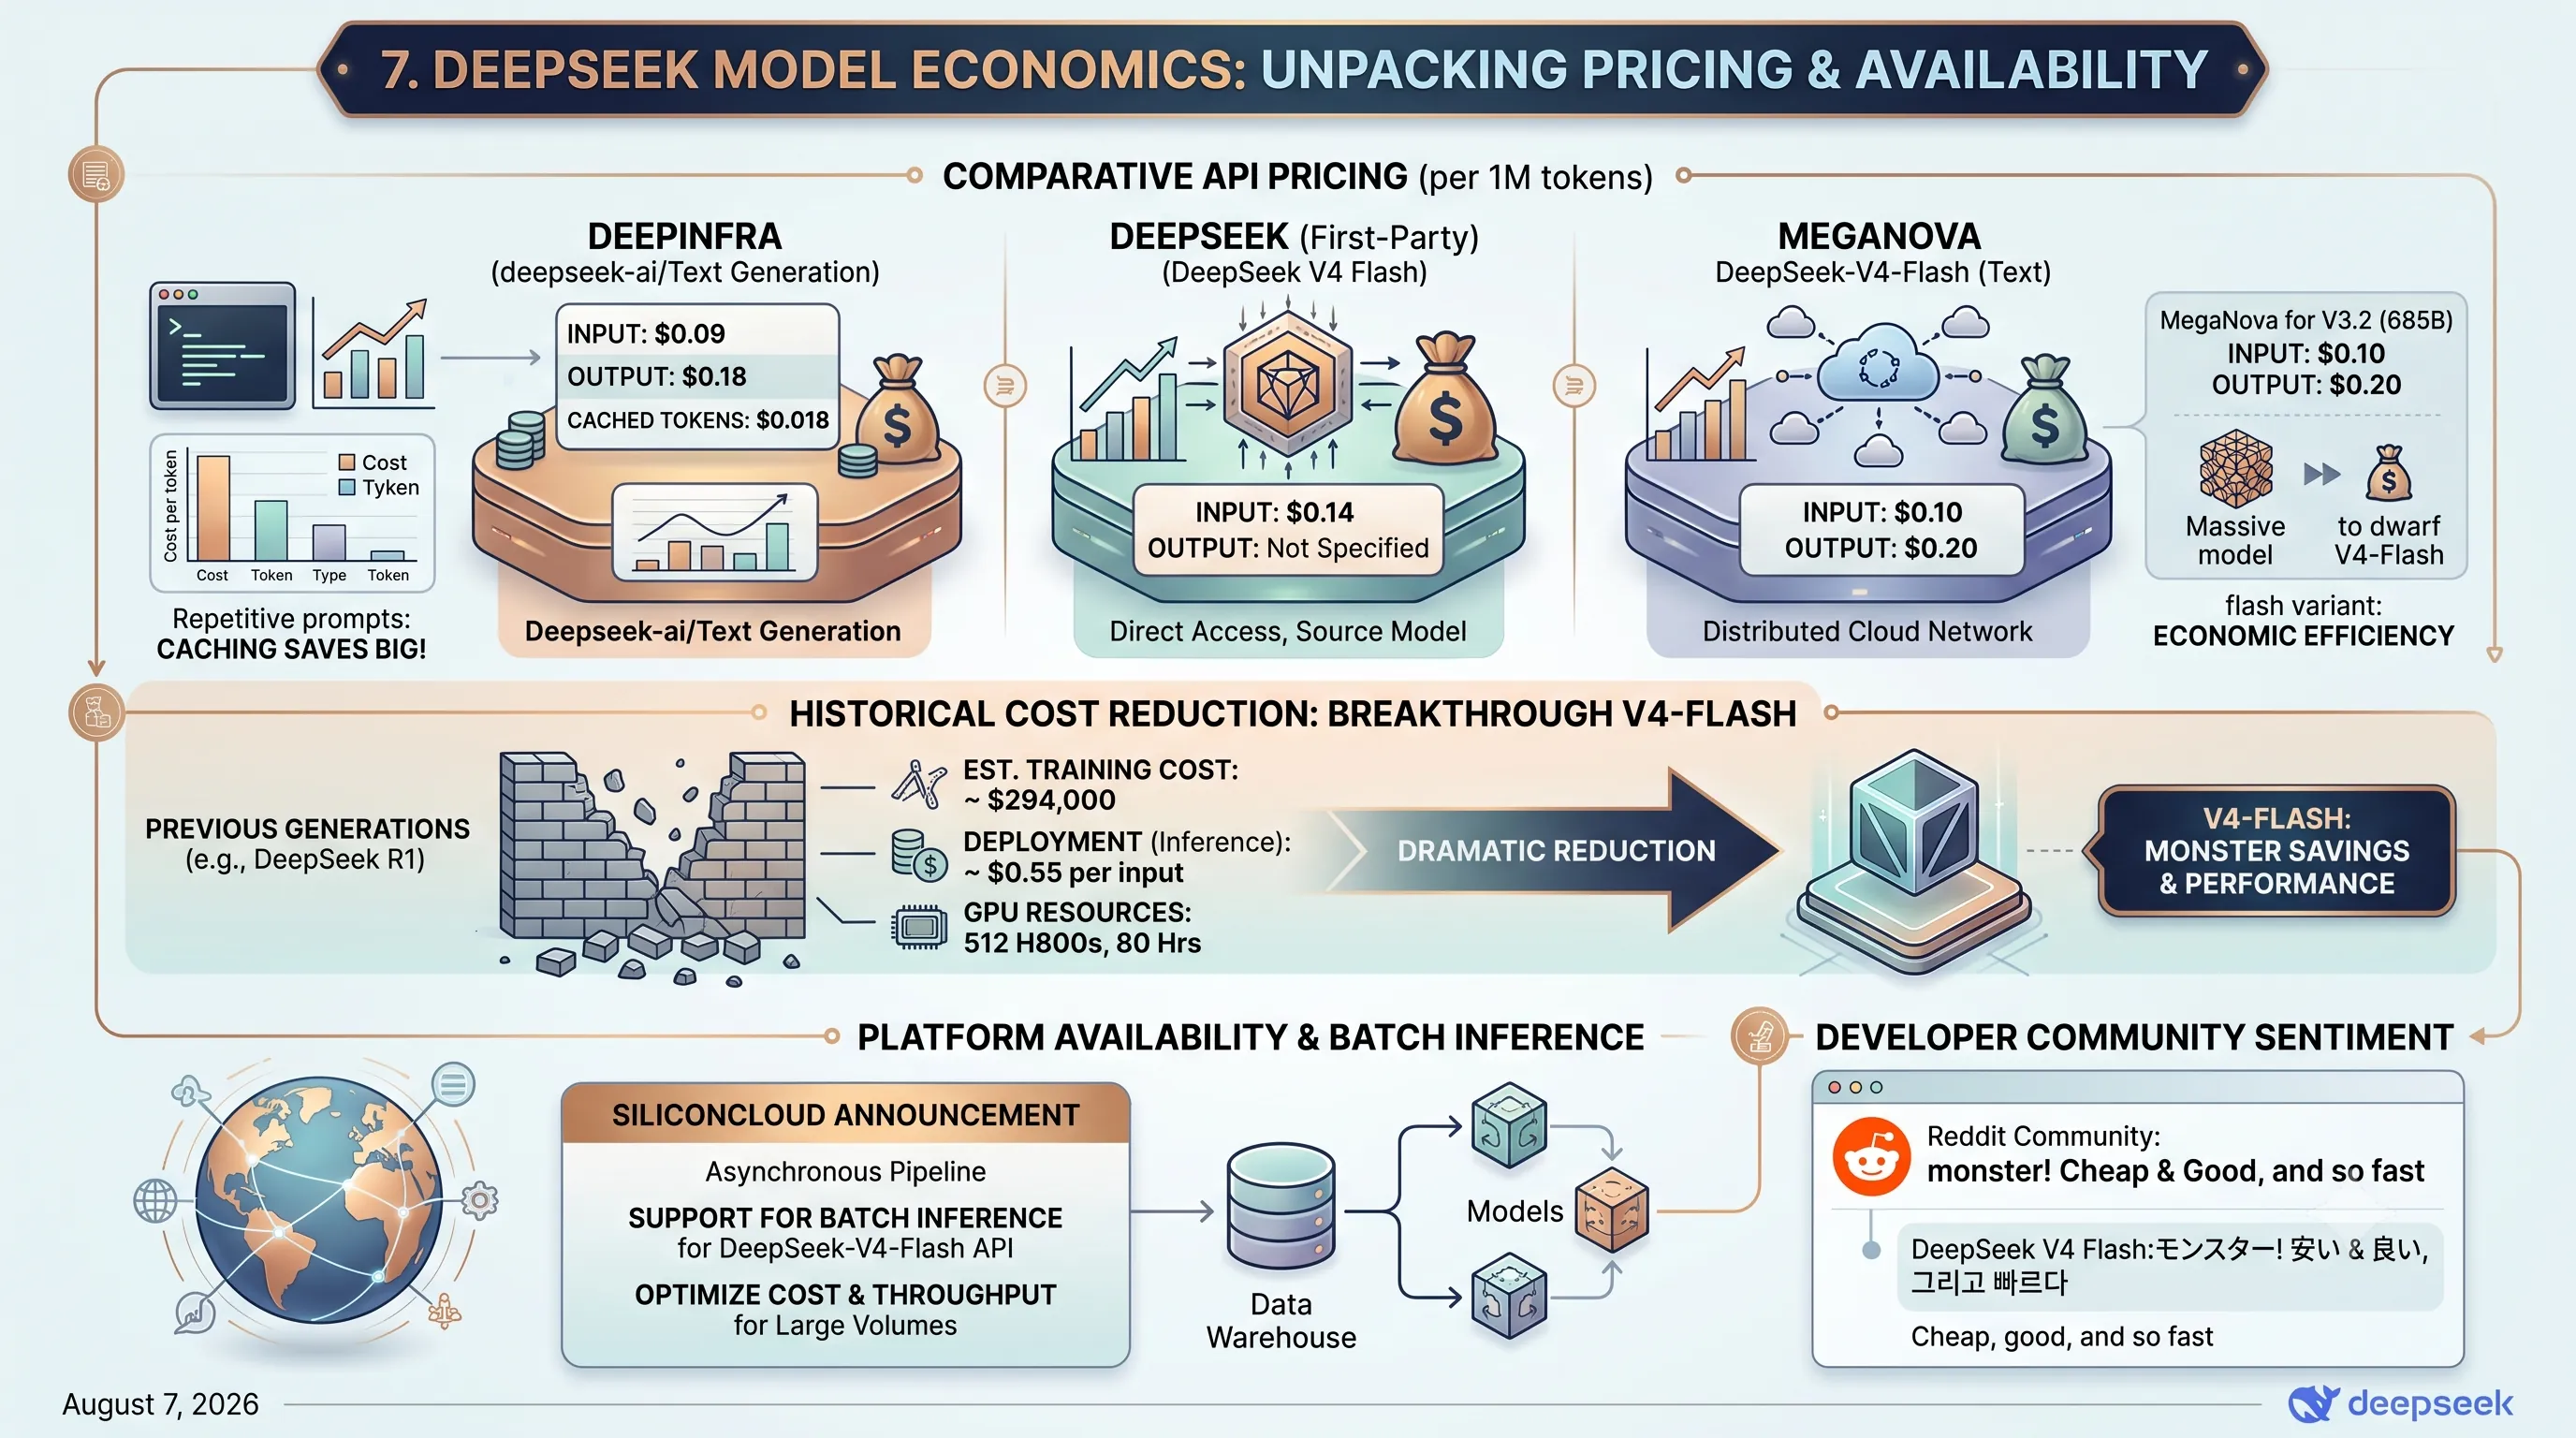
DeepInfra has emerged as a highly competitive platform for accessing DeepSeek models, offering a granular pricing scheme that benefits various use cases.For its `deepseek-ai/Text Generation` service, the platform charges $0.09 per 1 million input tokens and $0.18 per 1 million output tokens.
A notable feature is the pricing for cached tokens, set at an exceptionally low $0.018 per 1 million tokens, which significantly reduces costs for applications with repetitive prompts or contexts.
First-Party and MegaNova API Costs
When accessing the model directly from the source, the DeepSeek V4 Flash first-party API is priced at $0.14 per 1 million input tokens.Meanwhile, third-party provider MegaNova offers a slightly different structure for DeepSeek-V4-Flash, with rates of $0.10 per 1 million input tokens and $0.20 per 1 million output tokens.
To put the V4-Flash model's affordability in perspective, MegaNova's pricing for the much larger DeepSeek-V3.2 (685B) model is substantially higher, at $0.26 per 1M input tokens and $0.38 per 1M output tokens, highlighting the economic efficiency of the newer flash variant.
| Platform | Model | Input Cost (per 1M tokens) | Output Cost (per 1M tokens) |
|---|---|---|---|
| DeepInfra | deepseek-ai/Text Generation | $0.09 | $0.18 |
| DeepSeek (First-Party) | DeepSeek V4 Flash | $0.14 | Not Specified |
| MegaNova | DeepSeek-V4-Flash (Text) | $0.10 | $0.20 |
Historical Training and Inference Expenditures
Understanding the costs associated with previous generations of DeepSeek models provides valuable context for the economic breakthroughs achieved with V4-Flash.For instance, the training for the earlier DeepSeek R1 model incurred an estimated cost of approximately $294,000.
This training run required significant computational resources, utilizing 512 H800 GPUs for a duration of 80 hours.
In terms of deployment, historical inference costs for DeepSeek R1 were around $0.55 per input, a figure that showcases the dramatic cost reduction in newer, more efficient models like V4-Flash.
Platform Availability and Batch Inference
The accessibility of DeepSeek-V4-Flash continues to expand across the ecosystem, enhancing its utility for diverse workloads.A key development in this area is from SiliconCloud, which announced its support for batch inference for the DeepSeek-V4-Flash API.
This capability is crucial for organizations needing to process large volumes of data asynchronously, optimizing both cost and throughput.
The model's combination of performance and low cost has resonated strongly within the developer community, as captured by one user's sentiment on Reddit: "DeepSeek V4 Flash is a monster! Cheap & Good, and so fast".
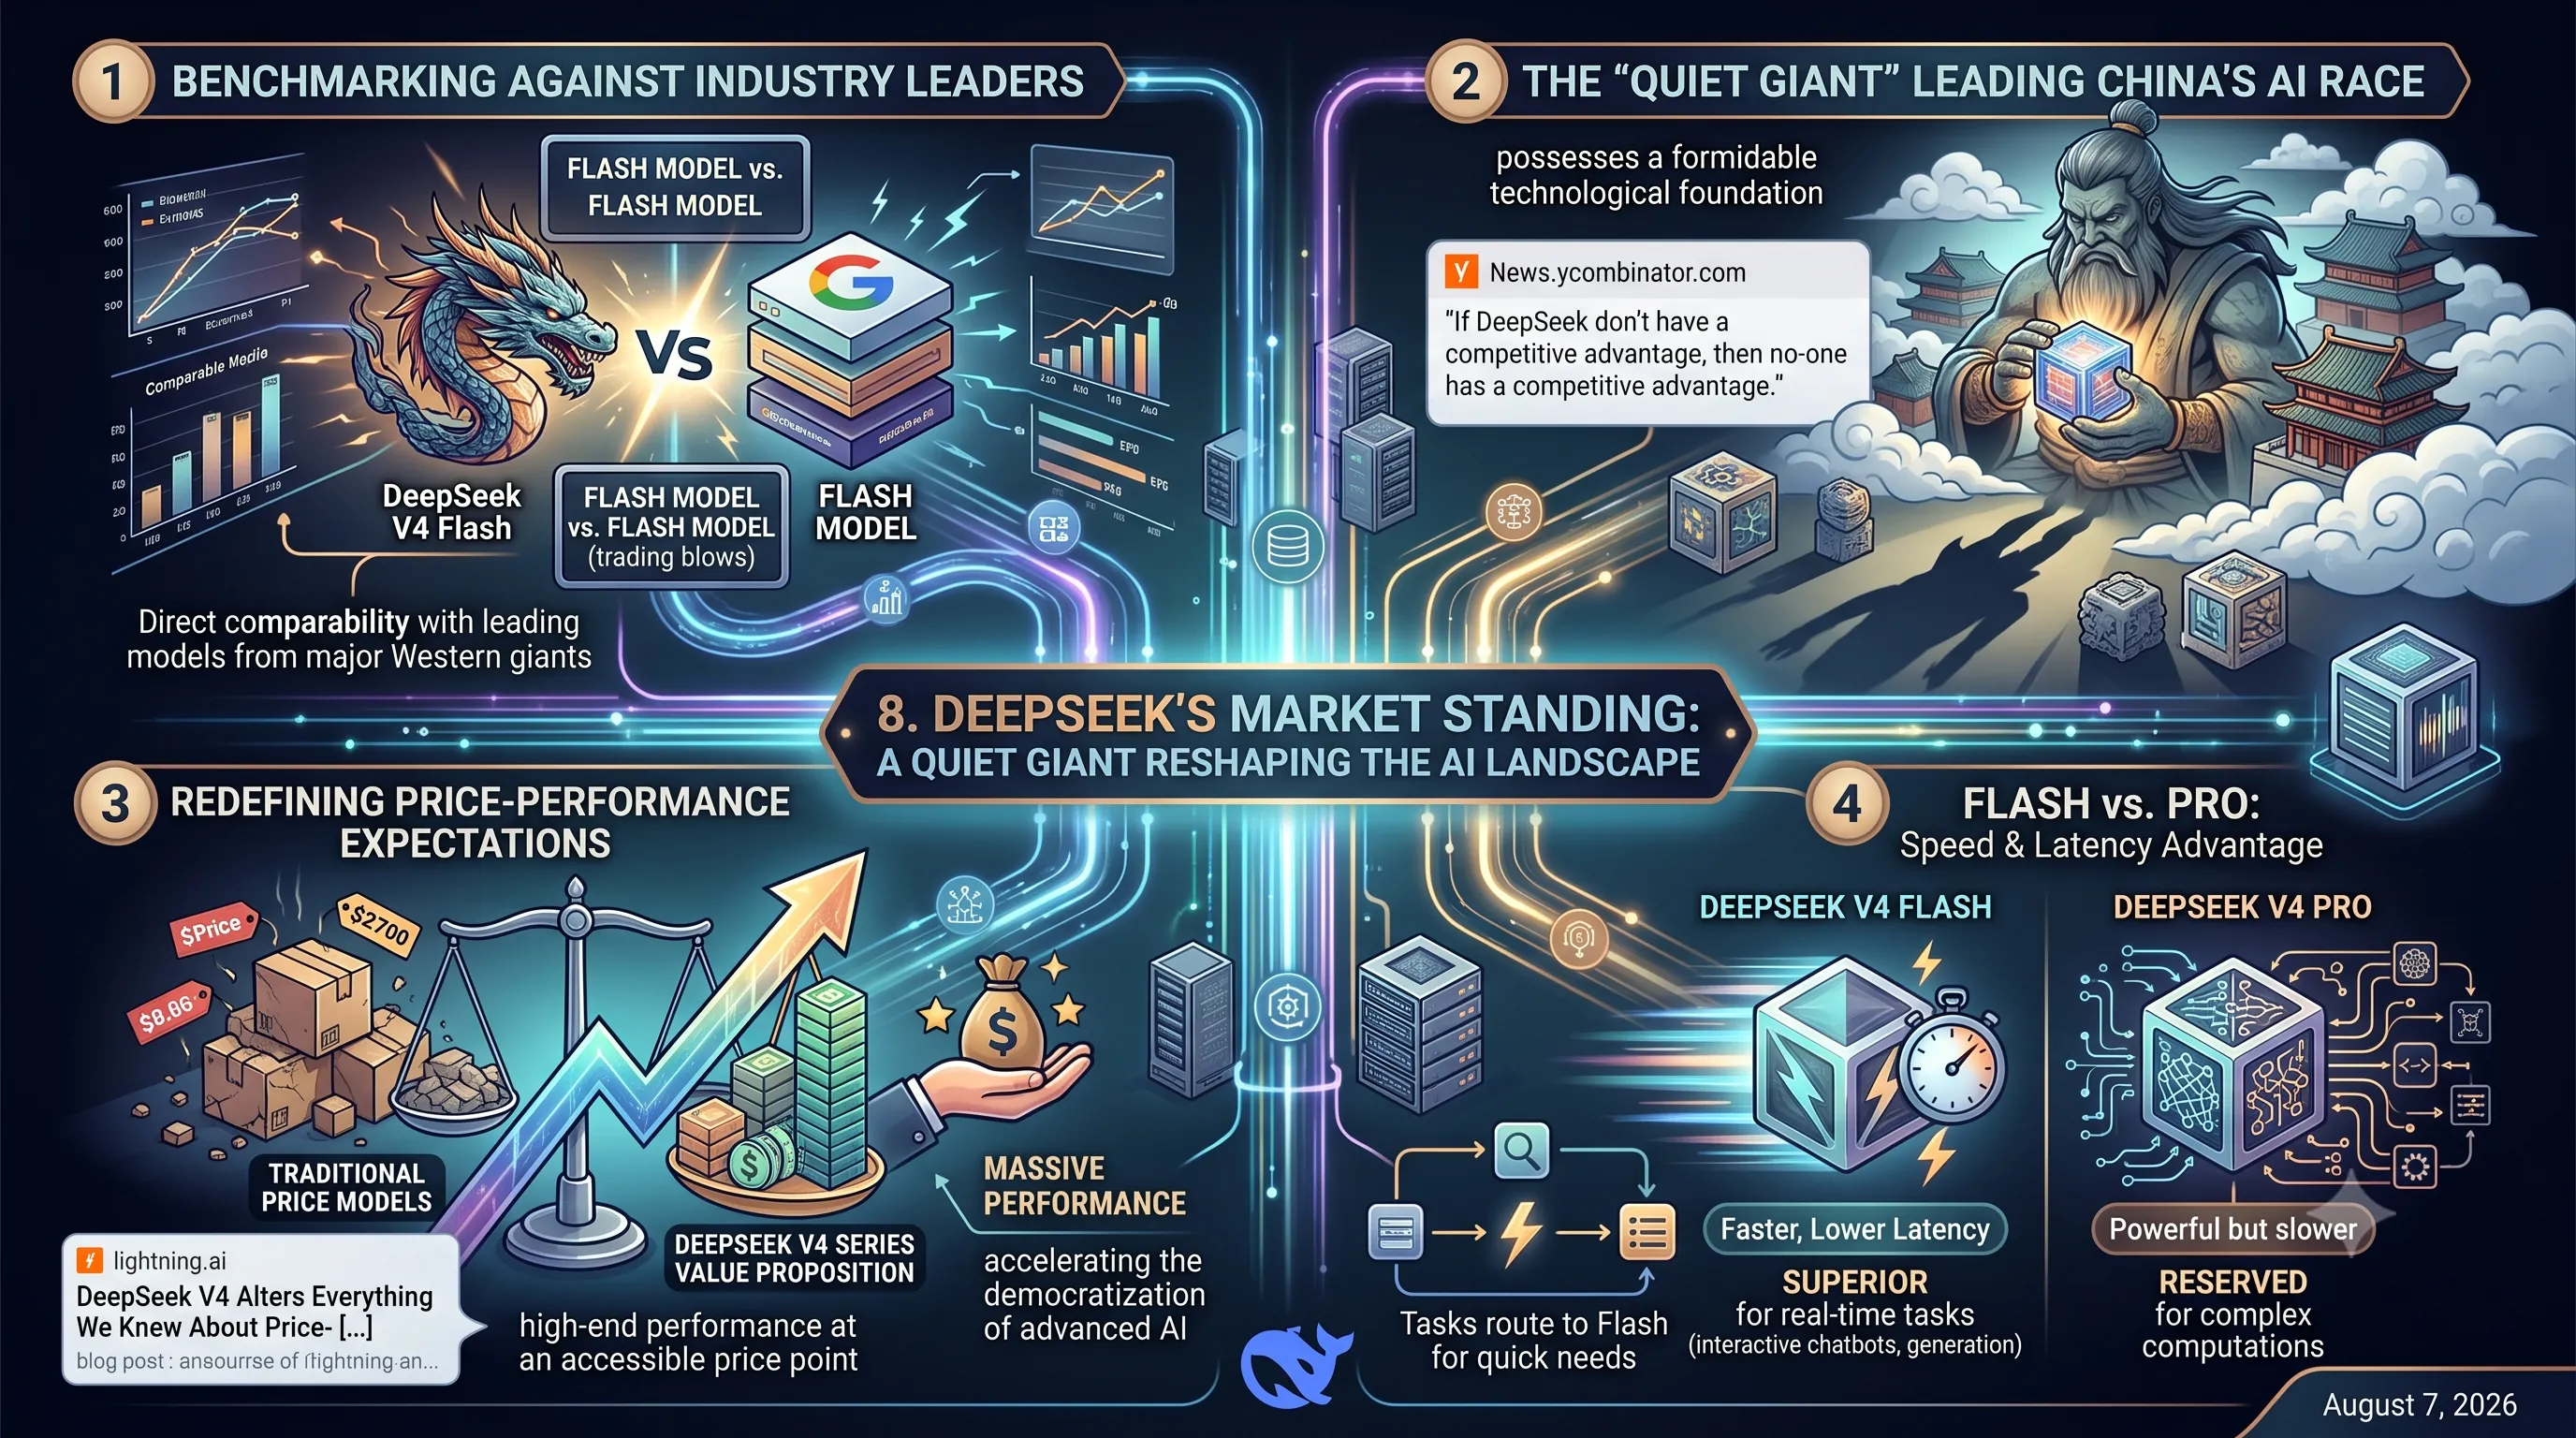
8. DeepSeek's Market Standing: A Quiet Giant Reshaping the AI Landscape
This section provides essential market context for our deep dive into the DeepSeek-V4-Flash model.By understanding DeepSeek's competitive positioning against industry giants and its role in redefining price-performance standards, we can better appreciate the technical significance of its specifications and API, which are detailed later in this guide.
Benchmarking Against Industry Leaders
DeepSeek has firmly established itself as a top-tier competitor in the global AI arena.The performance of its models is not just theoretical; DeepSeek V4 Flash actively "trades blows with Google's flash model" in key benchmarks.
This direct comparability with a leading model from a major Western tech giant demonstrates that DeepSeek is competing at the highest level, making its offerings a credible alternative for developers worldwide.
The "Quiet Giant" of AI
Within the industry, DeepSeek has earned the reputation of being "the quiet giant leading China's AI race."This description highlights a company that may not have the same level of global media exposure as its rivals but possesses a formidable technological foundation.
This sentiment is echoed in developer communities, where one observer on news.ycombinator.com stated, "If DeepSeek don't have a competitive advantage, then no-one has a competitive advantage."
This underscores the perception that DeepSeek's technological and strategic position grants it a significant edge in the highly competitive AI market.
Redefining Price-Performance Expectations
The release of the DeepSeek V4 series has had a disruptive impact on the market's value proposition.According to a blog post on lightning.ai, "DeepSeek V4 Alters Everything We Knew About Price- [...]," signaling a fundamental shift in what developers can expect to achieve for a given cost.
By offering high-end performance at a more accessible price point, DeepSeek is challenging established pricing models and forcing competitors to re-evaluate their own offerings, thereby accelerating the democratization of advanced AI capabilities.
Flash vs. Pro: Speed and Latency Advantage
Within its own powerful V4 lineup, DeepSeek provides tailored solutions for different use cases.A key distinction is that the DeepSeek V4 Flash is faster and has lower latency compared to DeepSeek V4 Pro.
This makes the Flash model the superior choice for applications where response time is critical, such as interactive chatbots, real-time content generation, and other latency-sensitive tasks, while the Pro model may be reserved for more complex, less time-sensitive computations.
Related Posts
NVIDIA Nemotron 3 Ultra: Open-Source LLM Empowers Next-Gen AI Agents with 5x Faster Inference & Advanced ReasoningNVIDIA Nemotron 3 Ultra is a new open-source, open-weight Mixture-of-Experts (MoE) model designed...
Comparative Analysis: Architectural Foundations of Tencent Hy4, DeepSeek-V4, and Qwen 3.8 MoE ModelsA deep dive into the architectural foundations, sparse activation strategies, and performance...
Optimizing LangGraph Agent Workflows with Node-Level CachingLearn how to optimize LangGraph agent performance by implementing node-level caching, custom...