
#LLM
7 posts
A Guide to Building Sovereign AI Infrastructure with Mistral Self-Hosted Stacks
Learn how to build sovereign, air-gapped AI infrastructure using Mistral's self-hosted enterprise stack for enhanced data security and control.
Architecting Resilient AI Agents with Pydantic AI: Type Safety, Execution Control, and Error Recovery
Learn how Pydantic AI enables production-grade AI agents through type-safe schema validation, deterministic state machine execution, and resilient error...
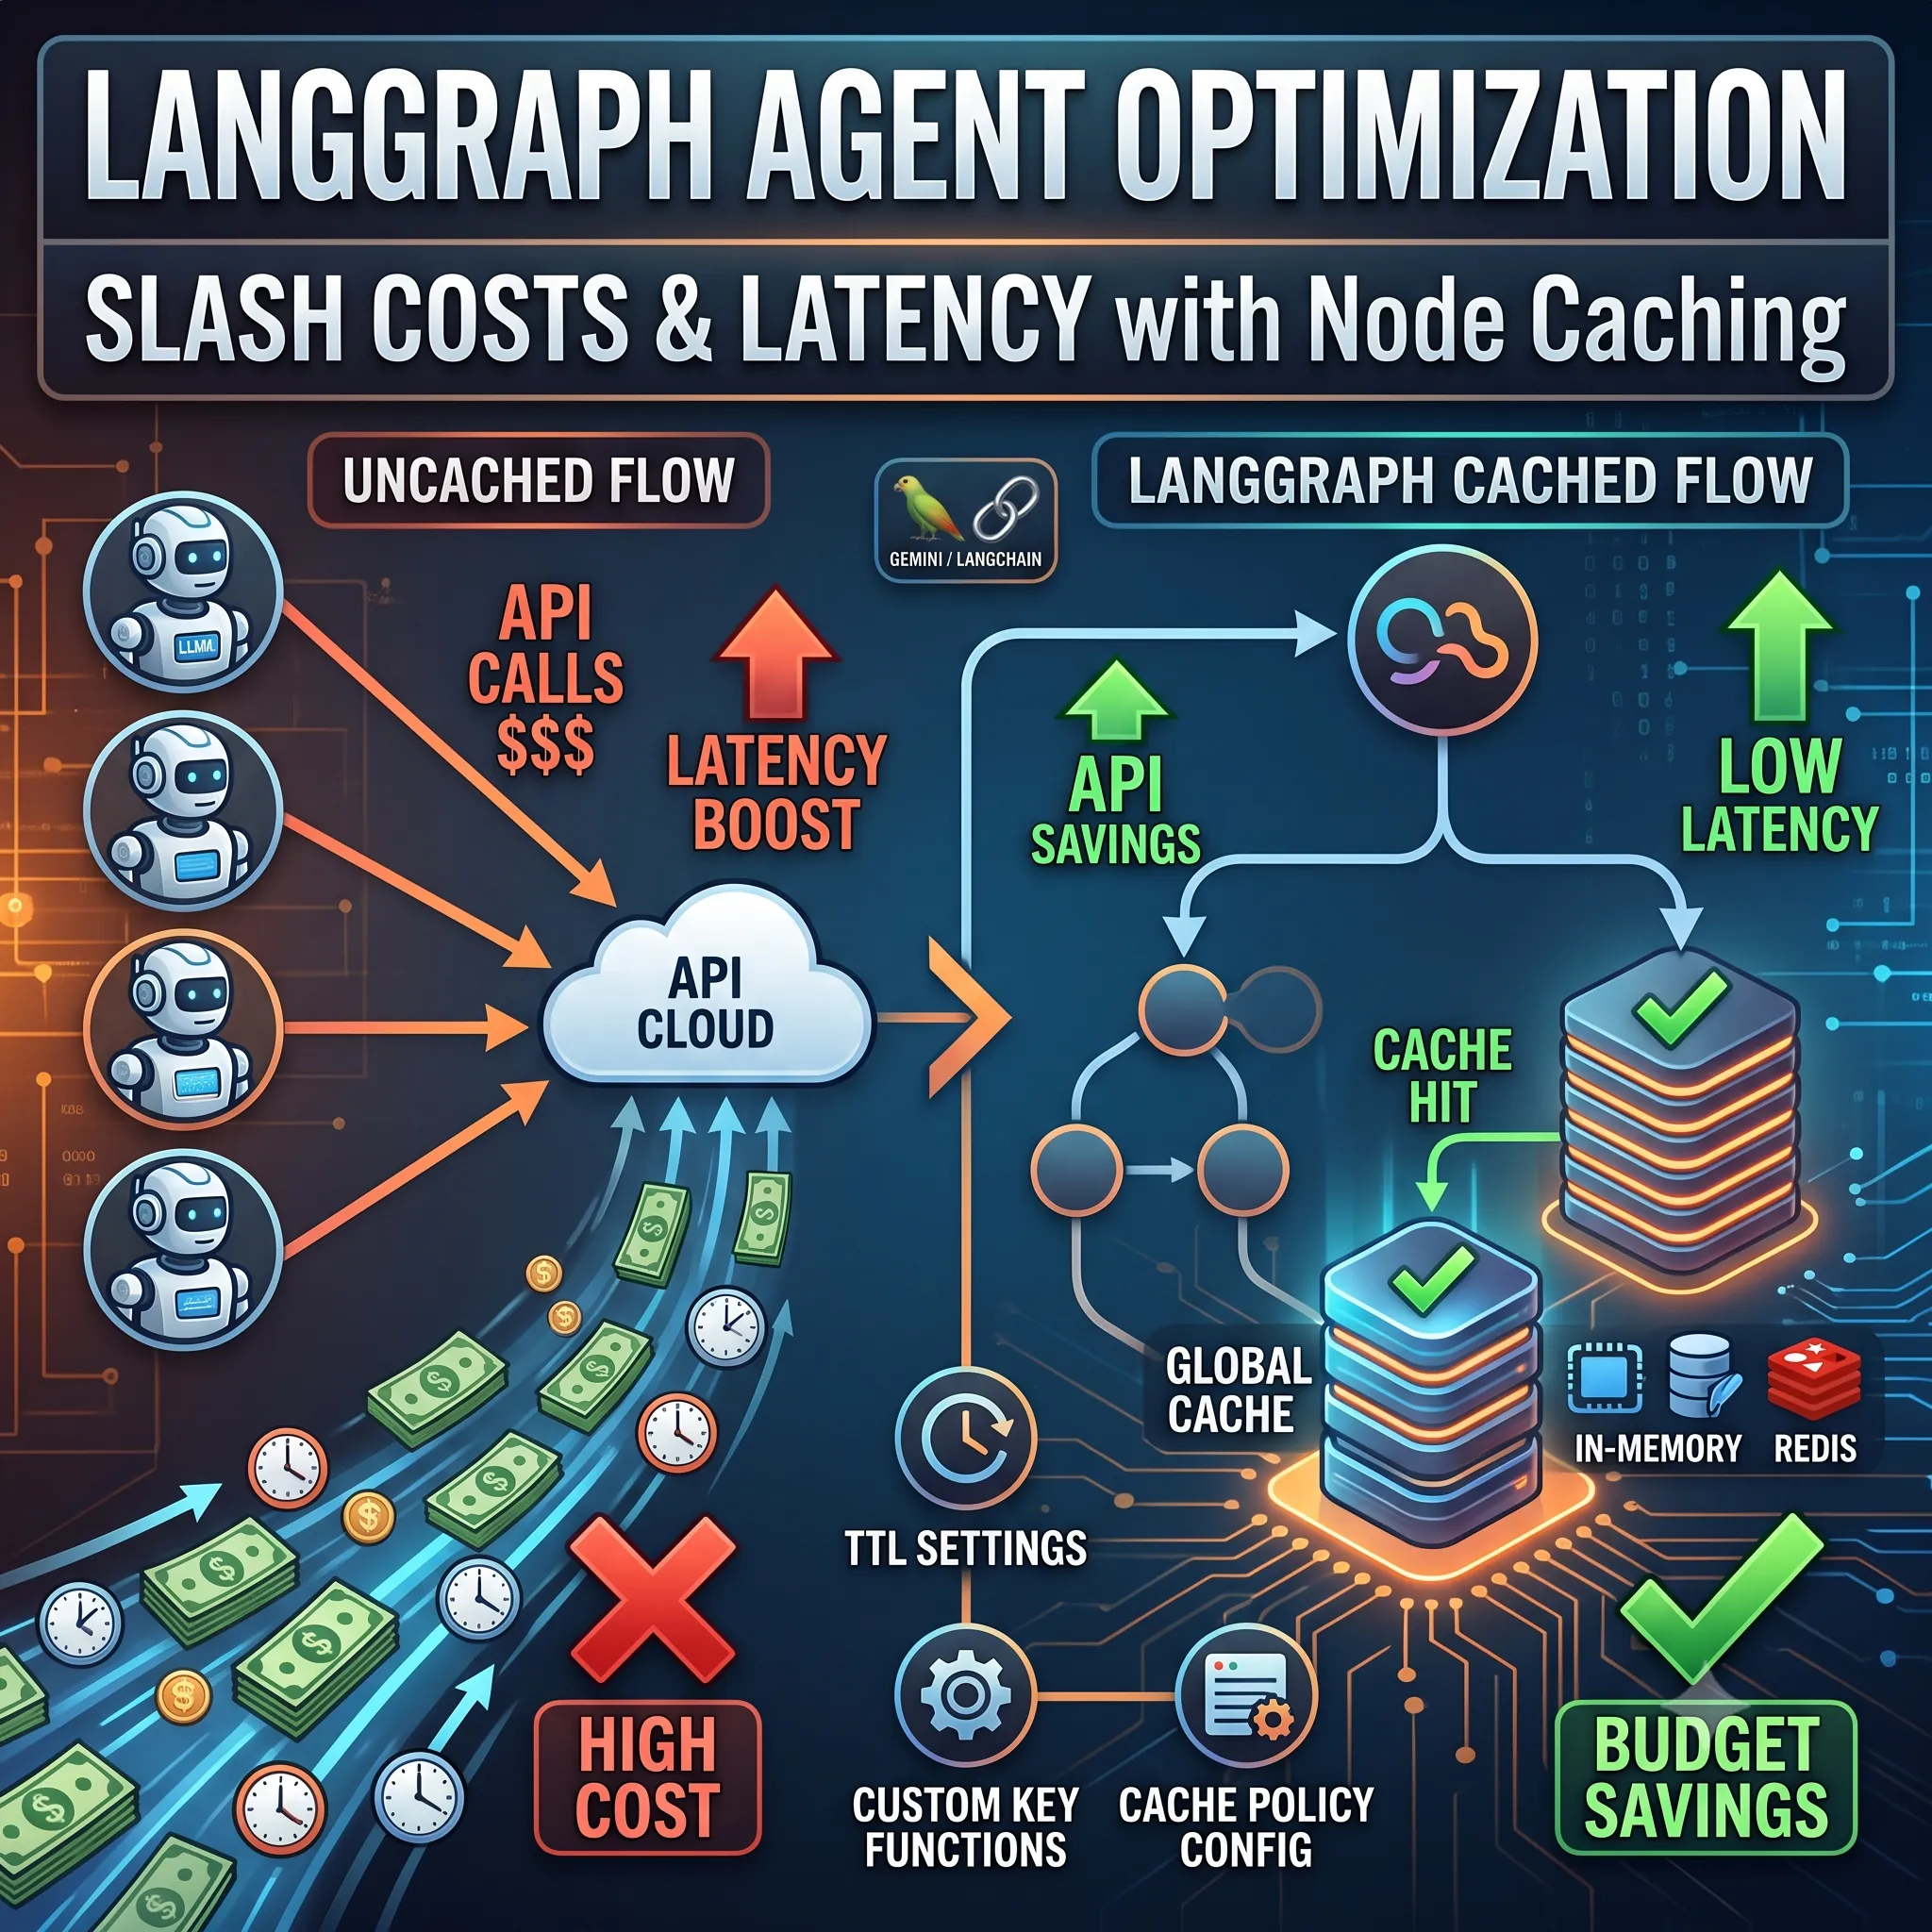
Optimizing LangGraph Agent Workflows with Node-Level Caching
Learn how to optimize LangGraph agent performance by implementing node-level caching, custom CachePolicy configurations, and distributed storage backends.
Seamless CI/CD for AI Prompts: Promptfoo for Quality, Security, and Evaluation
Learn how Promptfoo integrates into CI/CD pipelines to automate LLM prompt evaluation, security scanning, and ensure quality and reliability for AI...
DeepSeek-V4-Flash: Revolutionizing AI with 284B MoE, 1M Context & Unprecedented Efficiency on DeepInfra
DeepSeek-V4-Flash: The 284B MoE LLM revolutionizing AI with 1M context, extreme efficiency, speed, and competitive DeepInfra pricing.
Google DiffusionGemma Unveiled: Open-Source LLM Achieves 4x Faster Text Generation via Novel Diffusion & MoE Architecture for Real-Time AI
Google has released DiffusionGemma , an experimental open-source LLM introducing a novel text diffusion method for simultaneous text block generation. It...
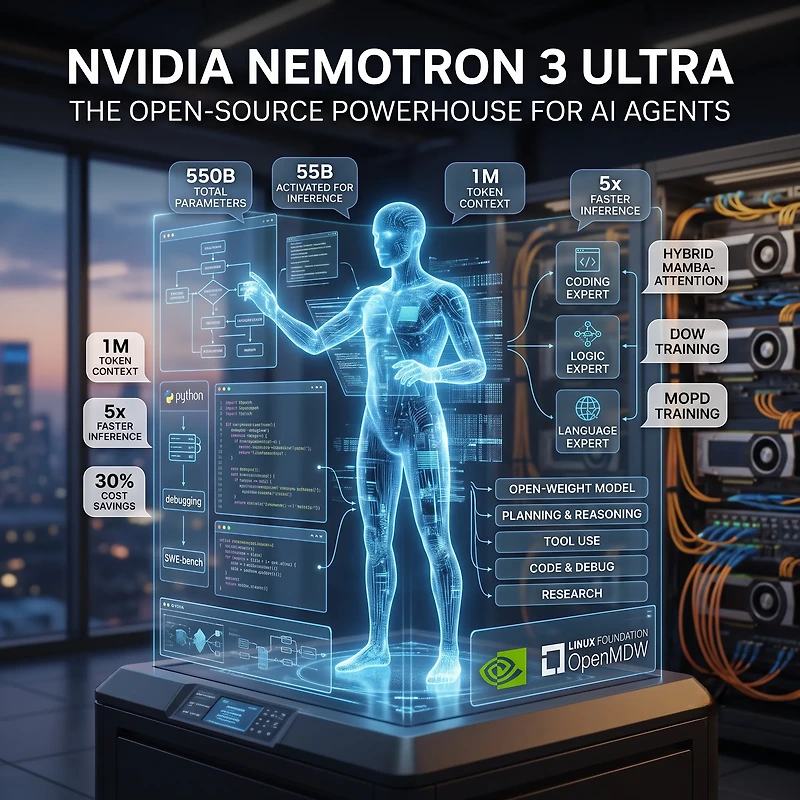
NVIDIA Nemotron 3 Ultra: Open-Source LLM Empowers Next-Gen AI Agents with 5x Faster Inference & Advanced Reasoning
NVIDIA Nemotron 3 Ultra is a new open-source, open-weight Mixture-of-Experts (MoE) model designed for AI agents to perform complex, long-duration tasks. It...