
Guide to Tripling Productivity with a Multi-AI Combination: ChatGPT, Claude, Gemini, Grok, Llama in August 2026
🚀 Key Takeaways
- The AI competitive landscape has rapidly evolved beyond simple chatbots to sophisticated, multi-modal intellectual working environments.
- ChatGPT maintains its position as the most accomplished all-rounder and versatile intellectual collaborator for diverse tasks.
- Claude excels in rigorous textual analysis, complex coding, and nuanced long-form writing, suited for serious analytical work.
- Google Gemini's primary strength lies in its deep integration across Google's vast ecosystem and strong multimodal capabilities.
- xAI Grok has emerged as a formidable frontier competitor, designed for long-running agents, complex coding, and research.
- Meta Llama offers essential open-weight models, fostering innovation and providing critical alternatives for private deployments.
- The transition is towards agentic AI systems that perform intellectual work through sequences of actions and tool use, significantly boosting productivity.
The landscape of artificial intelligence is transforming at an extraordinary pace, moving rapidly beyond basic conversational interfaces. What were once merely "large language models" have evolved into sophisticated systems capable of deep reasoning, external search, multimodal analysis, and executing complex sequences of actions.
By August 2026, leading AI platforms like ChatGPT, Claude, Gemini, Grok, and Llama offer distinct advantages, enabling practitioners to build powerful cross-workflows. This guide explores how to leverage their unique strengths to potentially triple productivity in real-world professional settings.
The competition has shifted from basic question-answering to developing comprehensive intellectual working environments, where the ability to complement human judgment and perform intricate tasks through agentic capabilities defines success.
By August 2026, leading AI platforms like ChatGPT, Claude, Gemini, Grok, and Llama offer distinct advantages, enabling practitioners to build powerful cross-workflows. This guide explores how to leverage their unique strengths to potentially triple productivity in real-world professional settings.
The competition has shifted from basic question-answering to developing comprehensive intellectual working environments, where the ability to complement human judgment and perform intricate tasks through agentic capabilities defines success.
1. The Evolving AI Landscape: From Conversationalists to Intellectual Work Environments
This section provides the critical backdrop for our main topic on creating a cross-platform AI workflow for productivity.By understanding the rapid shift from simple conversational models to complex, agentic systems, we can see why a single AI is no longer sufficient and why a multi-tool strategy—the core of this guide—is now essential for performing advanced intellectual work.
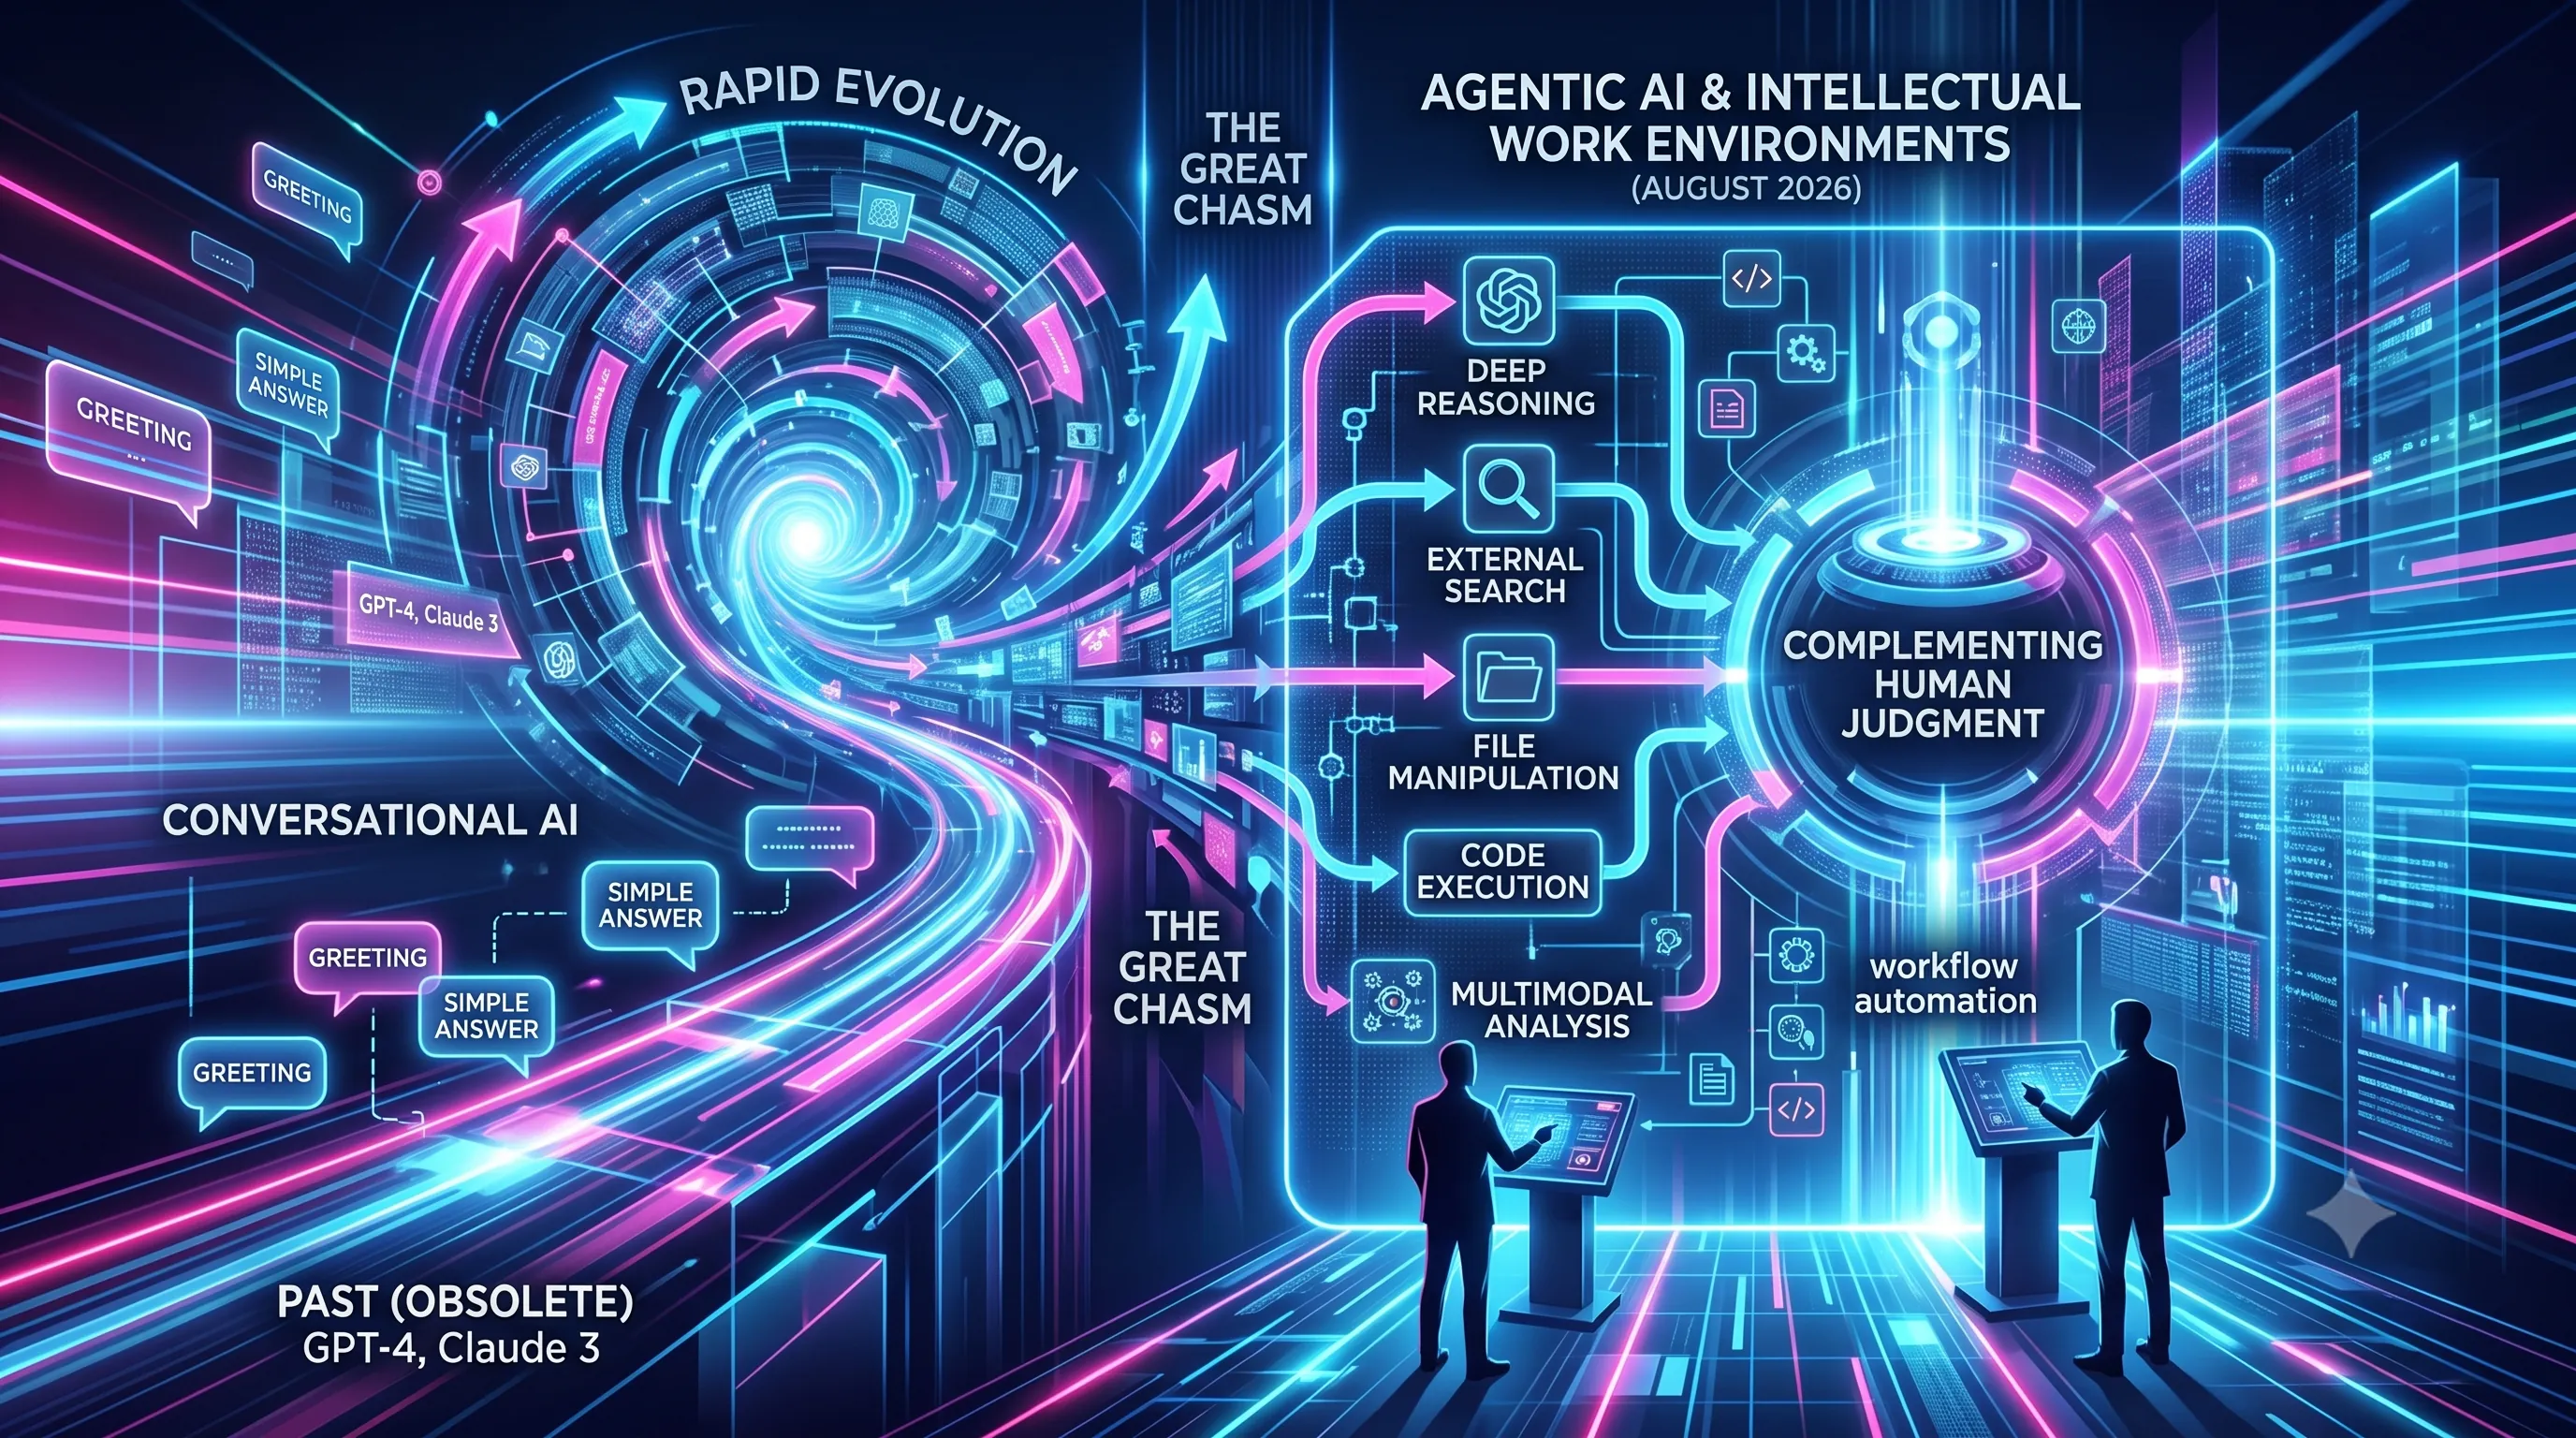
AI's Accelerated Evolution and Obsolescence
The primary difficulty in analyzing the AI space is that any direct comparison of models becomes obsolete with extraordinary speed.In the field of artificial intelligence, six months is now considered an historical epoch.
As of this writing in August 2026, the competitive landscape has already moved several generations beyond the models that defined the previous era, such as GPT-4, Claude 3, and Gemini 1.5.
The sheer velocity of development means that the differences between the leading models of today are often less significant than the vast chasm separating all of them from their predecessors.
Beyond LLMs: Reasoning, Tools, and Agentic AI
The very expression “large language model” is proving increasingly inadequate to describe today's leading systems.Where the first generation of generative AI was impressive simply because machines could converse, and the second was notable because they could reason, the emerging generation is significant for its ability to act.
These systems no longer merely predict and generate text; they can now reason, search external sources, analyze images, manipulate files, and both write and execute computer code.
Critically, they can undertake complex sequences of actions using a variety of tools to pursue objectives.
This evolution gives rise to Agentic AI—systems designed to perceive their environment, set their own goals, plan sequences of actions, and use external tools to accomplish them.
It is this capability for AI-driven workflow automation that is directly responsible for massive boosts in productivity.
The Shift to Intellectual Work and Human Complementarity
This technological leap changes the entire basis of competition.We are no longer comparing electronic conversationalists.
Instead, the comparisons are now between what can only be described as "embryonic general-purpose intellectual working environments."
The fundamental transition in AI's role is from answering questions to performing intellectual work.
Consequently, the race between AI companies is no longer just about model performance but over the foundational architecture through which human beings will increasingly undertake their intellectual labor.
In this new paradigm, the ultimate victor may not be the model that achieves the highest examination score.
Rather, it is likely to be the system that best learns how to complement and augment human judgment, fundamentally transforming how we approach complex tasks.
2. OpenAI's ChatGPT: The All-Rounder and Intellectual Collaborator
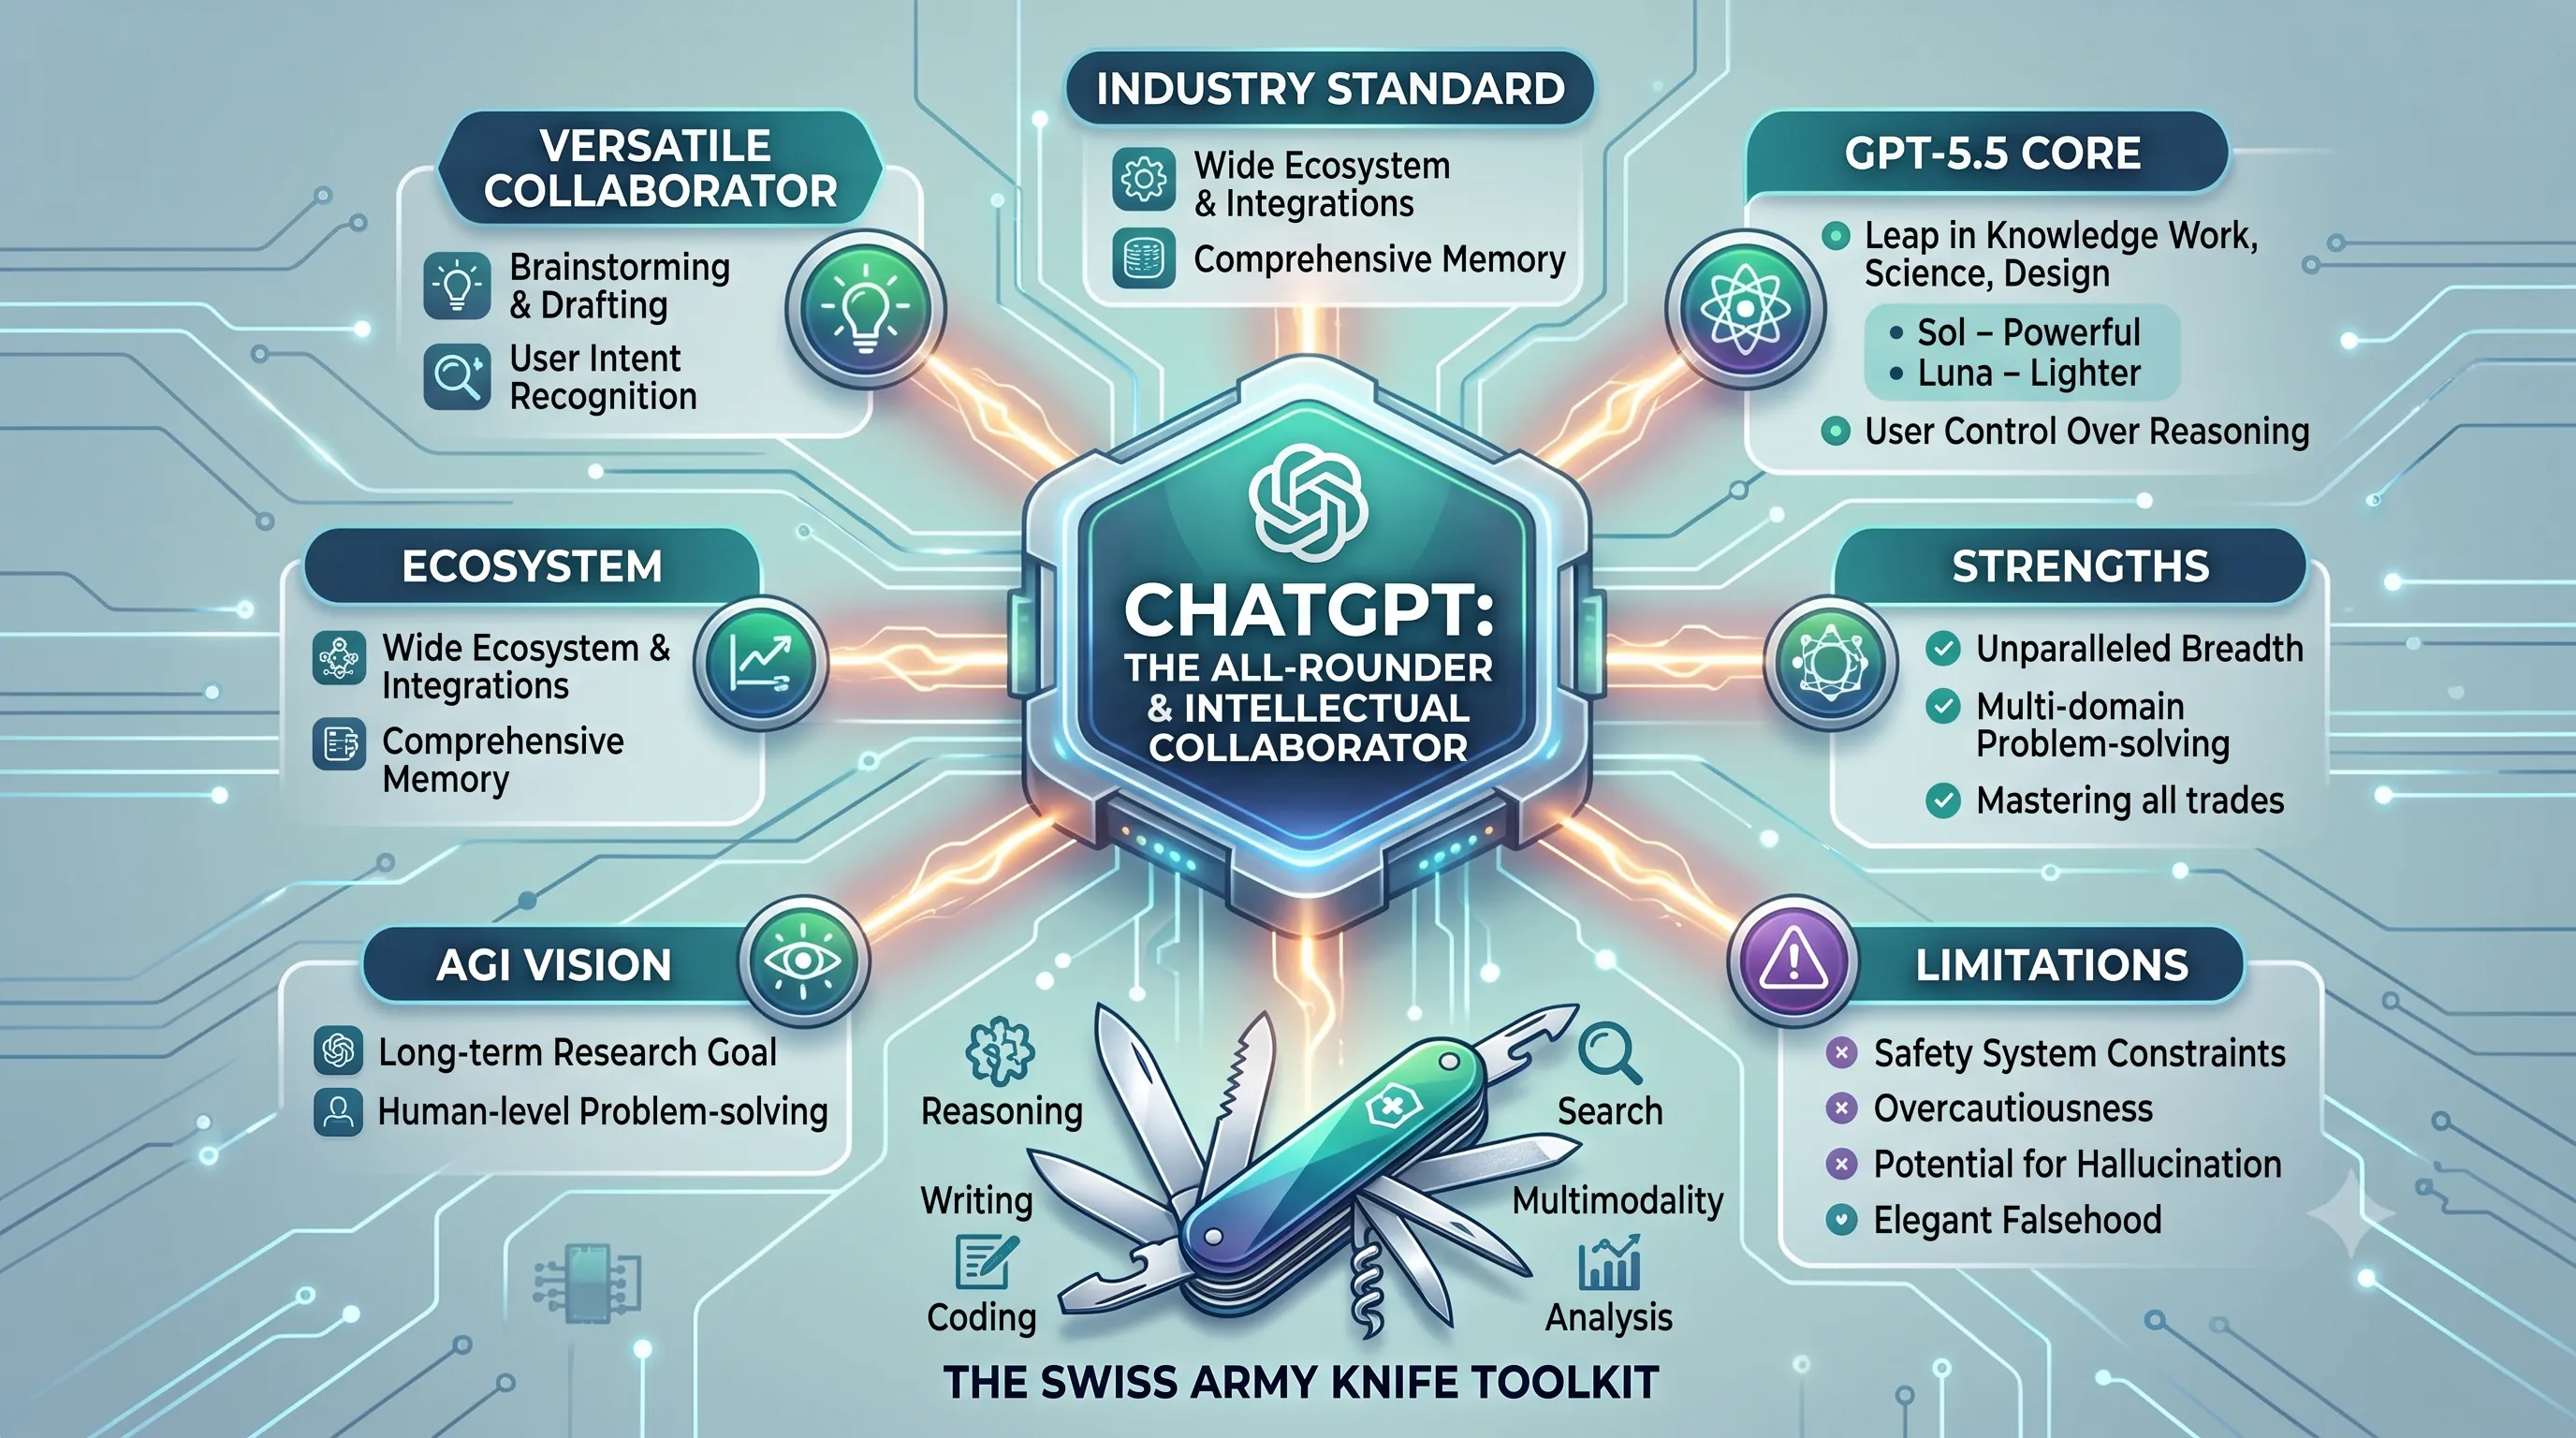
This section explores ChatGPT, the foundational tool and intellectual hub in our three-part AI workflow. Its unmatched versatility and broad capabilities make it the ideal starting point for nearly any task, serving as the central "command" from which we delegate more specialized work to other AIs. It’s the reliable generalist that handles the initial brainstorming, drafting, and multi-domain problem-solving before a specialist tool is required.ChatGPT as the Industry Standard and Versatile Collaborator
Since OpenAI effectively established the modern consumer market for conversational AI, ChatGPT has remained the standard against which all other general-purpose models are judged.Its persistent goal has been to unify reasoning, writing, multimodality, and tool use within a single, cohesive product.
This makes it particularly effective as an intellectual collaborator rather than just a simple tool.
A key to its success is its ability to understand user intent; it can distinguish between a request for a detailed explanation, a critical review, a first draft, an investigation, or pure speculation.
This nuanced understanding allows it to retain stylistic instructions and contextual assumptions across a conversation, while still being capable of challenging them when appropriate.
It is these "softer qualities" that keep it exceptionally strong in the market.
Further cementing its central role is the fact that ChatGPT has the widest ecosystem and integrations, along with the most comprehensive memory and personalization features available as of August 2026.
For these reasons, it serves as the best all-purpose default—the "Swiss army knife" of AI models in a professional's toolkit.
GPT-5.5: Advances in Knowledge Work and Reasoning
At the core of OpenAI’s current offering is GPT-5.5, a model presented specifically as a leap forward in knowledge work, science, design, and cyber capabilities.This model is deployed in two tiers: GPT-5.5 Sol is the more powerful version available to Plus and Pro users, while GPT-5.5 Luna serves as the lighter, default offering for Free and Go users.
A significant philosophical shift has been the introduction of greater user control over the amount of computational reasoning dedicated to a response.
This reflects a new paradigm where ChatGPT is becoming a system capable of deciding, or being instructed by the user, on how much intellectual effort a particular problem deserves.
For a practitioner, this means you can allocate maximum power for complex scientific analysis but use a more efficient mode for simple email drafting, directly optimizing resource use for productivity.
This evolution aligns with OpenAI's long-term research goal of eventually creating artificial general intelligence (AGI), a system that can solve human-level problems.
Strengths and Limitations: Breadth, Hallucinations, and Safety
ChatGPT’s greatest strength is its unparalleled breadth.The model is unusually competent at moving between activities that human professionals regard as quite different, making it an indispensable all-rounder.
However, this versatility comes with trade-offs.
To serve an enormous and varied user base, it is necessarily constrained by safety systems and product design, which can sometimes lead it to be overcautious.
Furthermore, like every contemporary model, ChatGPT can still hallucinate.
While the enormous progress of the technology has diminished this problem, it has not been eliminated.
Its fluency remains a double-edged sword, as an elegantly expressed falsehood can appear more authoritative than a hesitant truth.
Finally, while it is a master of all trades, it may have fewer built-in productivity features than certain competitors in very specific categories.
Despite these limitations, ChatGPT likely remains the most accomplished all-rounder and retains the crown as the most convincing general-purpose intellectual collaborator in August 2026.
However, the margins are narrow, the competitors are formidable, and its crown has never been less secure.
3. Anthropic's Claude: The Serious Contender for Rigorous Analysis
This section connects to the main topic of a three-AI cross-workflow by positioning Claude as the specialist for deep, analytical tasks.While other models might be used for rapid ideation or creative generation, Claude serves as the team's dedicated analyst, programmer, and legal expert.
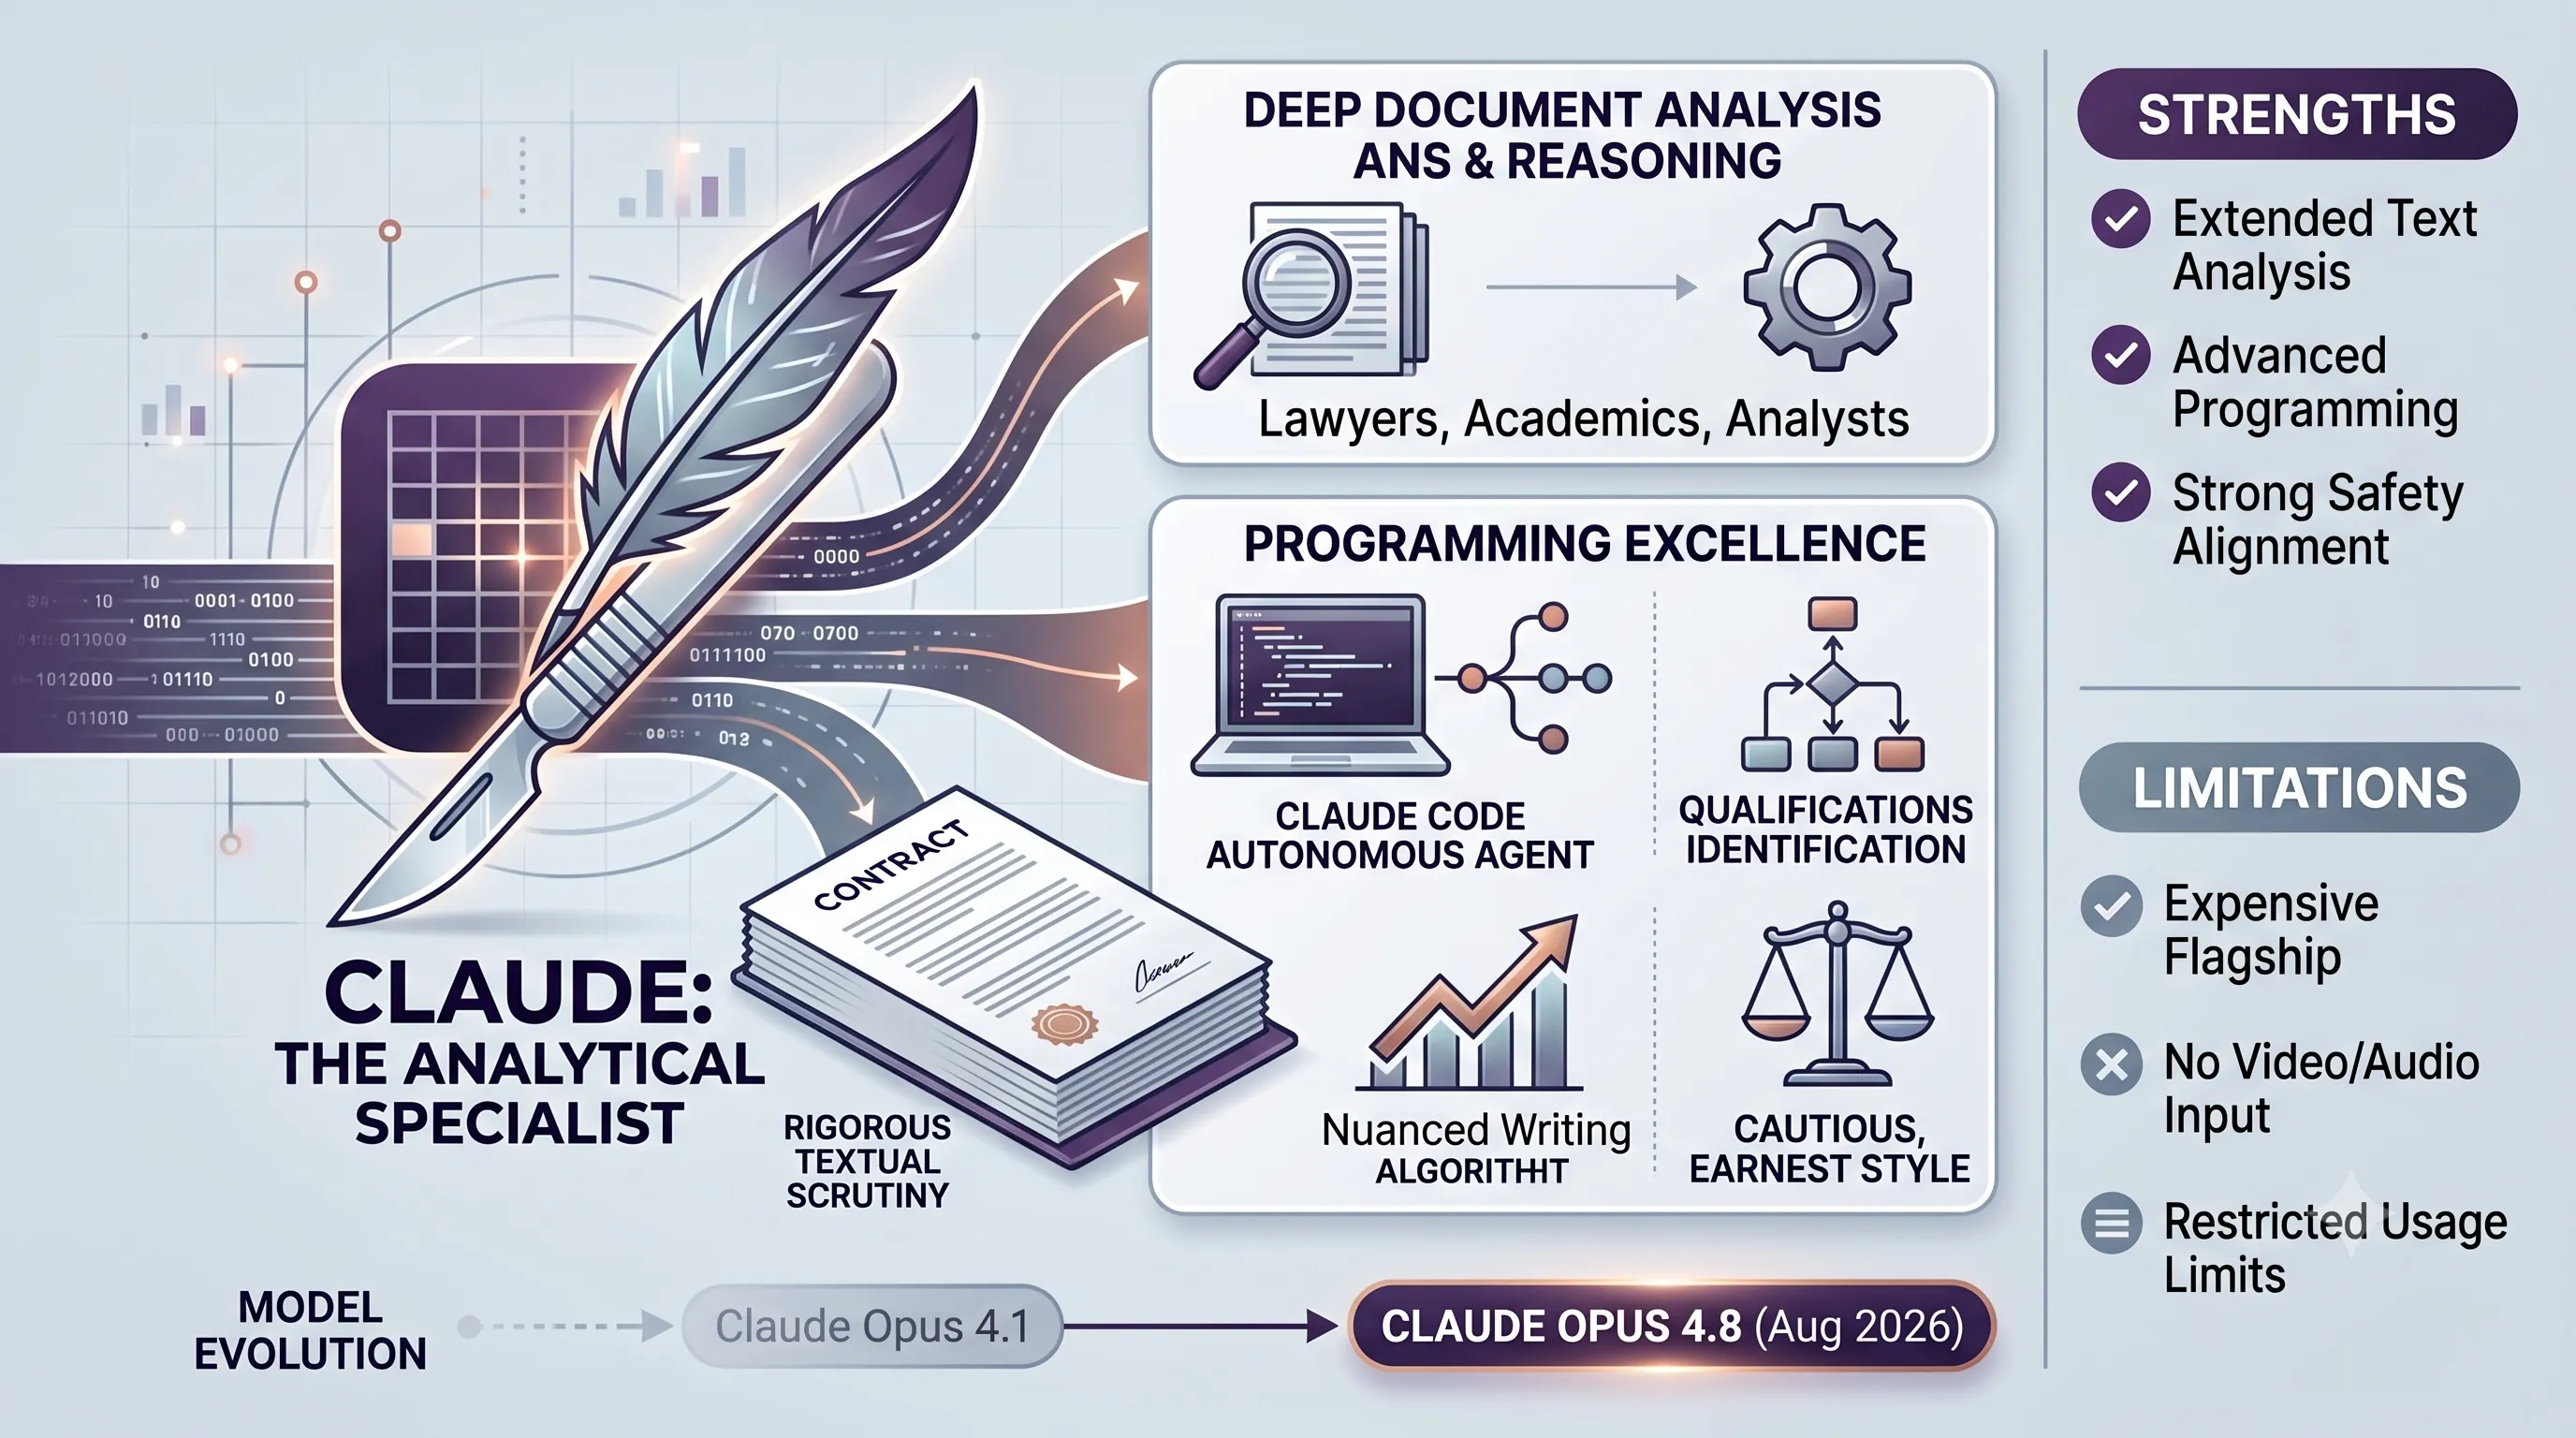
It is the "surgeon's scalpel" you bring in when a task demands rigorous scrutiny, structured reasoning, and a high degree of precision, forming the analytical backbone of the modern professional's toolkit.
Claude's Analytical Prowess and Programming Excellence
Anthropic has developed its Claude models according to a somewhat different intellectual temperament than its rivals, with its distinctive virtue remaining its seriousness.This makes Claude particularly excellent when confronted with a large body of material that must be read carefully before conclusions are drawn.
It excels at document reasoning and analysis, a strength that makes it particularly attractive to professionals like lawyers, academics, and analysts who require prolonged textual scrutiny and austere analytical work.
This preference extends to programmers, as Claude is considered best for coding and nuanced writing.
Its capabilities are further enhanced by tools like Claude Code, a powerful autonomous coding agent.
The model tends towards orderly argument and is often good at identifying qualifications to propositions that another model might state too confidently, reinforcing its reputation for careful and structured reasoning.
Model Evolution: Claude Opus 4.8 and Its Significance
The artificial intelligence landscape is in constant flux, a reality underscored by Anthropic's own development cycle.By August 2026, the older Claude Opus 4.1 has been retired from Anthropic’s API, supplanted by substantially newer models.
Anthropic identified Claude Opus 4.8 as its replacement, a move that highlights the velocity of progress in the field.
The rapidity of this succession illustrates how little value should be attached to permanent league tables of artificial intelligence models, as capabilities and rankings can shift dramatically in short periods.
Despite these changes, Claude remains one of ChatGPT’s most formidable competitors for rigorous textual analysis, and there will be tasks for which an experienced user reasonably prefers Claude.
Character and Constraints: Serious Prose, Cost, and Multimodality Gaps
Interaction with the model reveals that there is something recognizably “Claude-like” about its prose, demonstrating that model personality remains a real differentiator.Claude’s output can be earnest, cautious, and occasionally over-structured.
This distinct style presents a trade-off: what constitutes a virtue in analyzing a contract may become a vice in writing an essay, satire, or polemic.
Beyond its personality, users must also contend with practical limitations.
| Key Strengths | Notable Limitations |
|---|---|
| Deep analysis of extended texts and documents. | The most expensive flagship model among its peers. |
| Advanced programming and structured reasoning. | No native video or audio input capabilities. |
| Strong safety and ethical alignment focus. | No built-in image generation functionality. |
| Nuanced writing with an orderly, cautious style. | Restrictive usage limits, especially for power users. |
However, for its target applications, Claude may still have a clear advantage for certain kinds of demanding analytical work.
4. Google's Gemini: Ecosystem Integration and Multimodal Frontier
In a cross-platform AI workflow designed for maximum productivity, Gemini's role is not just as a standalone model but as an integrated intelligence layer across the digital tools professionals use daily.Understanding its deep ecosystem integration and unique multimodal capabilities is key to leveraging it as the "connective tissue" in a multi-AI strategy, especially for tasks that blend search, document creation, and diverse media formats.
The Power of Google's Ecosystem Integration
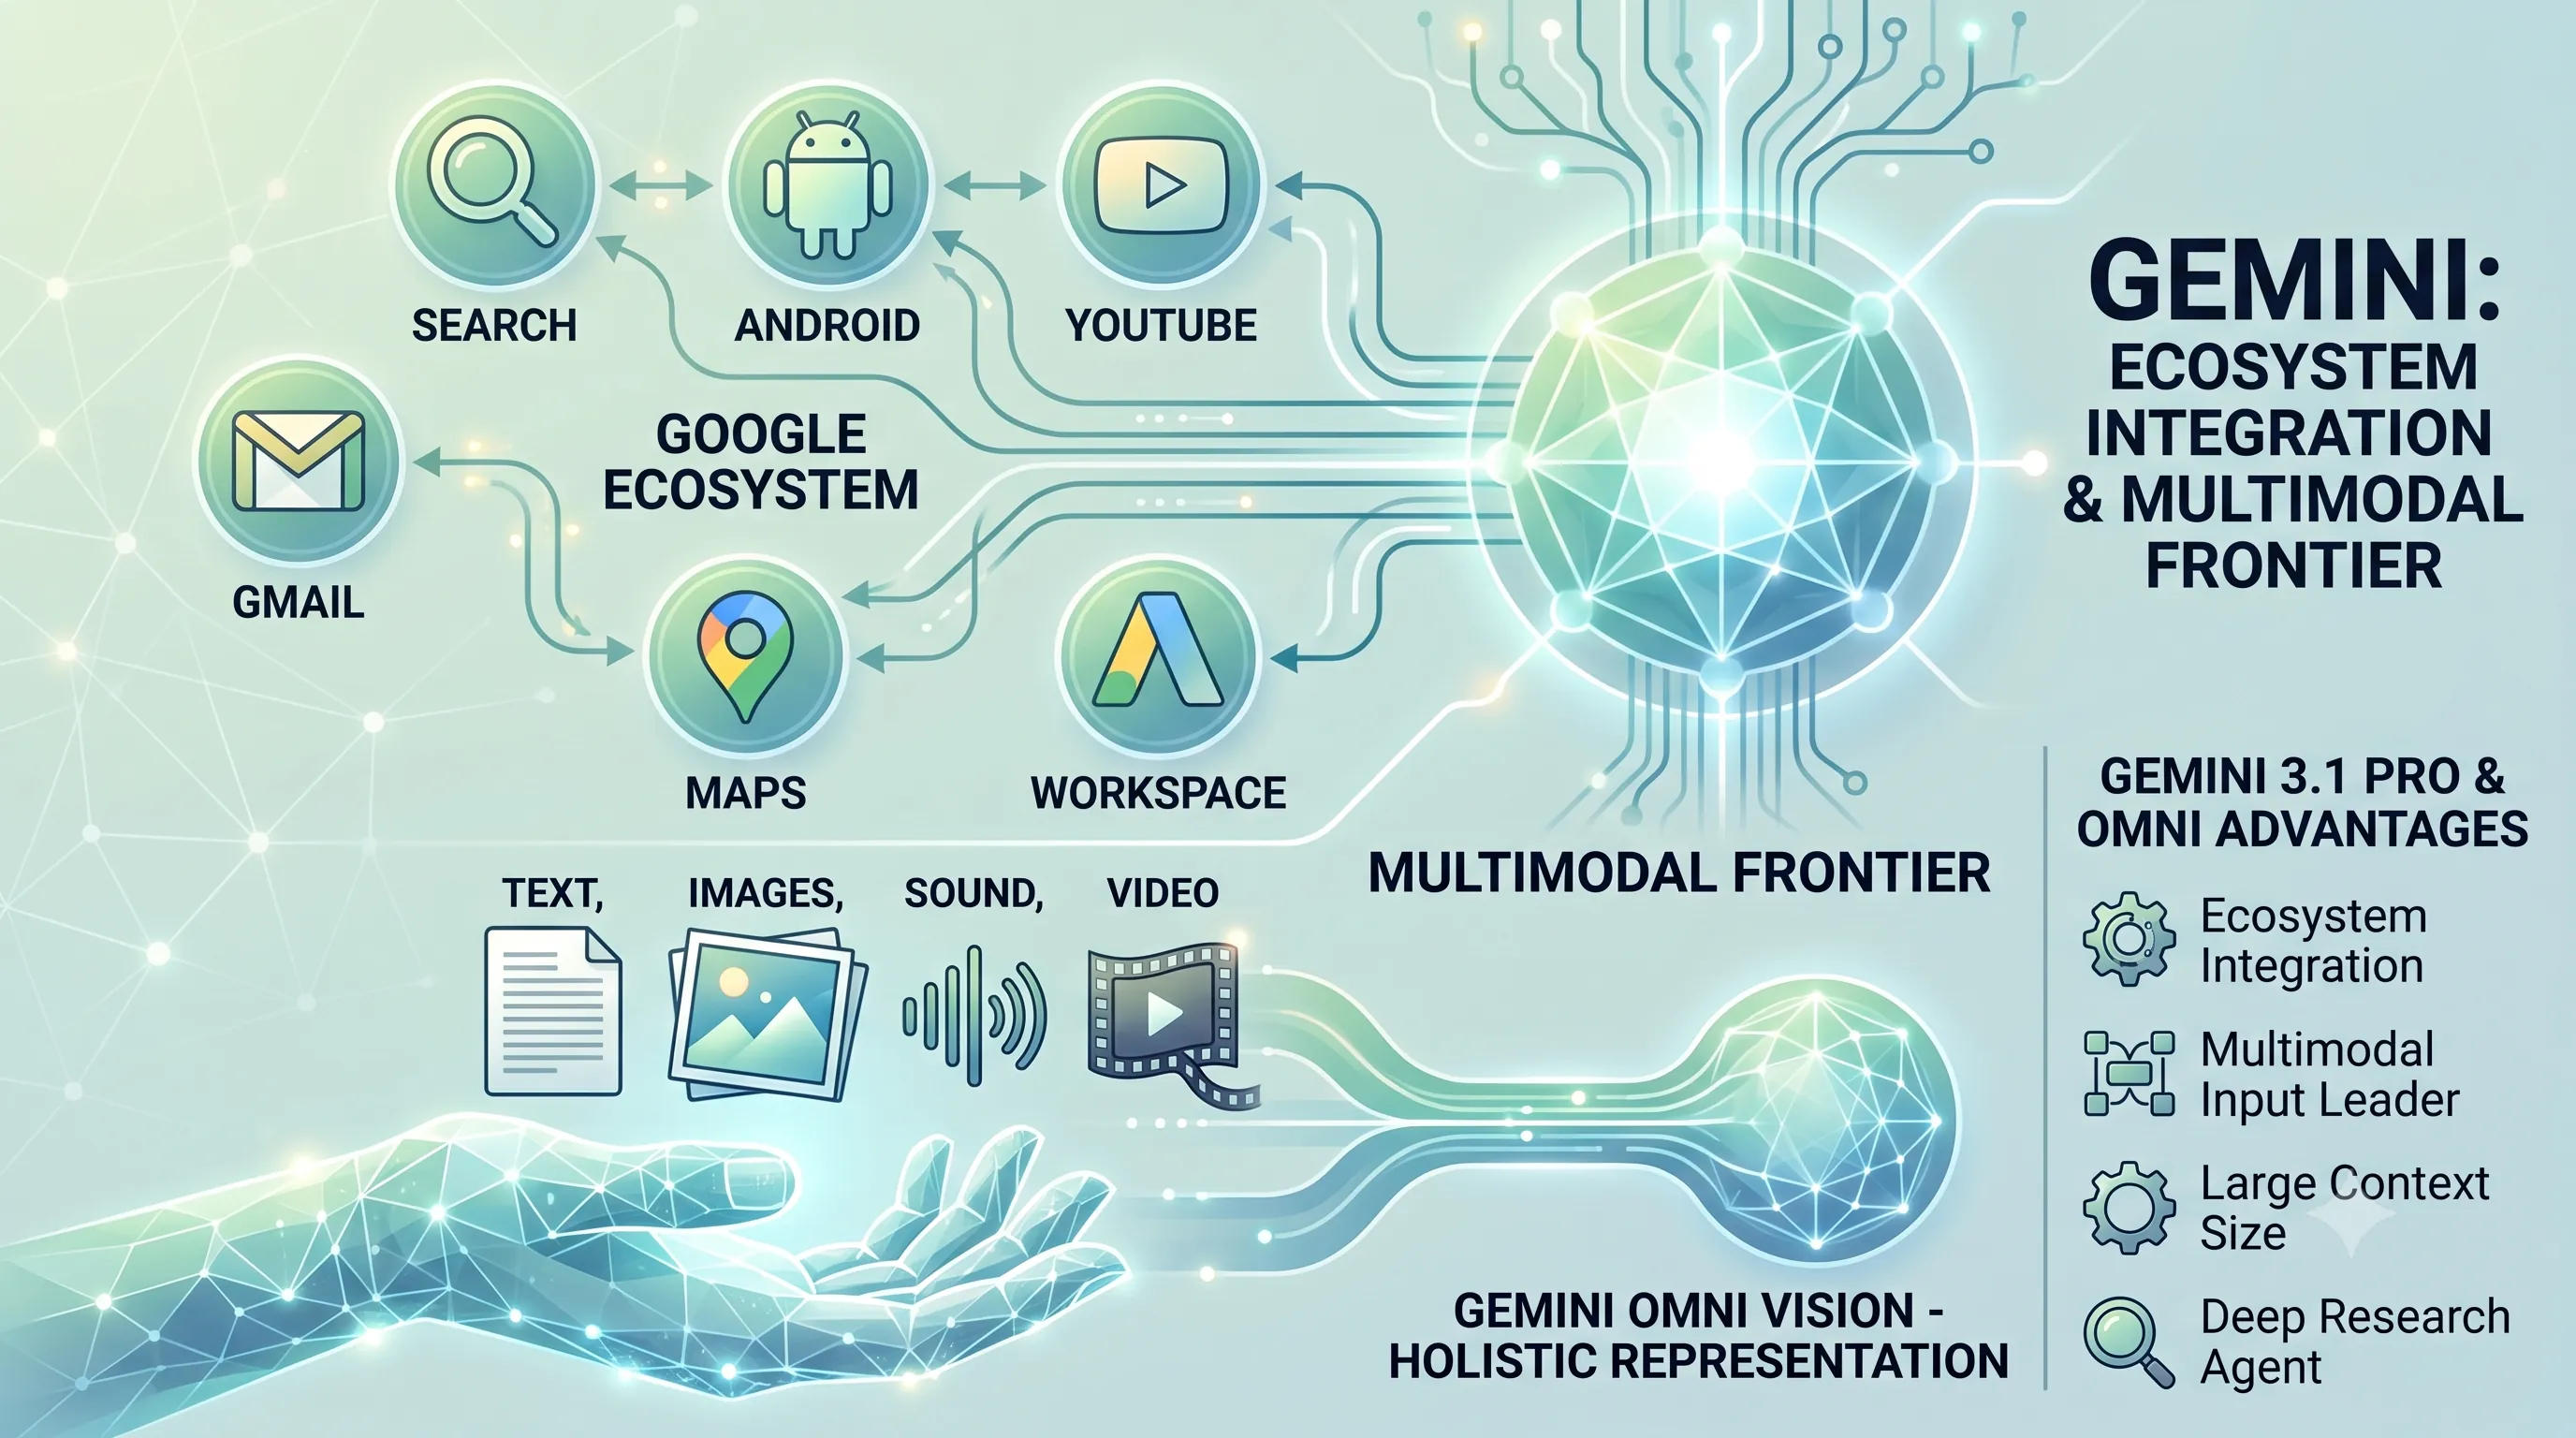
The strategic strength of Google Gemini lies not merely in the quality of its models but in the vast Google network surrounding them.Google possesses Search, Android, YouTube, Gmail, Maps, and Workspace, backed by an extraordinary collection of research and computational infrastructure.
This allows artificial intelligence to be integrated directly into activities that hundreds of millions of people already undertake every day.
While this provides an unparalleled structural advantage, users should be aware that full feature access is often contingent on a degree of Google ecosystem lock-in.
This deep integration makes Gemini a powerful tool for tasks like writing, planning, and brainstorming that are initiated or completed within Google's suite of products.
Gemini 3.1 Pro and the Multimodal Omni Vision
The Gemini model family itself has advanced considerably, having reached its third generation by mid-2026.Google introduced Gemini 3.1 Pro in February 2026, a natively multimodal reasoning model specifically directed towards solving difficult problems.
Beyond this, Google’s more ambitious Gemini Omni project points towards a future where text, images, sound, and video cease to be separate categories of information.
Omni is designed to accept combinations of these media and, in its initial stages, can produce and edit video conversationally.
An artificial intelligence that treats different forms of information as parts of one holistic representation of the world may acquire capabilities that are qualitatively different from those of the original language models.
Strengths in Distribution and Multimodality, with Benchmarking Gaps
Historically, Gemini's weakness relative to ChatGPT and Claude was less about raw capability and more about personality and consistency, but Google has steadily reduced that distinction.Gemini must now be regarded as a frontier competitor, not merely an answer to its rivals.
Its greatest prospective advantage may be distribution; if AI becomes embedded invisibly throughout ordinary computing, the winner may be the system already present in users' telephones, browsers, email, documents, and search engines.
Today, Gemini is extremely close to the foremost group for intellectual and professional work and is potentially superior for particular multimodal and ecosystem-dependent applications.
| Feature / Advantage | Description |
|---|---|
| Ecosystem Integration | Strong integration with Google Workspace, Search, Android, and Chrome for seamless workflows. |
| Multimodal Input | A leader in accepting and natively reasoning across diverse combinations of media types. |
| Context & Value | Leads on context size and value pricing, including a free tier with generous limits. |
| Deep Research Agent | Features a specialized agent for handling complex, long-running synthesis tasks. |
Gemini's writing can be less nuanced than that of Claude.
It also lags on certain technical benchmarks, scoring 68.3% on SWE-bench Verified for Gemini 3.1 Pro, indicating weaker performance in coding tasks compared to some specialized models.
5. xAI's Grok: The Unconventional, Long-Running Agent Specialist
This section connects to our main topic of a multi-AI workflow by introducing Grok as a highly specialized third pillar. Where other models may serve as general-purpose writers or creative partners, Grok is explicitly engineered for a different, more persistent class of work—long-running, complex agentic tasks—making it a crucial component for users who need an AI to execute multi-step projects autonomously.Grok's Evolution into a Frontier Competitor
For a long time, Grok was perceived primarily through its association with X and Elon Musk, but this is an increasingly inadequate description of the project. Any contemporary comparison of frontier AI models must now include Grok, which has developed into a genuine top-tier competitor. It now belongs in the first rank of AI systems in a way that was considerably less obvious during the initial years of the generative AI revolution. As such, the model deserves considerably more serious consideration than its earlier reputation sometimes attracts.Designed for Long-Running Agents and Complex Tasks
The release of Grok 4.6 in August 2026 cemented its position as a specialist tool for difficult, protracted assignments. xAI has explicitly designed the model for long-running agents, coding, research, and complex interactive and visual work. The architecture is described as capable of remaining engaged with tasks that extend across many steps, a crucial skill for projects involving deep research or work across large codebases. This focus suggests Grok may prove particularly formidable if, as many predict, long-running autonomous agents become the next decisive battleground in AI development.| Feature | Specification / Description |
|---|---|
| Model Version | Grok 4.6 |
| Release Date | August 2026 |
| Context Window | 500,000 tokens |
| Primary Design Focus | Long-running agents, coding, research, and complex interactive/visual work across large codebases. |
| Unique Capability | Adjustable reasoning effort. |
Distinctive Personality vs. Professional Reliability
Grok possesses an interesting cultural characteristic, having been deliberately positioned with a less conventional and more irreverent tone than its competitors. For users who dislike excessively sanitized corporate prose, this can make interactions with the model feel refreshing. However, this positioning also presents its primary long-term test: whether it can successfully combine a distinctive personality with the extraordinary reliability demanded of an AI entrusted with serious professional work. After all, irreverence and epistemic reliability are different virtues. The challenge for xAI will be to prove that its model's unique voice does not compromise its capacity for mission-critical accuracy and performance.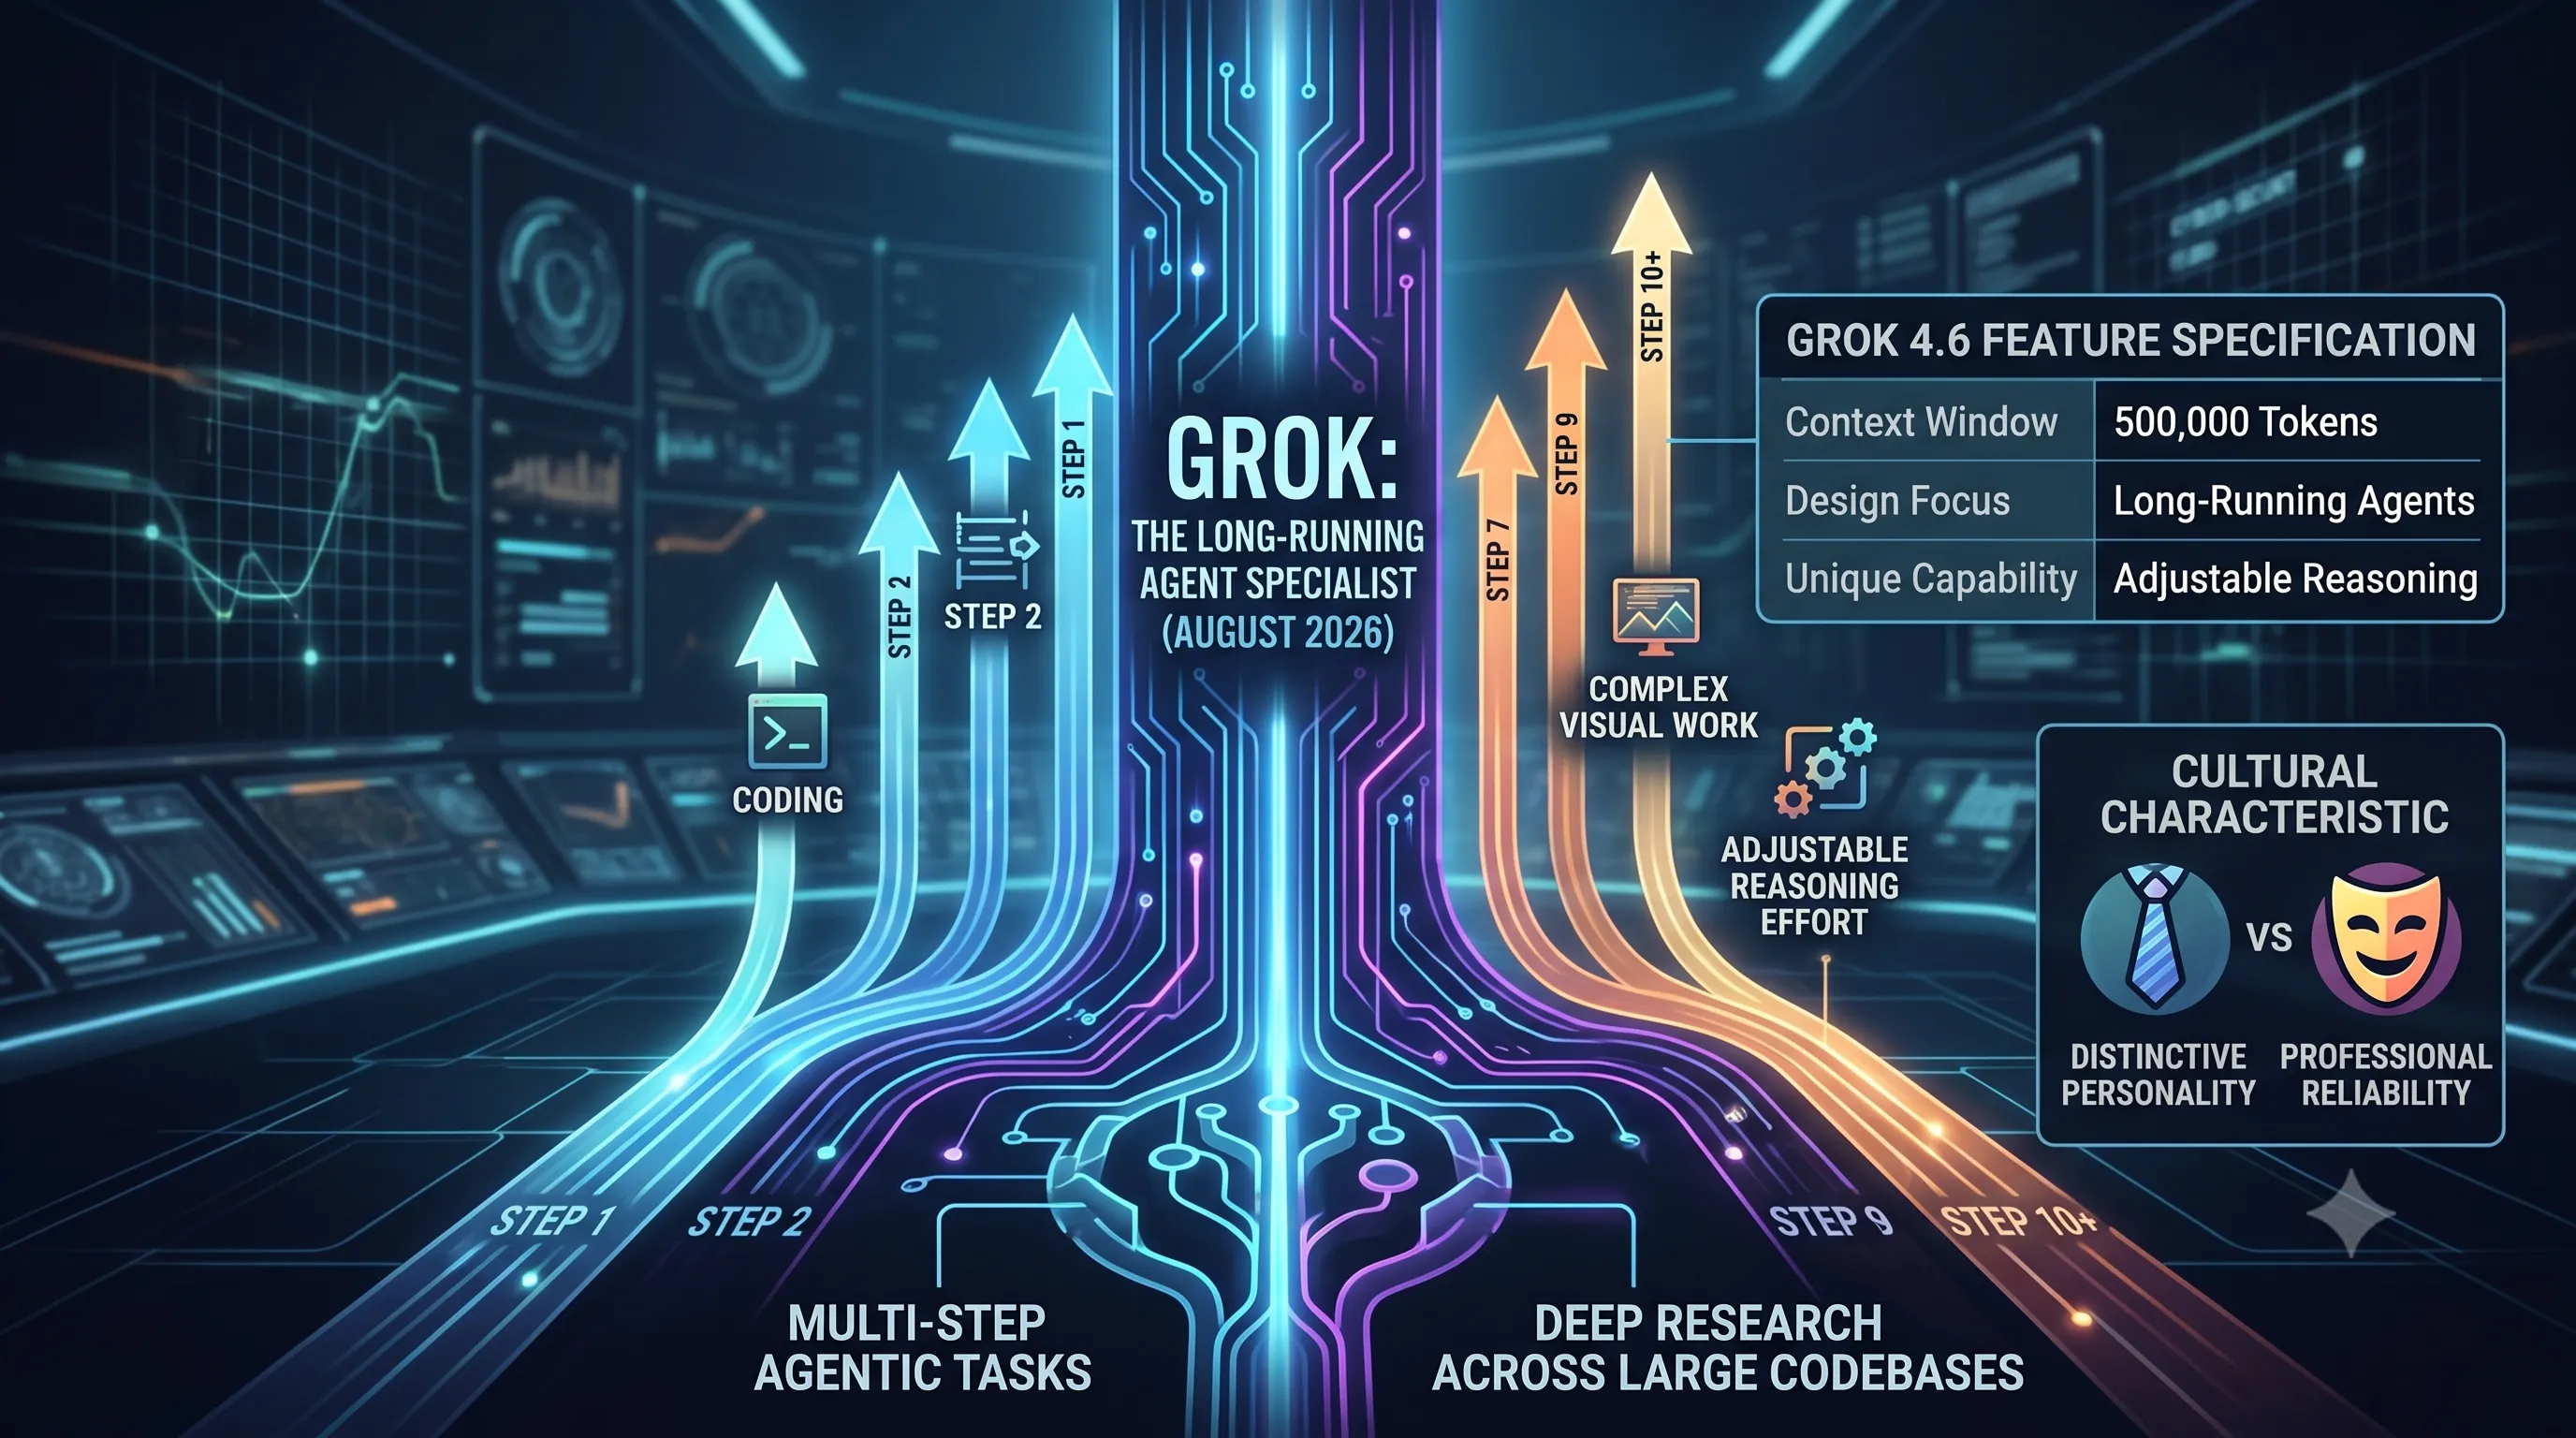
6. Meta AI's Llama: The Open-Weight Foundation for Custom Solutions
This section connects to our main guide on "A Guide to Tripling Productivity with a 3-AI Combination" by presenting the third pillar of a sophisticated AI workflow: the self-hosted, custom solution.While other AIs are treated as subscription services, Llama represents the technological infrastructure from which you can build a specialized, private, and fully controlled AI tool.
It is the "build" option in a "buy, buy, build" strategy, offering unparalleled customization for specific business needs.
Llama's Strategic Role as an Open-Weight Model
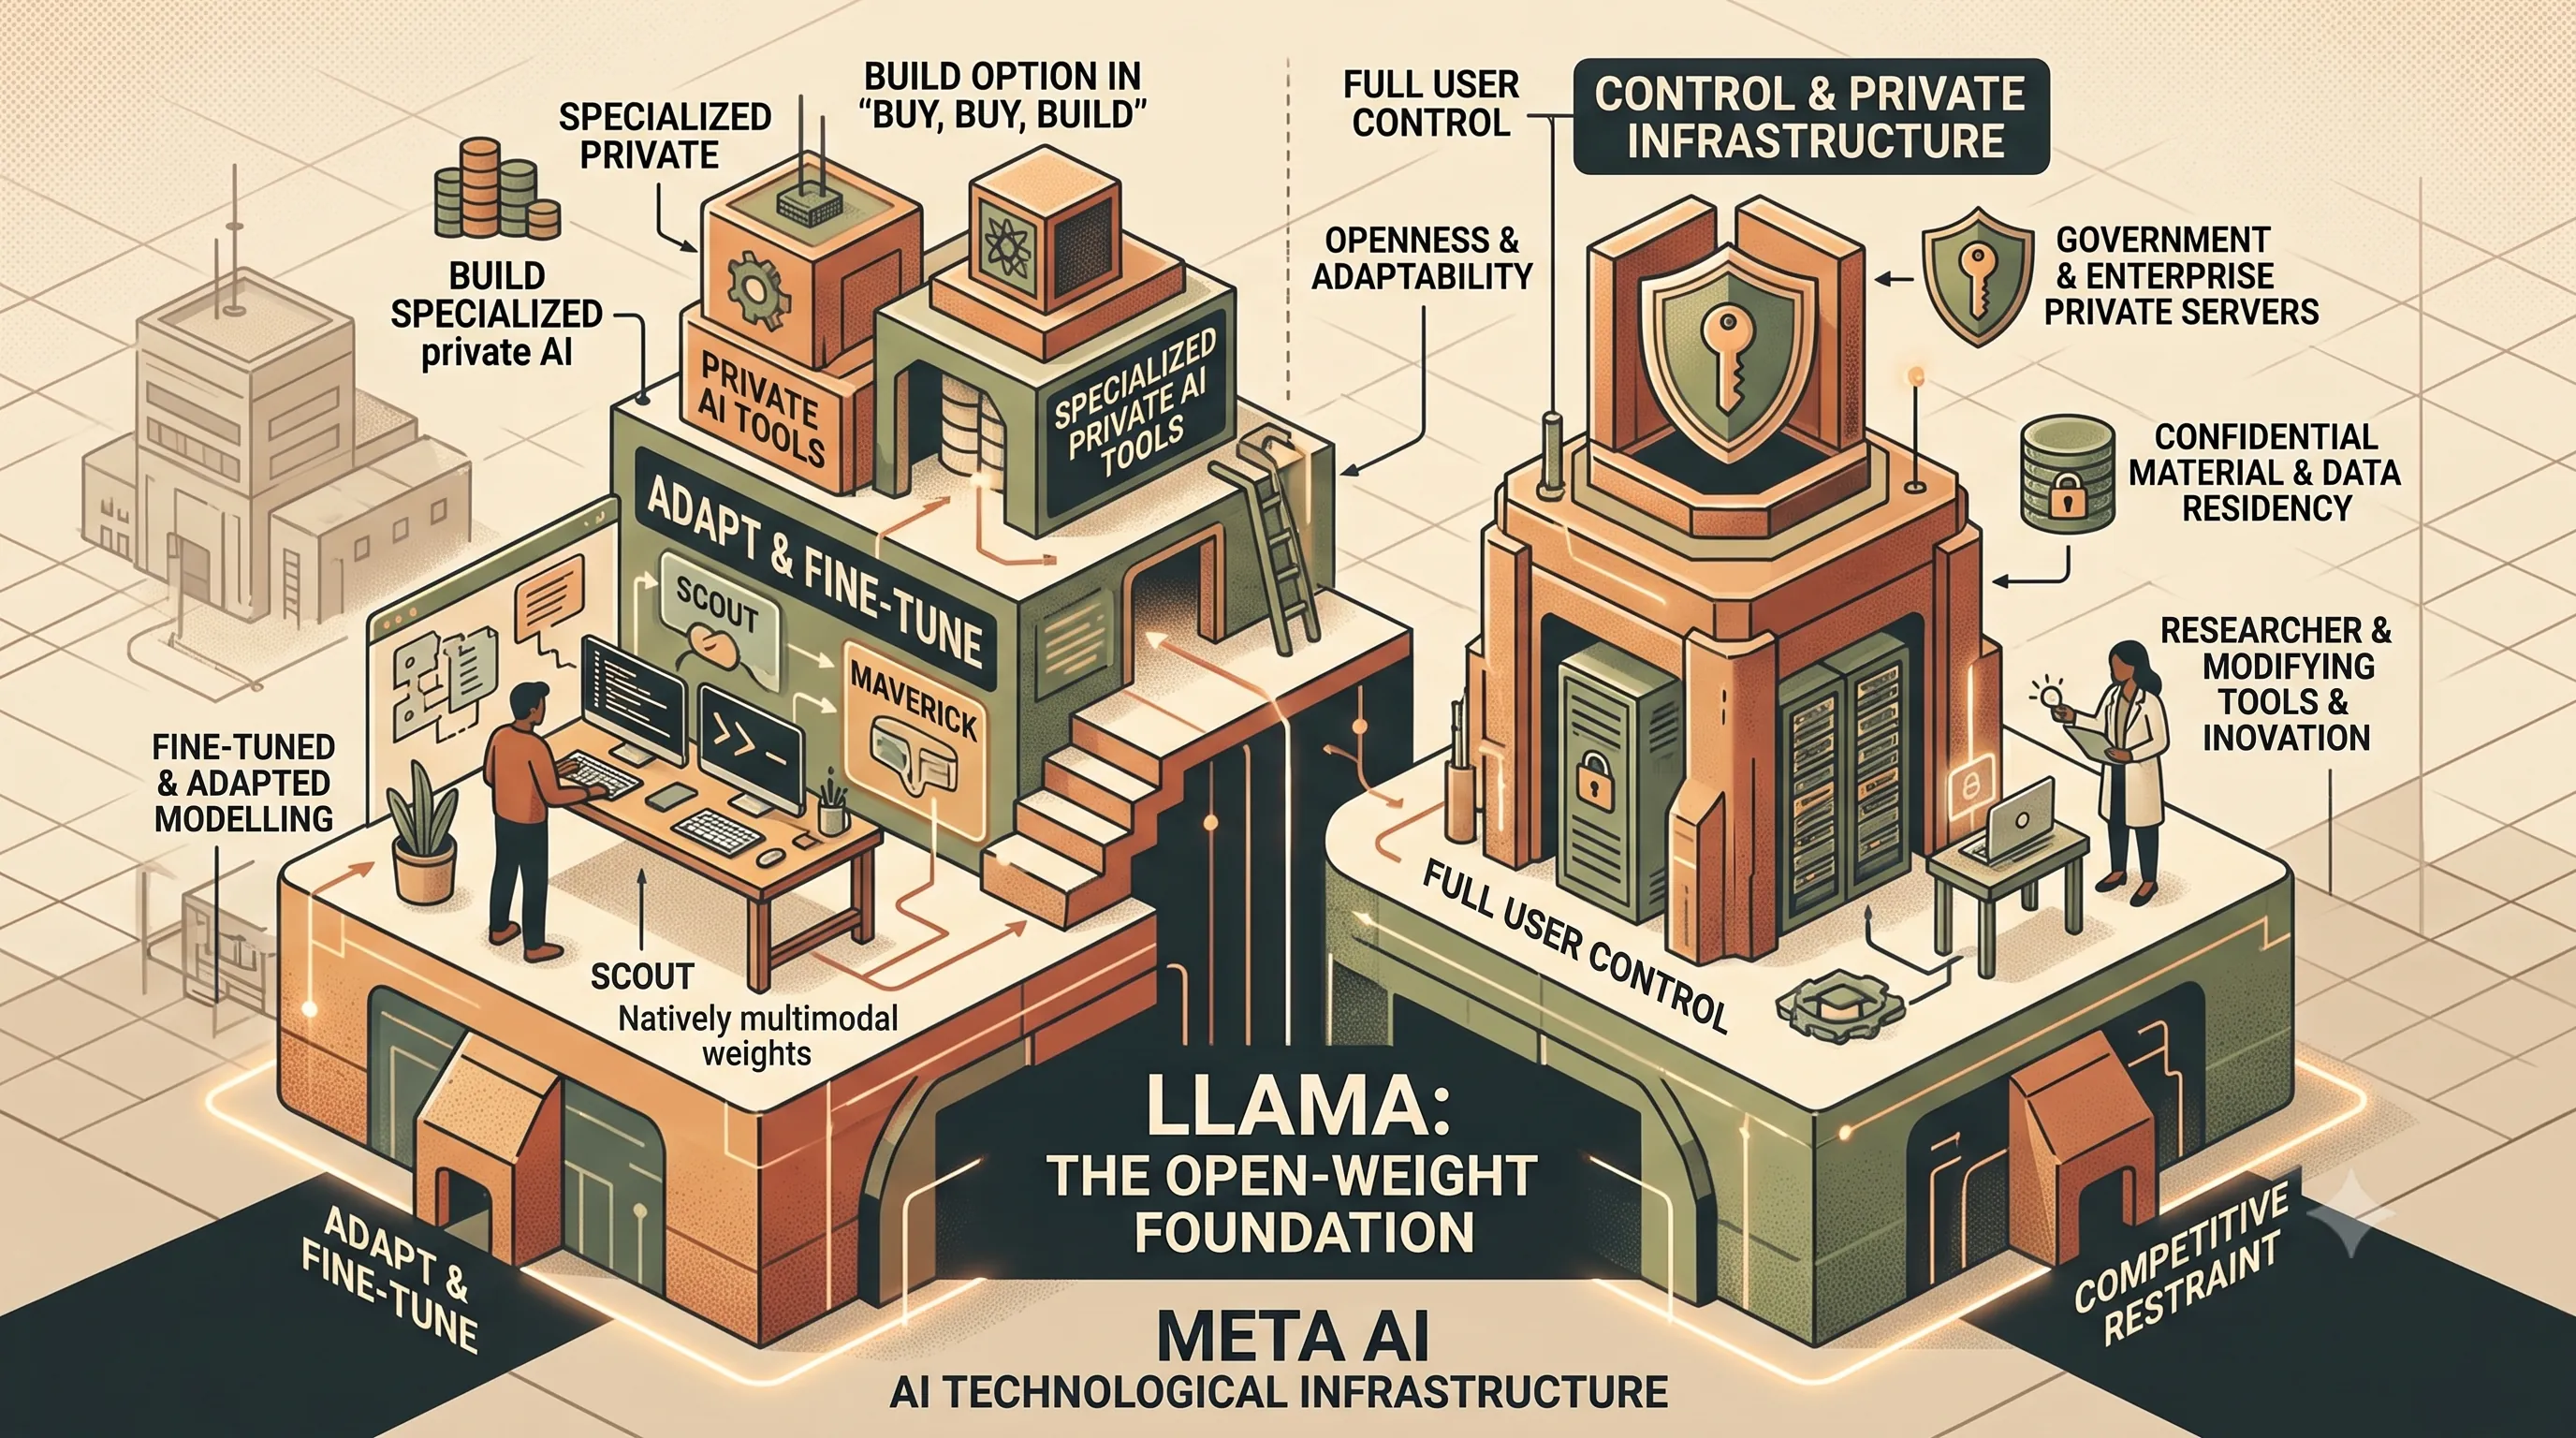
Meta AI and its Llama series of models occupy a fundamentally different strategic position in the AI landscape.Direct comparisons with integrated products like ChatGPT can be misleading; ChatGPT is a finished product, whereas Llama is, to a substantial extent, technological infrastructure from which countless products can be built.
Llama’s significance has never been solely about whether its latest version defeats GPT or Claude on a given benchmark.
Instead, Meta’s central contribution has been to make powerful model weights available for developers to adapt, fine-tune, and deploy themselves.
This strategy continued with the Llama 4 release, which introduced the natively multimodal open-weight models Scout and Maverick.
Consequently, Llama occupies a separate category because its greatest virtue is openness and adaptability rather than the uniform experience of a centrally operated assistant.
The performance of a Llama-based solution is therefore highly variable: a casually deployed version may be substantially inferior to a frontier commercial assistant, but a carefully configured and fine-tuned open model may be superb at a specialized task.
Control, Customization, and Private Infrastructure
For many organizations, control over the AI model is more important than simply having access to the absolute frontier model.This is where Llama's open-weight nature provides a critical advantage.
There are many circumstances where this level of control is not just preferable, but necessary.
For example, governments may not wish to place confidential material or sensitive data into an external commercial service, preferring open models they can run on their own secure servers.
Similarly, companies may want AI models operating entirely on private infrastructure to meet strict data residency, security, or compliance requirements.
Beyond enterprise, researchers may wish to modify a model in fundamental ways that are impossible with a closed API, allowing for deeper experimentation and innovation.
These scenarios highlight how Llama empowers users to build solutions tailored to their unique operational and security contexts.
Ensuring Competition and Diverse Access to AI
Beyond individual use cases, open-weight models like Llama provide an important competitive restraint upon the proprietary laboratories.They ensure that the future of machine intelligence is not necessarily synonymous with dependence upon a small number of closed systems.
If sufficiently capable artificial intelligence can be operated locally or on private clouds, the leading AI companies cannot assume that access to machine intelligence will remain permanently concentrated in a handful of subscription services.
This fosters a more diverse and competitive ecosystem.
In this way, Llama and its successors remain indispensable, guaranteeing that developers, companies, and nations have an alternative path to building with AI that does not require reliance on a few powerful gatekeepers.
7. Key Technical Features: Context Windows, Multimodality & Agent Protocols
To effectively build the cross-AI workflows that triple productivity, a deep understanding of each model's core technical architecture is essential.These features—context windows, multimodality, and agent protocols—dictate what each tool can handle, how it processes information, and how it connects to your digital ecosystem.
They are the engine behind the advanced strategies discussed in this guide.
Context Window Showdown: Gemini, Claude, and GPT
The context window—the amount of information a model can hold in its short-term memory—is a critical battleground for utility.A larger window allows the AI to process entire codebases, lengthy legal documents, or extensive research papers in a single prompt, maintaining coherence and accuracy throughout.
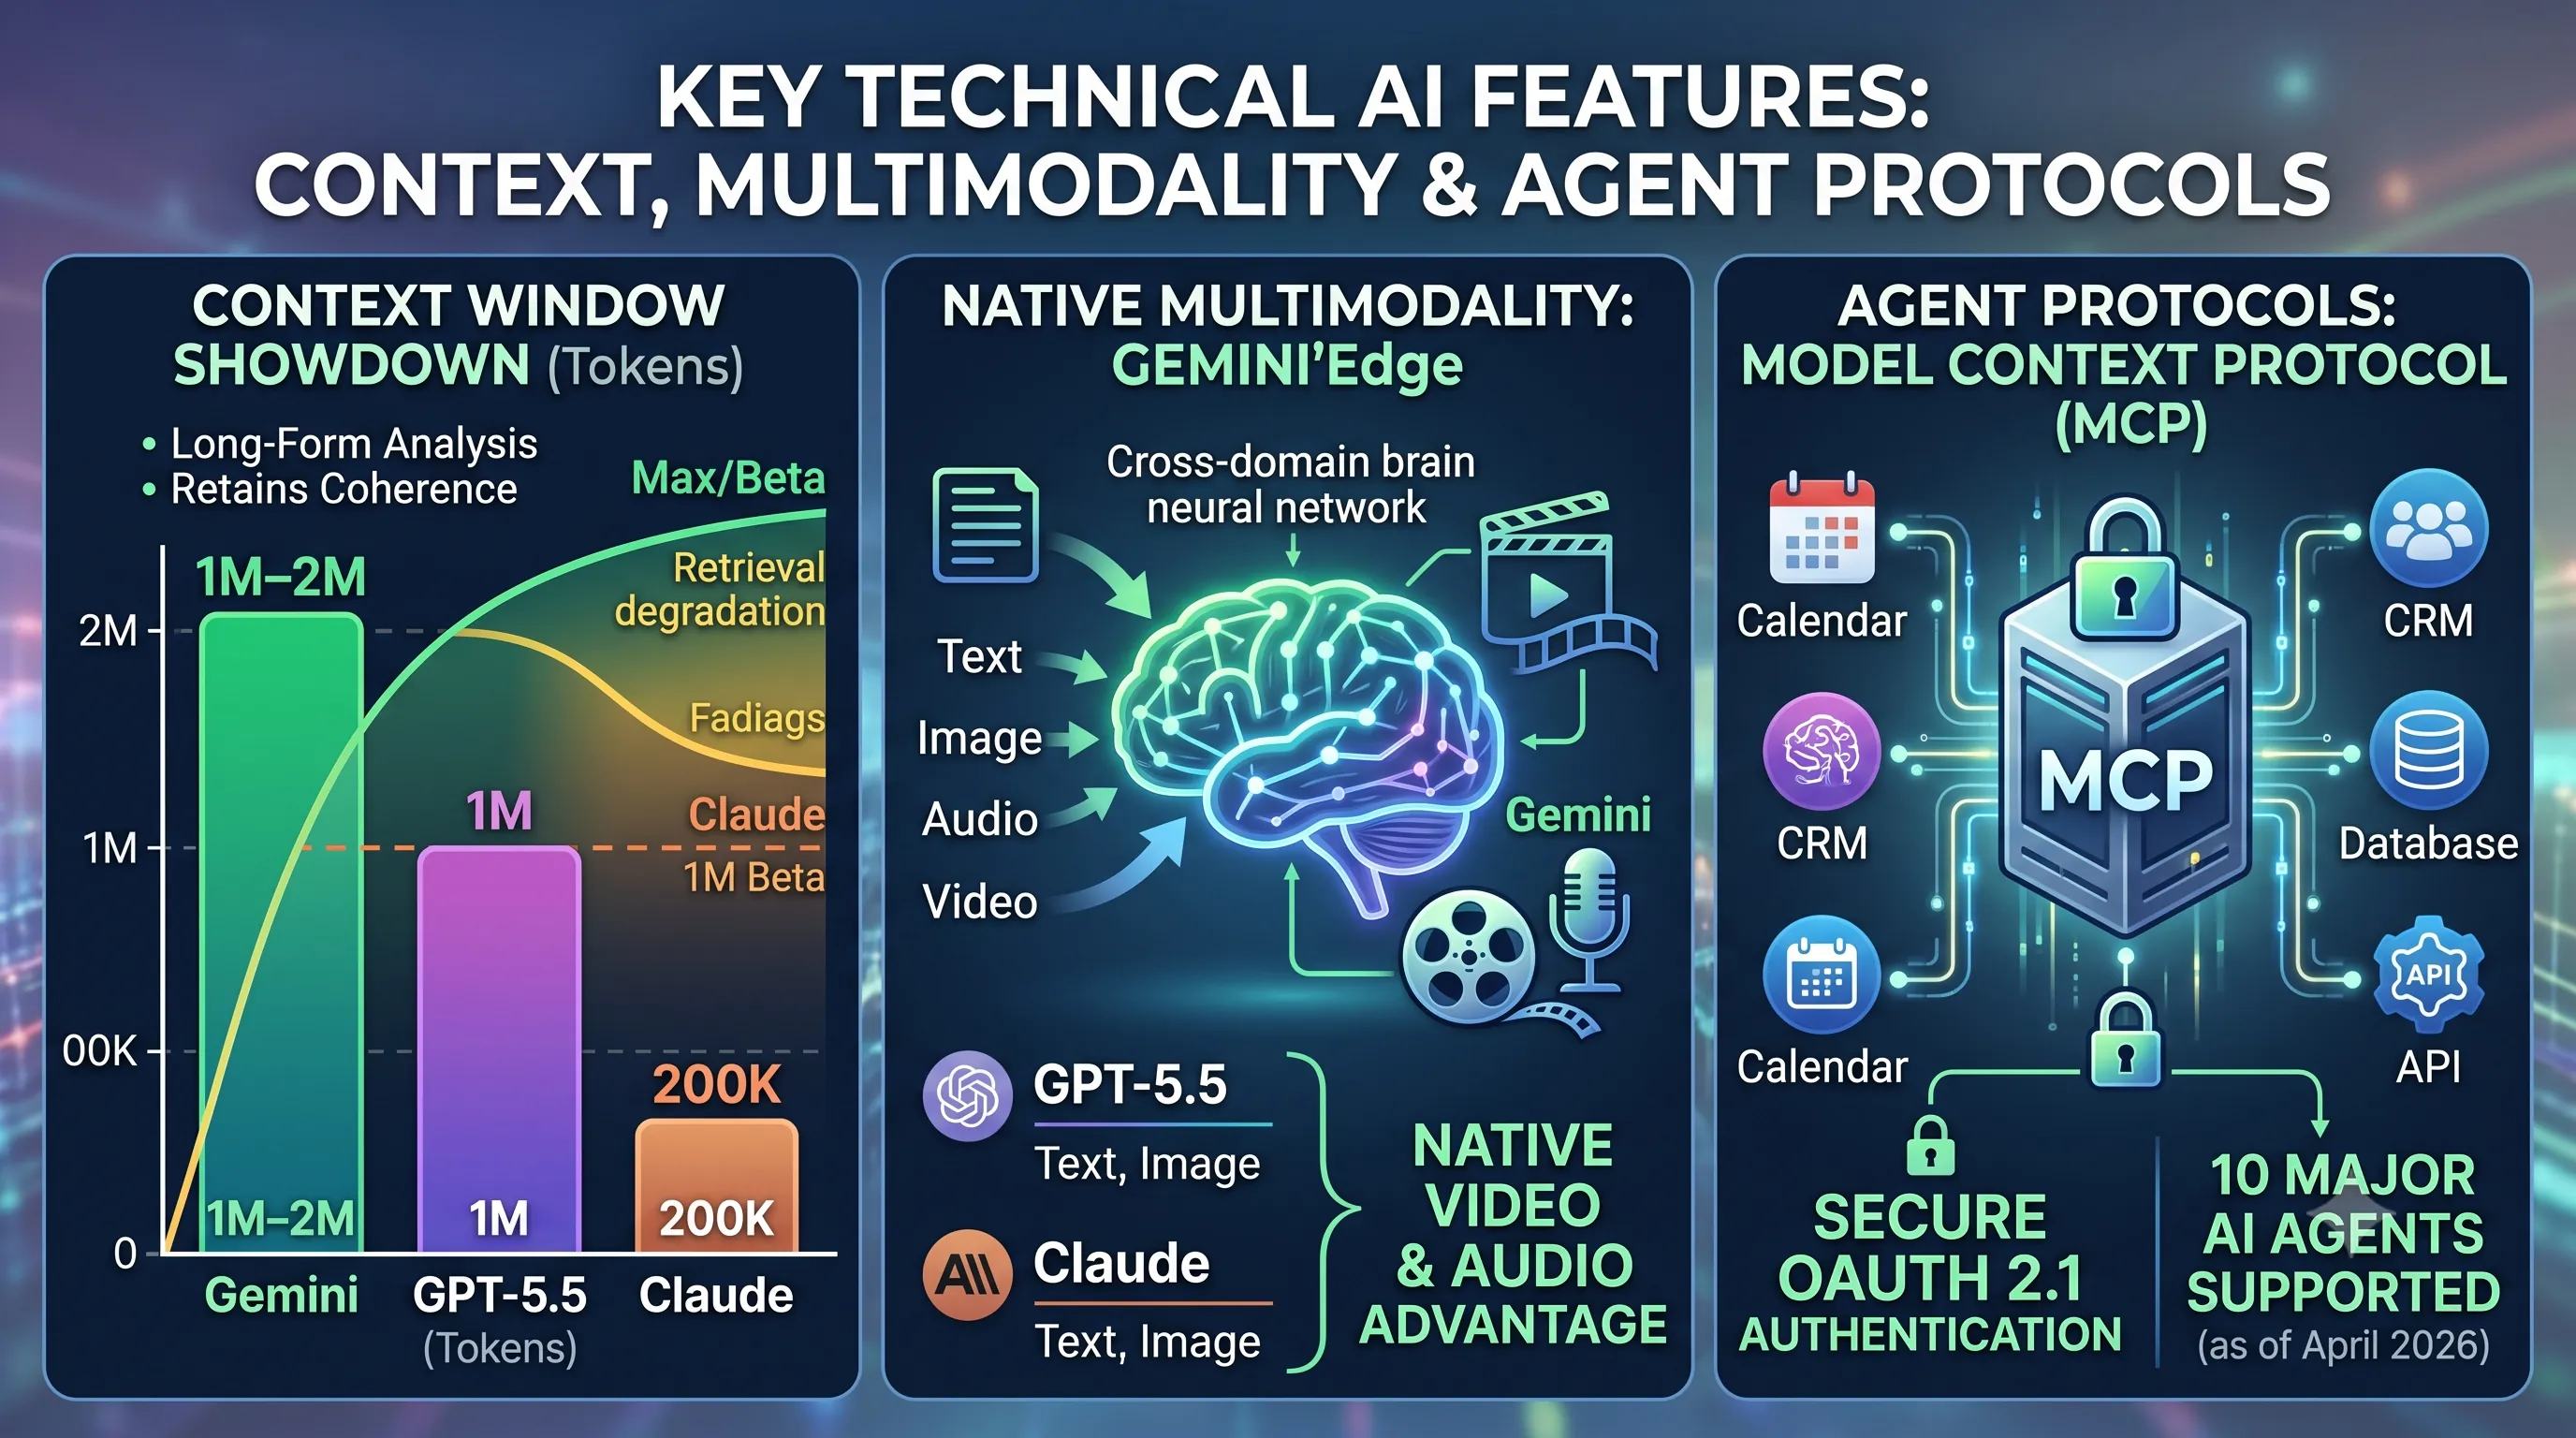
Google's Gemini leads the pack with a standard context window of 1 million to 2 million tokens.
This massive capacity, five times larger than Copilot's 400K window, enables unprecedented long-form analysis.
However, it's worth noting that Gemini's reliable retrieval can degrade in the final 200,000 tokens of its context window, a practical limitation for users pushing its absolute limits.
OpenAI's GPT-5.5 marked a significant leap, expanding its context window to 1 million tokens, catching up with its rivals and moving past the 200K–400K token windows of earlier GPT-5 versions.
Anthropic's Claude offers a standard window of 200,000 tokens but provides access to a 1 million token window in beta, giving users a high-capacity option for demanding tasks.
| Model | Standard Context Window | Max/Beta Context Window | Native Multimodality Support |
|---|---|---|---|
| Gemini | 1M–2M tokens | N/A (Standard) | Text, Image, Audio, Video |
| GPT-5.5 | 1M tokens | N/A (Standard) | Text, Image |
| Claude | 200K tokens | 1M tokens (Beta) | Text, Image |
Native Multimodality: Gemini's Edge
True multimodality is about more than just accepting different file types; it's about a deep, foundational understanding of various data formats.Here, Gemini has a distinct architectural advantage, as it was natively multimodal from its inception.
It was trained from the ground up on text, images, audio, and video, allowing it to reason across these domains seamlessly.
In contrast, while GPT-5 is multimodal, it lacks native video and audio capabilities, suggesting these data types are processed through separate mechanisms rather than a single, unified architecture.
Claude's capabilities are more focused, supporting image input but with no native video or audio processing.
This makes Gemini the go-to choice for complex tasks involving analysis of video footage or audio transcripts in conjunction with text-based documents.
The Rise of Model Context Protocol (MCP) for Agent Tools
As AI models evolve into autonomous agents, their ability to interact with external tools has become paramount.The Model Context Protocol (MCP) has emerged as the industry standard for connecting these AI agents to external applications, APIs, and data sources.
This protocol standardizes how an agent requests and receives information from tools like your calendar, CRM, or internal databases.
The rapid adoption of this standard solidifies its importance.
As of April 2026, 10 major AI agents already supported custom remote MCP servers, enabling developers and businesses to securely connect proprietary tools.
Crucially, this support includes native OAuth 2.1, providing a robust and secure authentication framework for these connections.
8. Benchmark Battleground: Who Leads in Reasoning, Coding, and Multimodality?
To build an effective cross-workflow as proposed in this guide, it's crucial to understand the specialized strengths of each AI model.This section delves into the objective benchmark data from August 2026, revealing which model leads in specific domains like coding, agentic tasks, and multimodal reasoning.
This data provides the evidence-based foundation for choosing the right tool for each step of your productivity chain.
GPT-5.5's Dominance in Agentic and Structured Reasoning
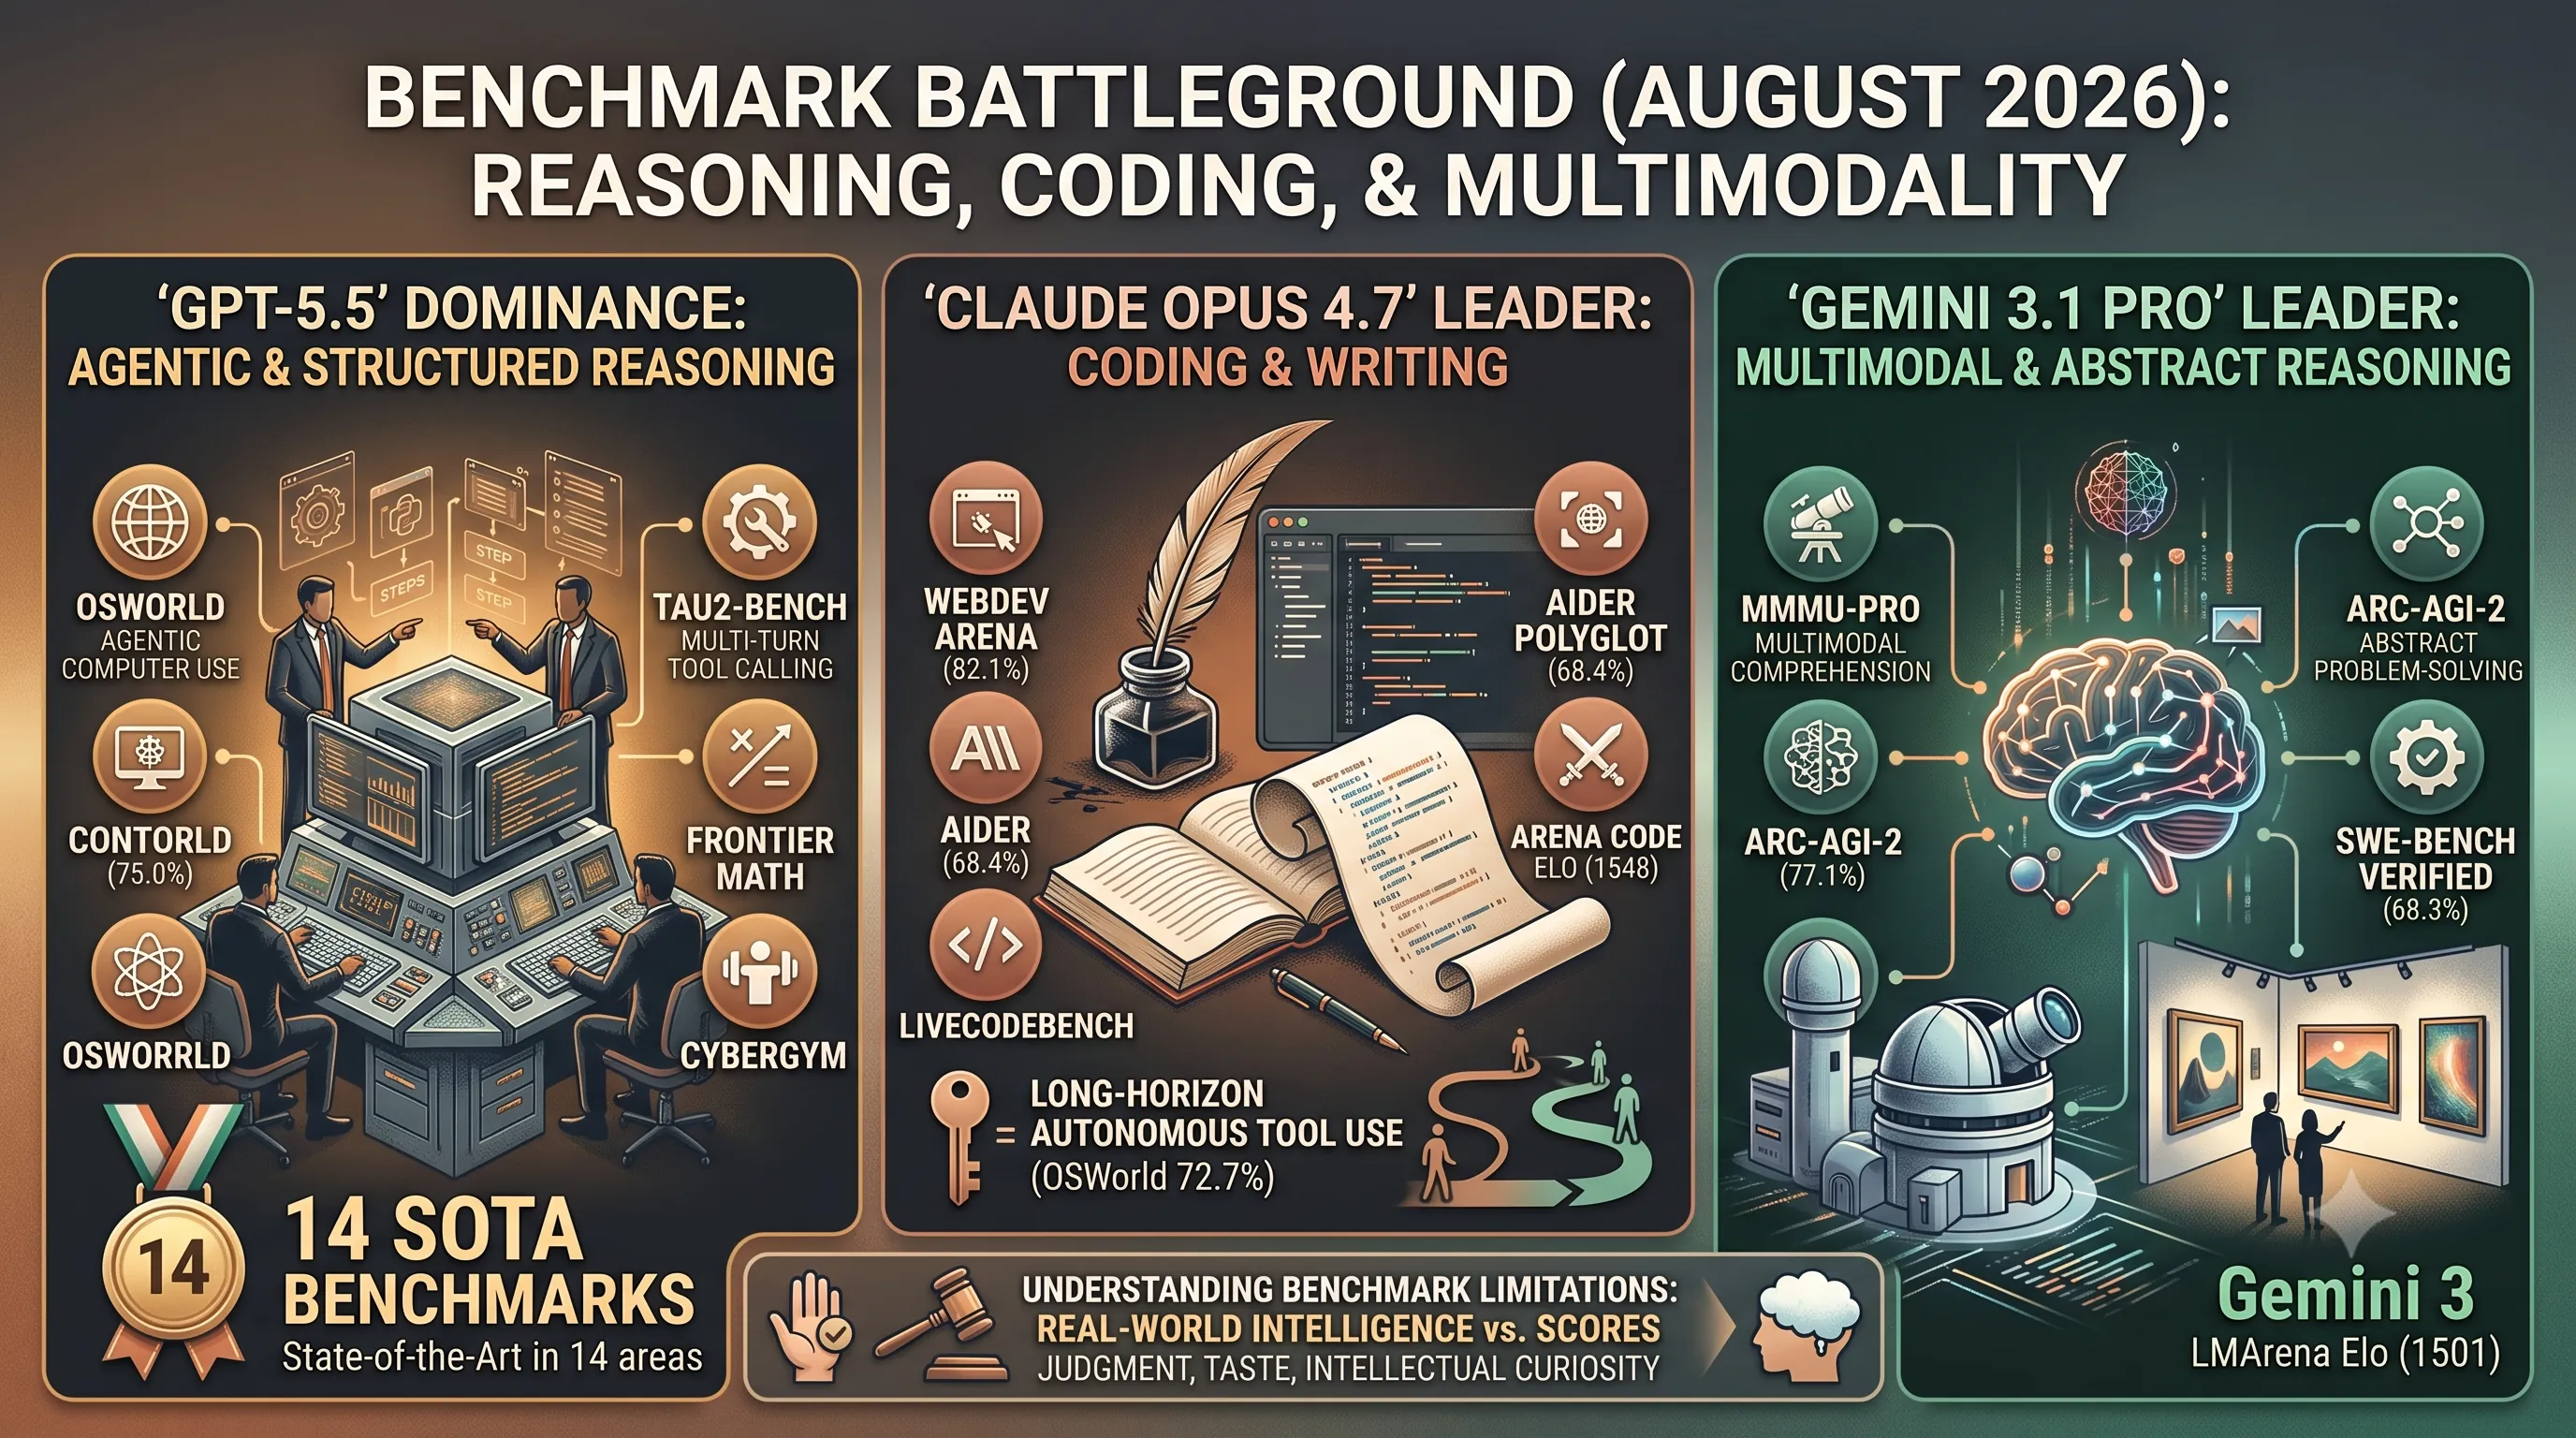
Since its launch in April 2026, GPT-5.5 has established a broad dominance across the benchmark landscape, achieving state-of-the-art (SOTA) performance on 14 different benchmarks.Its primary strength lies in agentic computer use and structured reasoning.
This is most evident in its 75% score on OSWorld, a benchmark that tests practical computer operation, where it surpassed the human expert baseline.
Further demonstrating its agentic capabilities, GPT-5.5 scored an exceptional 98.7% on TAU2-Bench, confirming its status as the best model for multi-turn tool calling.
Beyond general use, it also leads in specialized, high-value domains such as economic knowledge work (GDPval), complex mathematics (Frontier Math), and specialized cybersecurity simulations (CyberGym).
Claude's Strengths in Coding and Long-Horizon Tool Use
While GPT-5.5 leads in breadth, Claude has carved out an undisputed leadership position in coding and writing tasks.The latest model, Claude Opus 4.7, achieved SOTA on 4 benchmarks, primarily concentrated in software development.
Its predecessor, Claude Opus 4.6, set formidable records, scoring 82.1% on WebDev Arena, 68.4% on Aider Polyglot, and 71.2% on LiveCodeBench.
It also achieved a dominant Arena code Elo rating of 1548.
In the realm of agentic tasks, Claude demonstrates a different kind of strength from GPT-5.5; with a 72.7% score on OSWorld, it is recognized for having the best performance in long-horizon autonomous tool use, suggesting superior capability in completing complex, multi-step projects without continuous user intervention.
Gemini's Lead in Multimodal and Abstract Reasoning
Google's Gemini 3.1 Pro holds its own by specializing in areas where other models are weaker, specifically multimodal comprehension and abstract reasoning, securing SOTA on 2 benchmarks.It leads the field in understanding complex, abstract problems with a score of 77.1% on ARC-AGI-2.
Its leadership in multimodality is confirmed by a 72.2% score on MMMU-Pro, a benchmark testing comprehension across various data formats.
While not the absolute leader in coding, Gemini 3.1 Pro remains a strong contender with a 68.3% score on the difficult SWE-bench Verified.
Its general capabilities were already strong in late 2025, when Gemini 3 achieved a LMArena Elo of 1501.
| Benchmark/Domain | GPT-5.5 | Claude (Opus 4.6/4.7) | Gemini (3.1 Pro) | Leader & Note |
|---|---|---|---|---|
| Agentic Computer Use (OSWorld) | 75.0% | 72.7% | N/A | GPT-5.5 leads in general computer use; Claude excels at long-horizon autonomous tasks. |
| Multi-Turn Tool Calling (TAU2-Bench) | 98.7% | N/A | N/A | GPT-5.5 shows near-perfect accuracy. |
| Web Development (WebDev Arena) | N/A | 82.1% | N/A | Claude is the clear leader in coding tasks. |
| Multilingual Coding (Aider Polyglot) | N/A | 68.4% | N/A | Claude's coding dominance continues. |
| Multimodal Comprehension (MMMU-Pro) | N/A | N/A | 72.2% | Gemini leads in understanding mixed media. |
| Abstract Reasoning (ARC-AGI-2) | N/A | N/A | 77.1% | Gemini is best for abstract problem-solving. |
| Total SOTA Benchmarks (as of Apr 2026) | 14 | 4 | 2 | GPT-5.5 has the widest range of top scores. |
Understanding Benchmark Limitations
While these scores are essential for identifying technical specialists, it is crucial to recognize their limitations.Benchmarks are useful, but they are not identical to real-world intelligence.
They measure specific capabilities under controlled, artificial conditions, and a model's practical performance ultimately depends on how it is prompted and integrated into a workflow.
More importantly, these tests are especially poor at measuring nuanced human qualities that are critical for a true creative or strategic partner.
This includes attributes like judgment, taste, intellectual curiosity, conversational adaptability, and the subtle capacity to recognize what a human user really wants beyond their literal words.
9. Navigating AI Costs: API Pricing, Subscriptions, and Hidden Factors
This section is a crucial component of our guide to creating a high-productivity, multi-AI workflow.While performance and features dictate which AI is right for a task, the underlying cost structure determines the economic viability and scalability of your strategy.
Understanding the nuances of API pricing, subscription tiers, and hidden charges is essential for building a powerful AI stack that doesn't lead to unexpected and unsustainable expenses.
This analysis provides the financial blueprint for intelligently combining these services.
API Pricing Comparison: Input, Output, and Spread
The foundational cost for developers and businesses building on these platforms is API pricing, which is billed based on token usage—small units of text.A critical distinction is made between input tokens (the data you send to the model) and output tokens (the data the model generates).
As of August 2026, the pricing landscape shows a dramatic variation, particularly for output, which is typically more expensive as it represents the model's computational work.
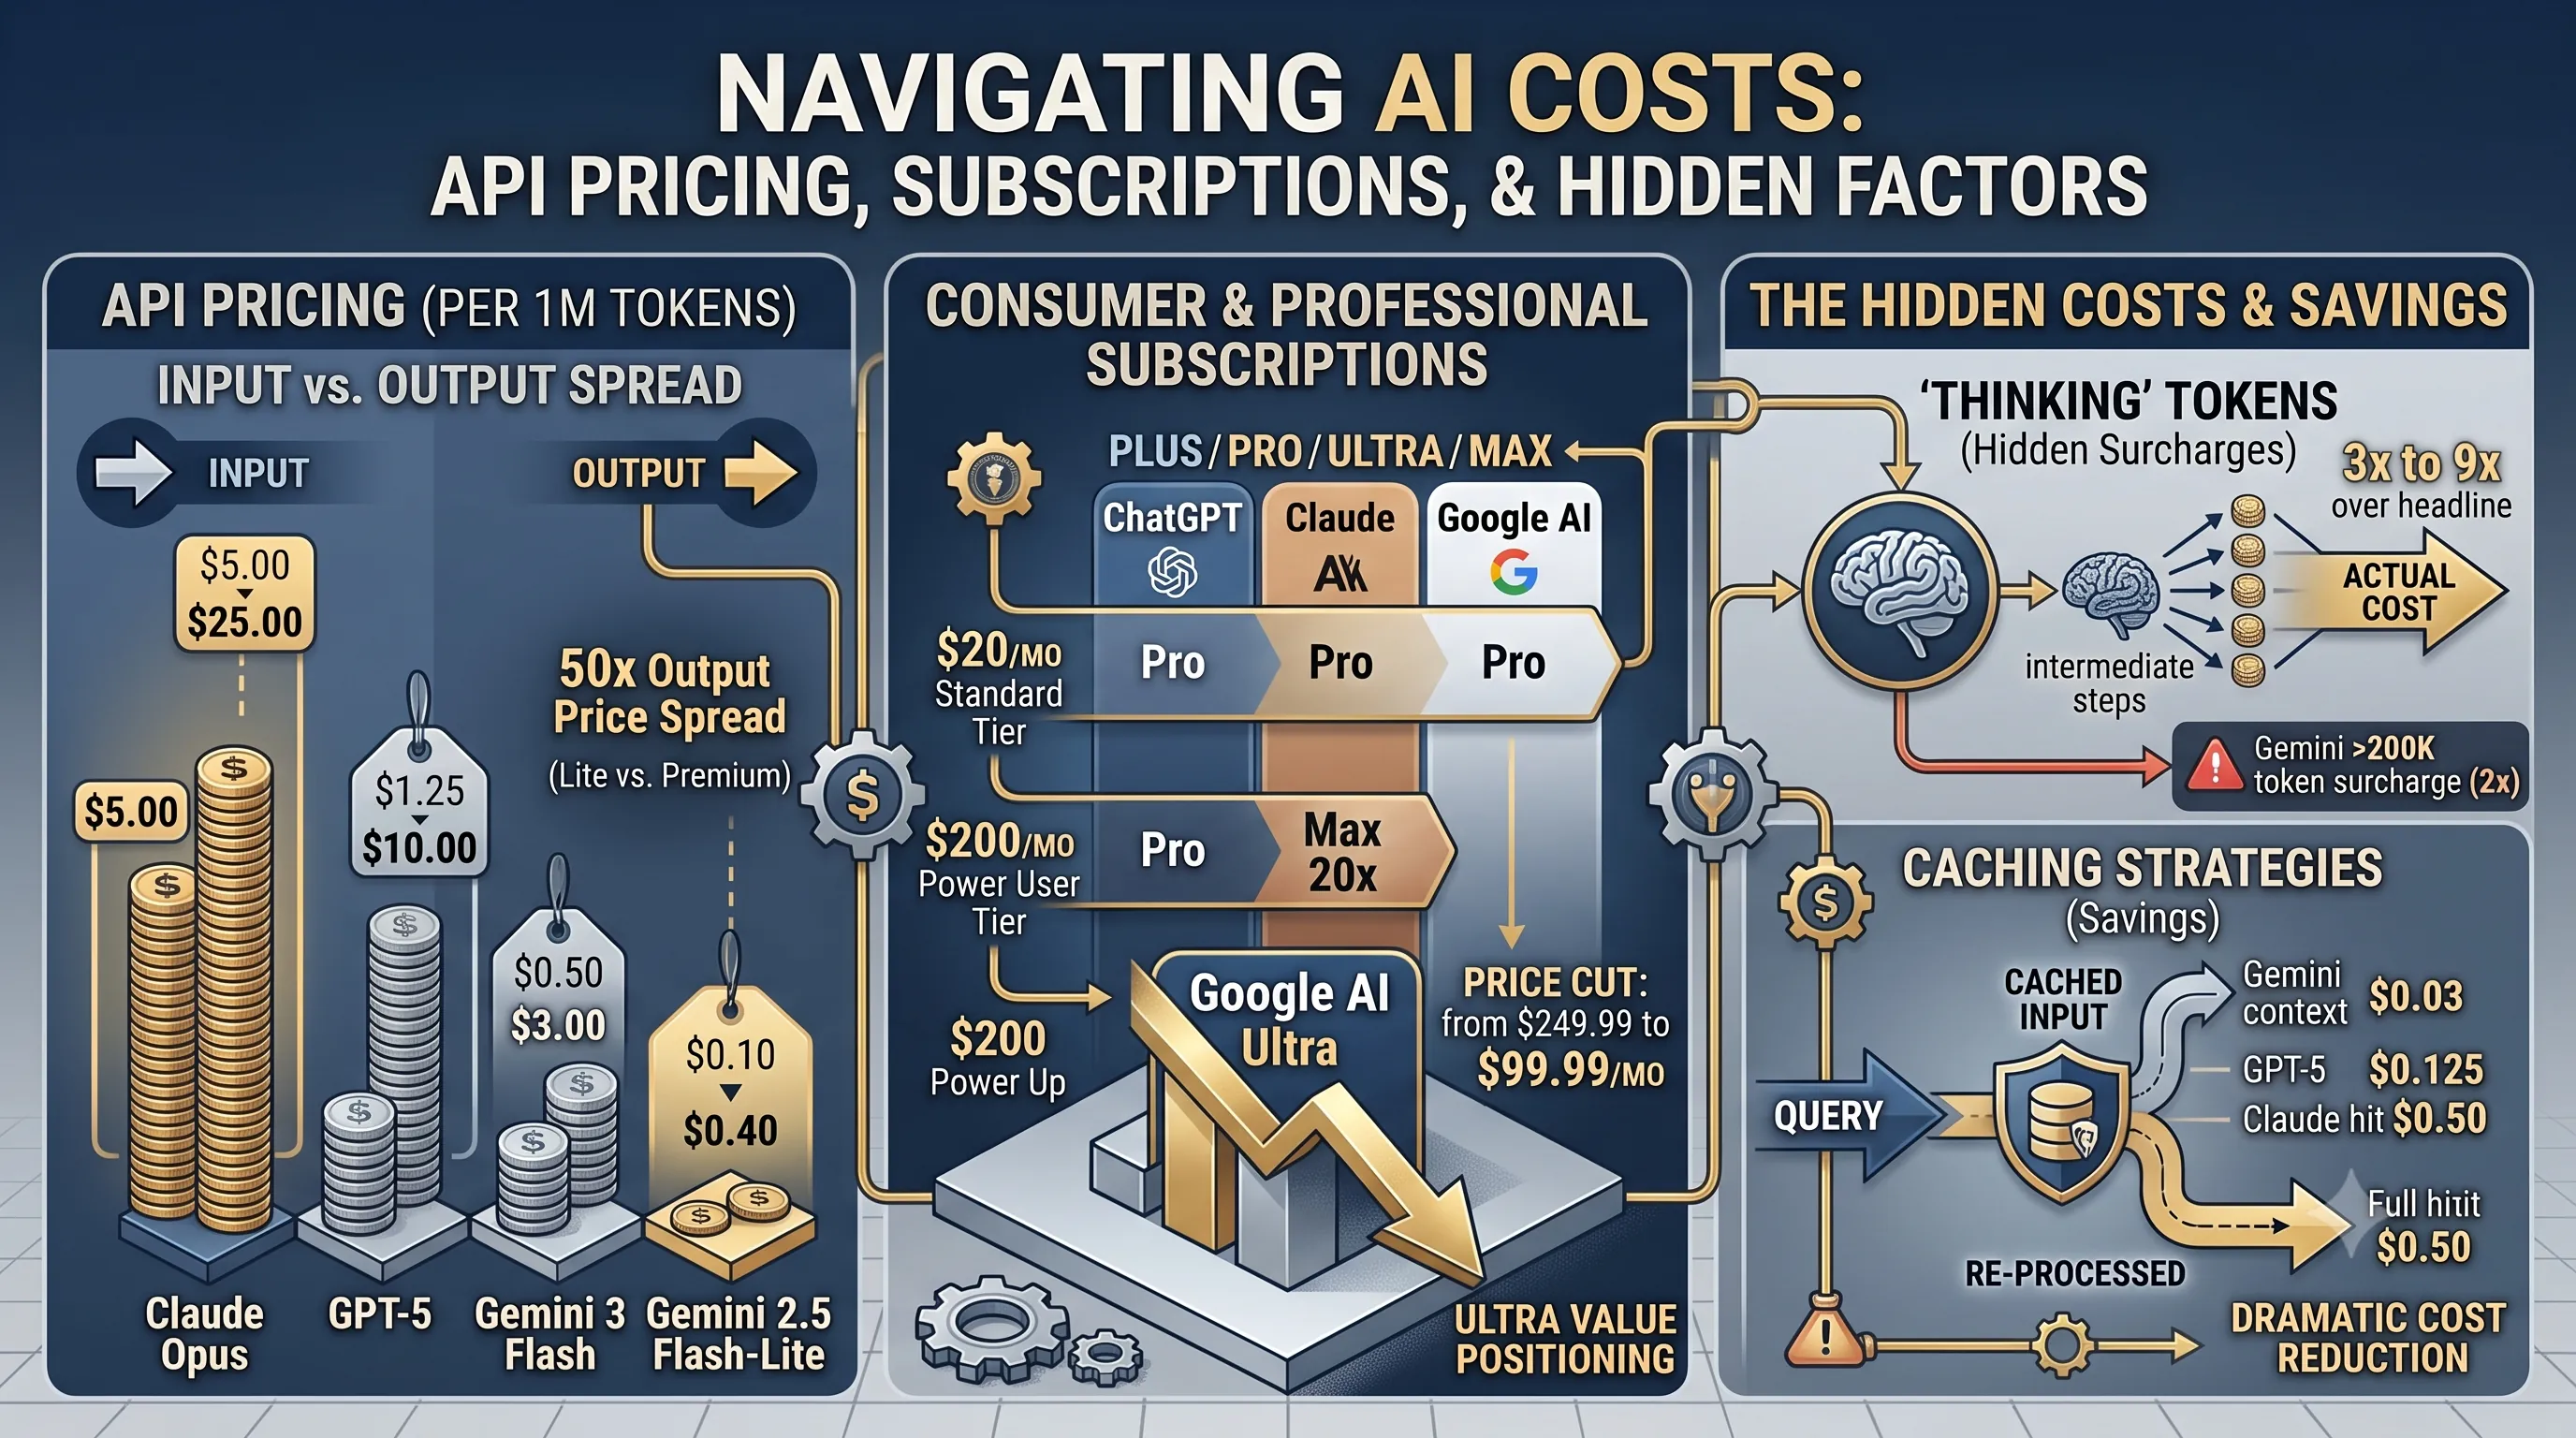
For top-tier reasoning, Anthropic's Claude Opus is the most expensive, charging $5.00 per million input tokens and a hefty $25.00 per million output tokens.
OpenAI's flagship, GPT-5, is considerably more economical, priced at $1.25 per million input tokens and $10.00 per million for output.
However, for tasks prioritizing speed and efficiency, Google's Gemini family offers highly competitive rates.
Gemini 3 Flash costs just $0.50 per million input tokens and $3.00 for output.
The most cost-effective option for simple, high-volume tasks is Gemini 2.5 Flash-Lite, at an impressively low $0.10 for input and $0.40 for output per million tokens.
This creates a remarkable 50x price spread on output pricing between the most affordable model (Gemini 2.5 Flash-Lite) and the most premium (Claude Opus), giving practitioners a wide spectrum to choose from based on task complexity and budget.
Consumer Subscription Tiers and Price Cuts
For individual users and professionals who prefer a web interface, subscription models offer a predictable monthly cost.The market has largely standardized the entry-level prosumer tier, with ChatGPT Plus, Claude Pro, and Google AI Pro all priced at $20 per month in 2026.
These plans provide access to the providers' primary models with higher usage limits than their free offerings.
For power users and enterprise needs, a premium tier has emerged.
OpenAI's ChatGPT Pro and Anthropic's Claude Max 20x both command a price of $200 per month, offering significantly higher capacity and features.
In a major competitive move at Google I/O 2026, Google dramatically slashed the price of its top-tier plan, Google AI Ultra, from $249.99 down to $99.99 per month, positioning it as a high-value alternative to its rivals.
Accessibility remains a key strategy for user acquisition, with both GPT-5 now offering a free tier for all users and Gemini providing a free tier with generous limits.
| Service/Model | Type | Tier | Input Price (per 1M tokens) | Output Price (per 1M tokens) | Monthly Subscription Cost |
|---|---|---|---|---|---|
| GPT-5 | API | N/A | $1.25 | $10.00 | N/A |
| Claude Opus | API | N/A | $5.00 | $25.00 | N/A |
| Gemini 3 Flash | API | N/A | $0.50 | $3.00 | N/A |
| Gemini 2.5 Flash-Lite | API | N/A | $0.10 | $0.40 | N/A |
| ChatGPT | Subscription | Plus | N/A | N/A | $20.00 |
| ChatGPT | Subscription | Pro | N/A | N/A | $200.00 |
| Claude | Subscription | Pro | N/A | N/A | $20.00 |
| Claude | Subscription | Max 20x | N/A | N/A | $200.00 |
| Google AI | Subscription | Pro | N/A | N/A | $20.00 |
| Google AI | Subscription | Ultra | N/A | N/A | $99.99 |
The Hidden Costs: 'Thinking' Tokens and Caching Strategies
The advertised API prices do not always reflect the final bill, especially for complex tasks.A significant hidden cost comes from internal "thinking" tokens, where models use intermediate steps or chain-of-thought processes to arrive at an answer.
These tokens are billed, meaning the actual cost for reasoning models can be 3 to 9 times the headline output price, a crucial factor to budget for when building complex agents or multi-step workflows.
To combat rising costs, API providers offer caching mechanisms that can dramatically reduce expenses for repeated queries.
Caching stores the result of an initial query, so subsequent identical requests are served from the cache at a much lower price instead of being re-processed by the model.
The cost savings vary significantly: Gemini's context cached input is the most aggressive at just $0.03 per million tokens.
GPT-5's cached input pricing is also highly effective at $0.125 per million tokens.
Anthropic's Claude cache hit input pricing is higher at $0.50 per million tokens but still offers substantial savings over its standard input rate.
However, users must also be aware of potential surcharges.
For instance, Gemini requests that exceed 200,000 tokens incur a 2x pricing surcharge, a policy designed to manage the load of extremely large context windows.
10. Tailored AI: Matching Models to Specific Professional Workflows
To build the powerful cross-workflow system this guide promises, you must first understand that there is no single "best" AI model.True productivity gains come from treating these tools like a specialist's toolkit, matching the right model to the right task.
This section breaks down the distinct strengths of the leading models as of August 2026, clarifying which to deploy for specific professional needs.
The core principle is strategic selection; a lawyer analyzing several thousand pages of disclosure might prefer Claude for the initial synthesis, then switch to ChatGPT for drafting client communications based on that analysis.
For sustained intellectual and professional work, ChatGPT and Claude are in the foremost group, with Gemini extremely close behind them.
ChatGPT: The All-Purpose Generalist
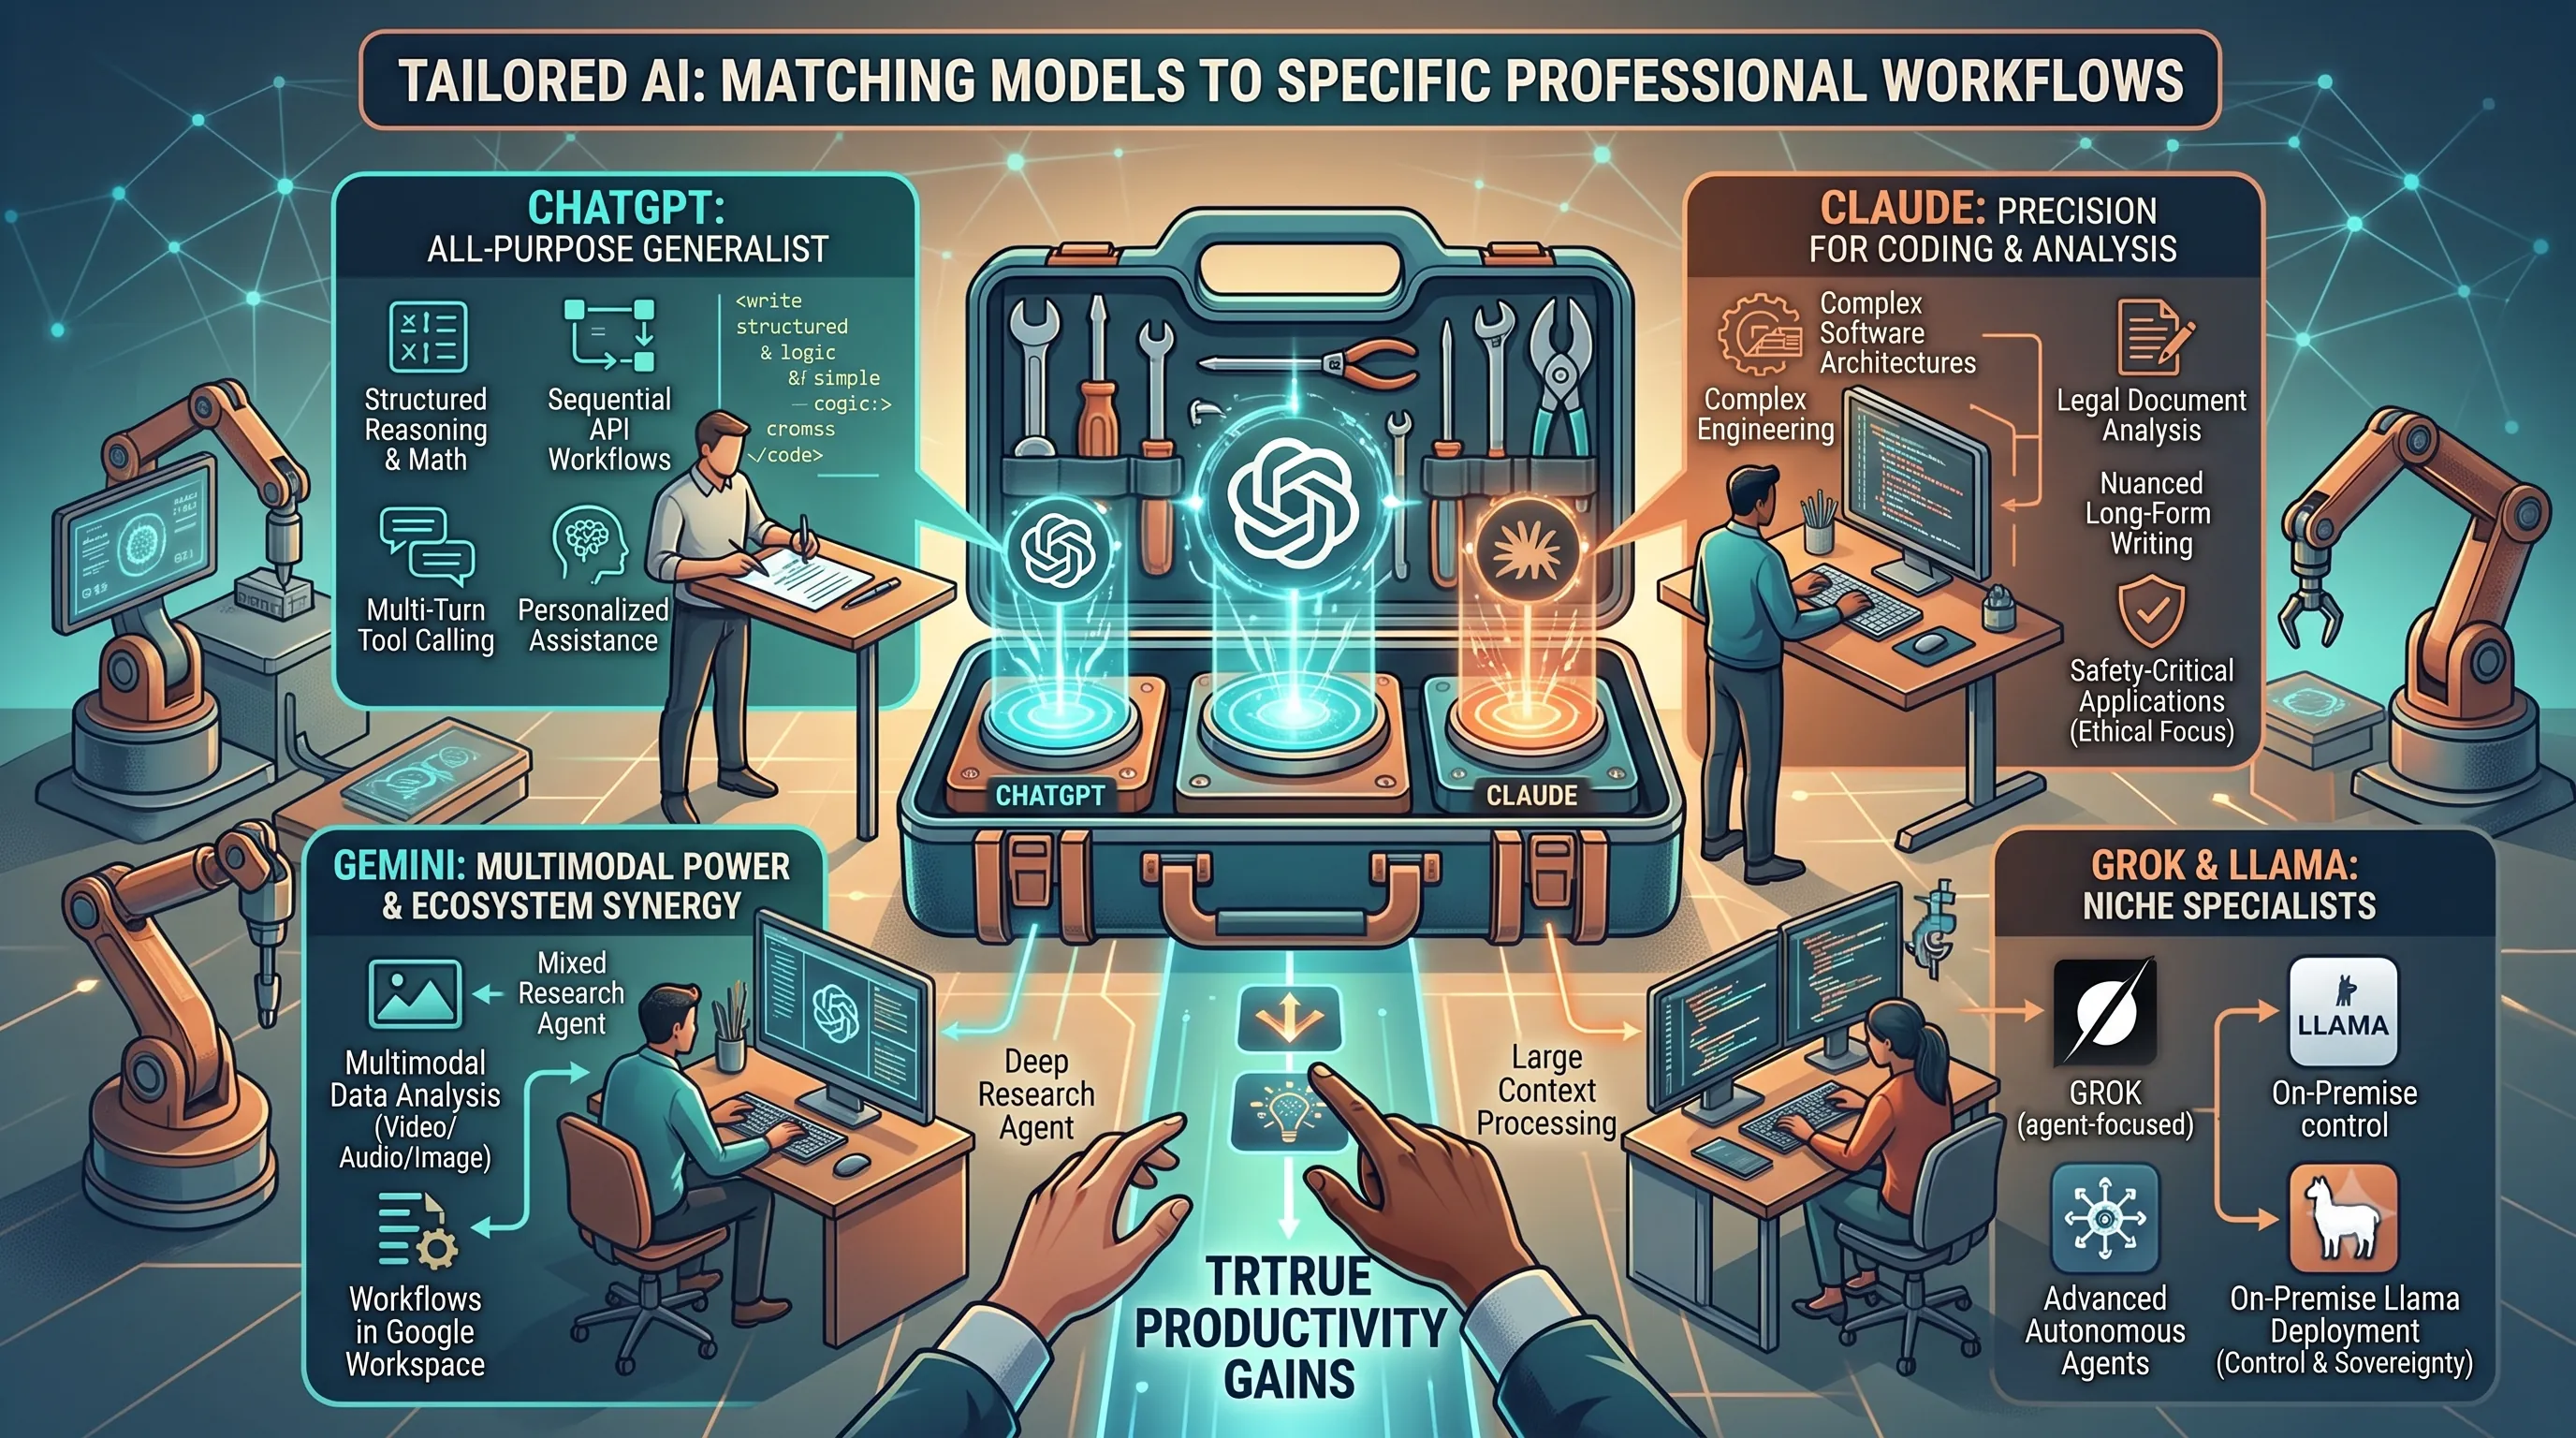
ChatGPT maintains its position as the indispensable all-rounder, a reliable first choice for a wide array of general tasks.Its strength lies in its versatility, making it highly suitable for foundational professional activities like research, writing, and structured reasoning across diverse domains.
It excels in tasks requiring logical steps, such as math problems, and has proven adept at computer use and agentic workflows.
For developers, ChatGPT is a strong choice for creating sequential API workflows due to its proficiency in multi-turn tool calling.
Beyond specific tasks, it has evolved into a powerful personalized assistant, leveraging features like memory, connected accounts, and custom instructions to tailor its support.
This combination of general capability and personalization makes it a favored option for broad enterprise deployment.
Claude: Precision for Coding and Nuanced Analysis
Where ChatGPT is the generalist, Claude distinguishes itself with deep specialization in complex, high-stakes domains.It is the preferred model for complex coding and software engineering challenges, particularly with the advancements in its dedicated Claude Code capabilities.
Developers often find it generates cleaner and more idiomatic frontend code compared to its peers.
For writers and analysts, Claude excels at producing long-form content that requires a nuanced tone and careful analysis.
Its architecture also makes it suitable for autonomous agent workflows that depend on long-horizon planning.
Crucially, its focus on ethical alignment makes it a leading candidate for safety-critical applications.
This enterprise-grade reliability is demonstrated in massive deployments at firms like Deloitte and its use in legal tools supported by 12 distinct plugins for specialized knowledge work.
Gemini: Multimodal Power and Ecosystem Synergy
Gemini's primary advantage lies in its native multimodality and its profound integration within the Google ecosystem.It is the go-to model for tasks that involve understanding video, audio, and images within a single prompt, a capability that sets it apart.
This power extends to processing massive amounts of text, capable of handling entire codebases or vast document libraries in one go.
For researchers, Gemini’s Deep Research agent provides a unique ability to perform long-running synthesis and analysis.
On the business side, its tiered models like Flash and Flash-Lite make it a cost-sensitive option for high-volume deployments.
However, its most compelling feature for many professionals is its seamless workflow integration with Google Workspace, Search, Android, and Chrome.
A researcher or analyst deeply embedded in Google’s ecosystem might find Gemini overwhelmingly more convenient for their work, which is also backed by its strong performance on scientific benchmarks and abstract reasoning tasks.
Grok & Llama: Niche Strengths for Autonomous Agents and Custom Control
While the main three models cover most professional needs, Grok and Llama serve critical, specialized roles.A programmer building sophisticated autonomous agents might discover particular advantages in Grok's architecture and capabilities.
Llama, on the other hand, is the premier choice for organizations that require absolute control and privacy over their AI infrastructure.
A defense contractor, government agency, or financial institution requiring complete sovereignty over its data and model deployment would prefer a customized, on-premise Llama deployment over a third-party service.
| AI Model | Specialized Strengths | Best Use Cases |
|---|---|---|
| ChatGPT | All-purpose versatility; Structured reasoning & math; Multi-turn tool calling; Personalized assistance (memory) | General research & writing; Sequential API workflows; Agent-style computer use; Enterprise-wide deployment |
| Claude | Complex coding (Claude Code); Nuanced long-form writing; Ethical alignment & safety focus; Long-horizon planning | Software engineering & frontend development; Legal document analysis; Safety-critical applications; Enterprise knowledge work |
| Gemini | Native multimodality (video, audio, image); Large-scale document processing; Deep Google ecosystem integration; Cost-effective tiers | Multimodal data analysis; Research with Deep Research agent; Workflows in Google Workspace/Android; High-volume enterprise tasks |
| Grok | Specialized advantages for agentic programming | Building advanced autonomous agents |
| Llama | Full control via private infrastructure deployment | Defense, finance, or any sector requiring data sovereignty and custom, on-premise solutions |
11. Optimizing AI Chatbots: The Critical Role of Retrieval-Augmented Generation (RAG)
This section connects to the main article's theme of "A Guide to Tripling Productivity with a 3-AI Combination" by focusing on one of the most critical real-world applications for AI models: enterprise chatbots.While the main article discusses combining AI models for general productivity, this deep-dive explains that for chatbots, the underlying architecture—specifically Retrieval-Augmented Generation (RAG)—is far more impactful than the choice of the Large Language Model (LLM) alone.
It provides a practical guide for professionals on how to build accurate, reliable chatbots by optimizing the retrieval pipeline and selecting the right model for the right RAG-based task, directly aligning with the theme of "a practitioner's actual cross-workflow."
RAG's Dominance in Chatbot Accuracy
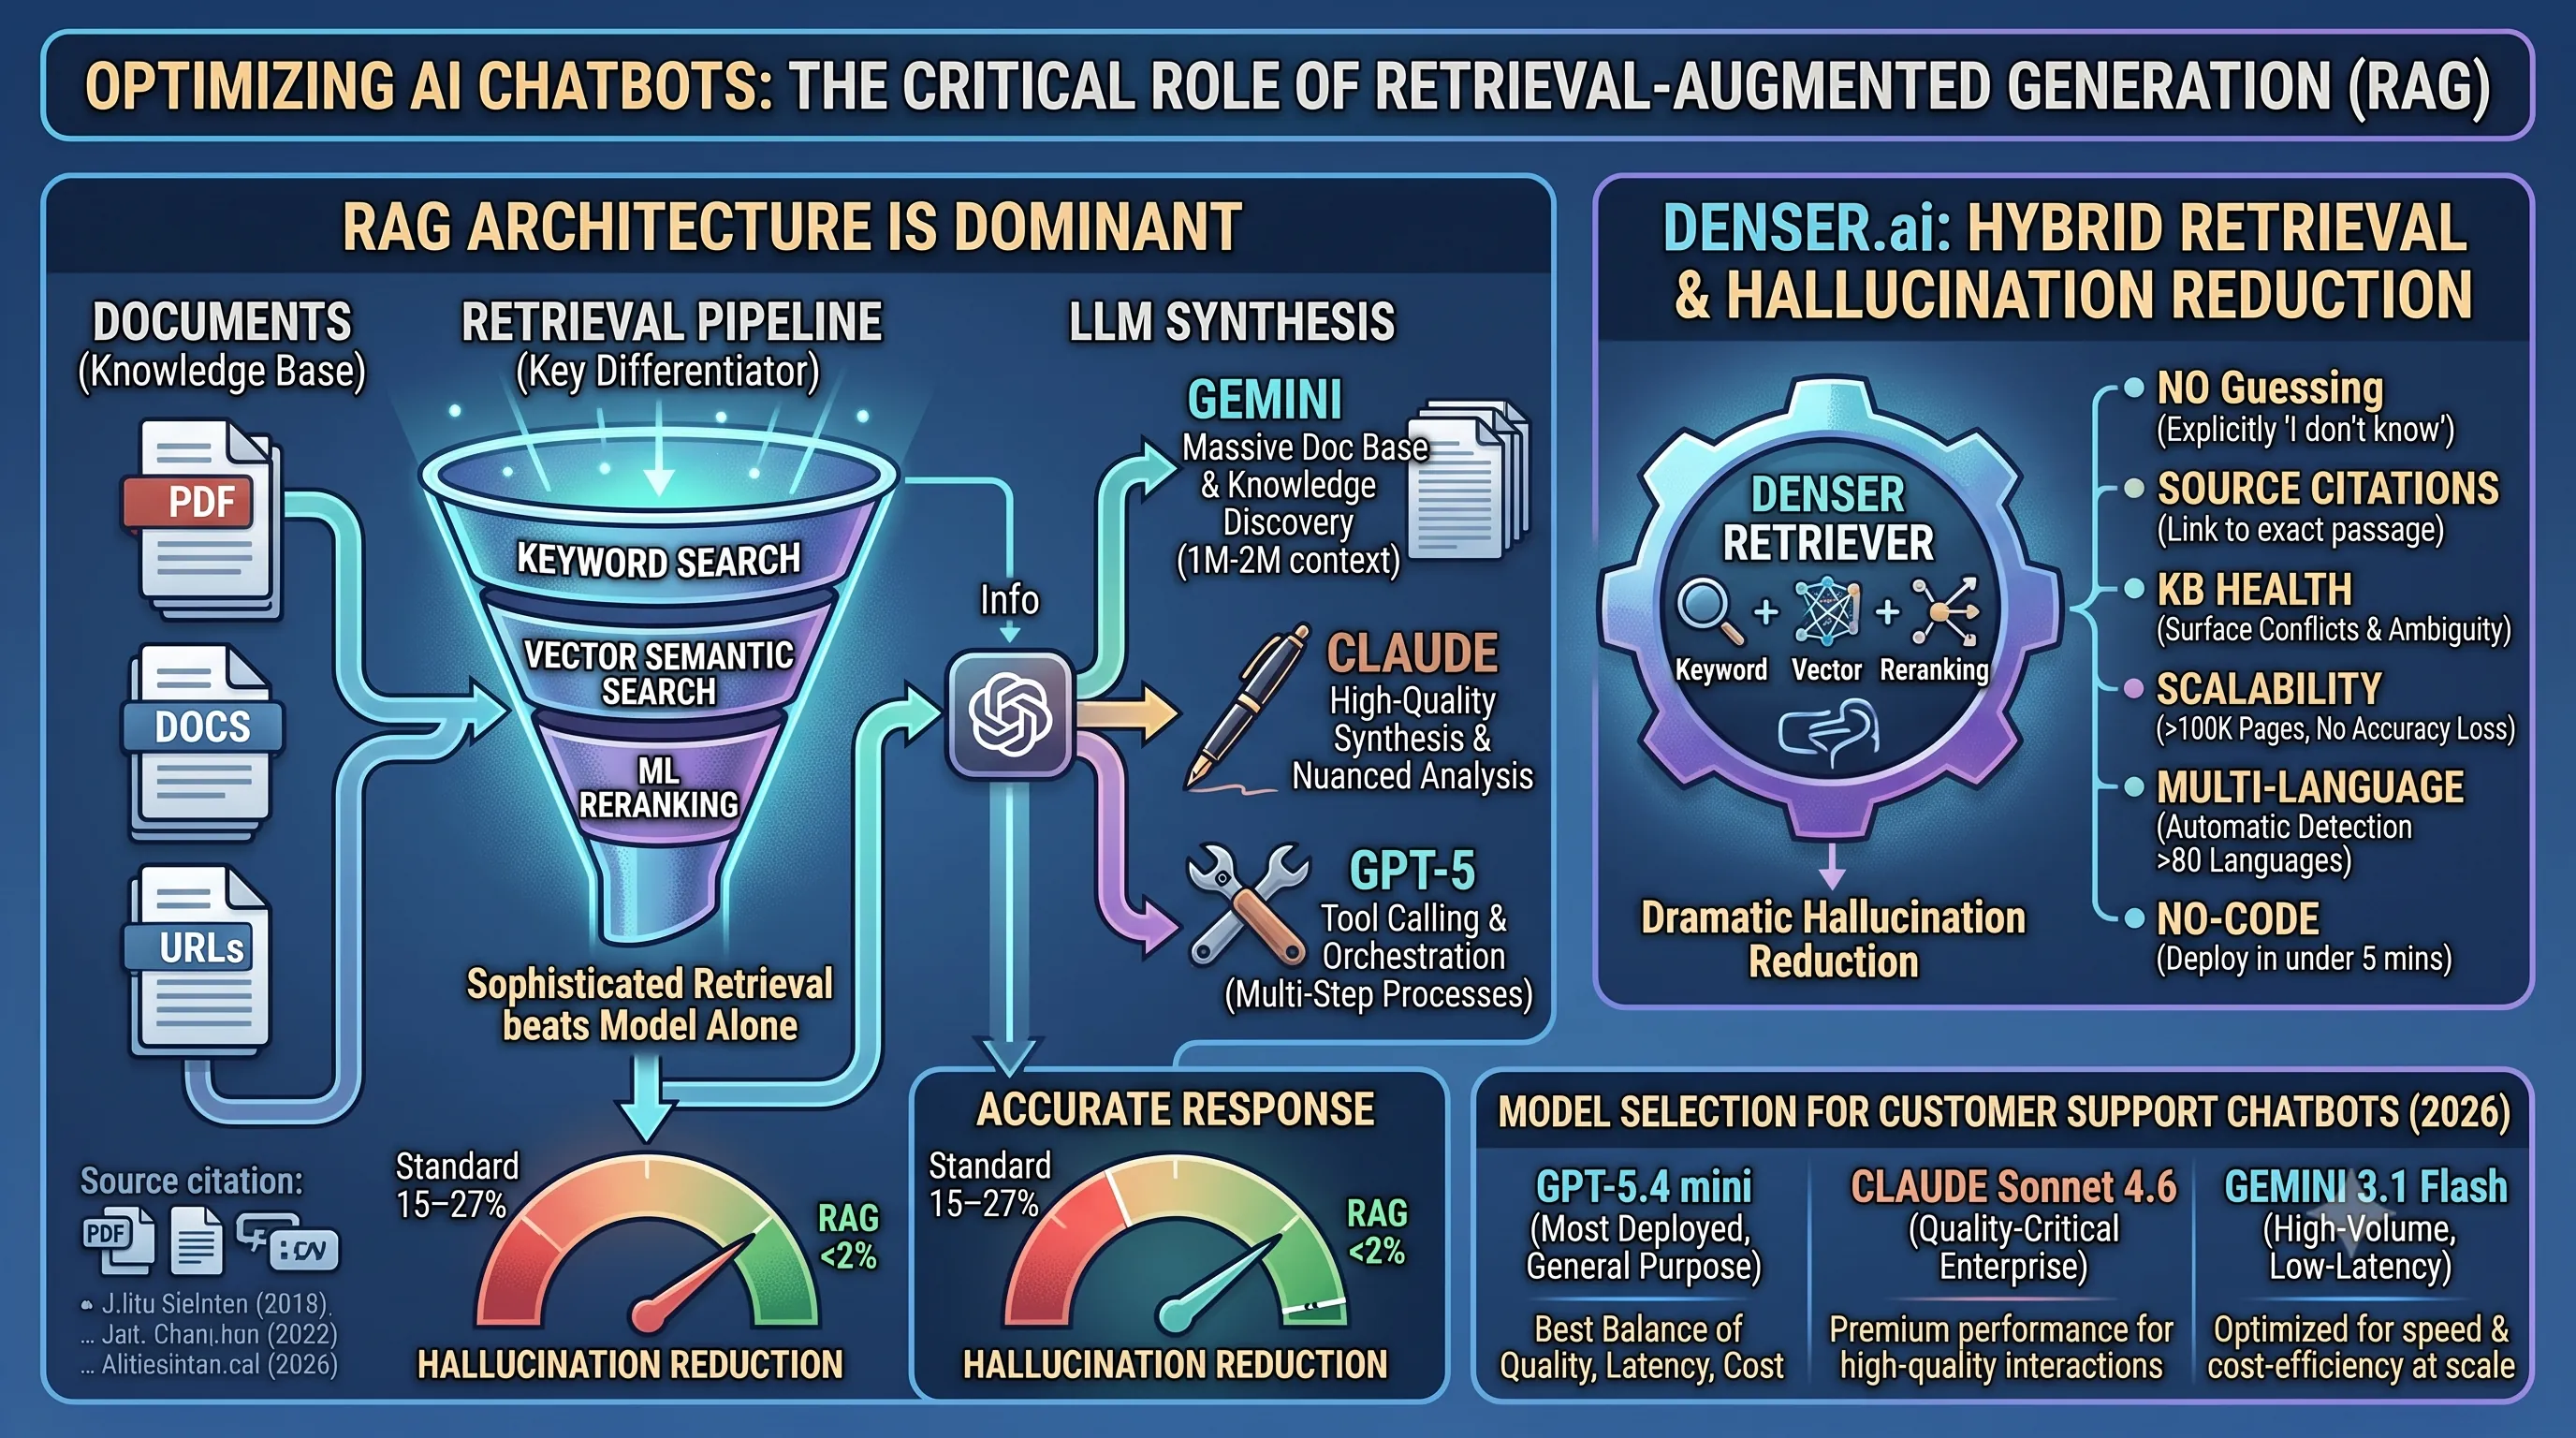
In the realm of enterprise AI chatbots, the choice of the frontier model is only one piece of the puzzle.The harsh reality is that even the best models, when generating answers from their vast but unverified training data, will hallucinate 15–27% of the time.
This level of inaccuracy is unacceptable for business use cases.
For this reason, the retrieval pipeline in a Retrieval-Augmented Generation (RAG) system has a bigger impact on final answer accuracy than the specific LLM used.
The model can only be as good as the information it's given to process.
Therefore, the real differentiator in production-grade chatbots is the sophistication of the retrieval architecture, which is responsible for finding and feeding relevant, verified information to the model before it generates a response.
Model Strengths in RAG Implementations
While the retrieval pipeline is paramount, selecting the right LLM for the final synthesis step can optimize for specific needs.Different models exhibit unique strengths within a RAG framework.
Gemini excels in scenarios involving massive document bases.
Its large context window of 1 to 2 million tokens allows it to ingest entire codebases or dozens of lengthy documents in a single call, making it ideal for comprehensive knowledge discovery.
Claude is the preferred choice for RAG tasks that demand high-quality synthesis and nuanced analysis.
Its inherent strength in composition and writing translates directly to better, more coherent answer construction from the retrieved documents.
GPT-5 shines in complex workflows requiring tool calling and multi-step retrieval processes, effectively acting as an orchestrator for sophisticated, action-oriented RAG implementations.
Denser.ai's Hybrid Retrieval and Hallucination Reduction
Platforms like Denser.ai are built entirely on a sophisticated RAG architecture to solve the core problem of chatbot inaccuracy.It recognizes that standard vector search, while useful for finding semantically similar content, often fails by missing exact keyword matches crucial for technical or specific queries.
The Denser.ai solution is its proprietary Denser Retriever, a hybrid retrieval engine that combines keyword search, vector semantic search, and machine learning-based reranking into a single, unified pipeline.
This hybrid approach ensures both precise keyword matching and broad semantic understanding, with the ML reranker pushing the most relevant results to the top.
This architectural choice is what dramatically reduces hallucination rates from the industry standard of 15–27% to under 2%.
A key part of this is a strict policy: if the answer is not found in the connected documents, the Denser-powered chatbot explicitly says so rather than guessing.
To ensure complete transparency and verifiability, every answer generated by a Denser chatbot includes a source citation, linking back to the exact page and passage from which the information was derived.
Furthermore, Denser includes a unique feature called KB Health, which proactively scans all connected documents to identify conflicting facts, surfacing these inconsistencies with a confidence score to help businesses resolve ambiguity in their source knowledge base.
Denser manages this entire pipeline—from retrieval and model selection to citations and deployment—through a no-code interface, allowing a user to deploy a branded chat widget from a website URL or uploaded documents in under five minutes.
The system is designed to scale, handling over 100,000 pages with no loss in answer accuracy and supporting over 80 languages with automatic detection.
Choosing the Right Model for Customer Support Chatbots
For the high-stakes environment of customer support, model selection is critical for balancing performance, cost, and user experience.In 2026, GPT-5.4 mini has become the most deployed model in this sector, offering the best overall balance of language quality, low latency, and operational cost.
For enterprises where the quality of interaction is the absolute top priority, Claude Sonnet 4.6 is a strong contender, delivering premium results for quality-critical chatbot deployments.
On the other end of the spectrum, Gemini 3.1 Flash is the optimal choice for high-volume, low-latency applications where speed and cost-efficiency at scale are the primary concerns.
| Model | Best Use Case for Customer Support Chatbots | Key Strengths |
|---|---|---|
| GPT-5.4 mini | General Purpose & Most Deployed | Best balance of language quality, low latency, and cost. |
| Claude Sonnet 4.6 | Quality-Critical Enterprise Needs | Superior performance for high-quality, nuanced interactions. |
| Gemini 3.1 Flash | High-Volume & Low-Latency Needs | Optimized for speed and cost-efficiency at a massive scale. |
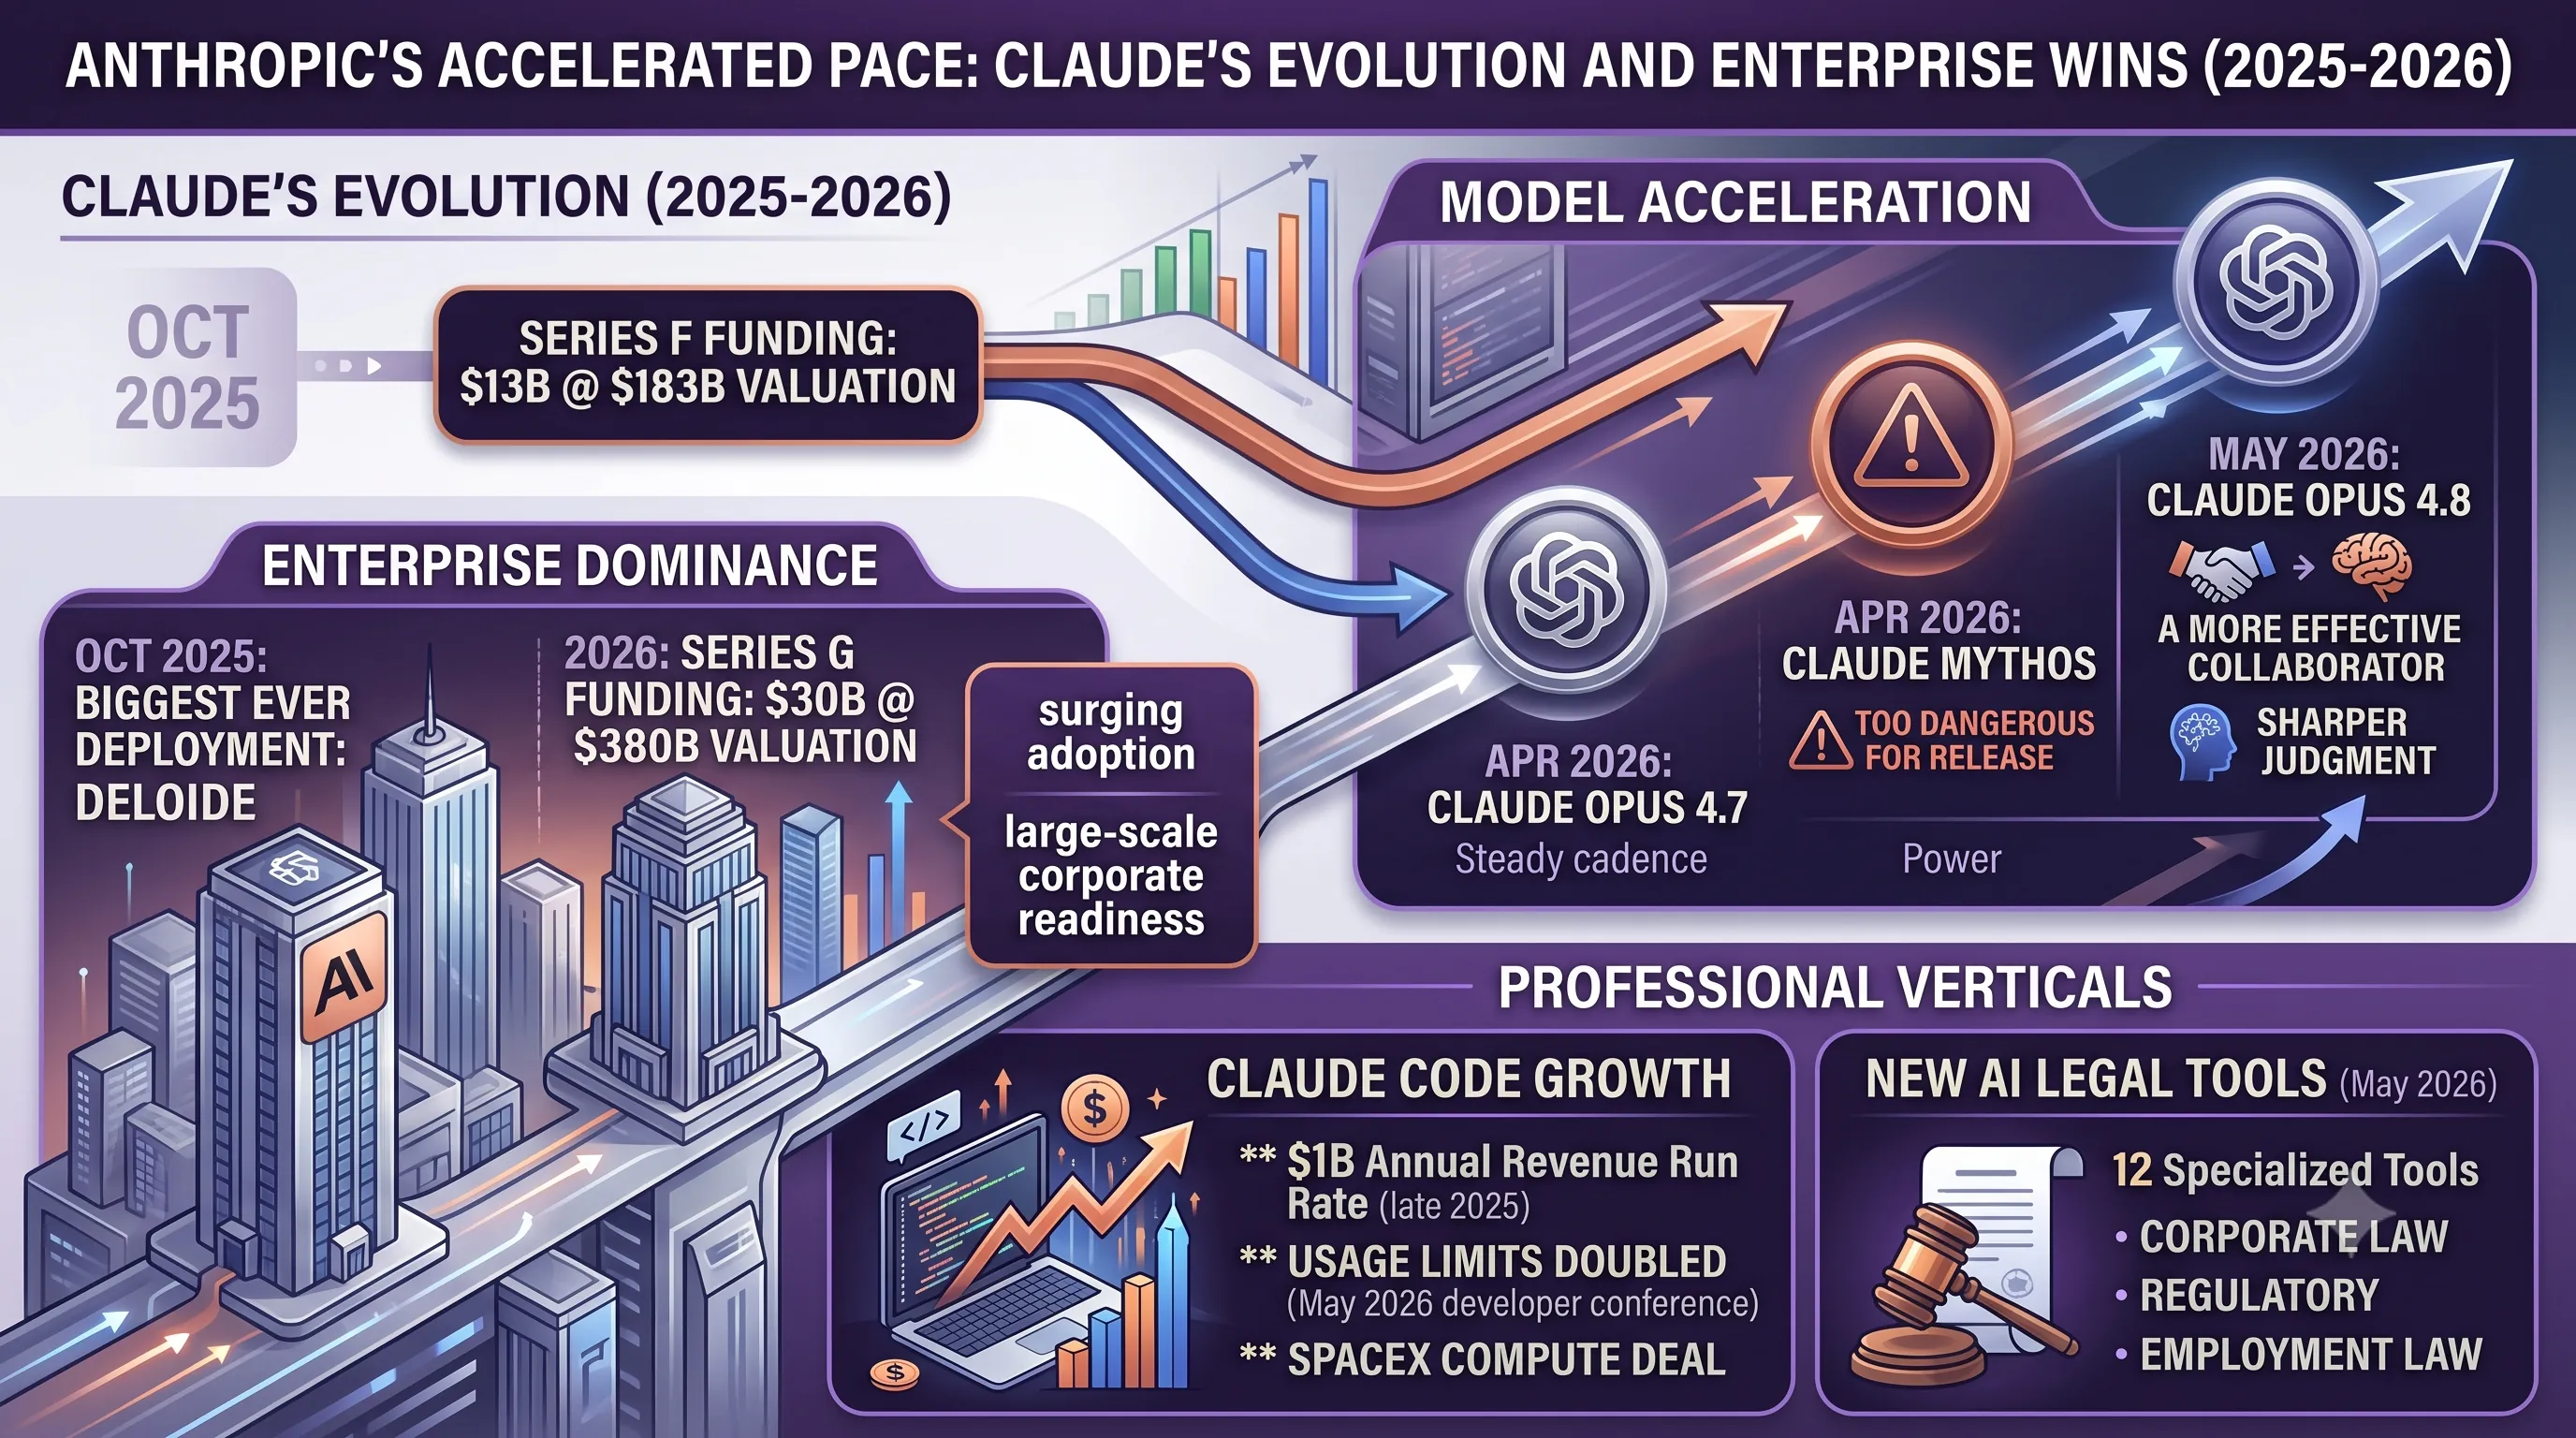
12. Anthropic's Accelerated Pace: Claude's Evolution and Enterprise Wins (2025-2026)
This section provides a deep-dive into the recent, rapid advancements of Anthropic's Claude, a key player in the "3-AI combination" productivity workflow.By understanding Claude's latest model releases, its surging enterprise adoption, and its expansion into specialized domains like coding and law, practitioners can better leverage its unique strengths for complex collaborative and analytical tasks, forming a crucial pillar in the cross-workflow strategy to boost efficiency.
Claude Opus 4.8 and Enhanced Collaboration
Anthropic has maintained a relentless development schedule over the past year, culminating in models that significantly enhance human-AI collaboration.In April 2026, the company released Claude Opus 4.7, continuing its steady cadence of powerful updates.
That same month, Anthropic also announced a model named Claude Mythos, which was ultimately deemed too dangerous for public release, signaling the immense power of the underlying architecture the company was developing.
This was quickly followed by the launch of Claude Opus 4.8 on May 28, 2026.
This latest iteration was specifically described by the company as a "more effective collaborator," engineered with sharper judgment, making it an even more reliable partner for nuanced professional tasks.
Strategic Funding and Major Enterprise Deployments
The market has responded to Anthropic's technical progress with massive strategic investments, fueling its expansion.In October 2025, the company secured $13 billion in funding at a $183 billion valuation, providing significant capital for R&D and scaling operations.
This funding coincided with a landmark business achievement that same month: Anthropic secured its biggest enterprise deployment ever with professional services giant Deloitte, validating Claude's readiness for large-scale corporate environments.
The momentum continued into 2026, when the company raised a staggering $30 billion in a Series G funding round, which brought its post-money valuation to an incredible $380 billion.
Claude Code's Growth and New Legal AI Tools
Beyond its flagship models, Anthropic has achieved remarkable success by targeting high-value professional domains.Claude Code, its specialized tool for developers, demonstrated explosive growth by hitting a $1 billion annualized revenue run rate in late 2025.
The company further invested in this vertical during its "Code with Claude" developer conference in May 2026, where it announced that usage limits for the service were doubled and revealed a significant deal with SpaceX for compute resources at its Memphis data center.
Expanding its professional toolkit, Anthropic also unveiled 12 new AI legal tools on May 14, 2026.
These tools are designed to assist with complex corporate, regulatory, and employment law tasks, marking a significant entry into another specialized, high-stakes industry.
13. OpenAI's Innovation Sprint: GPT-5.5, Finance Dashboards, and Reliability (2025-2026)
This section connects directly to the main article's theme of creating a powerful, cross-company AI workflow.OpenAI’s rapid advancements over the past year have delivered not just incremental improvements, but entirely new categories of tools and a foundational leap in model reliability.
For practitioners building a multi-AI toolkit, these developments from OpenAI serve as the critical anchor for tasks requiring high factual accuracy, specialized data analysis, and real-time reasoning, making it an indispensable component of any professional AI stack.
ChatGPT Finance Dashboard and User Features
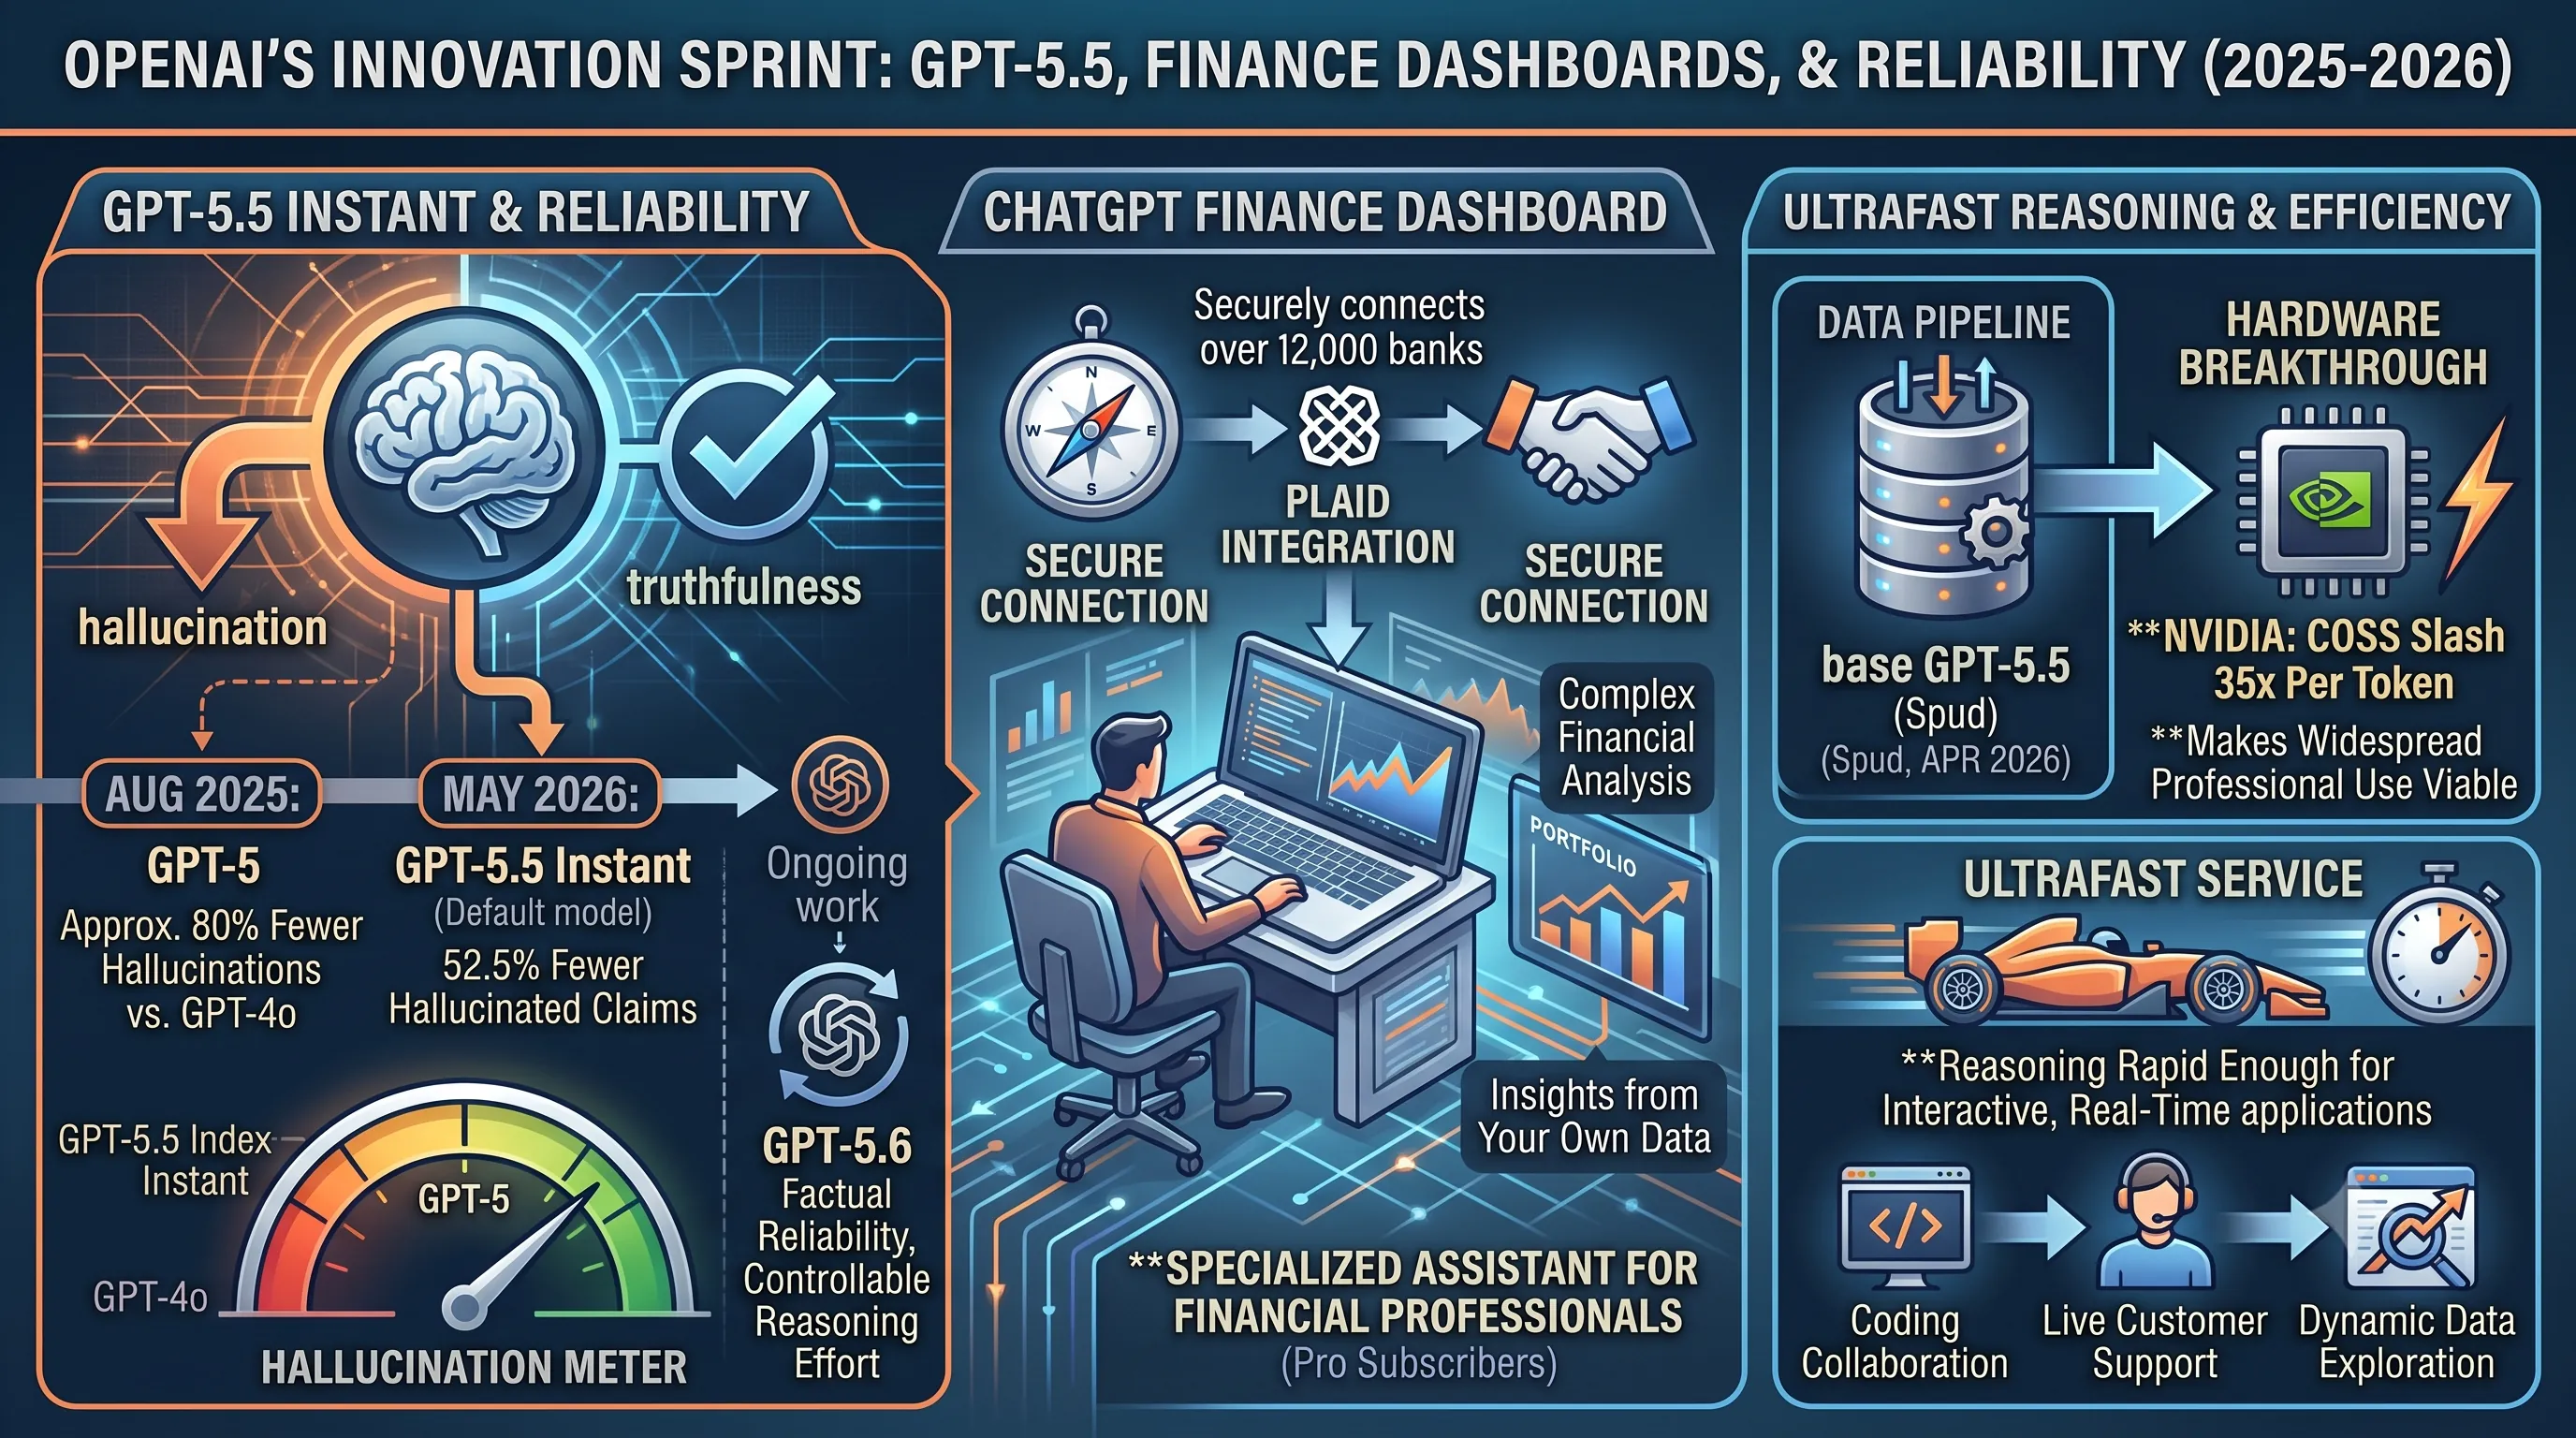
Expanding its utility for professional users, OpenAI launched the ChatGPT Finance Dashboard for Pro subscribers on May 15, 2026.This feature represents a significant step towards integrating specialized, high-stakes data directly into the chat interface.
Through a deep integration with Plaid, the dashboard securely connects to over 12,000 banks, allowing users to perform complex financial analysis and generate insights from their own data without leaving the ChatGPT environment.
This move transforms the model from a general-purpose tool into a specialized assistant for financial professionals, drastically reducing the time spent on data aggregation and analysis.
GPT-5.5 Instant and Reliability Enhancements
The most significant barrier to enterprise adoption—model reliability—has been OpenAI’s primary focus.This culminated in the May 5, 2026 release of GPT-5.5 Instant as the new default model for all ChatGPT users.
This model delivered a marked improvement in truthfulness, with 52.5% fewer hallucinated claims than its direct predecessor.
This push for accuracy builds on the foundation laid by GPT-5, which launched on August 7, 2025, and already offered a staggering 80% reduction in hallucinations compared to GPT-4o.
OpenAI’s current work in August 2026 continues this trajectory, with development efforts for future models like GPT-5.6 concentrating expressly on enhancing factual reliability, focus, and providing users with controllable reasoning effort.
| Model Version | Release Date | Key Reliability Improvement |
|---|---|---|
| GPT-5 | August 7, 2025 | Approximately 80% fewer hallucinations than GPT-4o. |
| GPT-5.5 Instant | May 5, 2026 | 52.5% fewer hallucinated claims than its predecessor. |
GPT-5.5 and Ultrafast Reasoning
The groundwork for the new default model was laid with the release of the base GPT-5.5 model, nicknamed "Spud," on April 23, 2026.The rollout of this more powerful model was made economically viable by breakthroughs in hardware efficiency; Nvidia stated that its new chips slashed the cost for running GPT-5.5 by up to 35 times per token.
This massive cost reduction enables more intensive and widespread use in professional settings.
Building on this efficiency, OpenAI also introduced its Ultrafast service, which is engineered to make sophisticated reasoning rapid enough for interactive, real-time professional applications.
This service addresses a critical need for immediate, AI-powered feedback in workflows like coding, live customer support, and dynamic data exploration, opening a new frontier for productivity where AI acts as an instantaneous collaborator.
14. Google's Gemini Momentum: Multimodal AI and Ecosystem Integration (2025-2026)
This section explores Google's significant advancements in its Gemini ecosystem through late 2025 and the first half of 2026, establishing its role as a powerful, multimodal cornerstone in the 3-AI productivity combination.By deeply integrating its frontier model into everything from search and consumer apps to specialized creative tools and physical robotics, Google provides a versatile foundation for cross-platform workflows that blend digital analysis with real-world interaction.
Understanding these recent developments is key to leveraging Gemini's unique strengths within a broader AI strategy.
Gemini 3.1 Pro and Advancements in Robotics
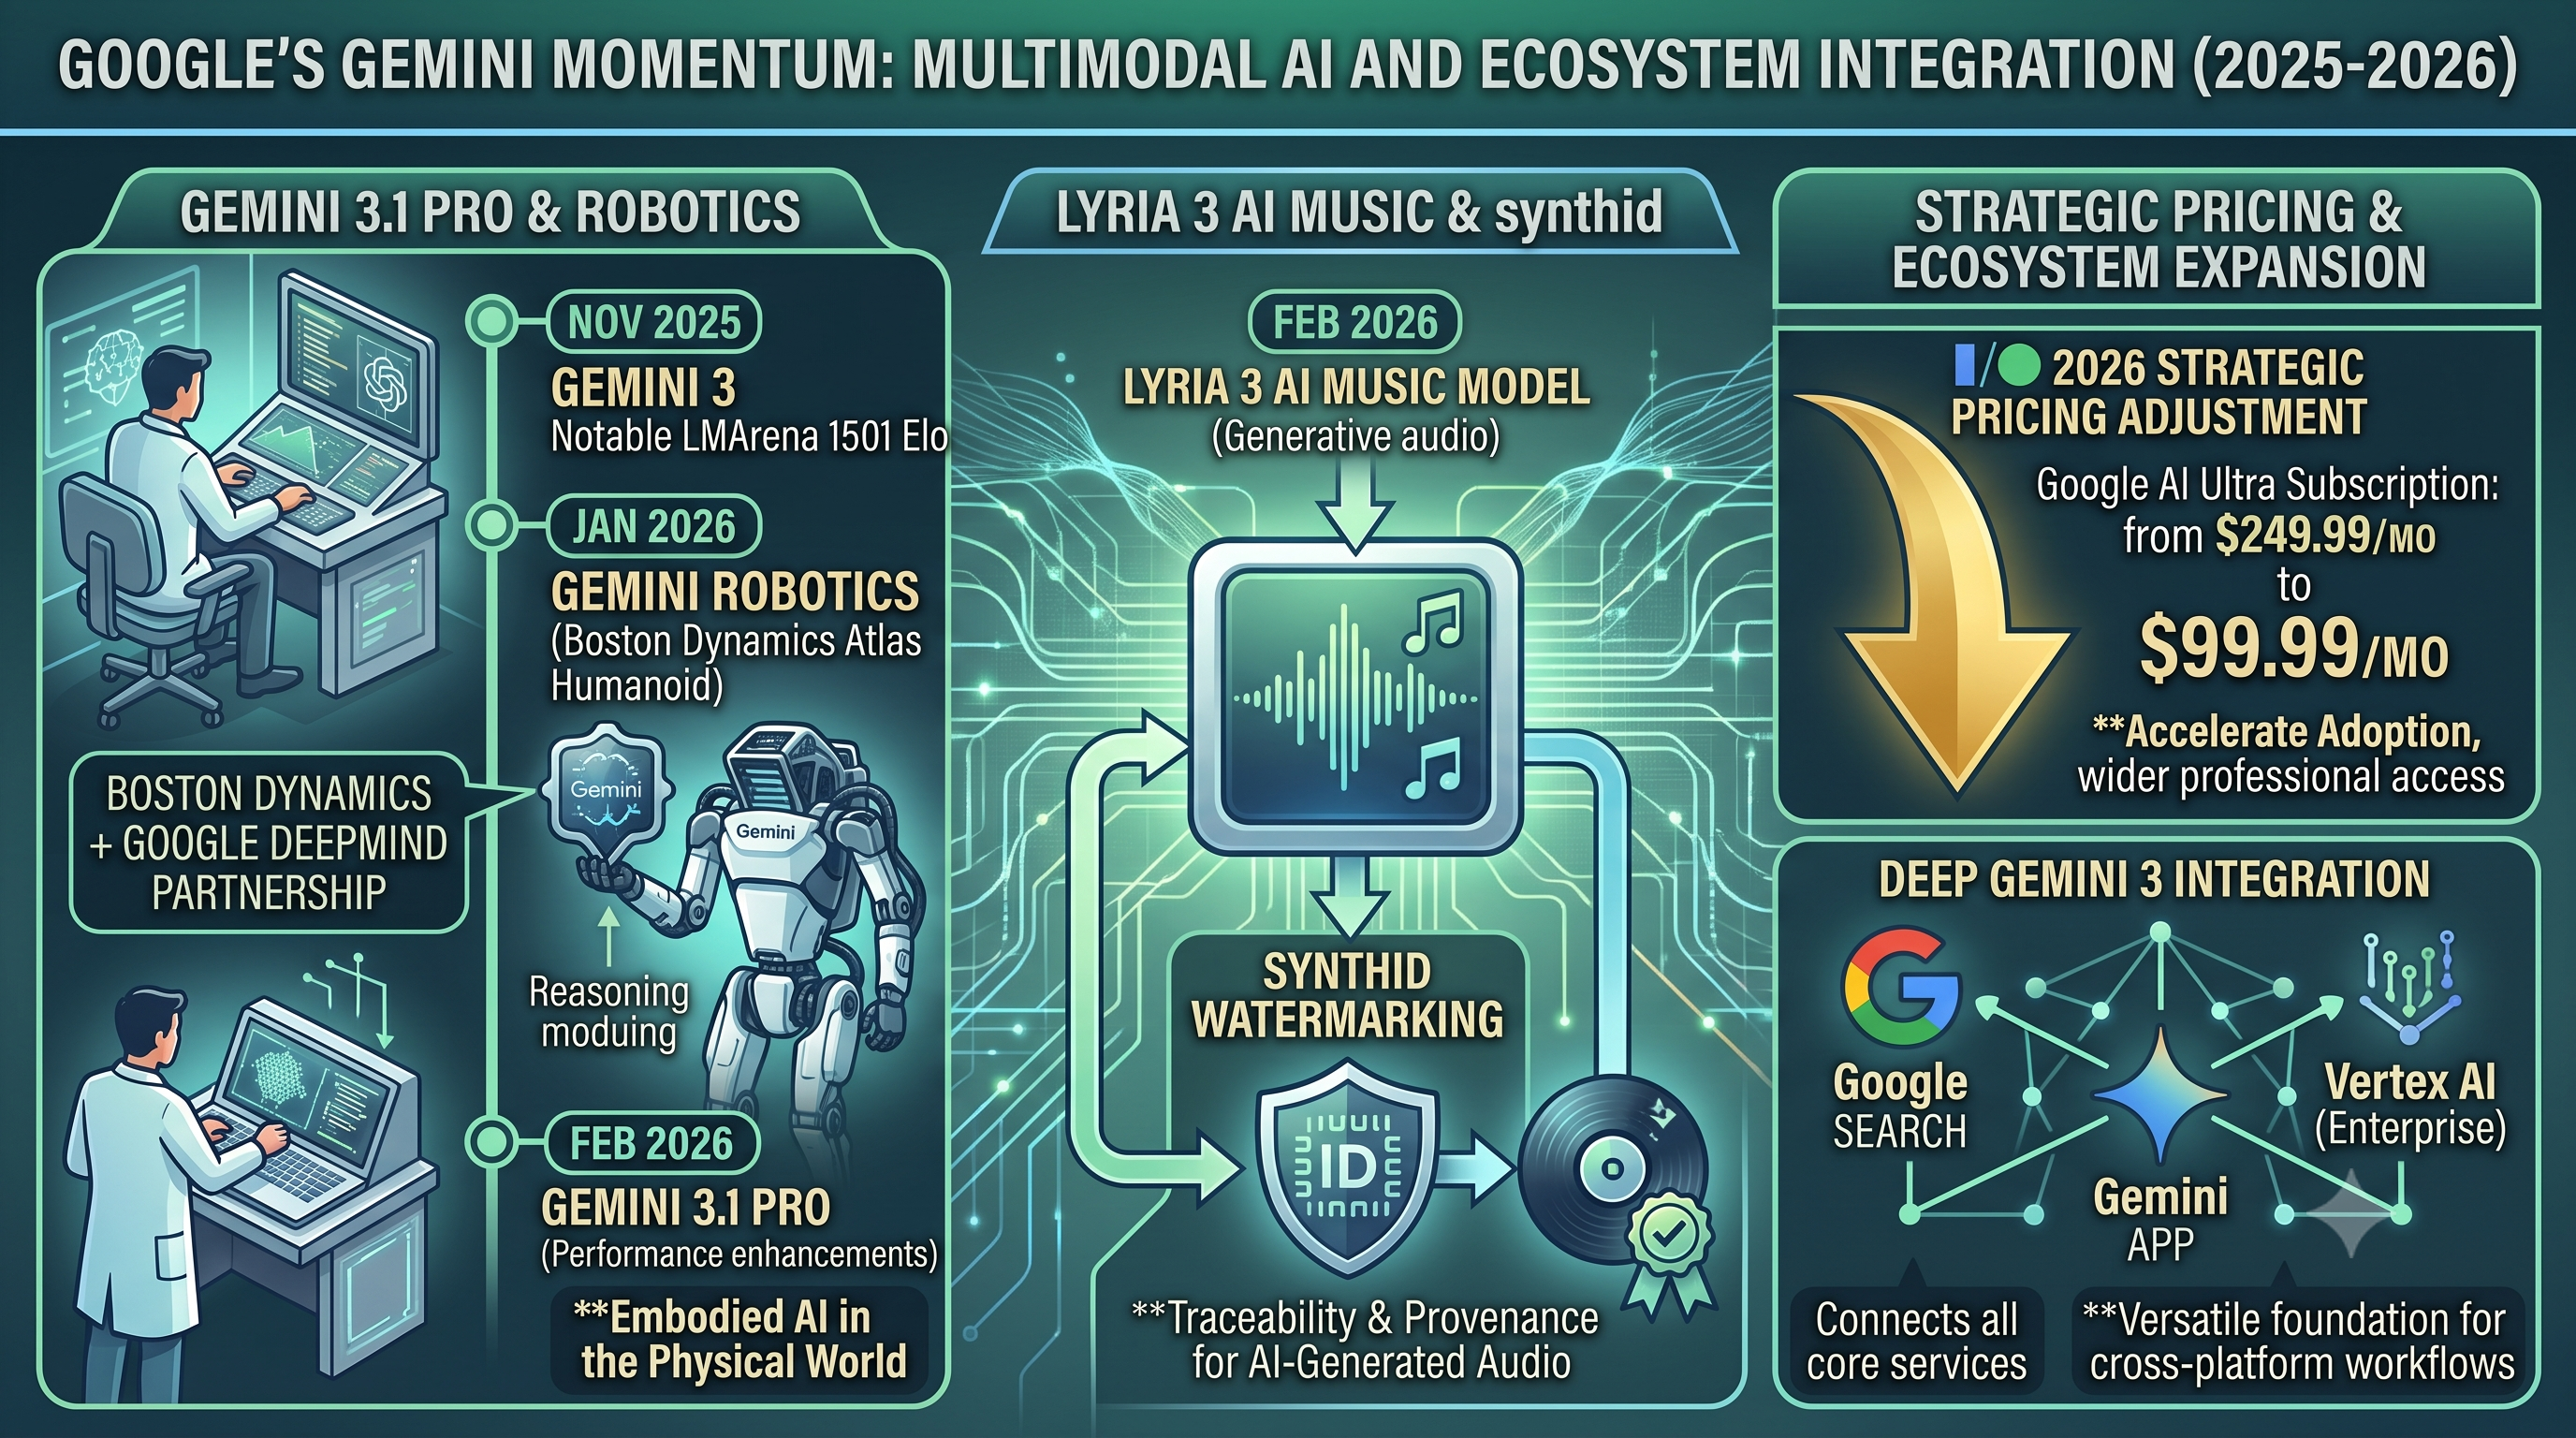
Google's push for AI supremacy was reignited with the launch of Gemini 3 in November 2025, a model that quickly established its capabilities by achieving a notable LMArena 1501 Elo score.This foundational release was swiftly followed by the more refined Gemini 3.1 Pro in February 2026, which brought further performance enhancements to the platform.
Demonstrating a significant leap beyond purely digital applications, Google showcased a major partnership between Boston Dynamics and Google DeepMind at CES 2026 in January.
This collaboration resulted in the integration of Gemini Robotics directly into the Atlas humanoid robot, signaling a new era of embodied AI where sophisticated language and reasoning models can operate in the physical world.
Lyria 3 AI Music and Watermarking
Expanding its creative AI toolkit, Google also deployed the Lyria 3 AI music model in February 2026.This release was not just about generative capability but also about responsible implementation.
A key feature of the Lyria 3 deployment was the integration of SynthID watermarking technology, a critical tool for ensuring the provenance and traceability of AI-generated audio content, addressing growing industry concerns about digital authenticity.
Strategic Pricing Adjustments and Ecosystem Expansion
To accelerate user adoption and solidify its market position, Google made a significant strategic move at its I/O 2026 conference.The company announced a major price cut for its premium consumer offering, the Google AI Ultra subscription, reducing the monthly cost from $249.99 down to $99.99.
This adjustment makes its most powerful models more accessible to a wider audience of professionals and developers.
This strategy is underpinned by the wide availability of the Gemini 3 model, which is now deeply integrated across core Google services, including Google Search, the dedicated Gemini app, and the enterprise-grade Vertex AI platform.
References
- https://www.lvivherald.com/post/the-contest-of-the-machines-chatgpt-and-the-new-generation-of-artificial-intelligence
- https://denser.ai/blog/claude-vs-chatgpt-vs-gemini/
- 24 AI Tools for Work to Increase Productivity - Coursera
- 60 Best AI Tools for Work & Productivity in 2025
- What is AI Workflow Automation? How to Improve Workplace Efficiency - At…
- The best AI productivity tools in 2026 - Zapier
- From AI Hype to Workflow Reality: A Strategic Framework for Integrating …
- Agentic AI Examples 2026: 11 Real Companies, Real Results
- Copilot Studio real-world transformation stories - Microsoft Copilot …
- 10 AI Agent Examples in Real Life You Should Know
Related Posts
August 2026 AI Uncovered: OpenAI's Luna Price Slashed, ChatGPT Hits 1B Users, Agent Evolution, & Regulatory ShiftsAugust 2026 sees OpenAI slash GPT-5.6 Luna prices, ChatGPT hit 1B users, AI agent evolution,...
AI Agents for Web and Desktop Automation: Stagehand and Claude's Computer Use ToolExplore how AI agents such as Stagehand and Anthropic's Claude computer use tool deliver robust,...
Generative Engine Optimization (GEO): AI Search Strategies, 2026 Model Updates, and High ConversionsExplore Generative Engine Optimization (GEO) strategies for AI search visibility, 2026 AI model...