
Mastering Gemini's AI Thinking: Control Reasoning, Optimize Cost & Unlock Advanced Capabilities
🚀 Key Takeaways
- Gemini models, particularly the 3 and 2.5 series, employ an internal "thinking process" for enhanced reasoning and multi-step planning.
- Users can control Gemini's thought behavior using parameters like
thinkingLevelfor Gemini 3+ andthinkingBudgetfor Gemini 2.5+. - The API offers thought summaries and signatures, providing insight into the model's reasoning and maintaining context across multi-turn interactions.
- Costs for thinking-enabled models are based on the total number of output tokens plus internal thought tokens generated.
- Optimizing thinking settings based on task complexity and best practices is crucial for efficient and effective use of Gemini's advanced capabilities.
The era of truly intelligent AI is here, marked by models that can engage in complex internal reasoning before generating a response.
Google's Gemini 3 and 2.5 series models exemplify this advancement, equipped with a sophisticated "thinking process" designed to tackle the most demanding computational and creative challenges, making them invaluable tools for innovation.
For developers and users leveraging the Gemini API, mastering these inference capabilities, particularly with models like the Gemini 3.7 Flash, is paramount to unlocking their full potential.
This guide delves into effectively managing Gemini's thinking behavior, from controlling reasoning depth with parameters like
By applying task-specific settings and adhering to best practices, you can finely tune Gemini's problem-solving approach.
This ensures optimal performance and efficiency across a spectrum of applications, from intricate coding and advanced mathematics to detailed data analysis, ultimately leading to smarter AI interactions.
Google's Gemini 3 and 2.5 series models exemplify this advancement, equipped with a sophisticated "thinking process" designed to tackle the most demanding computational and creative challenges, making them invaluable tools for innovation.
For developers and users leveraging the Gemini API, mastering these inference capabilities, particularly with models like the Gemini 3.7 Flash, is paramount to unlocking their full potential.
This guide delves into effectively managing Gemini's thinking behavior, from controlling reasoning depth with parameters like
thinkingLevel to understanding the cost implications and leveraging thought insights for debugging and optimization.By applying task-specific settings and adhering to best practices, you can finely tune Gemini's problem-solving approach.
This ensures optimal performance and efficiency across a spectrum of applications, from intricate coding and advanced mathematics to detailed data analysis, ultimately leading to smarter AI interactions.
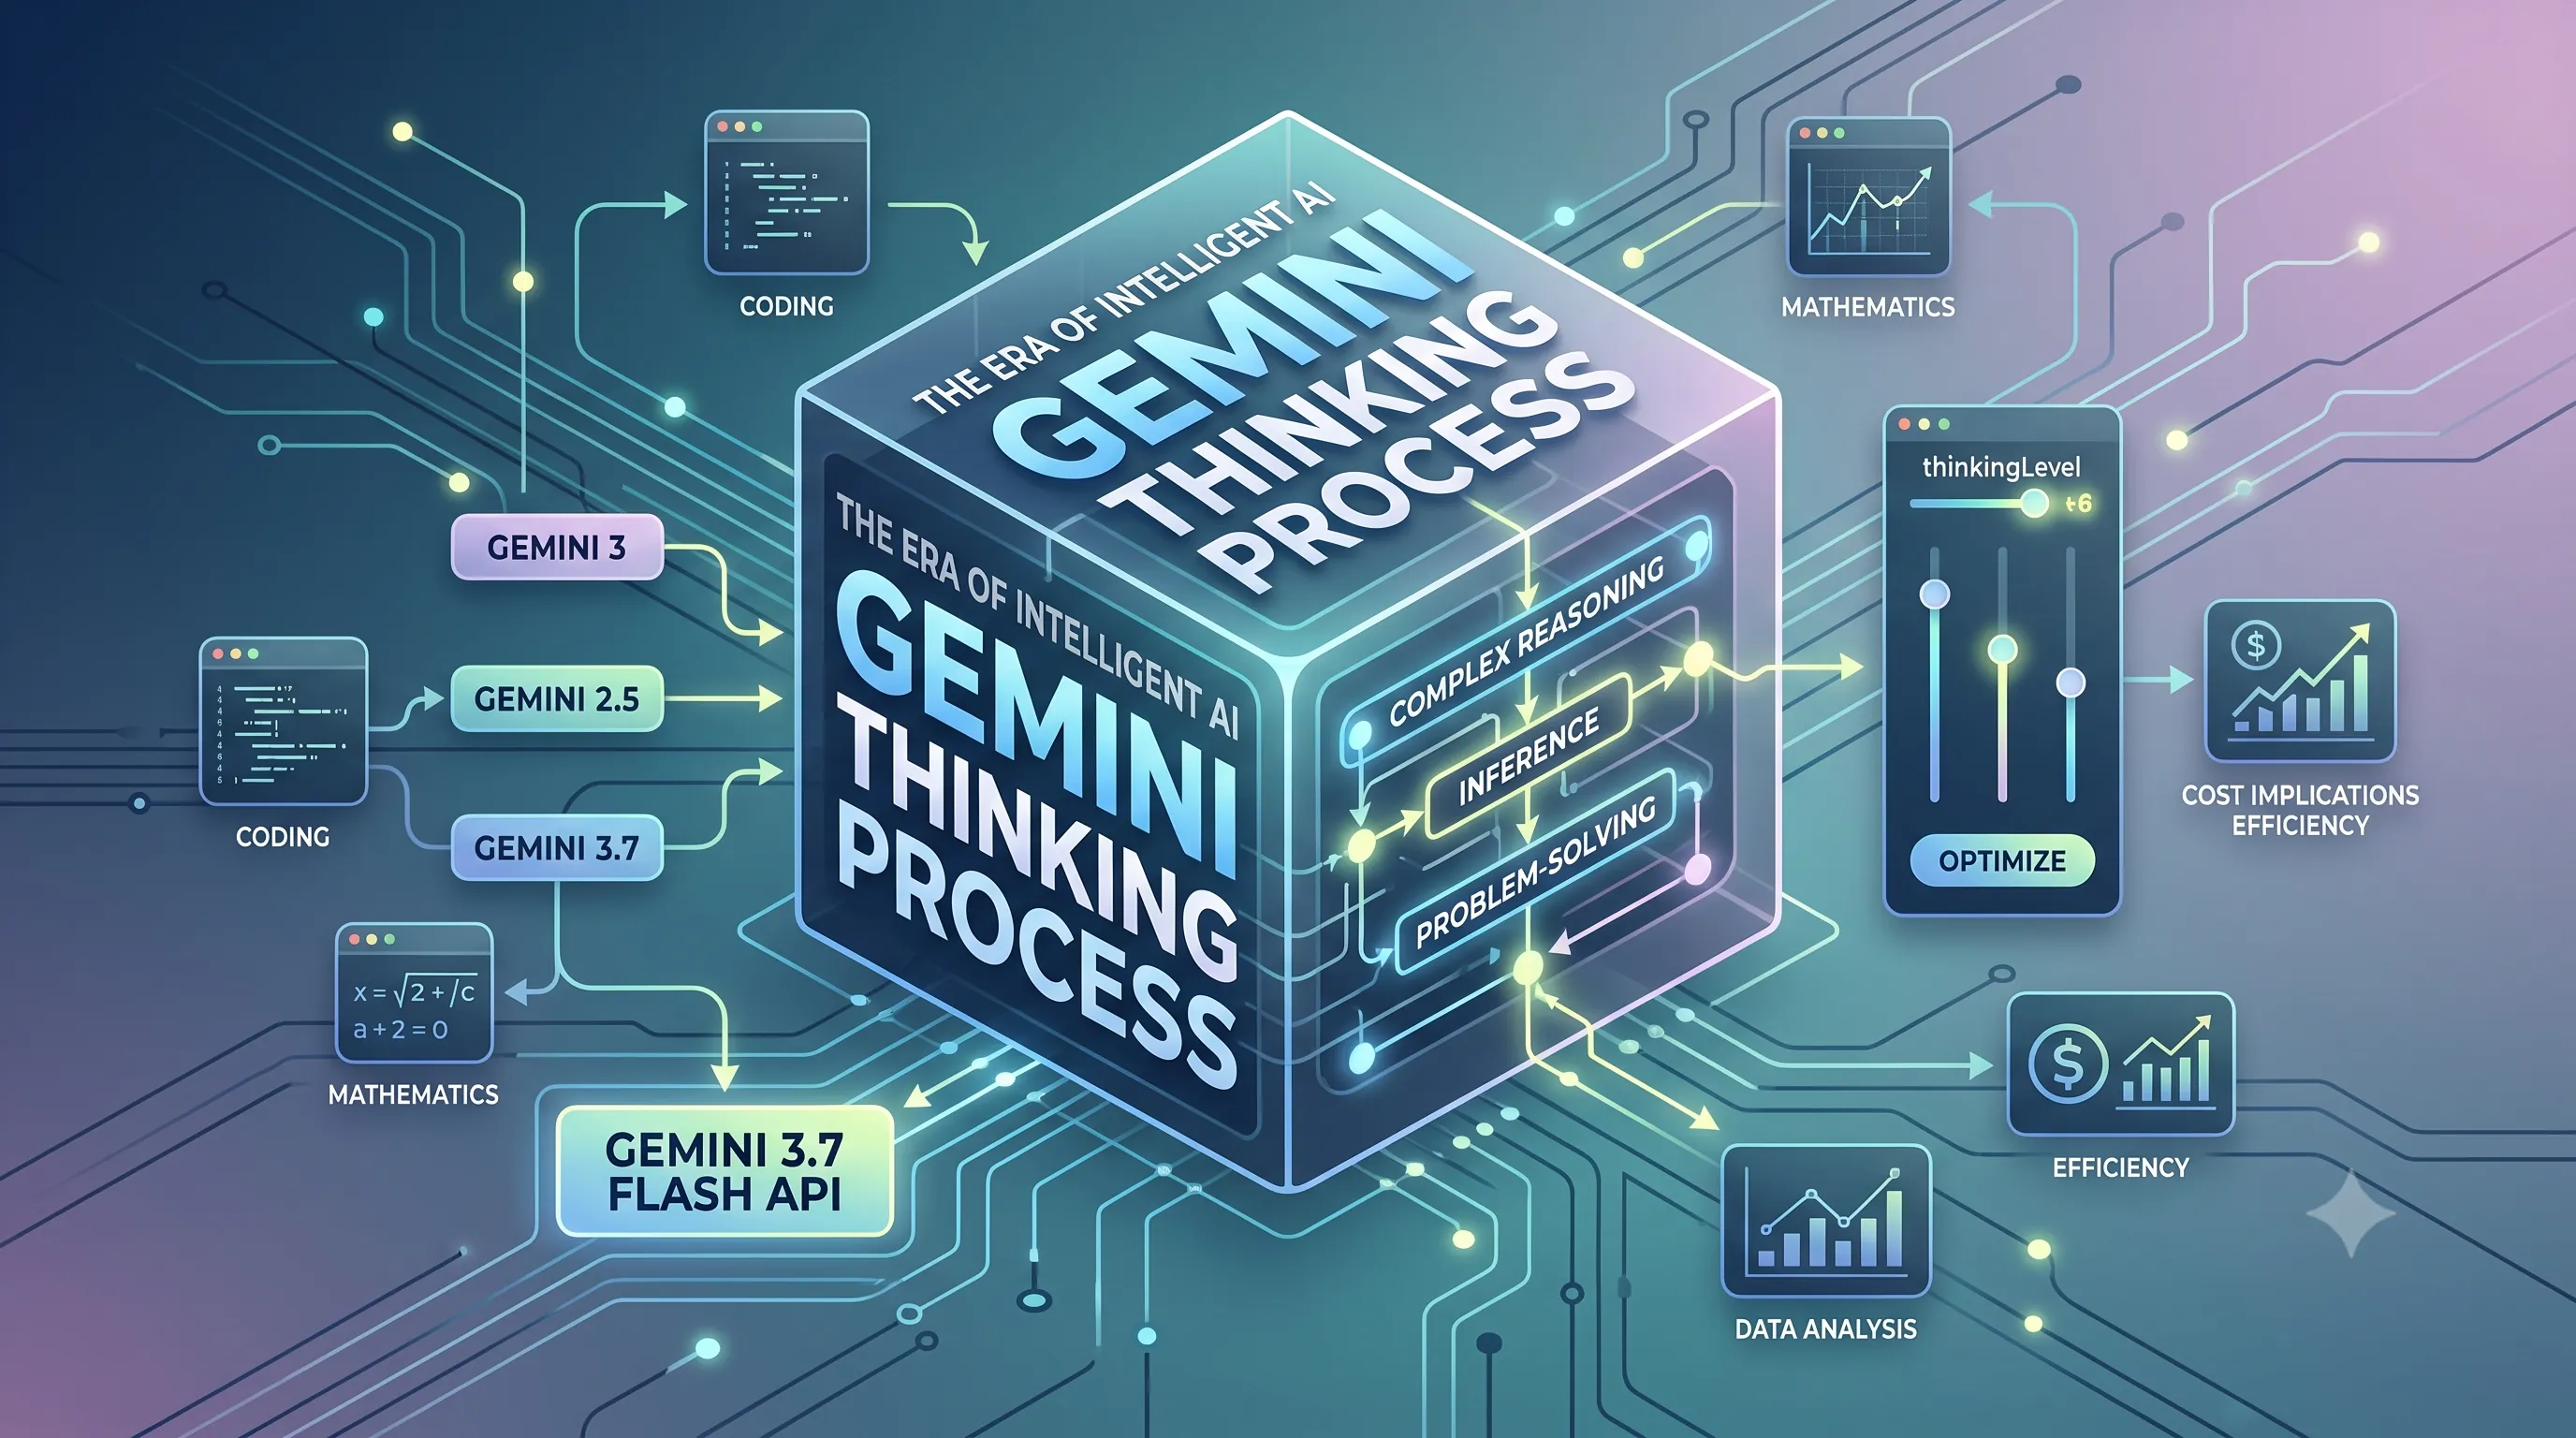
1. Gemini's 'Thinking Mode': Powering Advanced Reasoning
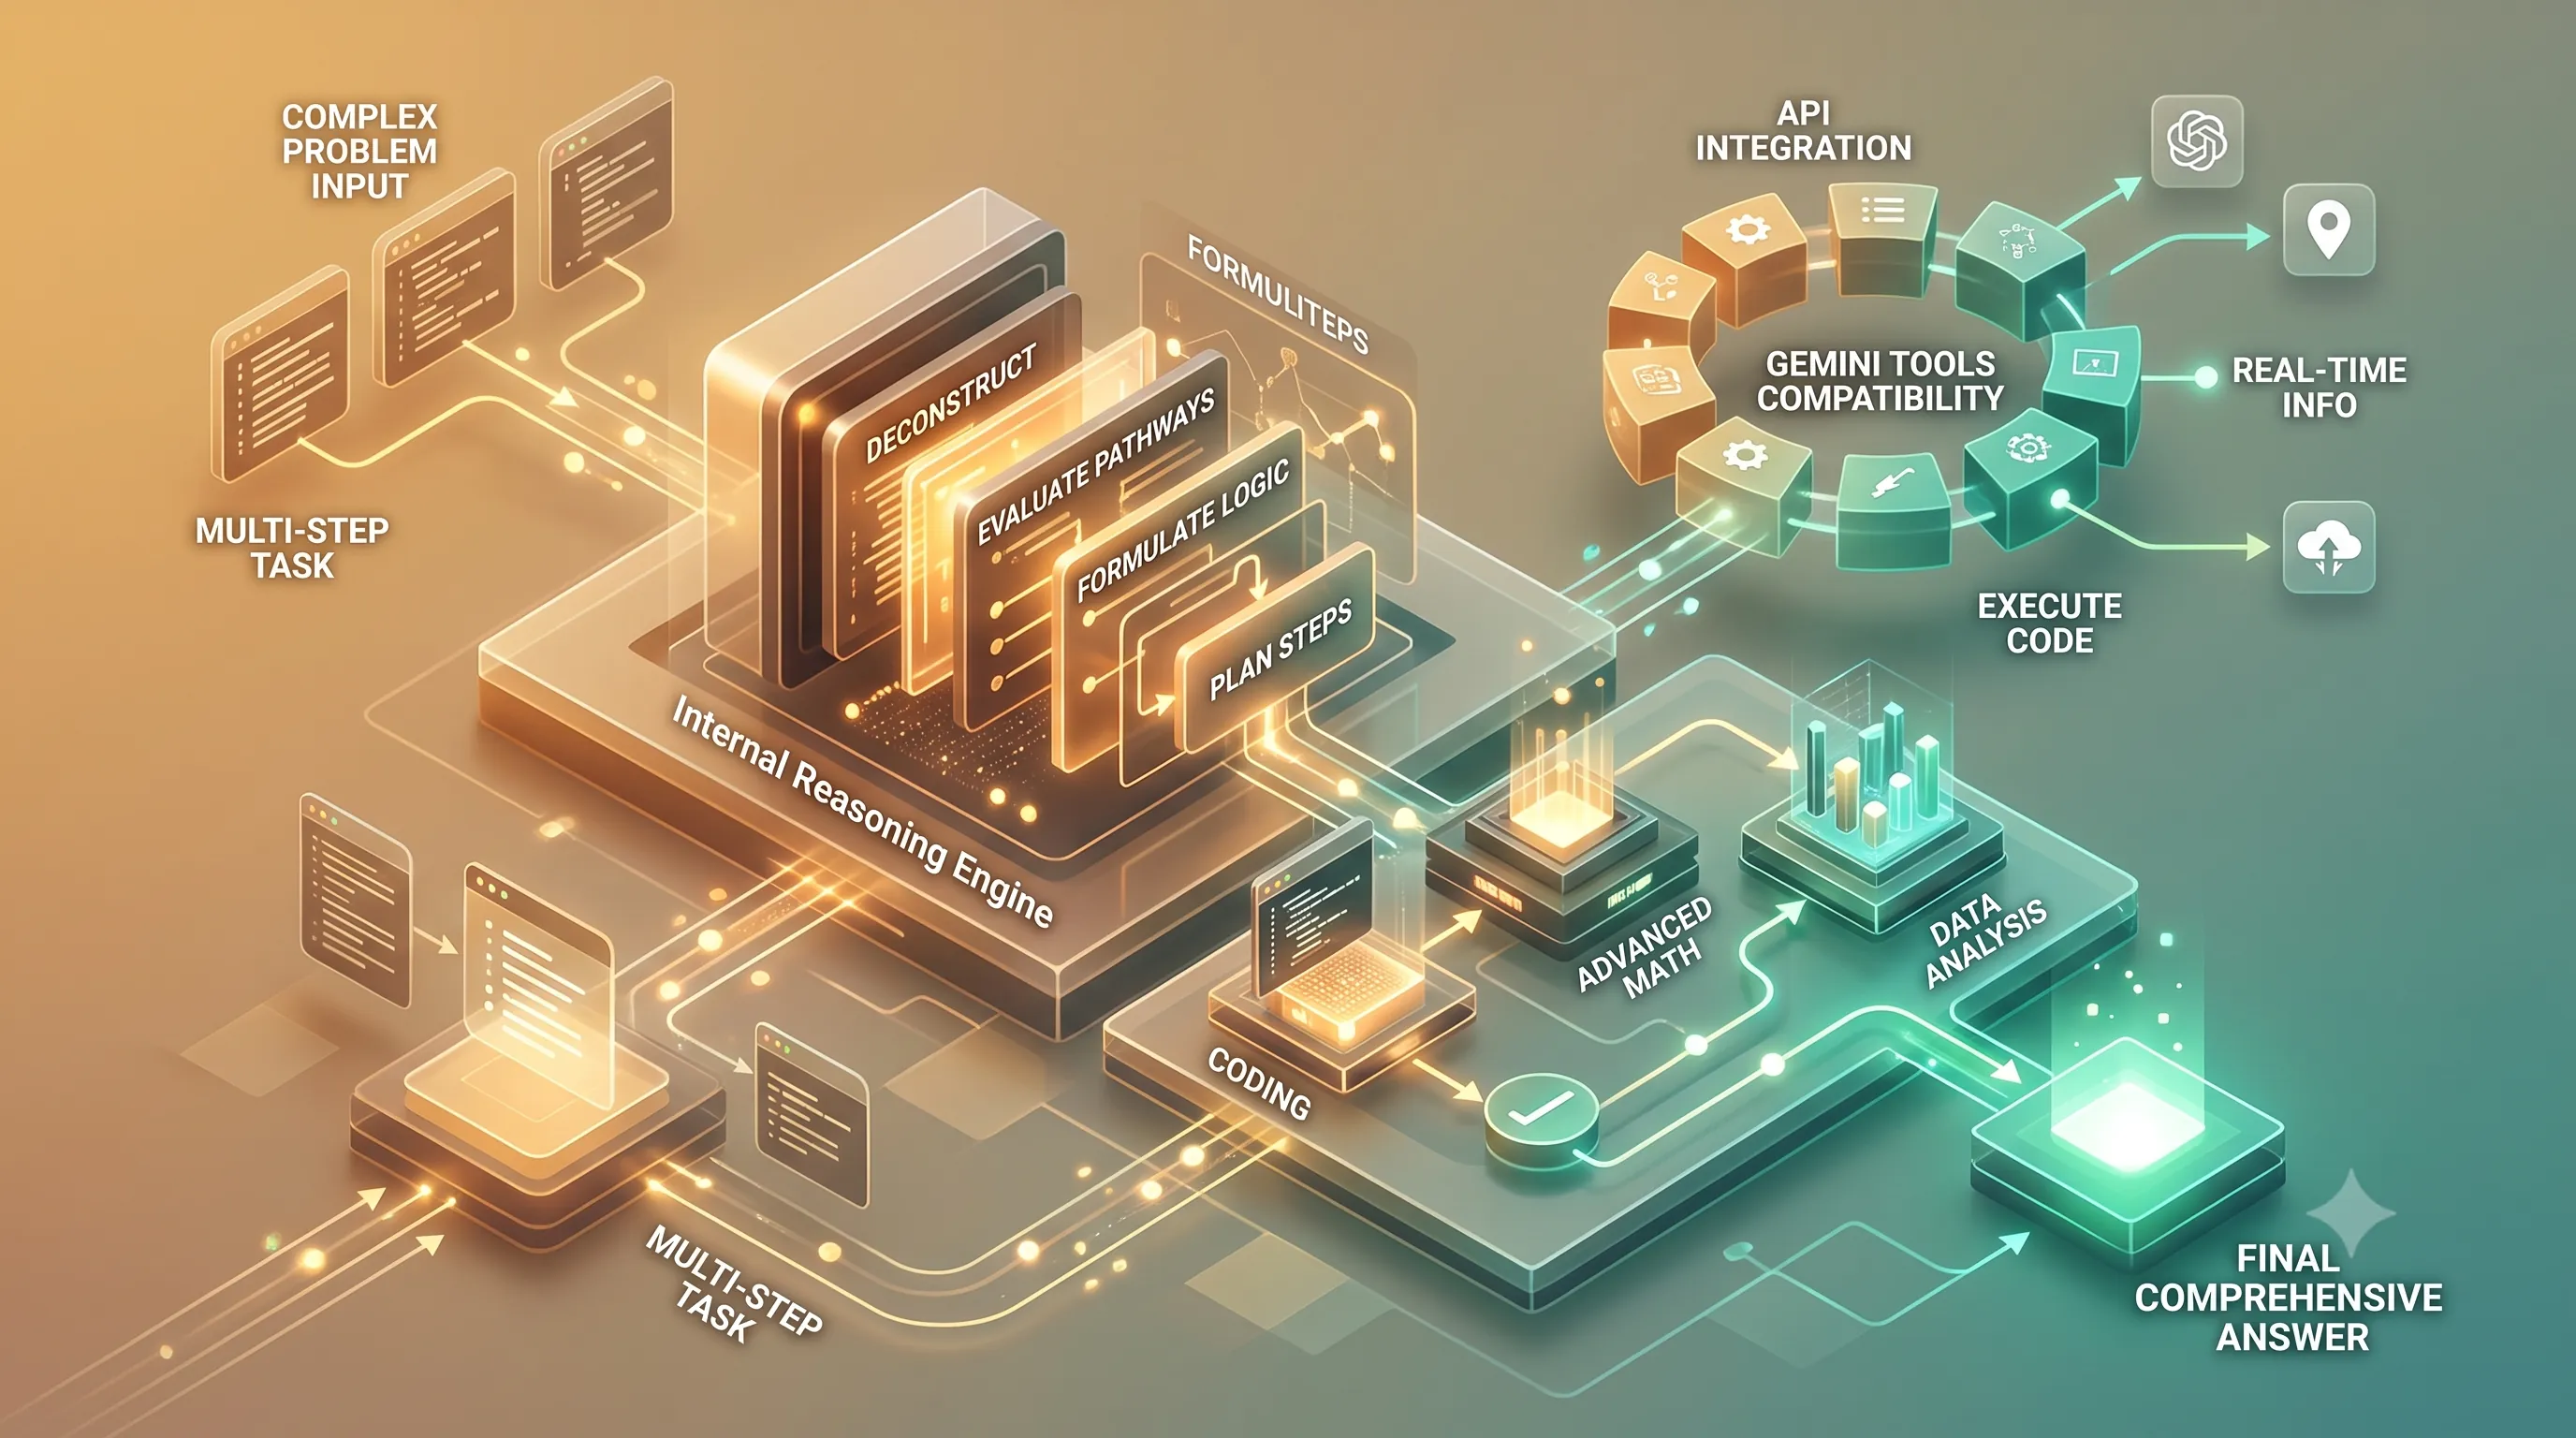
This section explores the foundational technology behind the user-configurable 'Thinking Level' settings, detailing the internal reasoning process that enables Gemini models to tackle complex, multi-step problems.The Internal Reasoning Engine
At the core of the advanced capabilities discussed in this article is an internal 'thinking process' native to the Gemini 3 and 2.5 series models.This is not merely faster processing, but a fundamental enhancement to how the models operate, designed to significantly improve their capacity for sophisticated reasoning and multi-step planning.
By engaging this internal process, the models can deconstruct problems, evaluate potential pathways, and formulate more coherent and logical solutions than was previously possible.
Applications in Complex Tasks
The practical benefit of this internal thinking is most evident in its application to highly demanding domains.This enhanced reasoning makes the Gemini 3 and 2.5 models highly effective for a range of complex tasks.
Specific areas that see a substantial performance boost include disciplines like coding, advanced mathematics, and in-depth data analysis, where breaking down a problem into sequential, logical steps is critical for success.
API Integration and Tool Compatibility
For developers and organizations looking to harness this power, the 'thinking' feature is directly accessible via the Gemini API.Initiating a request with this capability is straightforward: developers simply need to specify one of the thinking-supported models in the 'model' field of their API call.
Crucially, this advanced reasoning is not a niche feature; thinking capabilities are supported in all Gemini 3 and 2.5 series models.
Furthermore, these thinking models maintain full compatibility with all existing Gemini tools and features.
This integration is key, as it enables the models to interact with external systems, execute code, or access real-time information as part of their reasoning process to formulate comprehensive final answers.
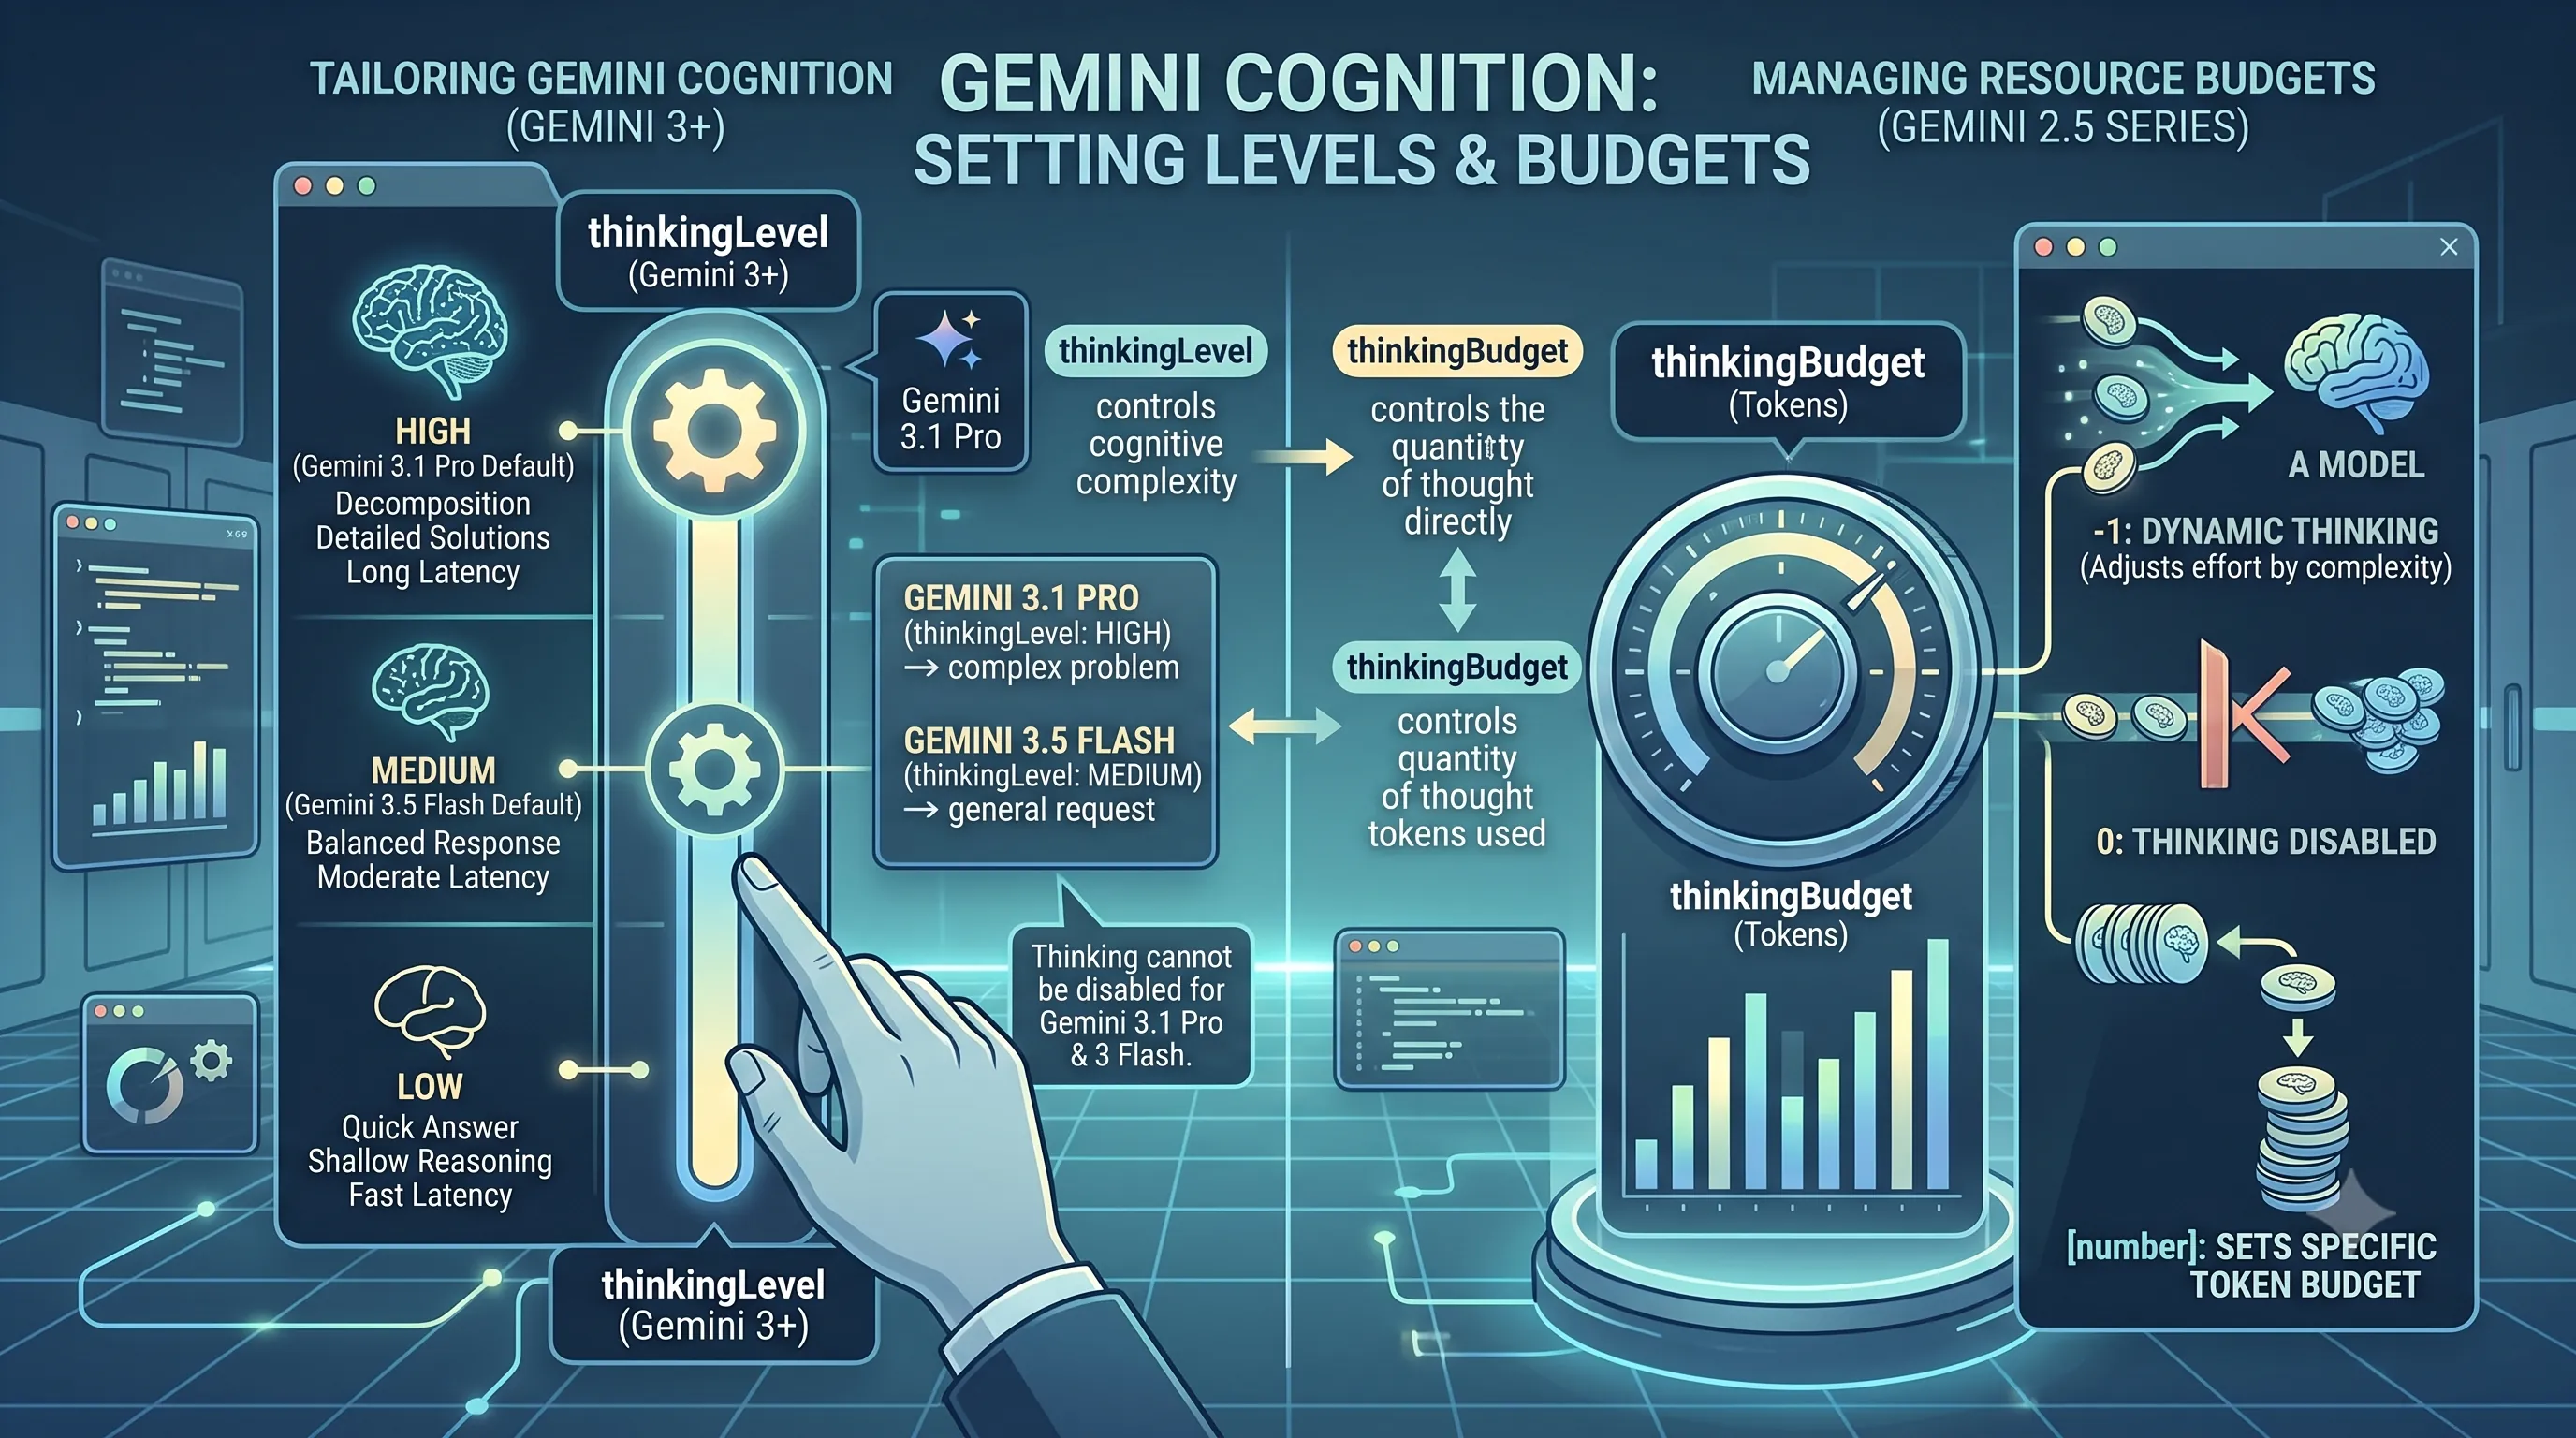
2. Tailoring AI's Cognition: Setting Gemini's Thinking Levels and Budgets
This section provides the technical foundation for our broader discussion on "Smartly Handling Thinking AI".Here, we dissect the specific parameters you can use to direct Gemini's cognitive processes, explaining how to set reasoning levels and resource budgets to tailor the AI's performance for any given task.
Dynamic Thinking by Default
By default, Gemini models operate with dynamic thinking.This means the AI automatically assesses the complexity of a user's request and adjusts its reasoning effort accordingly, dedicating more cognitive resources to difficult problems and fewer to simple ones.
While this autonomous behavior is efficient, users can optionally control the thinking process using specific parameters.
This level of control is particularly useful when working under strict latency constraints where a faster, less-reasoned answer is preferable, or conversely, when you need to ensure the model engages in deeper, more thorough reasoning for a complex problem.
Fine-tuning with 'thinkingLevel' (Gemini 3+)
For Gemini 3 models and subsequent versions, the `thinkingLevel` parameter is the recommended method for controlling reasoning behavior.This parameter allows you to set a predefined tier of cognitive effort.
Specifically, Gemini 3.1 Pro offers three distinct settings configurable via the `thinking_level` parameter: LOW, MEDIUM, and HIGH.
If you do not specify a `thinkingLevel`, the model will revert to a default setting, which varies between models.
For instance, the default thinking level for Gemini 3.1 Pro is 'high', while for the speed-optimized Gemini 3.5 Flash, the default is 'medium'.
Managing Resources with 'thinkingBudget' (Gemini 2.5)
The earlier Gemini 2.5 series of models introduced the `thinkingBudget` parameter to manage reasoning resources.It is important to note that models in the Gemini 2.5 series do not support the newer `thinkingLevel` parameter.
The `thinkingBudget` parameter gives you direct control by instructing the model on a specific number of thought tokens to expend on reasoning for a given query.
Setting this parameter to -1 enables dynamic thinking, allowing the model to adjust its token budget based on request complexity, mirroring the default behavior in newer models.
Conversely, setting `thinkingBudget` to 0 explicitly disables the thinking feature for the request.
| Parameter | Applicable Model Series | Description | Key Settings & Effects |
|---|---|---|---|
| thinkingLevel | Gemini 3.0 and newer | Controls reasoning behavior by setting a predefined cognitive effort level. |
|
| thinkingBudget | Gemini 2.5 series | Instructs the model on a specific number of thought tokens to use for reasoning. |
|
Model-Specific Thinking Constraints
It is critical to be aware of certain limitations when attempting to control AI cognition.For some of the most advanced models, the thinking process is integral and cannot be fully turned off.
Thinking cannot be disabled for Gemini 3.1 Pro.
Similarly, the high-speed Gemini 3 Flash and Flash-Lite models do not support the complete disablement of their thinking capabilities, ensuring a baseline level of reasoning is always active.
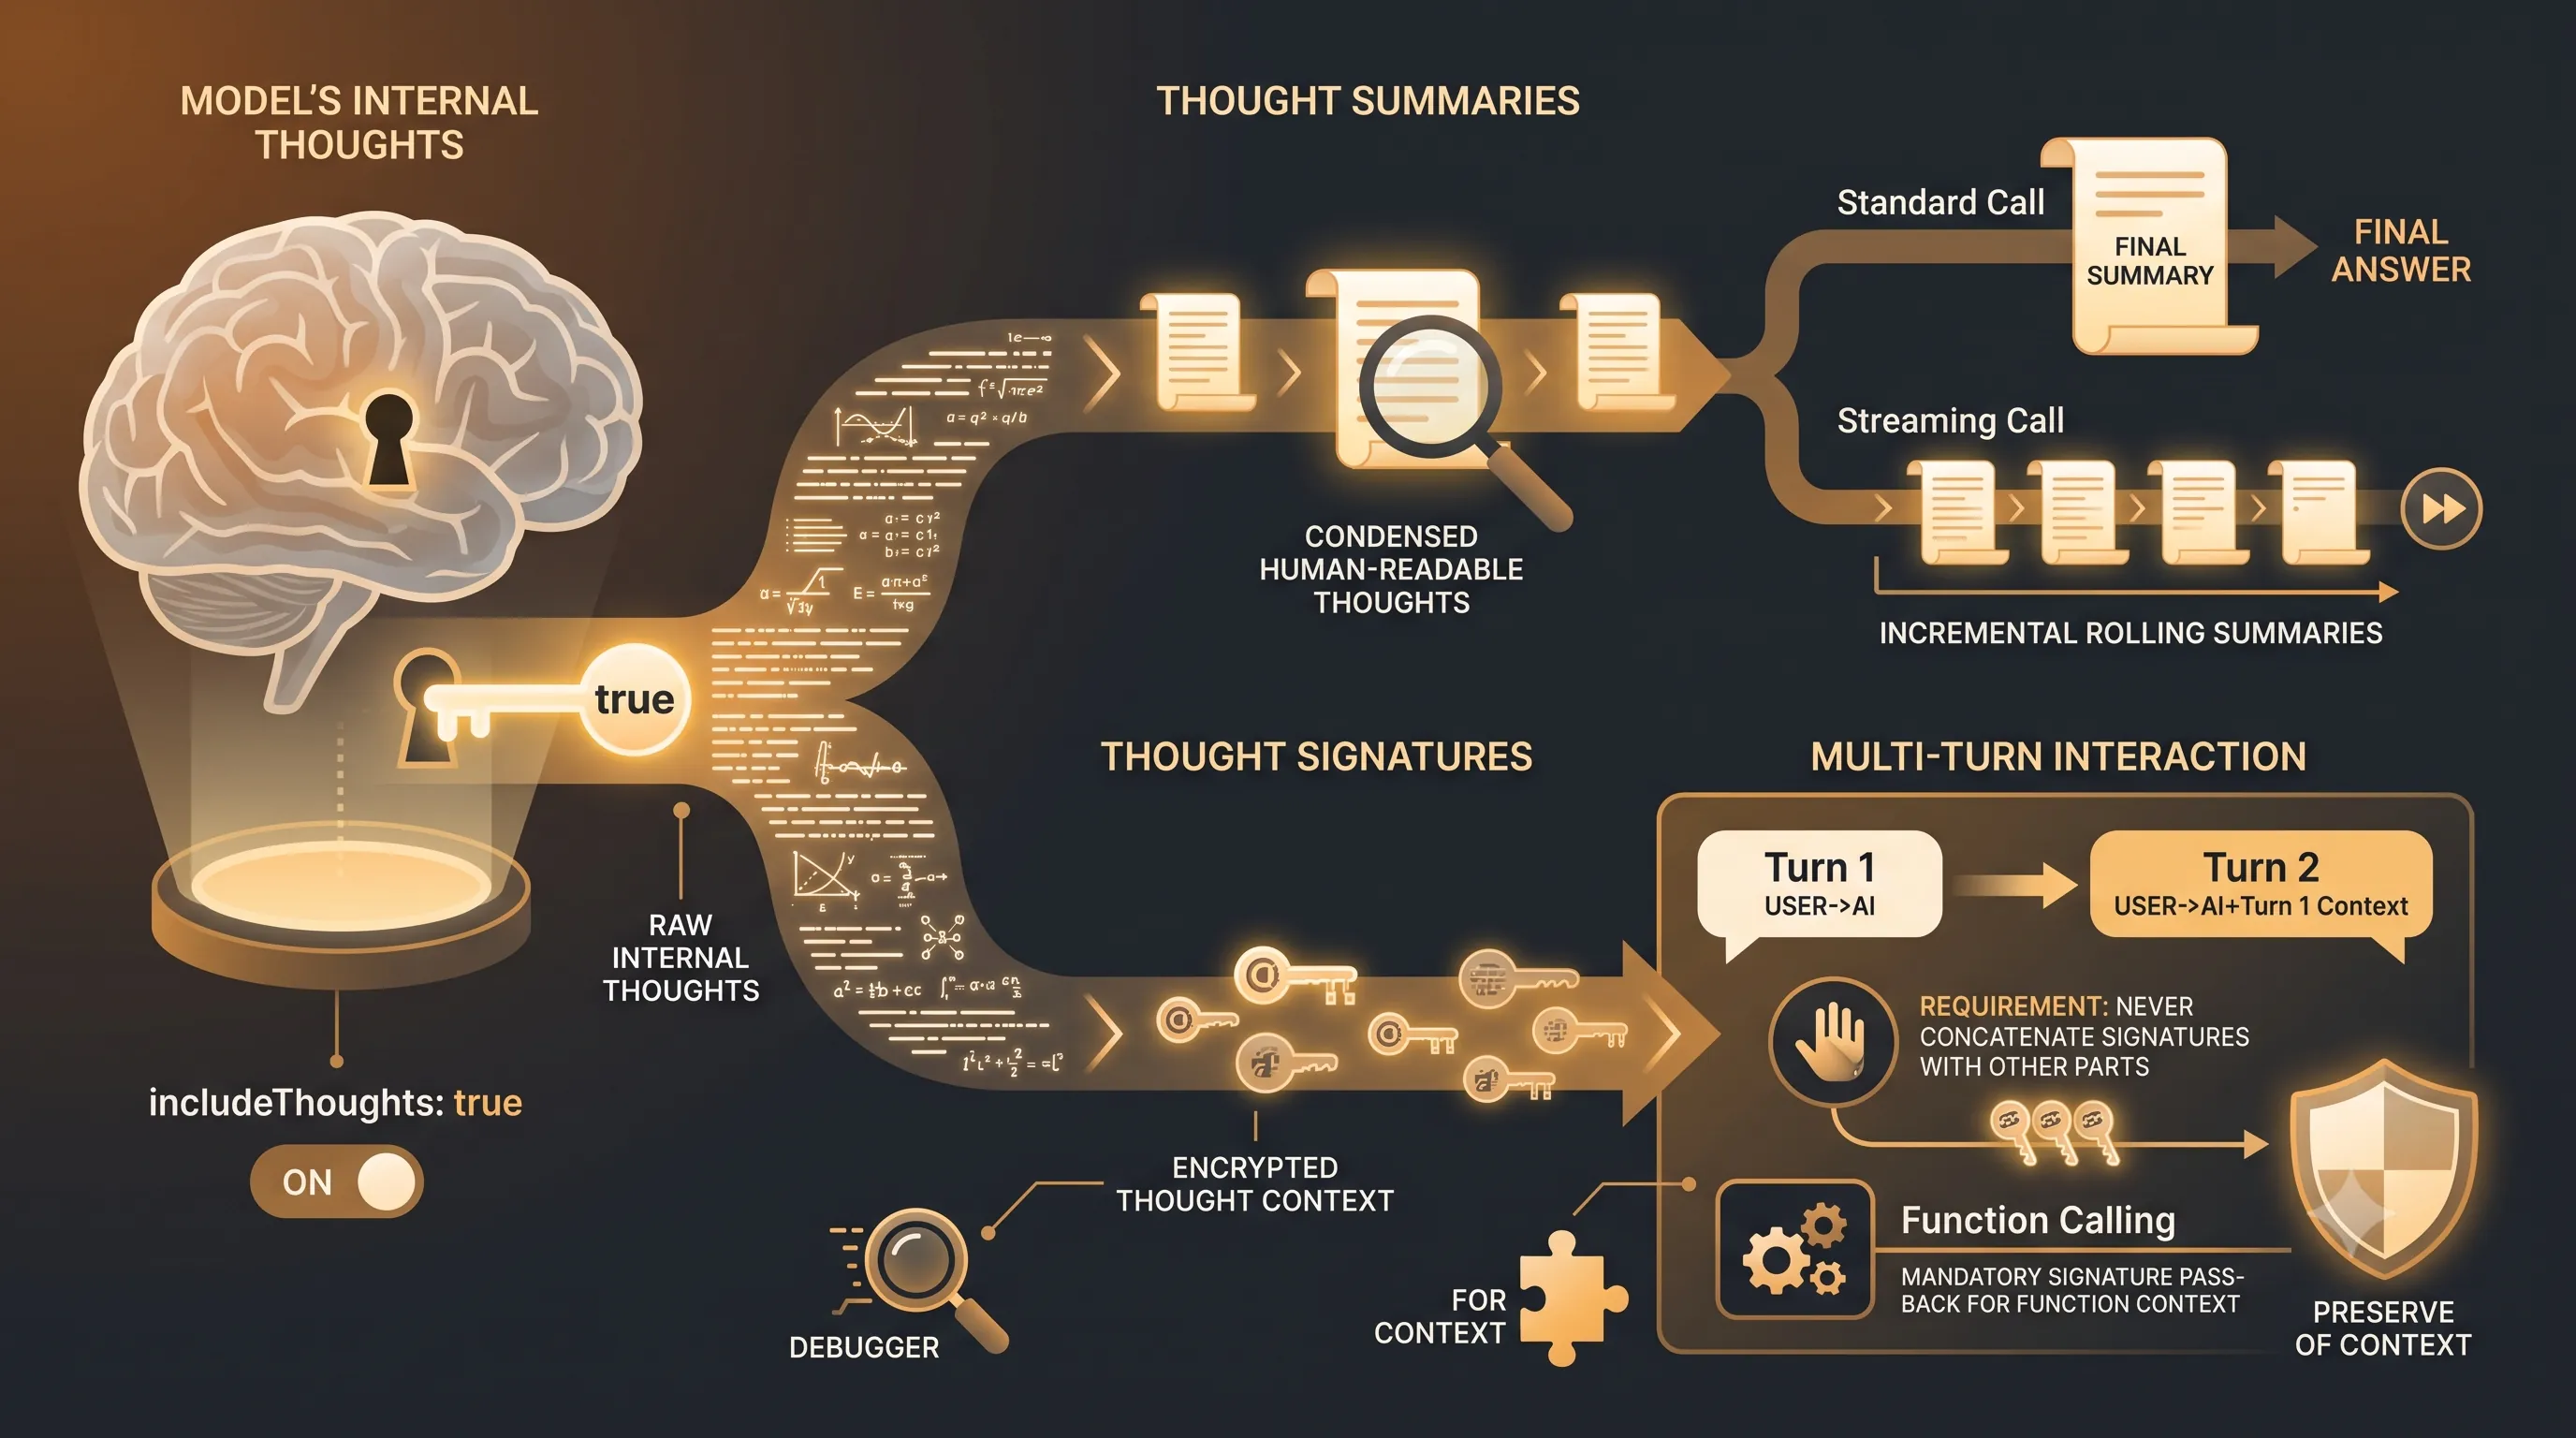
3. Peering into AI's Mind: Extracting Insights with Thought Summaries and Signatures
This section connects directly to the main article's theme of "Smartly Handling Thinking AI" by providing the practical mechanisms to look inside the model's reasoning.Once you've set a 'Thinking Level' for a task, thought summaries and signatures are the tools that allow you to verify the model's approach and maintain its train of thought across complex, multi-step interactions.
Accessing Internal Reasoning with Thought Summaries
To gain visibility into the model's cognitive process, developers can use thought summaries.A thought summary is a condensed, human-readable version of the model's raw, internal thoughts, offering direct insight into its reasoning steps.
You can enable this feature by setting the 'includeThoughts' parameter to 'true' in your API request configuration.
When enabled, the summary can be accessed programmatically by iterating through the 'parts' in the API 'response' and identifying the part where the 'thought' boolean is true.
It is crucial to understand that the thinking levels and compute budgets you configure apply to the model's raw thoughts, not to the resulting summary itself; the summary is merely an output of that deeper process.
Streamed vs. Final Thought Outputs
The delivery of thought summaries differs based on whether you are using a streaming or non-streaming API call.In a standard, non-streaming request, the model completes its entire generation process, and then a single, final thought summary is returned along with the final answer.
This provides a complete, retrospective overview of the model's reasoning from start to finish.
Conversely, when using streaming, the API returns rolling, incremental summaries during the generation process.
This allows you to observe the model's reasoning as it unfolds in near real-time, which is particularly useful for monitoring complex, long-running tasks.
Preserving Context with Thought Signatures
The Gemini API is fundamentally stateless, meaning each request is processed independently without inherent memory of previous interactions.Consequently, models cannot natively access the thought context from a prior turn in a multi-turn conversation.
To solve this, Gemini provides thought signatures, which are an encrypted representation of the model's internal thought process from a given turn.
These signatures act as a key to help the model maintain thought context in subsequent requests.
The implementation of signatures has evolved; Gemini 2.5 models would return them only when thinking was enabled and the request included function declarations.
However, the more advanced Gemini 3 models can return thought signatures for all types of parts, greatly expanding their utility.
You will find these signatures returned from the model embedded within other parts of the response, such as in text or function call parts.
Multi-Turn Interaction Guidelines
Properly managing thought signatures is essential for effective multi-turn interactions.As a best practice, it is recommended to pass back all received signatures from the previous turn in your next request to maintain a cohesive conversational context.
For interactions involving function calling, this practice is not just recommended but required; you must pass back the function call signatures for the model to continue its reasoning chain correctly.
A critical implementation detail is to never concatenate parts that contain signatures with other parts.
Doing so can corrupt the signature's structure and break the contextual link, leading to errors or a loss of continuity in the model's thought process.
4. Optimizing Performance and Cost: Best Practices for Gemini Thinking Modes
This section directly supports the main article's goal of "smartly handling thinking AI" by focusing on the crucial balance between performance and cost.To effectively use Gemini's reasoning capabilities, it is essential to understand the cost implications of enabling the thinking mode and to apply strategic best practices for different types of tasks, ensuring you achieve optimal results without incurring unnecessary expenses.
Understanding Thought Token Pricing
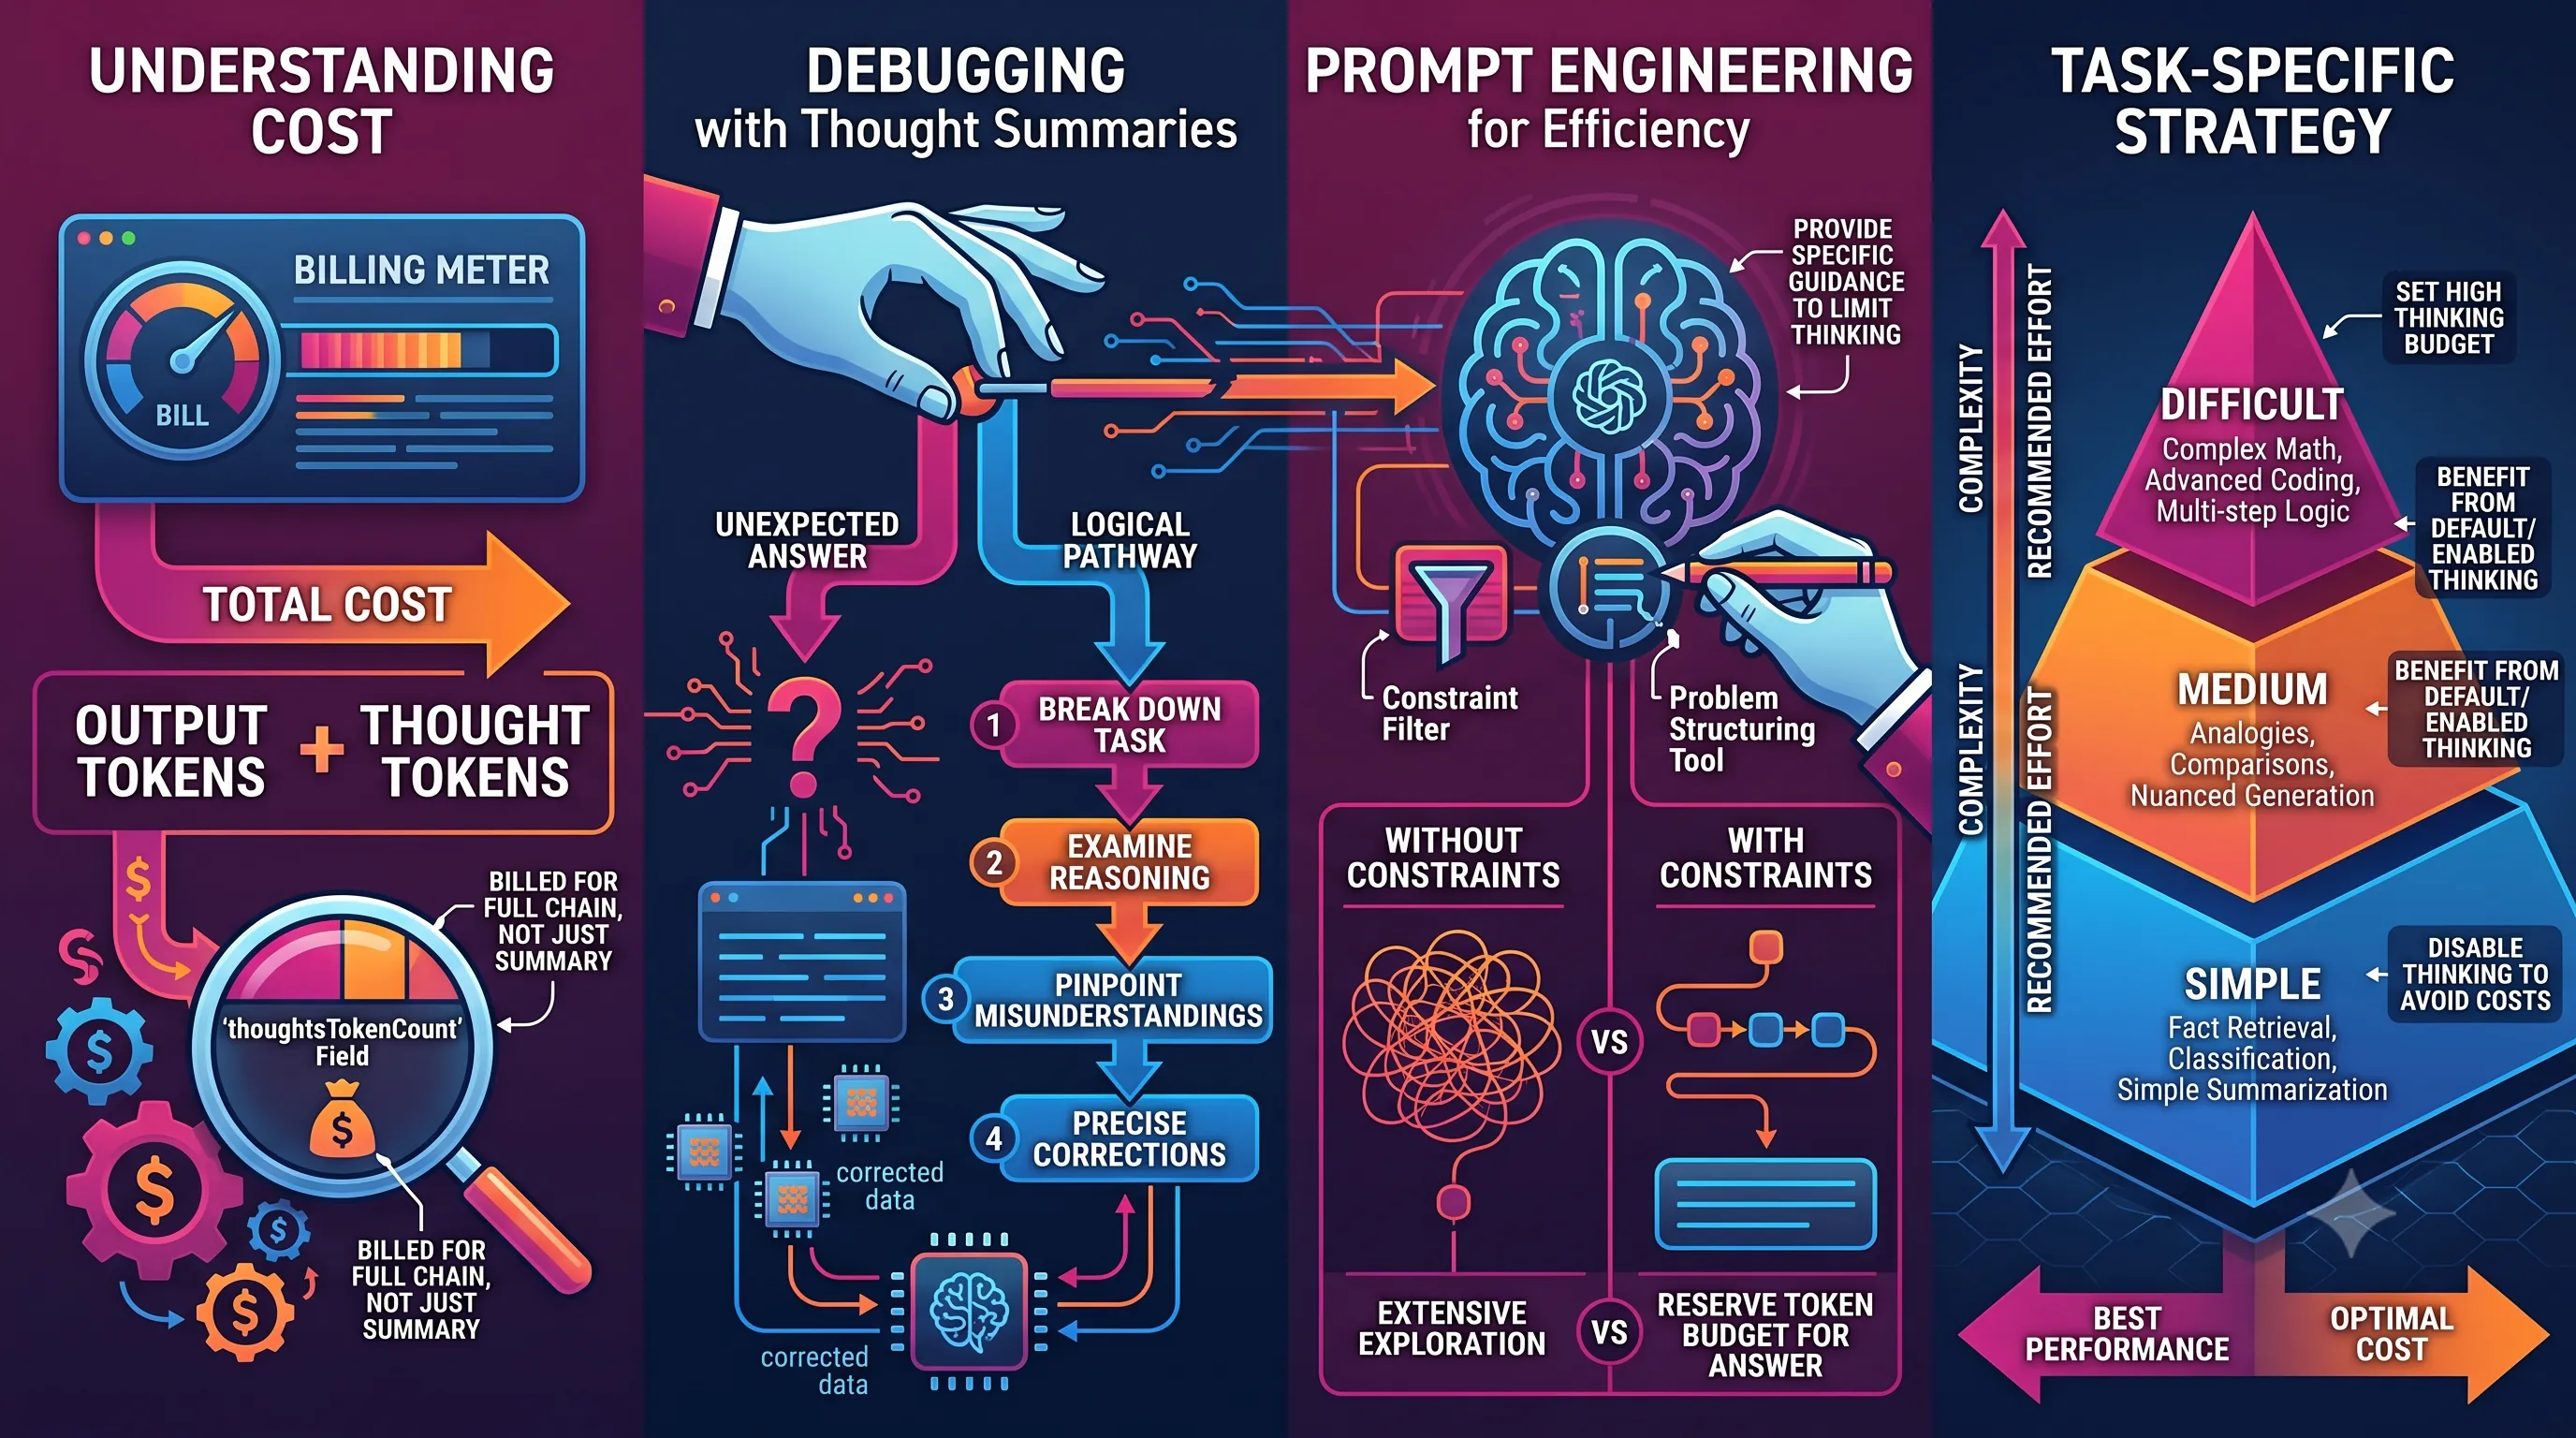
When you enable Gemini's thinking mode, the cost structure for your API call changes.The final price is calculated as the sum of the standard output tokens and the newly introduced thought tokens.
The API response includes a specific field,
'thoughtsTokenCount', which clearly indicates the total number of thought tokens that were generated during the reasoning process to produce the final answer.It is critical to understand that you are billed for the full count of thought tokens generated, even if the API is configured to only return a summary of the model's thoughts.
This means the entire chain of reasoning, planning, and internal monologue contributes to the final cost, not just the portion you see.
Debugging with Thought Summaries
One of the most powerful secondary benefits of the thinking feature is its utility as a debugging tool.If you receive an unexpected or incorrect answer from Gemini, you can analyze its thought summaries to understand its logical pathway.
This transparency allows you to effectively debug the model's performance by reviewing how it reached its conclusions.
By breaking down the task and examining the model's step-by-step reasoning, you can pinpoint misunderstandings or flawed logic, which then allows you to make precise corrections to your prompt or approach for better results on subsequent attempts.
Prompt Engineering for Efficient Thinking
Achieving cost-effective and accurate results starts with solid prompt engineering.Following Google's established prompt writing guidelines and best practices is the foundation for getting optimal performance from Gemini's thinking modes.
A key strategy for managing costs is to provide specific guidance within your prompt to limit the amount of thinking the model needs to perform.
For example, by structuring the problem clearly or providing key constraints, you can reduce the model's need for extensive exploration.
This technique is especially valuable for tasks that require very long outputs, as it helps reserve a larger portion of the token budget for the answer itself rather than the preliminary thinking process.
Task-Specific Thinking Strategy
Not all tasks are created equal, and your approach to using the thinking mode should reflect the complexity of the job at hand.Aligning the thinking level and budget with the task is the most effective way to optimize for both performance and cost.
Simple, medium, and difficult tasks each have a distinct best practice.
| Task Complexity | Example Use Cases | Recommended Thinking Strategy |
|---|---|---|
| Simple | Fact retrieval, classification, simple summarization. | Thinking is generally not required for these tasks. It is best to disable the feature to avoid unnecessary costs. |
| Medium | Creating analogies, performing comparisons, nuanced content generation. | These tasks often benefit from the default thinking settings or at least some enabled thinking to improve the quality and depth of the response. |
| Difficult | Solving complex math problems, advanced coding, multi-step logical reasoning. | It is highly recommended to set a high thinking budget. This allows the model to utilize its full reasoning and planning capabilities for the most accurate and comprehensive results. |
5. The Broader Gemini Ecosystem: General Context and Recent Developments
To fully grasp the granular controls of Gemini 3.7's "Thinking Level," it's essential to first understand the broader platform and its recent evolution.This section provides that foundational context, covering Gemini's core purpose as an AI assistant, its key features, and recent model and API updates that set the stage for the advanced capabilities discussed in this article.
Gemini's Role as a Versatile AI Assistant
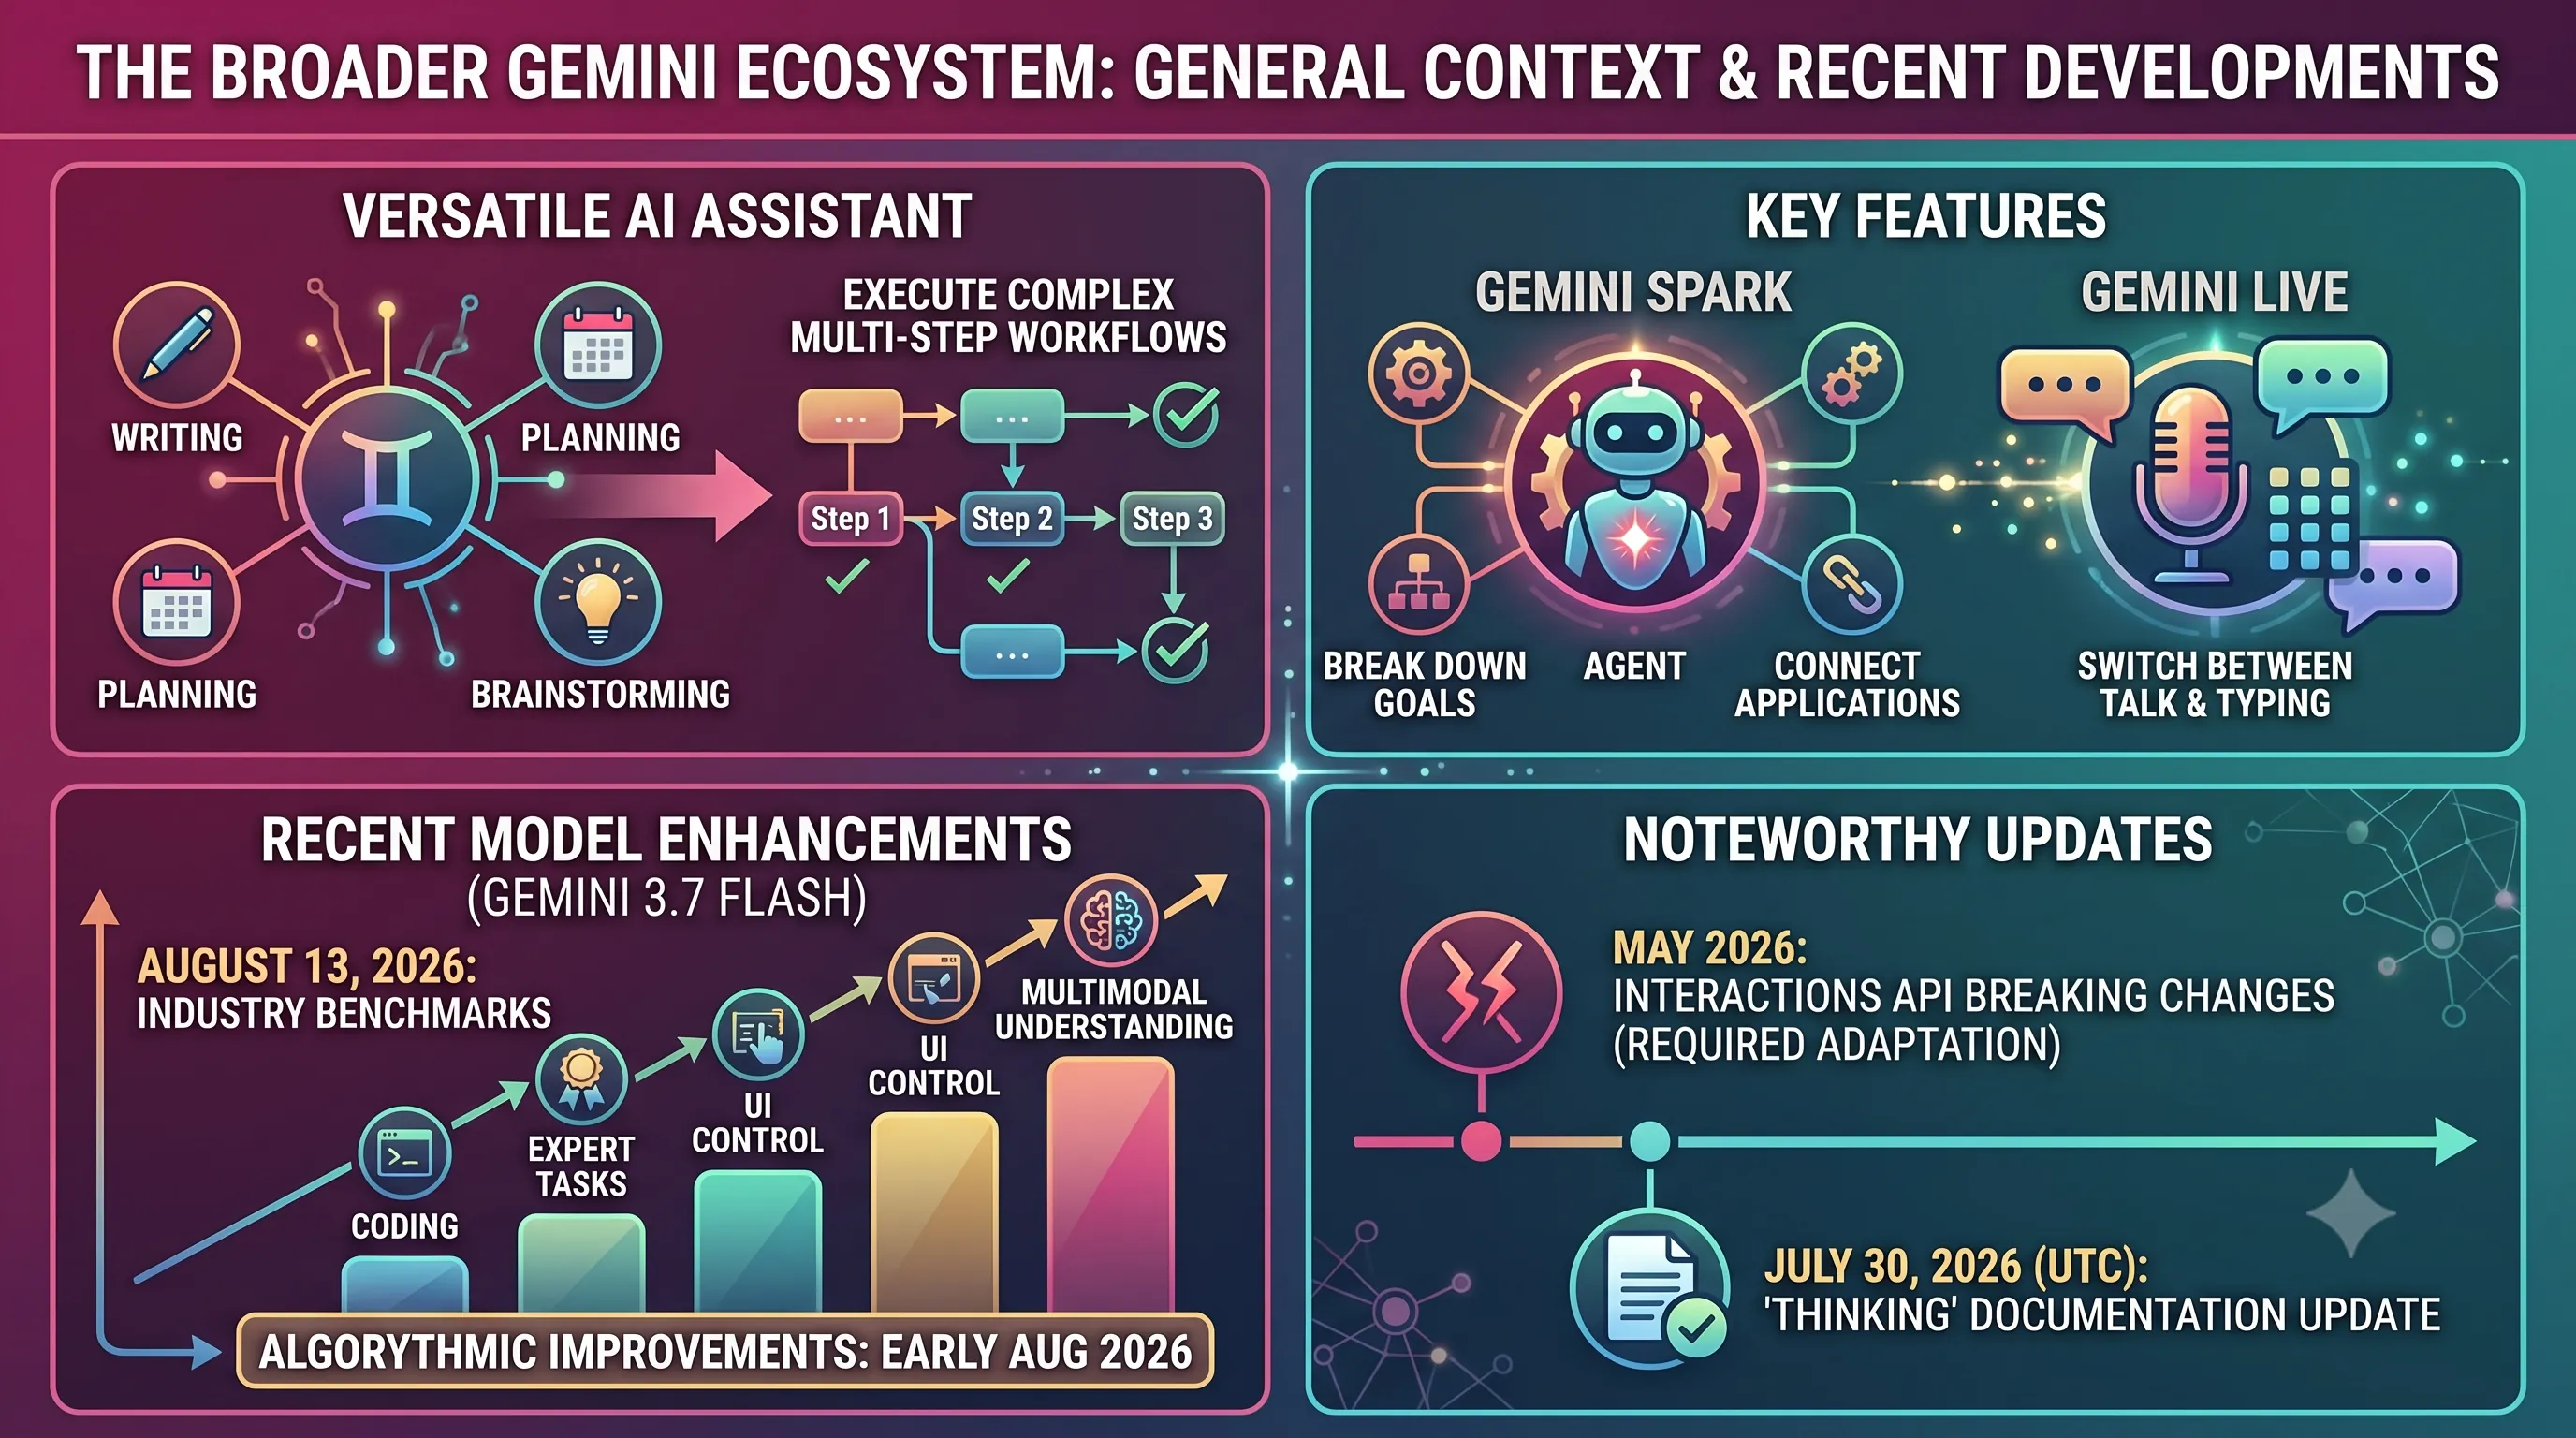
At its core, Gemini serves as Google's comprehensive AI assistant, designed to help users with a wide range of cognitive tasks.Its fundamental capabilities include assisting with writing, planning, and brainstorming.
The latest generation of Gemini models is engineered to go beyond simple queries, combining frontier intelligence with the ability to take action.
This design philosophy enables the models to execute complex, multi-step workflows, making Gemini a powerful tool for sophisticated projects.
Key Features: Spark and Live
Google has expanded the Gemini ecosystem with specialized features that enhance its utility.One notable addition is Gemini Spark, which is described as a personal AI agent.
Spark's primary function is to break down high-level goals into manageable steps and connect different applications to achieve them.
Another key feature is Gemini Live, which is integrated directly into the chat interface.
This integration facilitates a more natural and flexible user experience by enabling seamless switching between talking to the assistant and typing commands or queries.
Recent Model Enhancements (Gemini 3.7 Flash)
The Gemini 3 model family continues to evolve with significant performance upgrades.As of early August 2026, the latest iteration is Gemini 3.7 Flash, which features notable algorithmic improvements.
This model's capabilities were recently evaluated across a diverse set of industry benchmarks.
These evaluations, current as of August 13, 2026, tested its performance in areas such as coding, expert tasks, user interface (UI) control, and multimodal understanding.
Noteworthy API and Documentation Updates
For developers and advanced users, staying aware of platform changes is critical.Earlier this year, in May 2026, Google implemented breaking changes to the Interactions API, which required developers to adapt their integrations.
In a related update, the official documentation page specifically covering Gemini's "thinking" capabilities was last updated on July 30, 2026 (UTC), providing the most current official guidance on the subject preceding this article's publication.
Related Posts
Gemini 3.8 Flash: GA Specifications, Reasoning Controls, and Cost-Efficiency AnalysisExplore the official Gemini 3.8 Flash release: covering its 1M context window, configurable...
AI Agents for Web and Desktop Automation: Stagehand and Claude's Computer Use ToolExplore how AI agents such as Stagehand and Anthropic's Claude computer use tool deliver robust,...
Ensuring Reliable Structured Outputs from LLMs with OpenAI and InstructorLearn how OpenAI's Structured Outputs and the Instructor library ensure reliable, schema-compliant...