
Llama 3 to Llama 4: The Open-Source AI Evolution Dethroning Proprietary Models with Multimodal Power & On-Premise Flexibility
🚀 Key Takeaways
- Llama 3 offers state-of-the-art capabilities in multilinguality, coding, and reasoning, comparable to leading proprietary AI models.
- The public release of Llama 3 foundation models empowers organizations to custom fine-tune and deploy advanced AI solutions on-premise.
- Future iterations, such as Llama 4, further advance the open-source ecosystem with multimodal features, efficiency, and expanded context windows.
- These developments are fundamentally challenging the monopoly of closed AI by providing accessible, customizable, and powerful alternatives.
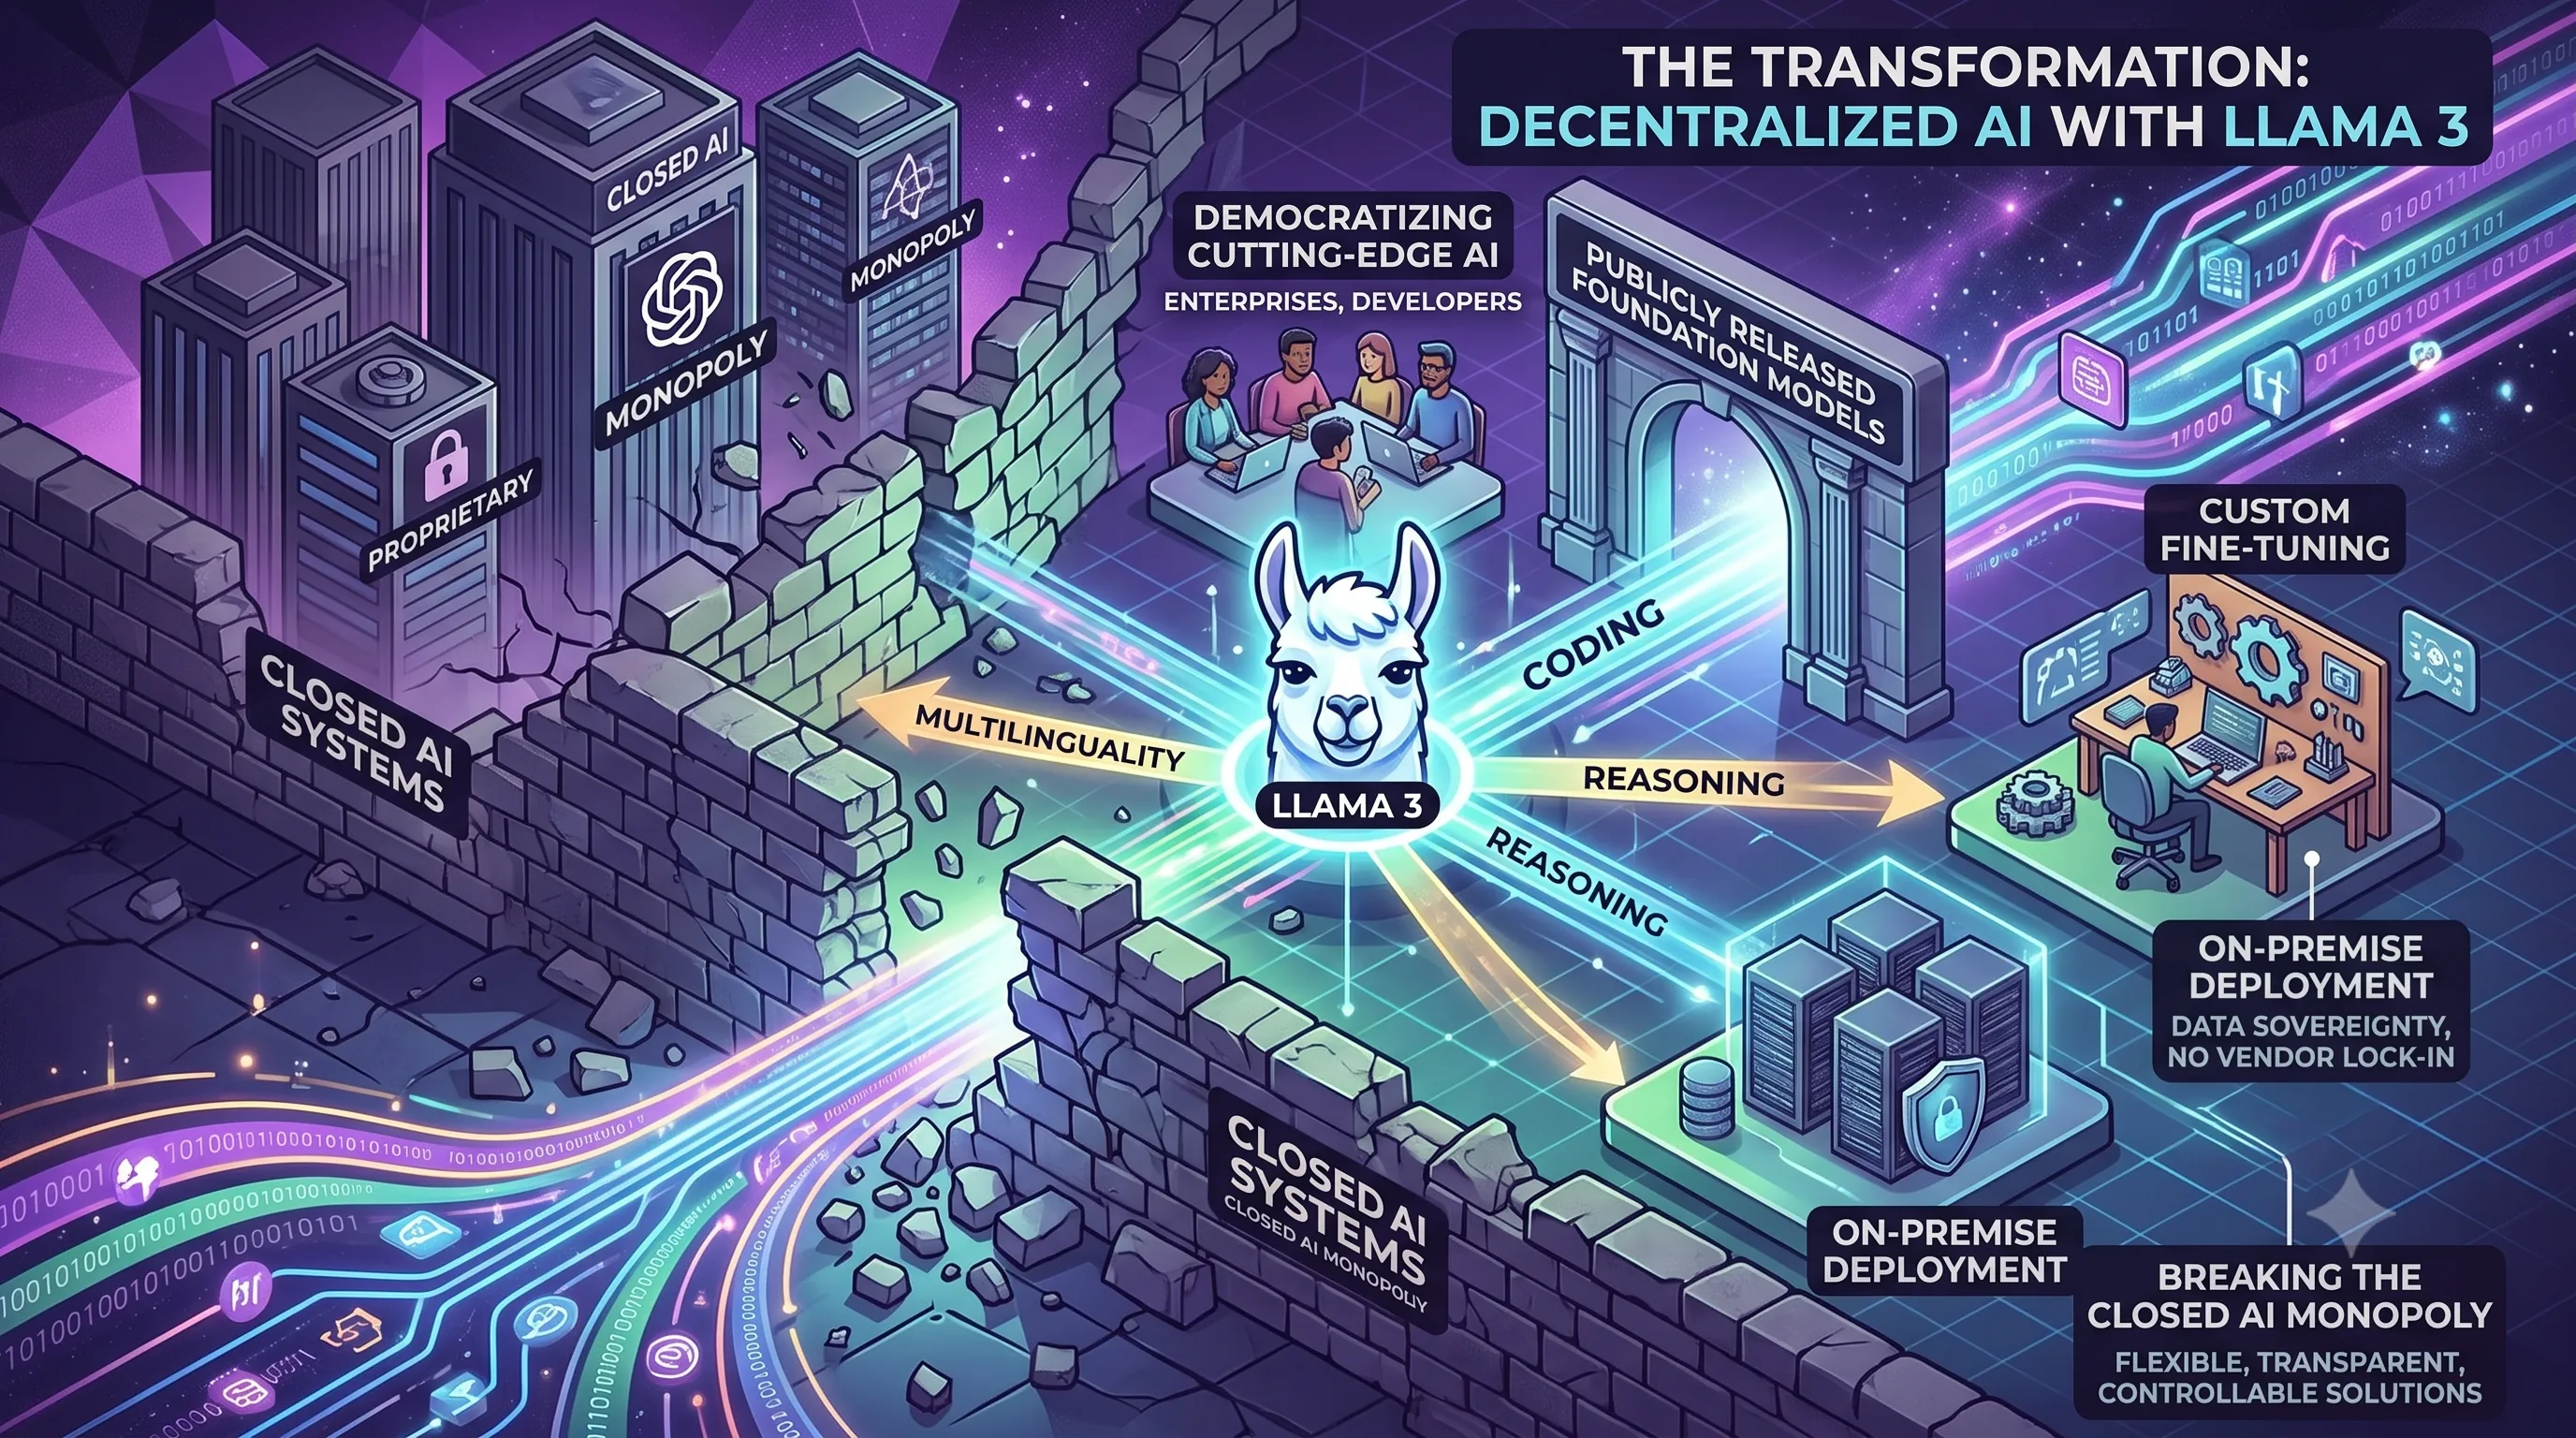
The artificial intelligence landscape is witnessing a profound transformation, with a growing movement to dismantle the dominance of closed, proprietary models.
Enterprises and developers are actively seeking more flexible, transparent, and controllable AI solutions that align with their unique operational requirements and data governance policies.
In this pivotal shift, Llama 3 has emerged as a game-changer.
As a publicly released suite of foundation models, it delivers advanced capabilities in areas such as multilinguality, coding, and complex reasoning, achieving performance on par with some of the most sophisticated closed-source offerings.
This accessibility, coupled with the inherent ability to custom fine-tune and deploy Llama 3 models on-premise, is crucial.
It not only democratizes access to cutting-edge AI but also enables organizations to tailor these powerful language models precisely to their specific use cases, ensuring data sovereignty, reducing vendor lock-in, and ultimately breaking the monopoly of closed AI systems.
Enterprises and developers are actively seeking more flexible, transparent, and controllable AI solutions that align with their unique operational requirements and data governance policies.
In this pivotal shift, Llama 3 has emerged as a game-changer.
As a publicly released suite of foundation models, it delivers advanced capabilities in areas such as multilinguality, coding, and complex reasoning, achieving performance on par with some of the most sophisticated closed-source offerings.
This accessibility, coupled with the inherent ability to custom fine-tune and deploy Llama 3 models on-premise, is crucial.
It not only democratizes access to cutting-edge AI but also enables organizations to tailor these powerful language models precisely to their specific use cases, ensuring data sovereignty, reducing vendor lock-in, and ultimately breaking the monopoly of closed AI systems.
1. Unpacking Llama 3: Core Capabilities and Ecosystem Presence
This section serves as a foundational overview of the Llama 3 model family, which is the core subject of our main article.Before diving into the technical specifics of fine-tuning and on-premise deployment, it is crucial to understand what Llama 3 is, its core architectural strengths, performance benchmarks, and the ecosystem surrounding it.
This analysis establishes why Llama 3 is a compelling open alternative to closed-source models and provides the necessary context for the practical steps that follow.
Key Innovations and Performance Benchmarks
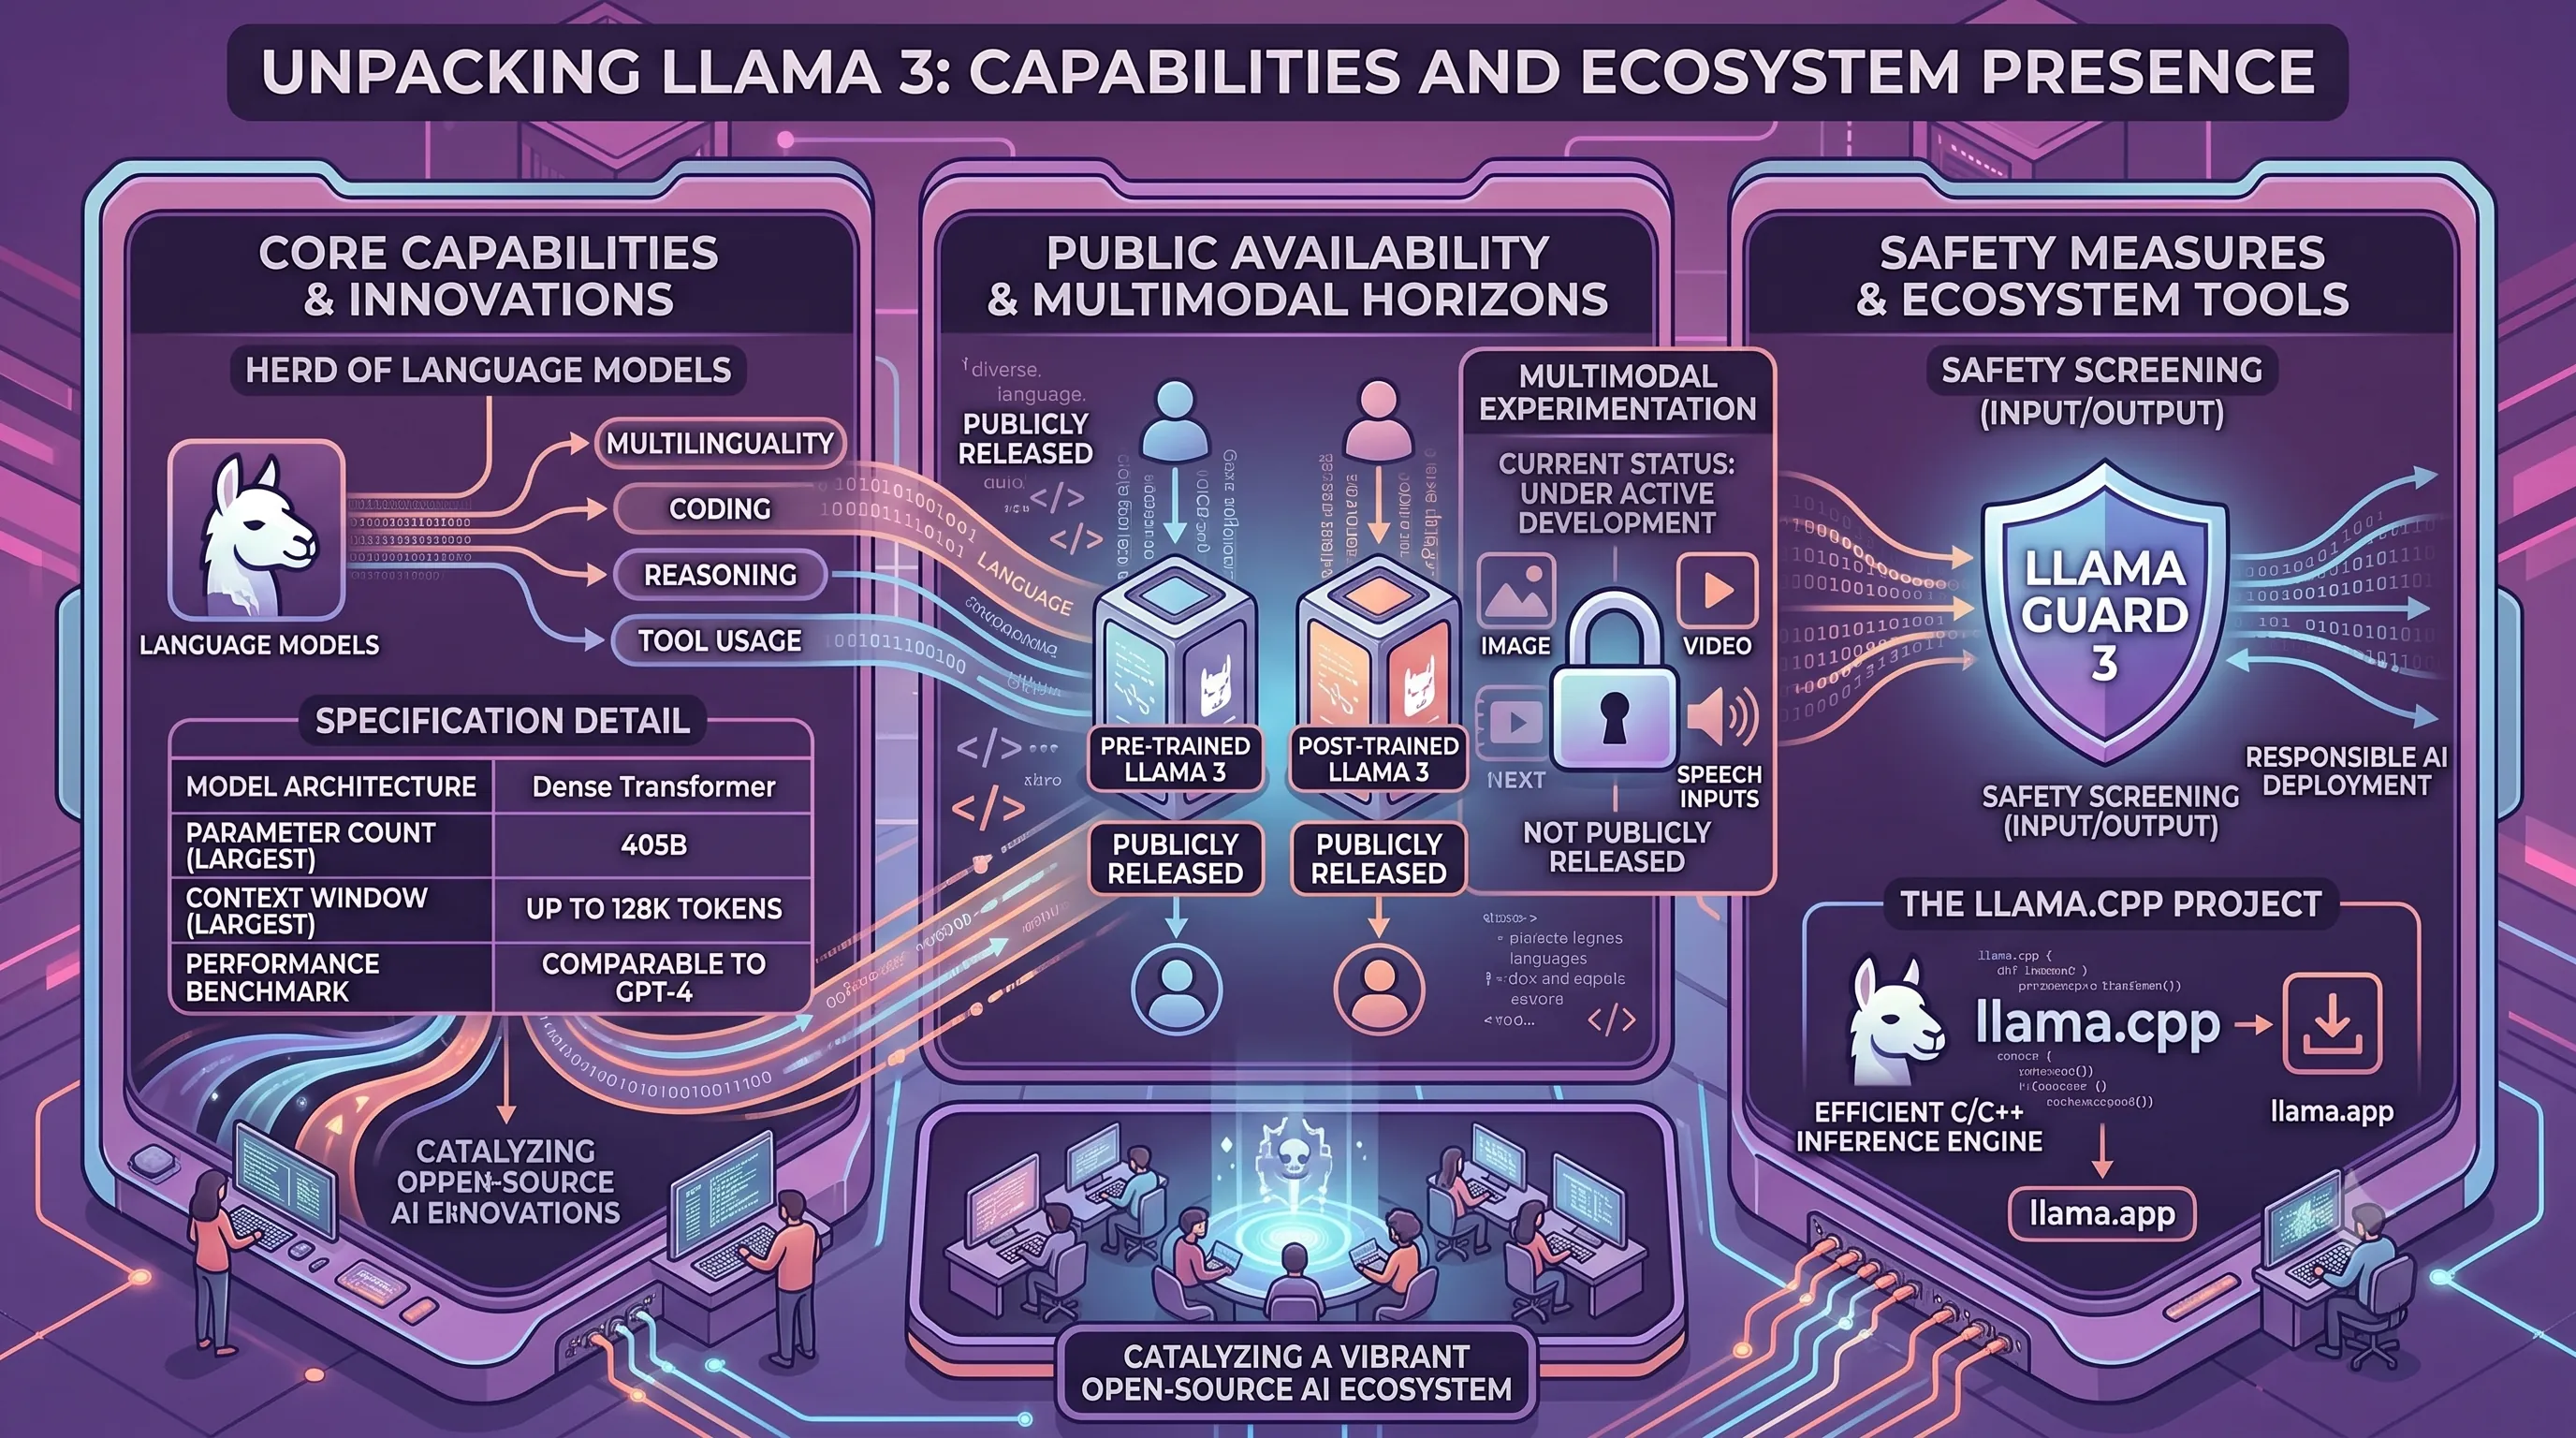
Llama 3 represents a new generation of foundation models, described by its creators at the Llama team as a "herd of language models".This designation reflects its inherent design for versatility, with native support for a wide range of tasks including multilinguality, coding, reasoning, and tool usage.
The flagship of this family is an exceptionally large dense Transformer model boasting 405 billion parameters, a scale that places it at the forefront of AI research.
This model's architecture also features a massive context window of up to 128,000 tokens, enabling it to process and understand much longer and more complex inputs.
Critically, performance evaluations detailed in the official paper published on arXiv on July 23, 2024, show that Llama 3 delivers quality comparable to leading proprietary models like GPT-4 across many industry-standard benchmarks.
| Specification | Detail |
|---|---|
| Model Architecture | Dense Transformer |
| Parameter Count (Largest Model) | 405B |
| Context Window (Largest Model) | Up to 128K tokens |
| Performance Benchmark | Comparable quality to leading models such as GPT-4 |
Multimodal Horizons: Current Status
Beyond its text-based prowess, Llama 3 is a platform for multimodal experimentation.The development team has successfully integrated image, video, and speech capabilities into the model using a compositional approach.
This method has proven highly effective, achieving performance that is competitive with state-of-the-art models on various recognition tasks.
However, it is important to note the current status of this work: these advanced multimodal Llama 3 models are still under active development.
Consequently, versions with these integrated image, video, and speech capabilities are not yet being broadly released to the public.
Public Availability and Safety Measures
Llama 3 is publicly released, making its powerful capabilities accessible to the broader research and development community.The public release includes both pre-trained and post-trained versions of the 405B parameter language model, offering different starting points for custom applications.
Alongside the core models, the team has also released Llama Guard 3.
This is a specialized model designed to enhance safety by screening both the inputs sent to the model and the outputs it generates, providing a crucial tool for responsible AI deployment.
The llama.cpp Project: An Ecosystem Tool
The open release of Llama 3 has catalyzed a vibrant ecosystem of third-party tools and projects designed to make the models more accessible and efficient.A prime example of this is the llama.cpp project, a highly popular C/C++ implementation for running Llama models on a wide range of hardware.
The official website for this influential project can be found at llama.app, serving as a central hub for developers looking to leverage this efficient inference engine.
2. The Evolution of Llama 3.1: NVIDIA's Nemotron-Ultra Enhancement
This section provides a crucial case study for our main topic of breaking the closed AI monopoly.The evolution of Llama 3.1 into NVIDIA's Nemotron-Ultra demonstrates how an open-source foundation enables third-party innovators to create specialized, high-performance models.
This process directly challenges the monolithic, closed-source AI paradigm by showcasing the power of collaborative and derivative innovation.
Llama 3.1 405B: The Foundation
The starting point for this significant advancement was the Llama 3.1 405B model.This large-scale model, with its extensive parameter count, provided the powerful and sophisticated architecture that NVIDIA selected as the foundation for its targeted enhancements.
It represented a capable but unrefined canvas for further optimization.
NVIDIA's Strategic Enhancements
NVIDIA did not simply adopt the base model; instead, it implemented a multi-faceted strategy to refine and reshape it into a more efficient and powerful tool.The process involved several key modifications aimed at boosting performance while streamlining the architecture.
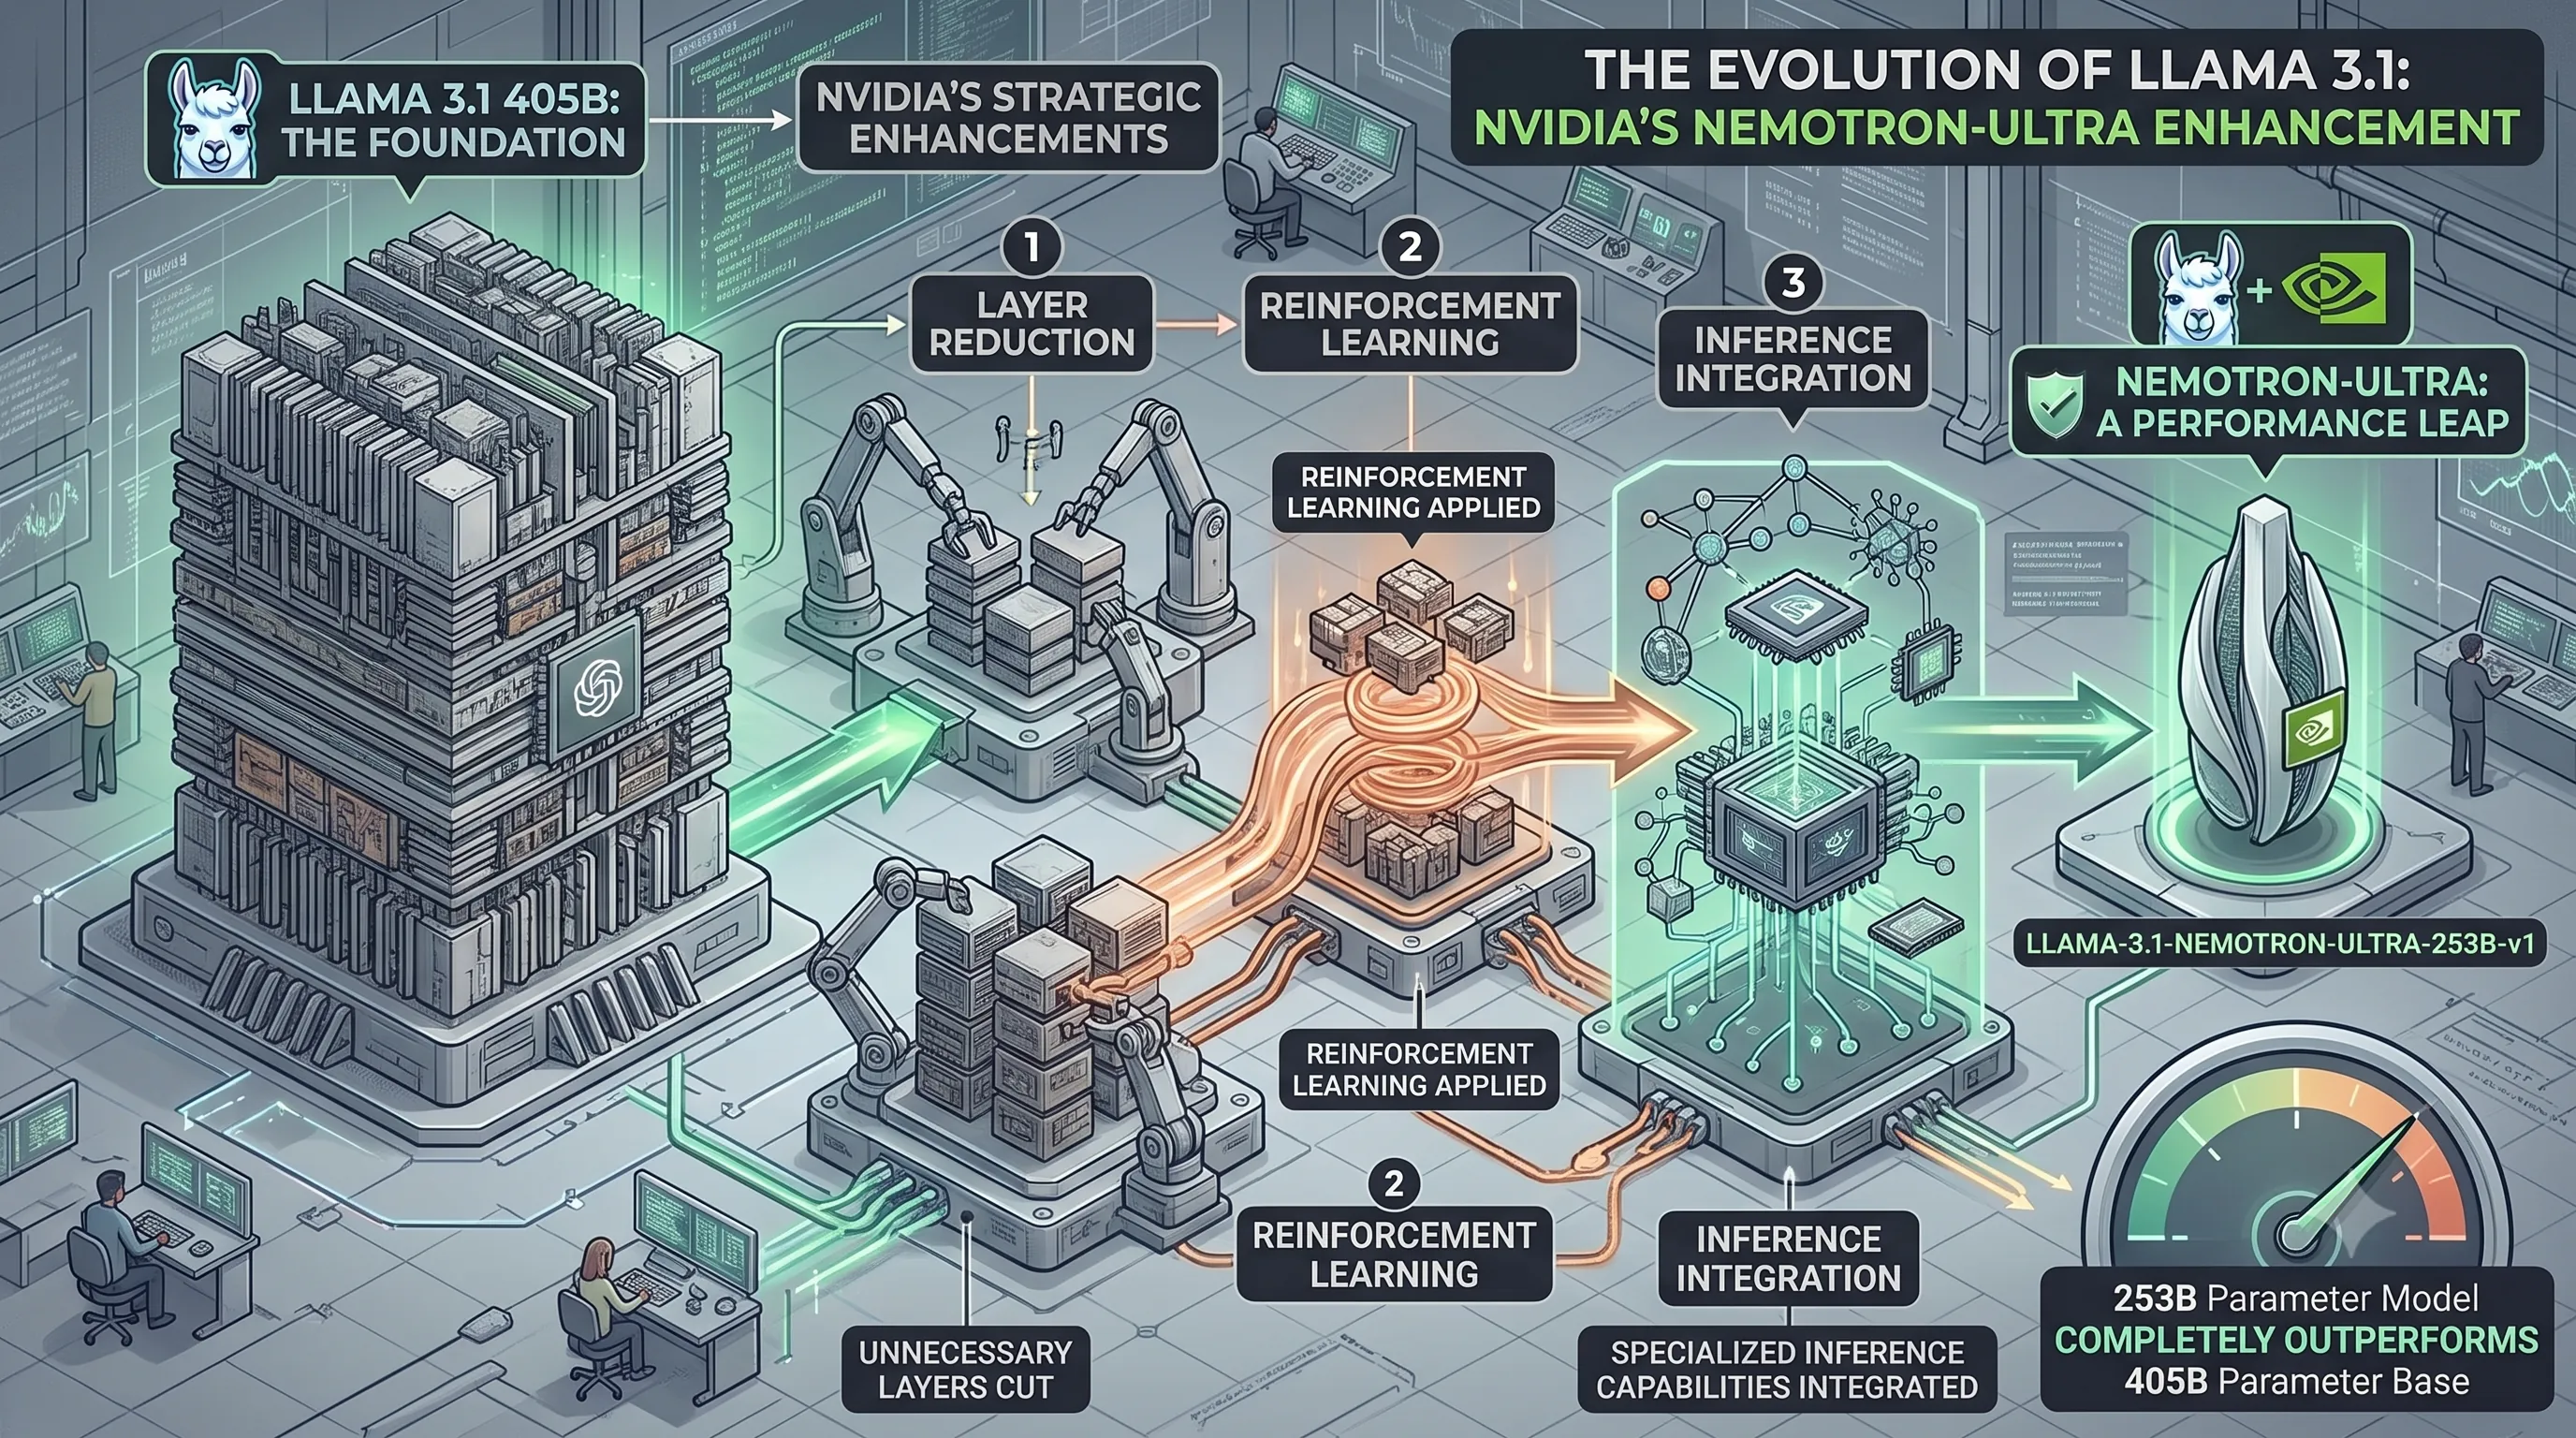
NVIDIA's engineers began by strategically cutting unnecessary layers from the Llama 3.1 405B model, a move designed to reduce computational overhead without compromising reasoning ability.
Following this architectural pruning, NVIDIA added additional reinforcement learning, a critical step to further hone the model's accuracy and alignment with complex instructions.
To complete the transformation, the company integrated specific inference capabilities, optimizing the model for fast and efficient performance during real-world deployment.
The culmination of these efforts was an entirely new model: Llama-3.1-Nemotron-Ultra-253B-v1.
| NVIDIA Enhancement on Llama 3.1 405B | Description |
|---|---|
| Layer Reduction | Unnecessary layers were cut from the original model's architecture. |
| Reinforcement Learning | Additional reinforcement learning techniques were applied to improve model behavior. |
| Inference Integration | Specialized capabilities for inference were integrated directly into the model. |
Nemotron-Ultra: A Performance Leap
The results of NVIDIA's modifications were not just incremental; they represented a fundamental leap in performance.In benchmark comparisons and practical applications, the resulting Llama-3.1-Nemotron-Ultra-253B-v1 completely outperformed the original Llama 3.1 405B model.
This outcome is particularly notable because the superior model has a significantly smaller parameter count (253B vs. 405B), proving that intelligent optimization, targeted training, and architectural refinement can yield far greater results than raw scale alone.
3. Llama 4: Next-Generation Multimodal AI and Flexible Deployment
This section moves our discussion from the powerful Llama 3 to its successor, Llama 4, showcasing how the open-source movement continues to advance, not just in text but into the complex realm of multimodality, further challenging the dominance of closed, proprietary systems.Multimodal Prowess and Context Capabilities
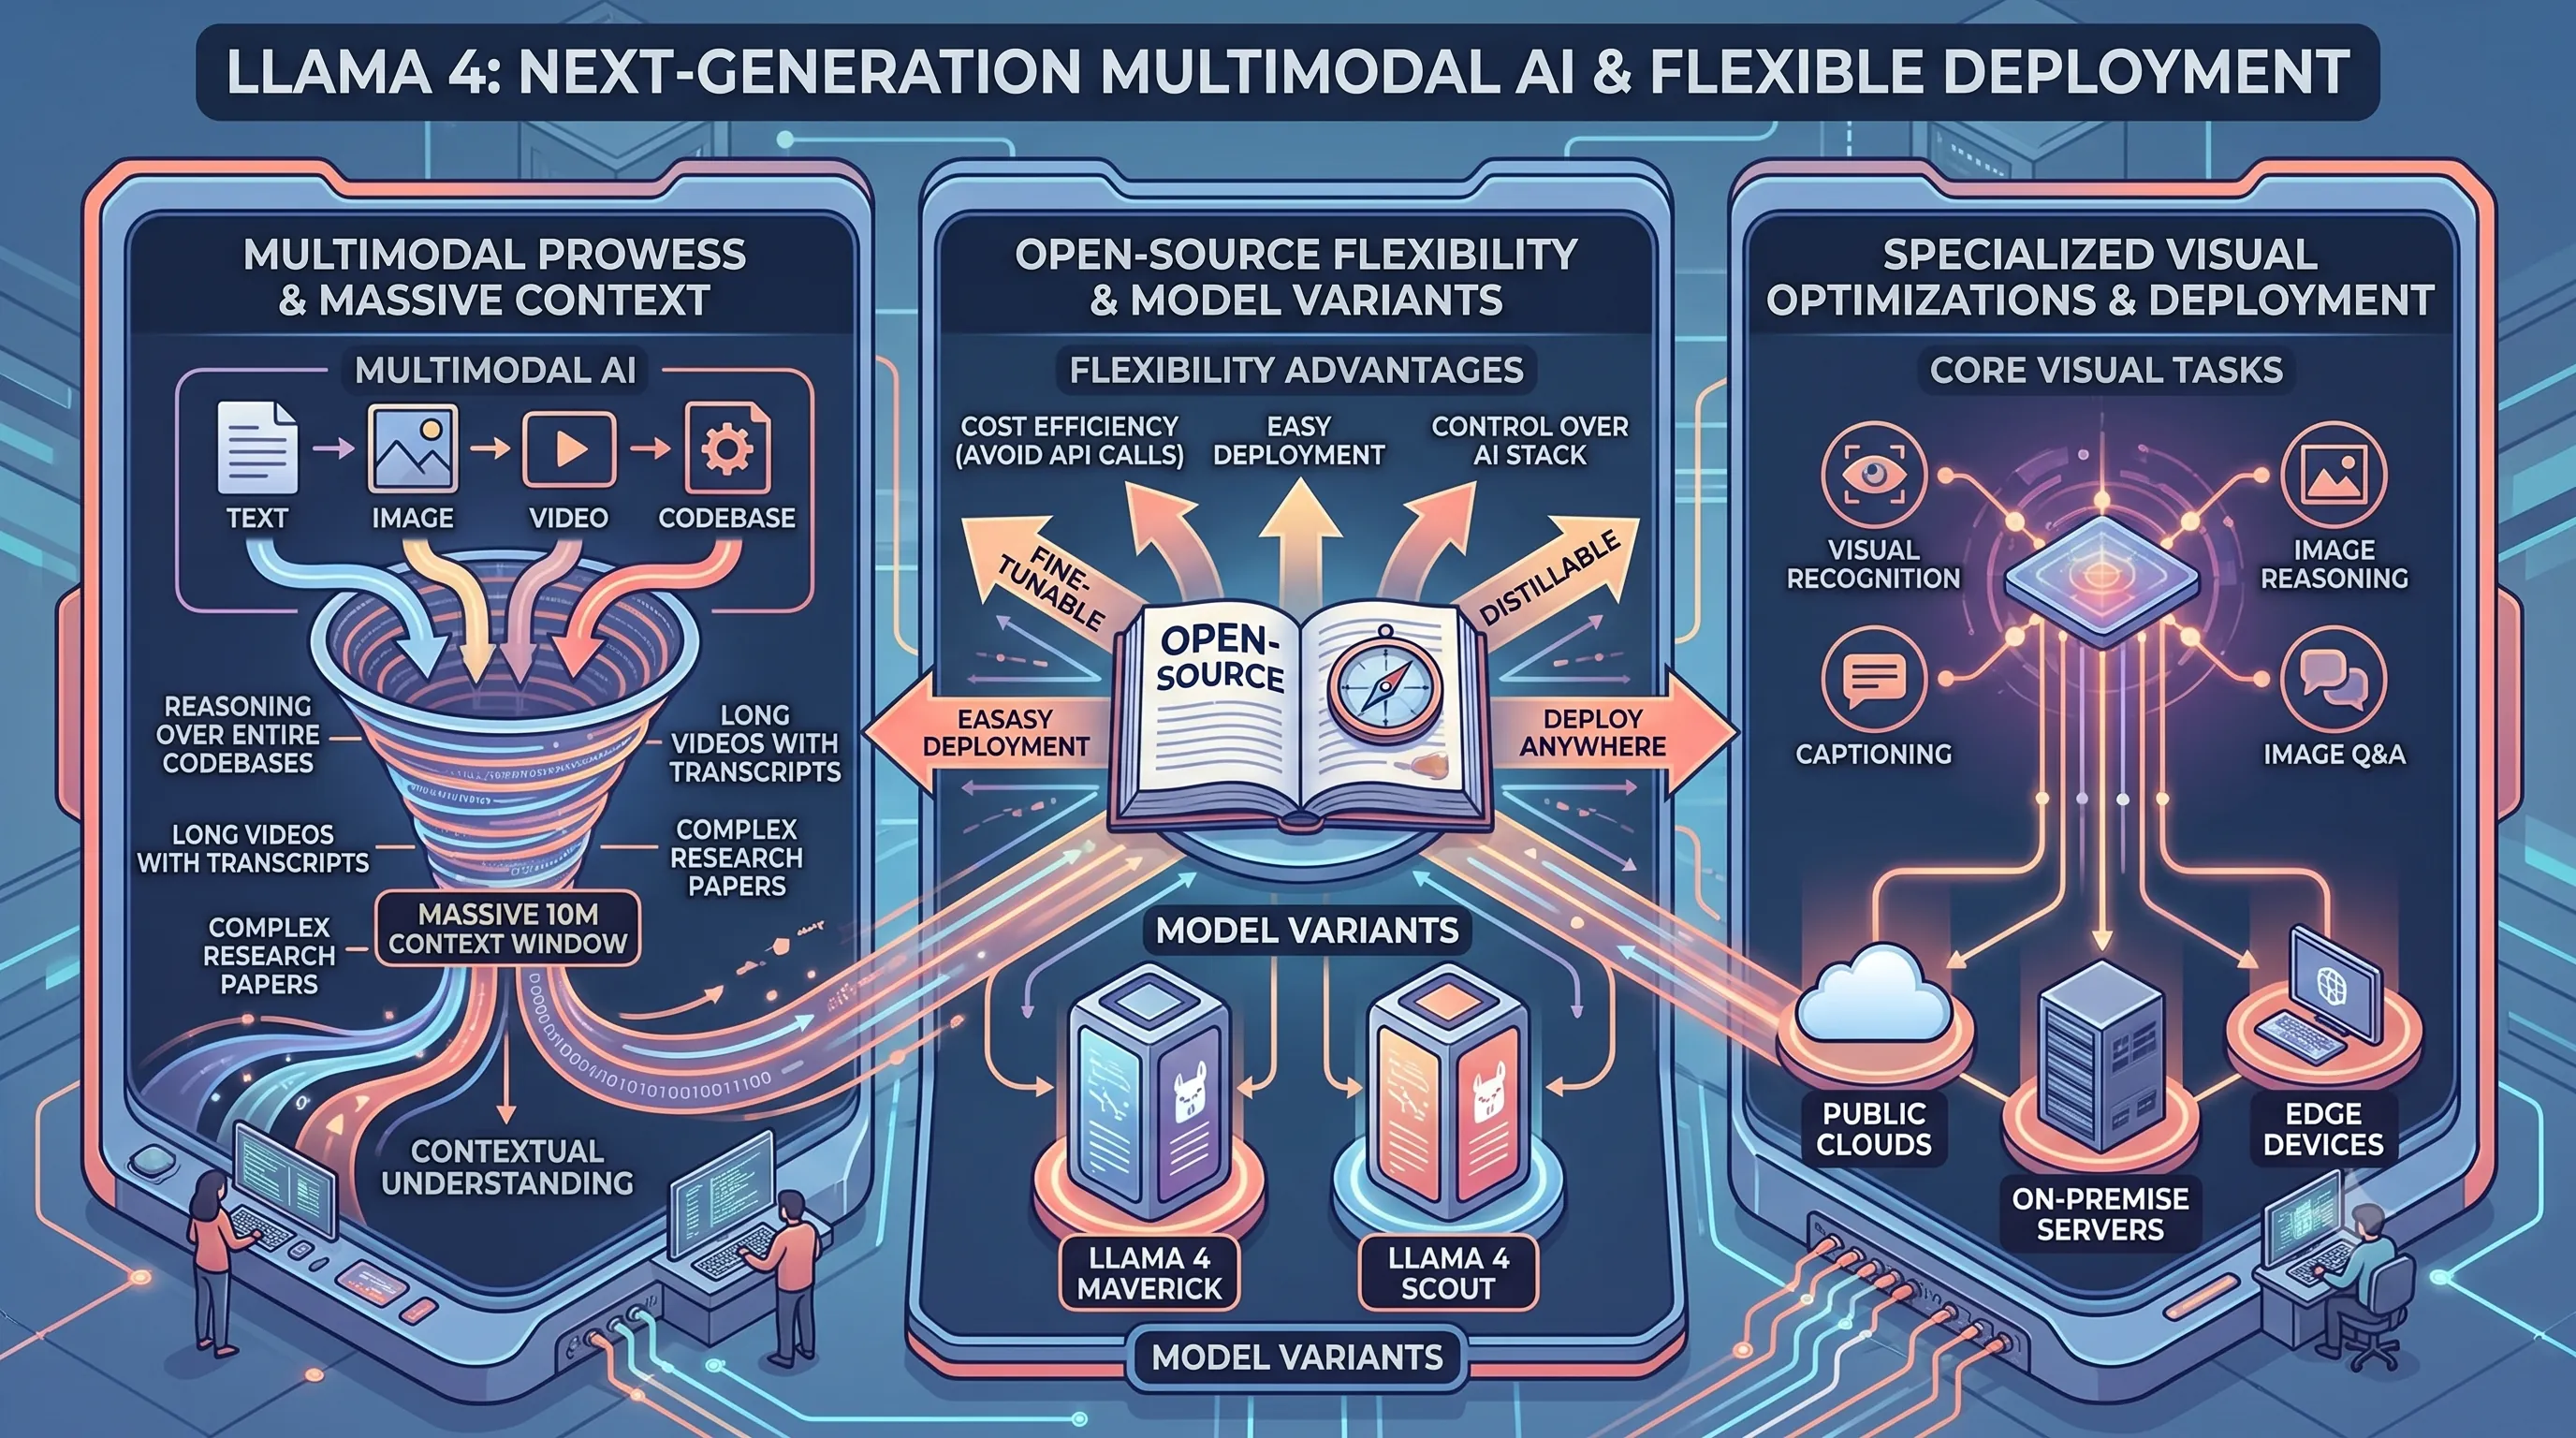
Llama 4 stands as the latest multimodal AI model, fundamentally expanding the scope of what open-source models can achieve.Its most significant architectural leap is the introduction of a massive 10M context window.
This enormous capacity allows the model to process and reason over vast amounts of information—equivalent to entire codebases, extensive research papers, or lengthy videos with transcripts—in a single prompt, enabling a level of contextual understanding previously unseen in openly available models.
Open-Source Flexibility and Deployment Advantages
True to the Llama lineage, the entire Llama 4 family is open-source, providing a powerful and transparent alternative to closed-off ecosystems.This core principle delivers significant advantages in cost efficiency, as organizations can avoid expensive API calls and per-token charges.
Furthermore, the models are designed for easy deployment, giving developers unprecedented control over their AI stack.
This flexibility is comprehensive: Llama 4 models can be fine-tuned on custom datasets to specialize their performance for specific tasks, distilled into smaller, more efficient versions for edge devices, and ultimately deployed anywhere—from public clouds to secure, on-premise servers.
Specialized Optimizations and Model Variants
Llama 4 is not merely a text model with added senses; it has been meticulously optimized for a range of visual tasks.Its capabilities are fine-tuned for high-accuracy visual recognition, sophisticated image reasoning, and generating descriptive captioning for complex scenes.
The model also excels at answering general questions about an image, combining its visual understanding with its vast knowledge base.
To serve different computational and performance needs, two distinct models are available: Llama 4 Maverick and Llama 4 Scout.
| Feature Category | Specification / Capability | Applicable Models |
|---|---|---|
| Model Type | Latest Multimodal AI | Llama 4 Maverick, Llama 4 Scout |
| Context Window | 10M Tokens | Llama 4 Maverick, Llama 4 Scout |
| Licensing | Open-Source | Llama 4 Maverick, Llama 4 Scout |
| Deployment & Customization | Fine-tunable, Distillable, Deploy Anywhere | Llama 4 Maverick, Llama 4 Scout |
| Core Visual Optimizations | Visual Recognition, Image Reasoning, Captioning, Image Q&A | Llama 4 Maverick, Llama 4 Scout |
| Key Advantages | Cost Efficiency, Easy Deployment | Llama 4 Maverick, Llama 4 Scout |
Related Posts
NVIDIA Acquires Hugging Face for $12.93 Billion to Expand Full-Stack AI EcosystemNVIDIA has acquired Hugging Face for $12.93 billion, marking a major expansion into open-source AI,...
Gemini 3.7 Flash: Google's Next-Gen AI for Developers – Unlocking Superior Coding, Multimodal Power & Cost-Effective PerformanceDiscover Google's Gemini 3.7 Flash: the latest AI model offering superior coding, multimodal input...
Gemini 3.8 Flash: GA Specifications, Reasoning Controls, and Cost-Efficiency AnalysisExplore the official Gemini 3.8 Flash release: covering its 1M context window, configurable...