
Microsoft Unleashes MAI: First-Party AI Family Replaces OpenAI, Powers Microsoft 365 & GitHub Copilot, Cuts Costs by 89%
🚀 Key Takeaways
- Microsoft has officially launched its proprietary MAI (Microsoft AI) model family, marking a strategic pivot to first-party AI.
- The MAI family consists of seven powerful in-house models, developed from scratch to replace external dependencies in key Microsoft products.
- Key MAI models like MAI-Thinking-1 (reasoning) and MAI-Code-1-Flash (coding) are now actively deployed across Microsoft 365 and GitHub Copilot.
- Microsoft's extensive Phi-4 edge SLM portfolio and the new Aion 1.0 on-device intelligence offer powerful, locally deployable AI solutions.
- Organizations can leverage Reinforcement Learning Environments (RLEs) to frontier tune MAI models, creating custom, customer-owned AI solutions.
- Microsoft now fields a complete, vertically integrated AI portfolio, spanning custom silicon, cloud, edge, and on-device models.
- The Copilot orchestration layer intelligently routes tasks to optimize for cost-efficiency with MAI models and capability with frontier third-party models.
August 2026 marks a pivotal moment for Microsoft as its ambitious first-party AI strategy fully transitions into an operational reality.
The company has unveiled and deployed its proprietary MAI (Microsoft AI) family of models, significantly reducing its reliance on third-party AI providers like OpenAI and Anthropic.
This comprehensive shift encompasses a full spectrum of AI capabilities, from cloud-based frontier models and specialized code-generation engines to open-weight edge models and on-device intelligence.
Microsoft's new portfolio, built entirely in-house, promises enhanced performance, substantial cost reductions, and unprecedented control over its AI stack.
The integration of these models across core products like Microsoft 365 and GitHub Copilot, alongside custom silicon and innovative tuning environments, positions Microsoft as a unique end-to-end AI provider.
This development fundamentally reshapes the landscape for enterprises and developers leveraging Microsoft's ecosystem, offering powerful, vertically integrated AI solutions at scale.
The company has unveiled and deployed its proprietary MAI (Microsoft AI) family of models, significantly reducing its reliance on third-party AI providers like OpenAI and Anthropic.
This comprehensive shift encompasses a full spectrum of AI capabilities, from cloud-based frontier models and specialized code-generation engines to open-weight edge models and on-device intelligence.
Microsoft's new portfolio, built entirely in-house, promises enhanced performance, substantial cost reductions, and unprecedented control over its AI stack.
The integration of these models across core products like Microsoft 365 and GitHub Copilot, alongside custom silicon and innovative tuning environments, positions Microsoft as a unique end-to-end AI provider.
This development fundamentally reshapes the landscape for enterprises and developers leveraging Microsoft's ecosystem, offering powerful, vertically integrated AI solutions at scale.
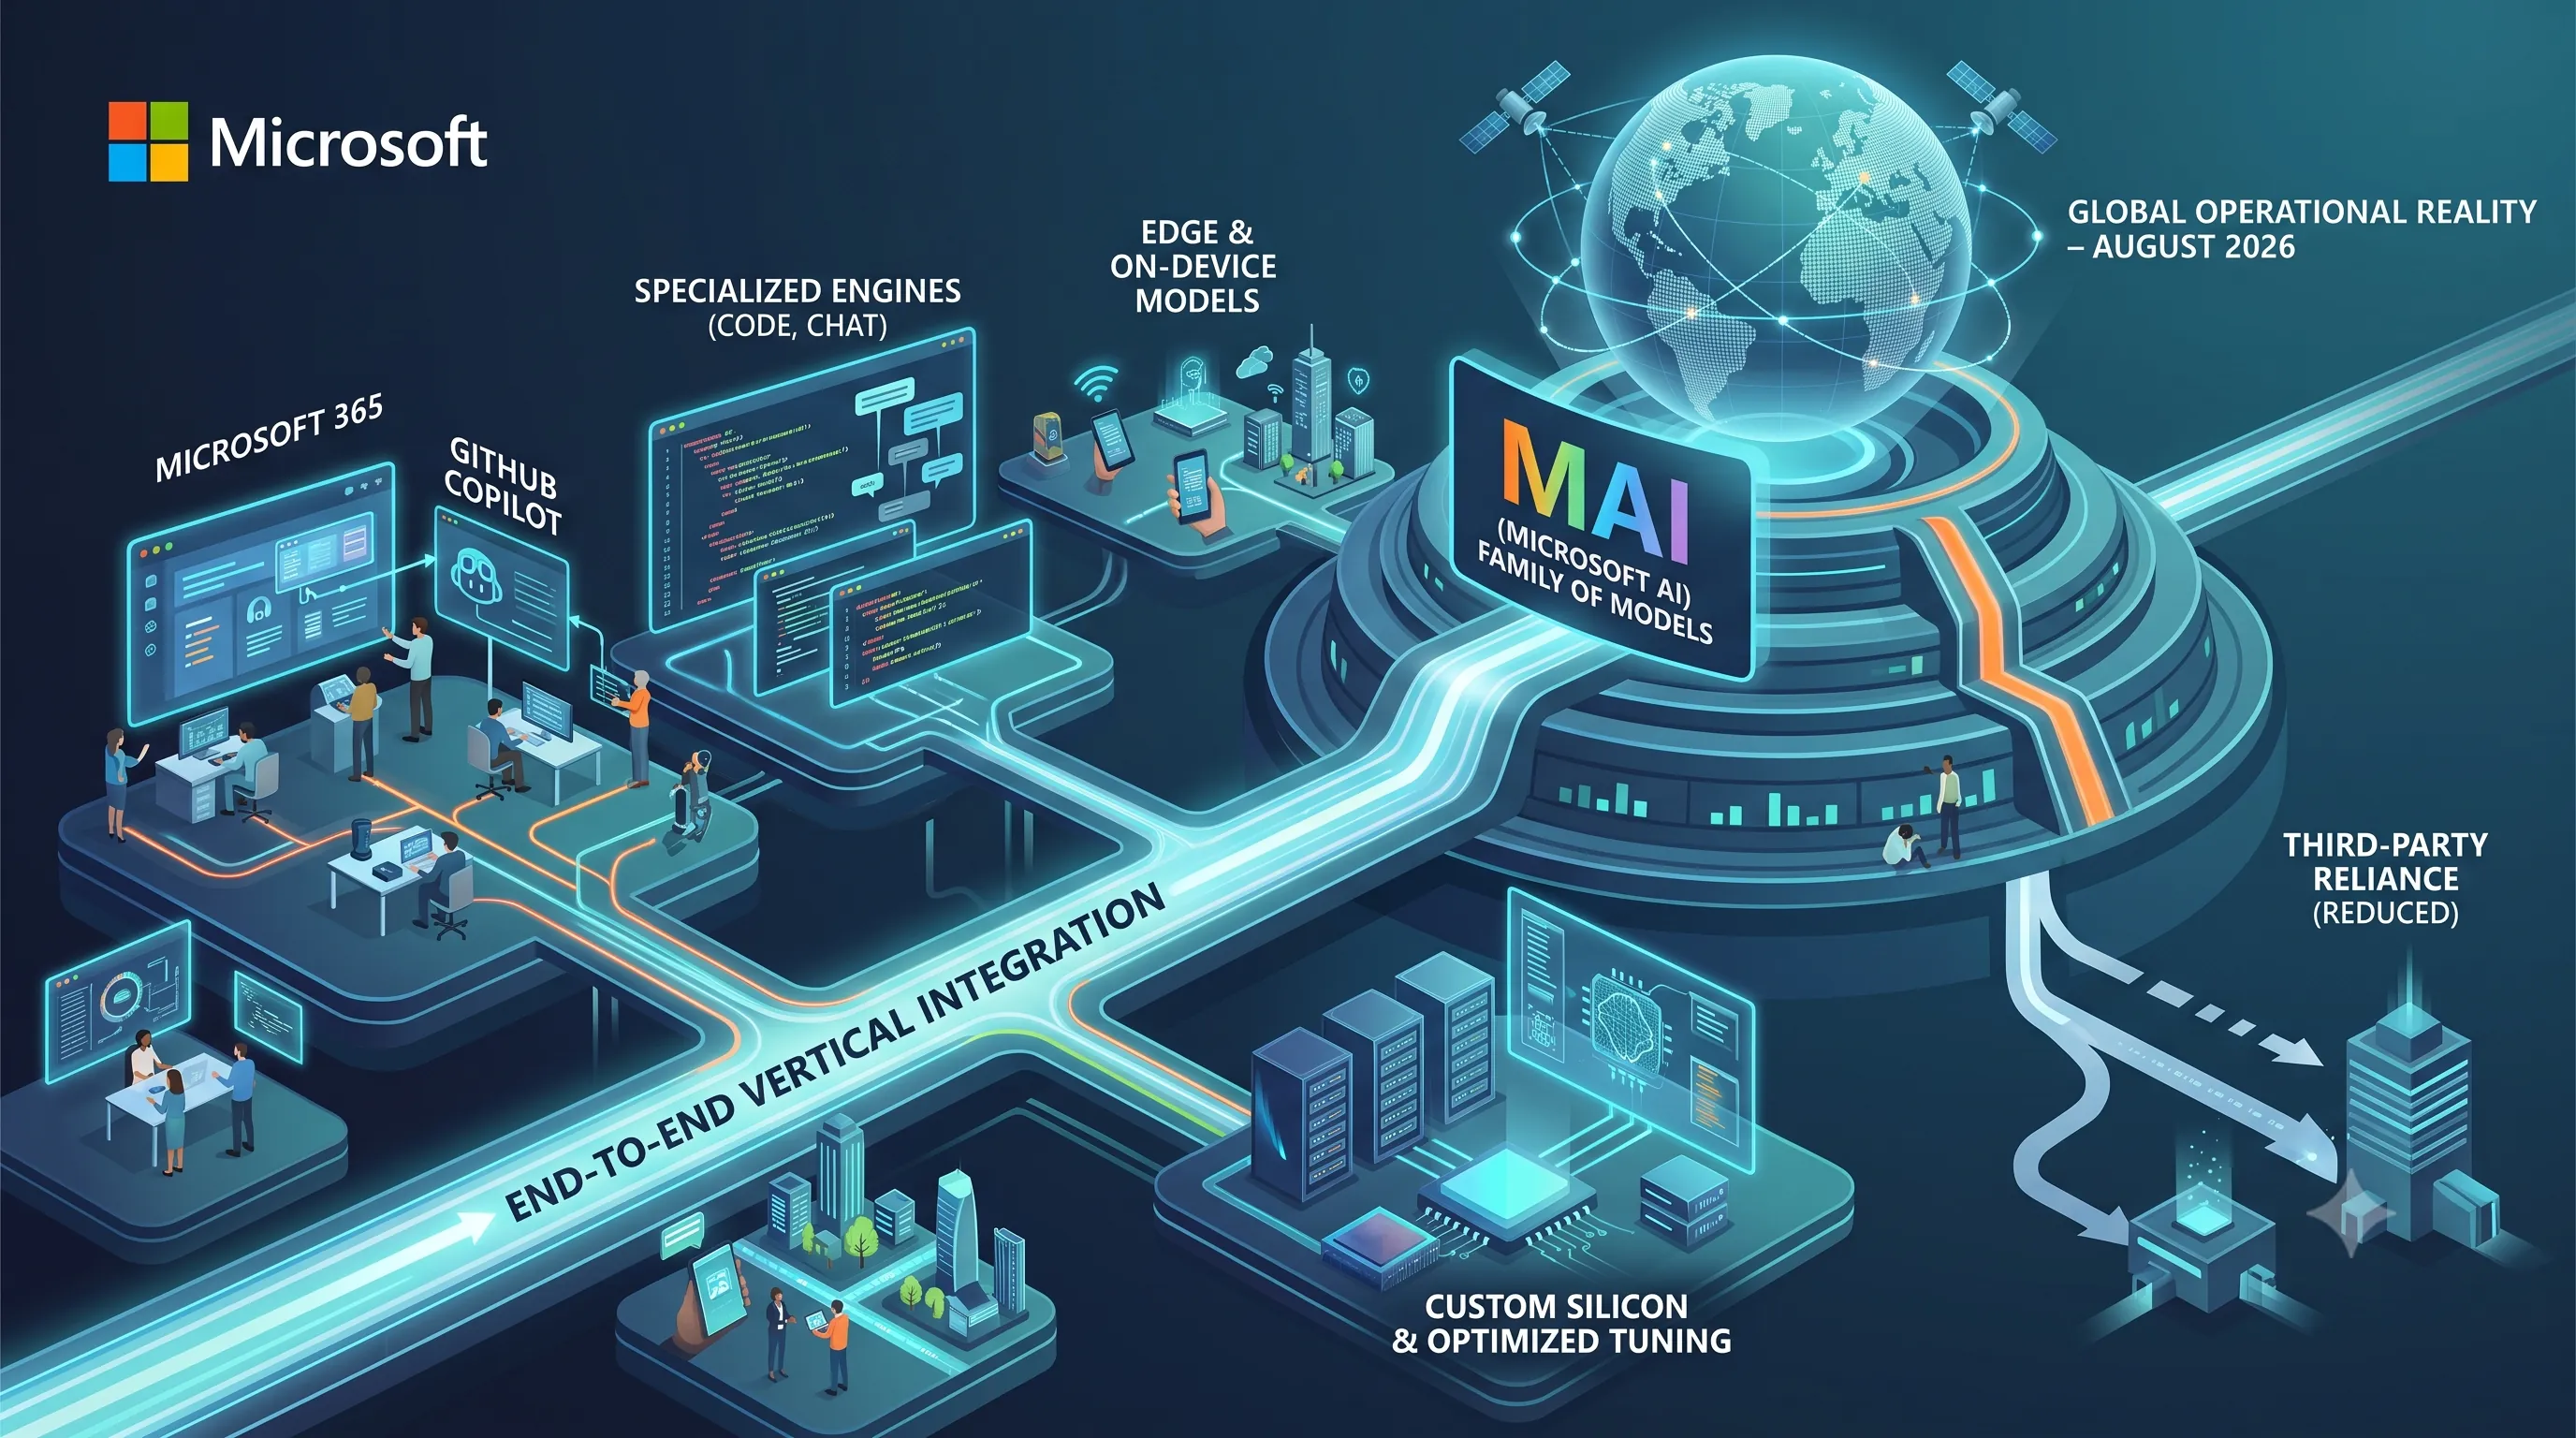
1. Microsoft's MAI Family: Unveiling a New First-Party AI Strategy
Strategic Inflection and Full AI Stack
The middle of 2026 marked a critical inflection point for Microsoft's AI ambitions, with August 2026 representing the moment its new first-party strategy became an operational reality.This strategic pivot centers on a comprehensive, in-house model stack designed to cover every computational tier, from massive cloud infrastructure to on-device processing.
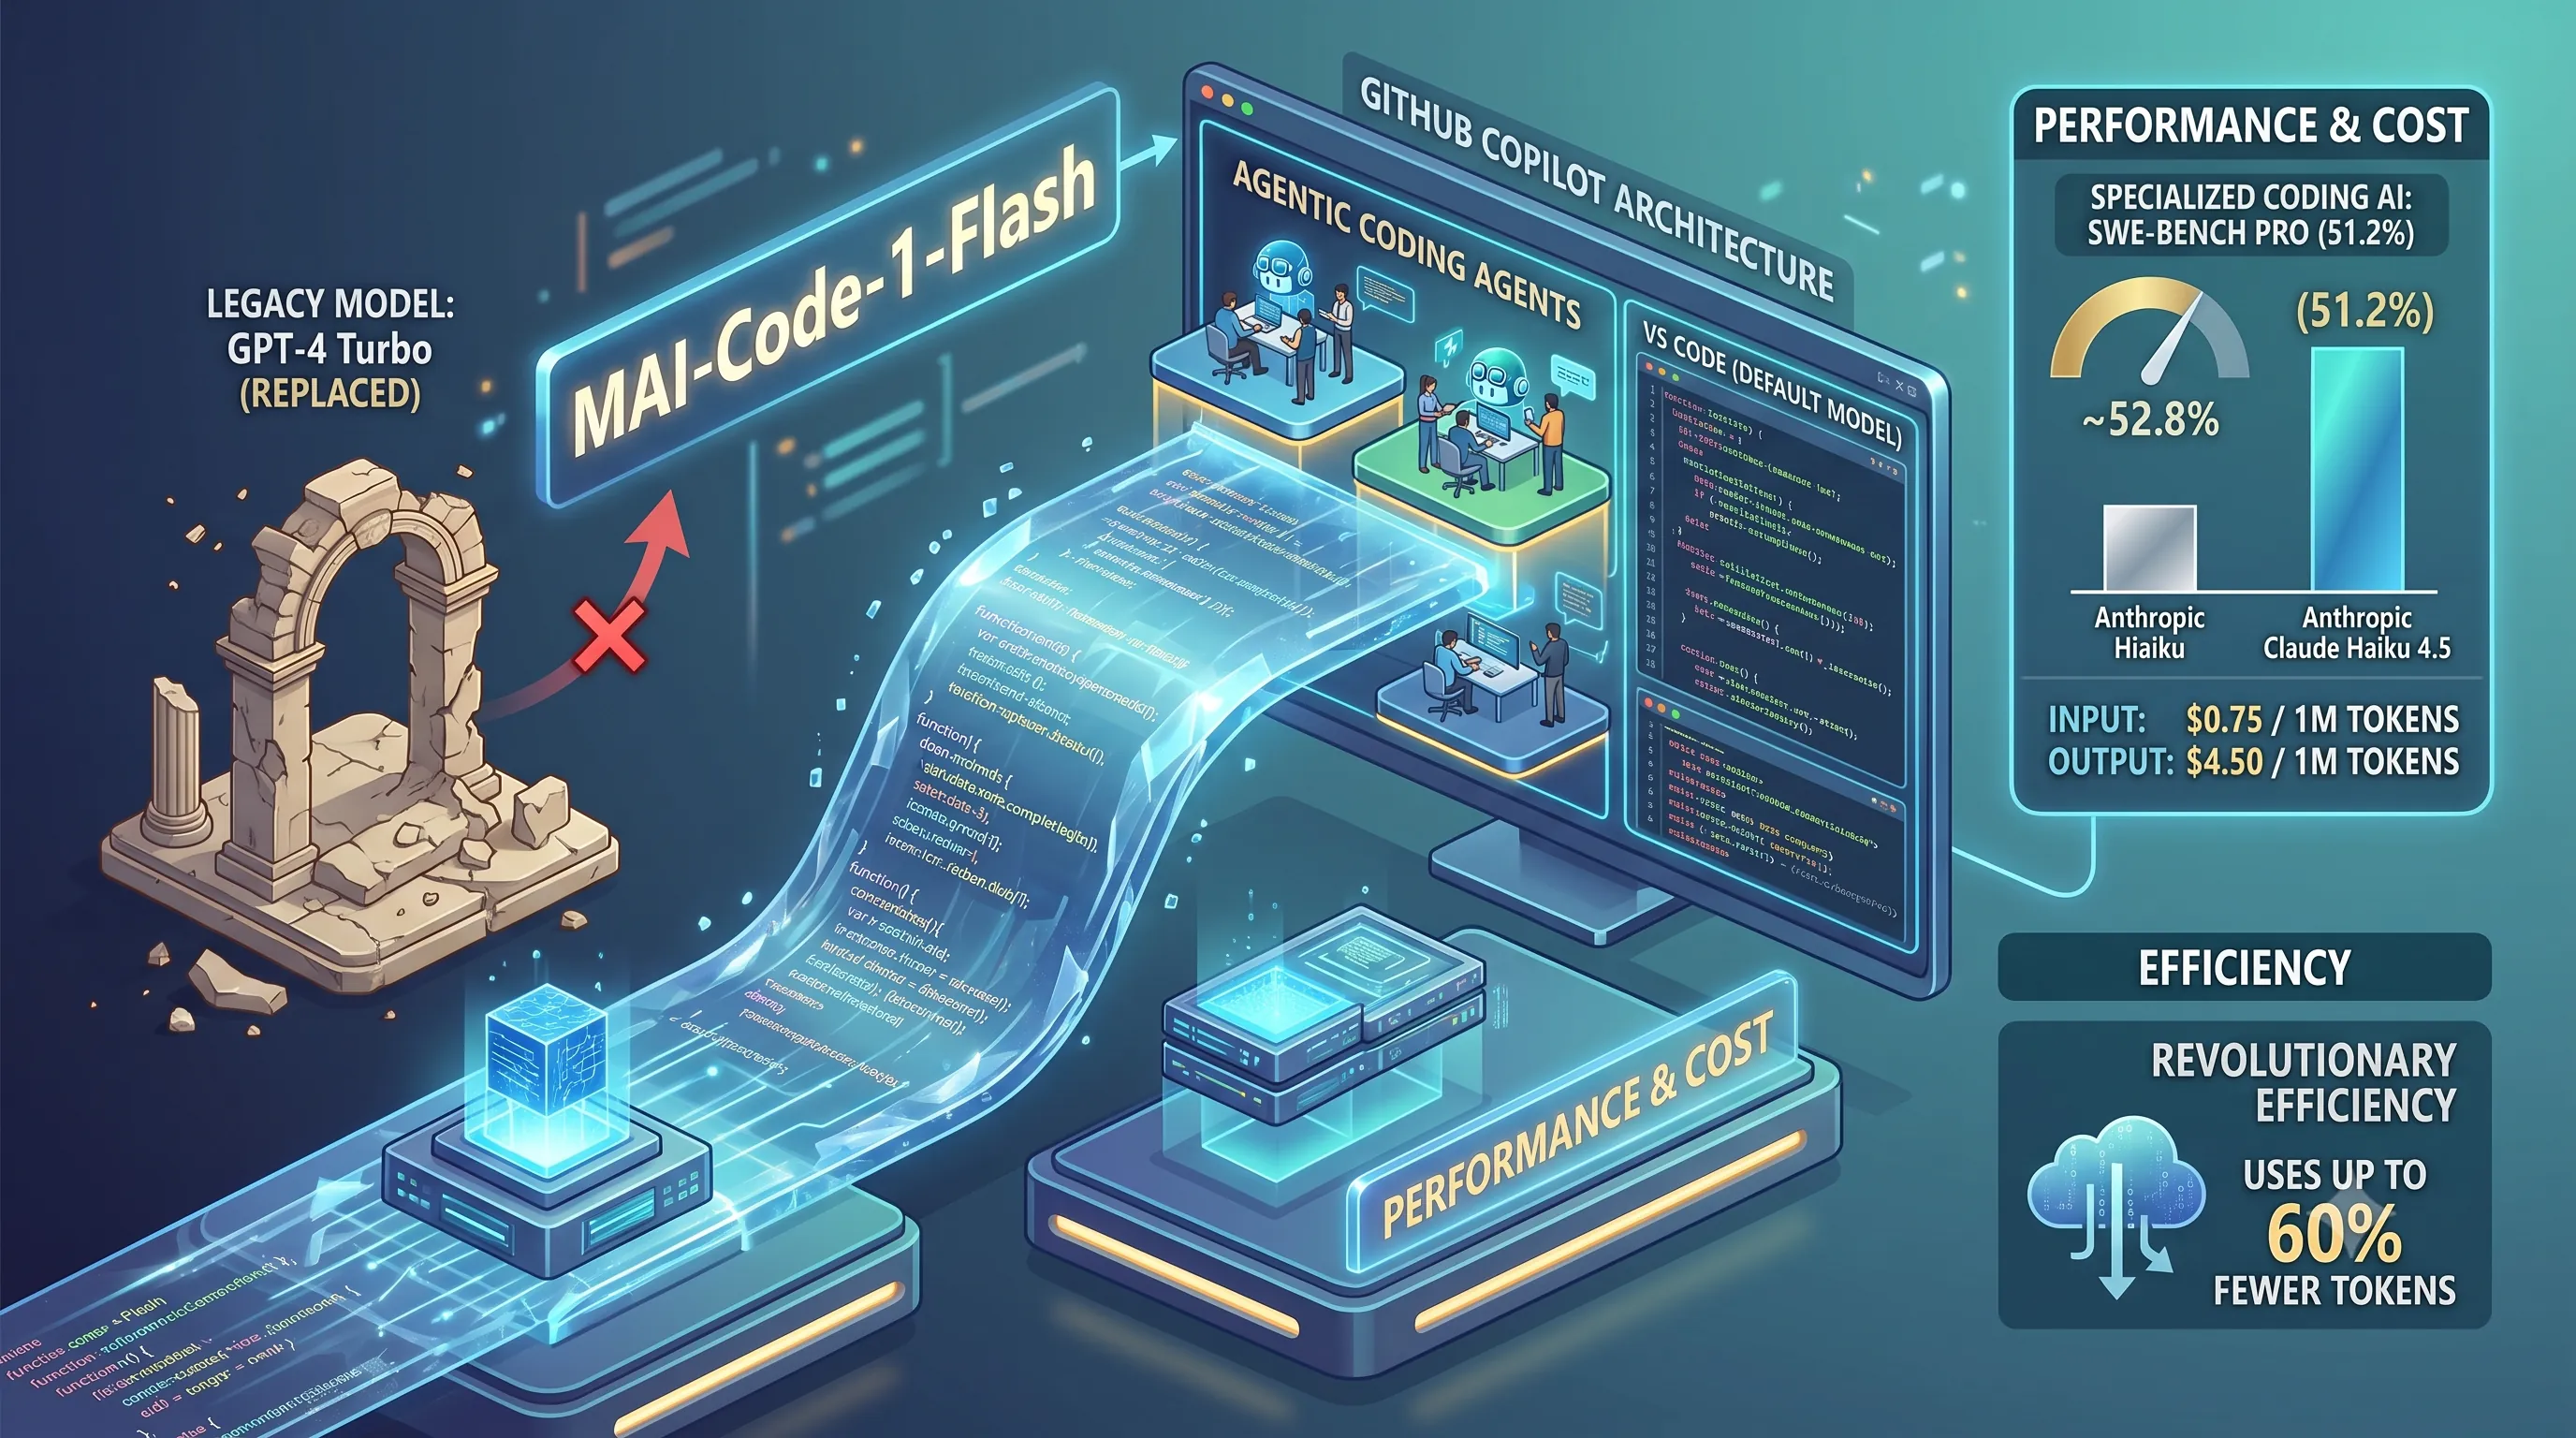
This multi-layered portfolio now includes the MAI cloud models, Phi-4 edge variants, the Aion on-device family, and the overarching Copilot orchestration layer.
This strategy also clarifies the future for other internal models, establishing a clear transition timeline for Phi Silica and a scheduled retirement deadline for the Florence-2 vision model.
| Component | Domain | Description |
|---|---|---|
| MAI Model Family | Cloud | A family of seven foundational models for large-scale, cloud-based AI workloads. |
| Phi-4 Model Family | Edge | A collection of seven model variants optimized for edge computing environments. |
| Aion Model Family | On-Device | A series of models designed to run efficiently directly on user devices. |
| Phi Silica | Transitioning | An existing model with a defined transition timeline into the new first-party stack. |
| Florence-2 | Retiring | A vision-focused model with a scheduled retirement deadline as part of the strategic consolidation. |
| Copilot | Orchestration | The intelligent layer that manages and routes user prompts and tasks across the entire model stack. |
The MAI Family: In-House Innovation and Training
The centerpiece of this new era is the MAI (Microsoft AI) family of models, which was officially unveiled at the Build 2026 conference this past June.Representing Microsoft’s most significant in-house AI investment to date, the MAI family consists of seven distinct models, all developed entirely from the ground up by Mustafa Suleyman’s AI Superintelligence Team.
A key differentiator in their development is the use of an internal training pipeline called the 'Hill-Climbing Machine'.
This internal approach underscores a crucial strategic declaration: no MAI models are distilled from OpenAI, Anthropic, or any other third-party lab, ensuring complete independence.
Furthermore, Microsoft has emphasized that the MAI training data is enterprise-grade, fully traceable, and built upon commercially licensed sources, a critical factor for enterprise customers concerned with data provenance and commercial rights.
Enterprise Adoption and Cost Efficiencies
Microsoft is moving swiftly to commercialize and integrate its new models.The MAI family is being sold directly through Azure Foundry, making it accessible to enterprise customers.
Internally, adoption is already demonstrating the models' practical capabilities.
The MAI-Cyber-1-Flash model is now a core component inside MDASH, Microsoft's advanced multi-agent harness for identifying and remediating software vulnerabilities.
Its application in security is set to expand, with Project Perception planning to leverage the model for a wide range of security workflows.
This internal confidence is mirrored in Microsoft's broader product ecosystem, where the company has already begun replacing some OpenAI and Anthropic models within Microsoft 365 applications.
This shift is not trivial; Bloomberg confirmed that Microsoft is now actively routing tens of thousands of prompts from core applications like Excel and Outlook to its own MAI models.
The financial incentive for this transition is substantial, with internal figures showing that using the MAI models cuts processing costs by up to 89% compared to relying on equivalent OpenAI models.
2. MAI-Thinking-1: Microsoft's Reasoning Flagship Model
This section details the specifications and performance of MAI-Thinking-1, the flagship reasoning model at the heart of Microsoft's strategic shift to first-party AI. It serves as the primary example of the advanced capabilities the company is developing in-house.Technical Prowess and Architecture
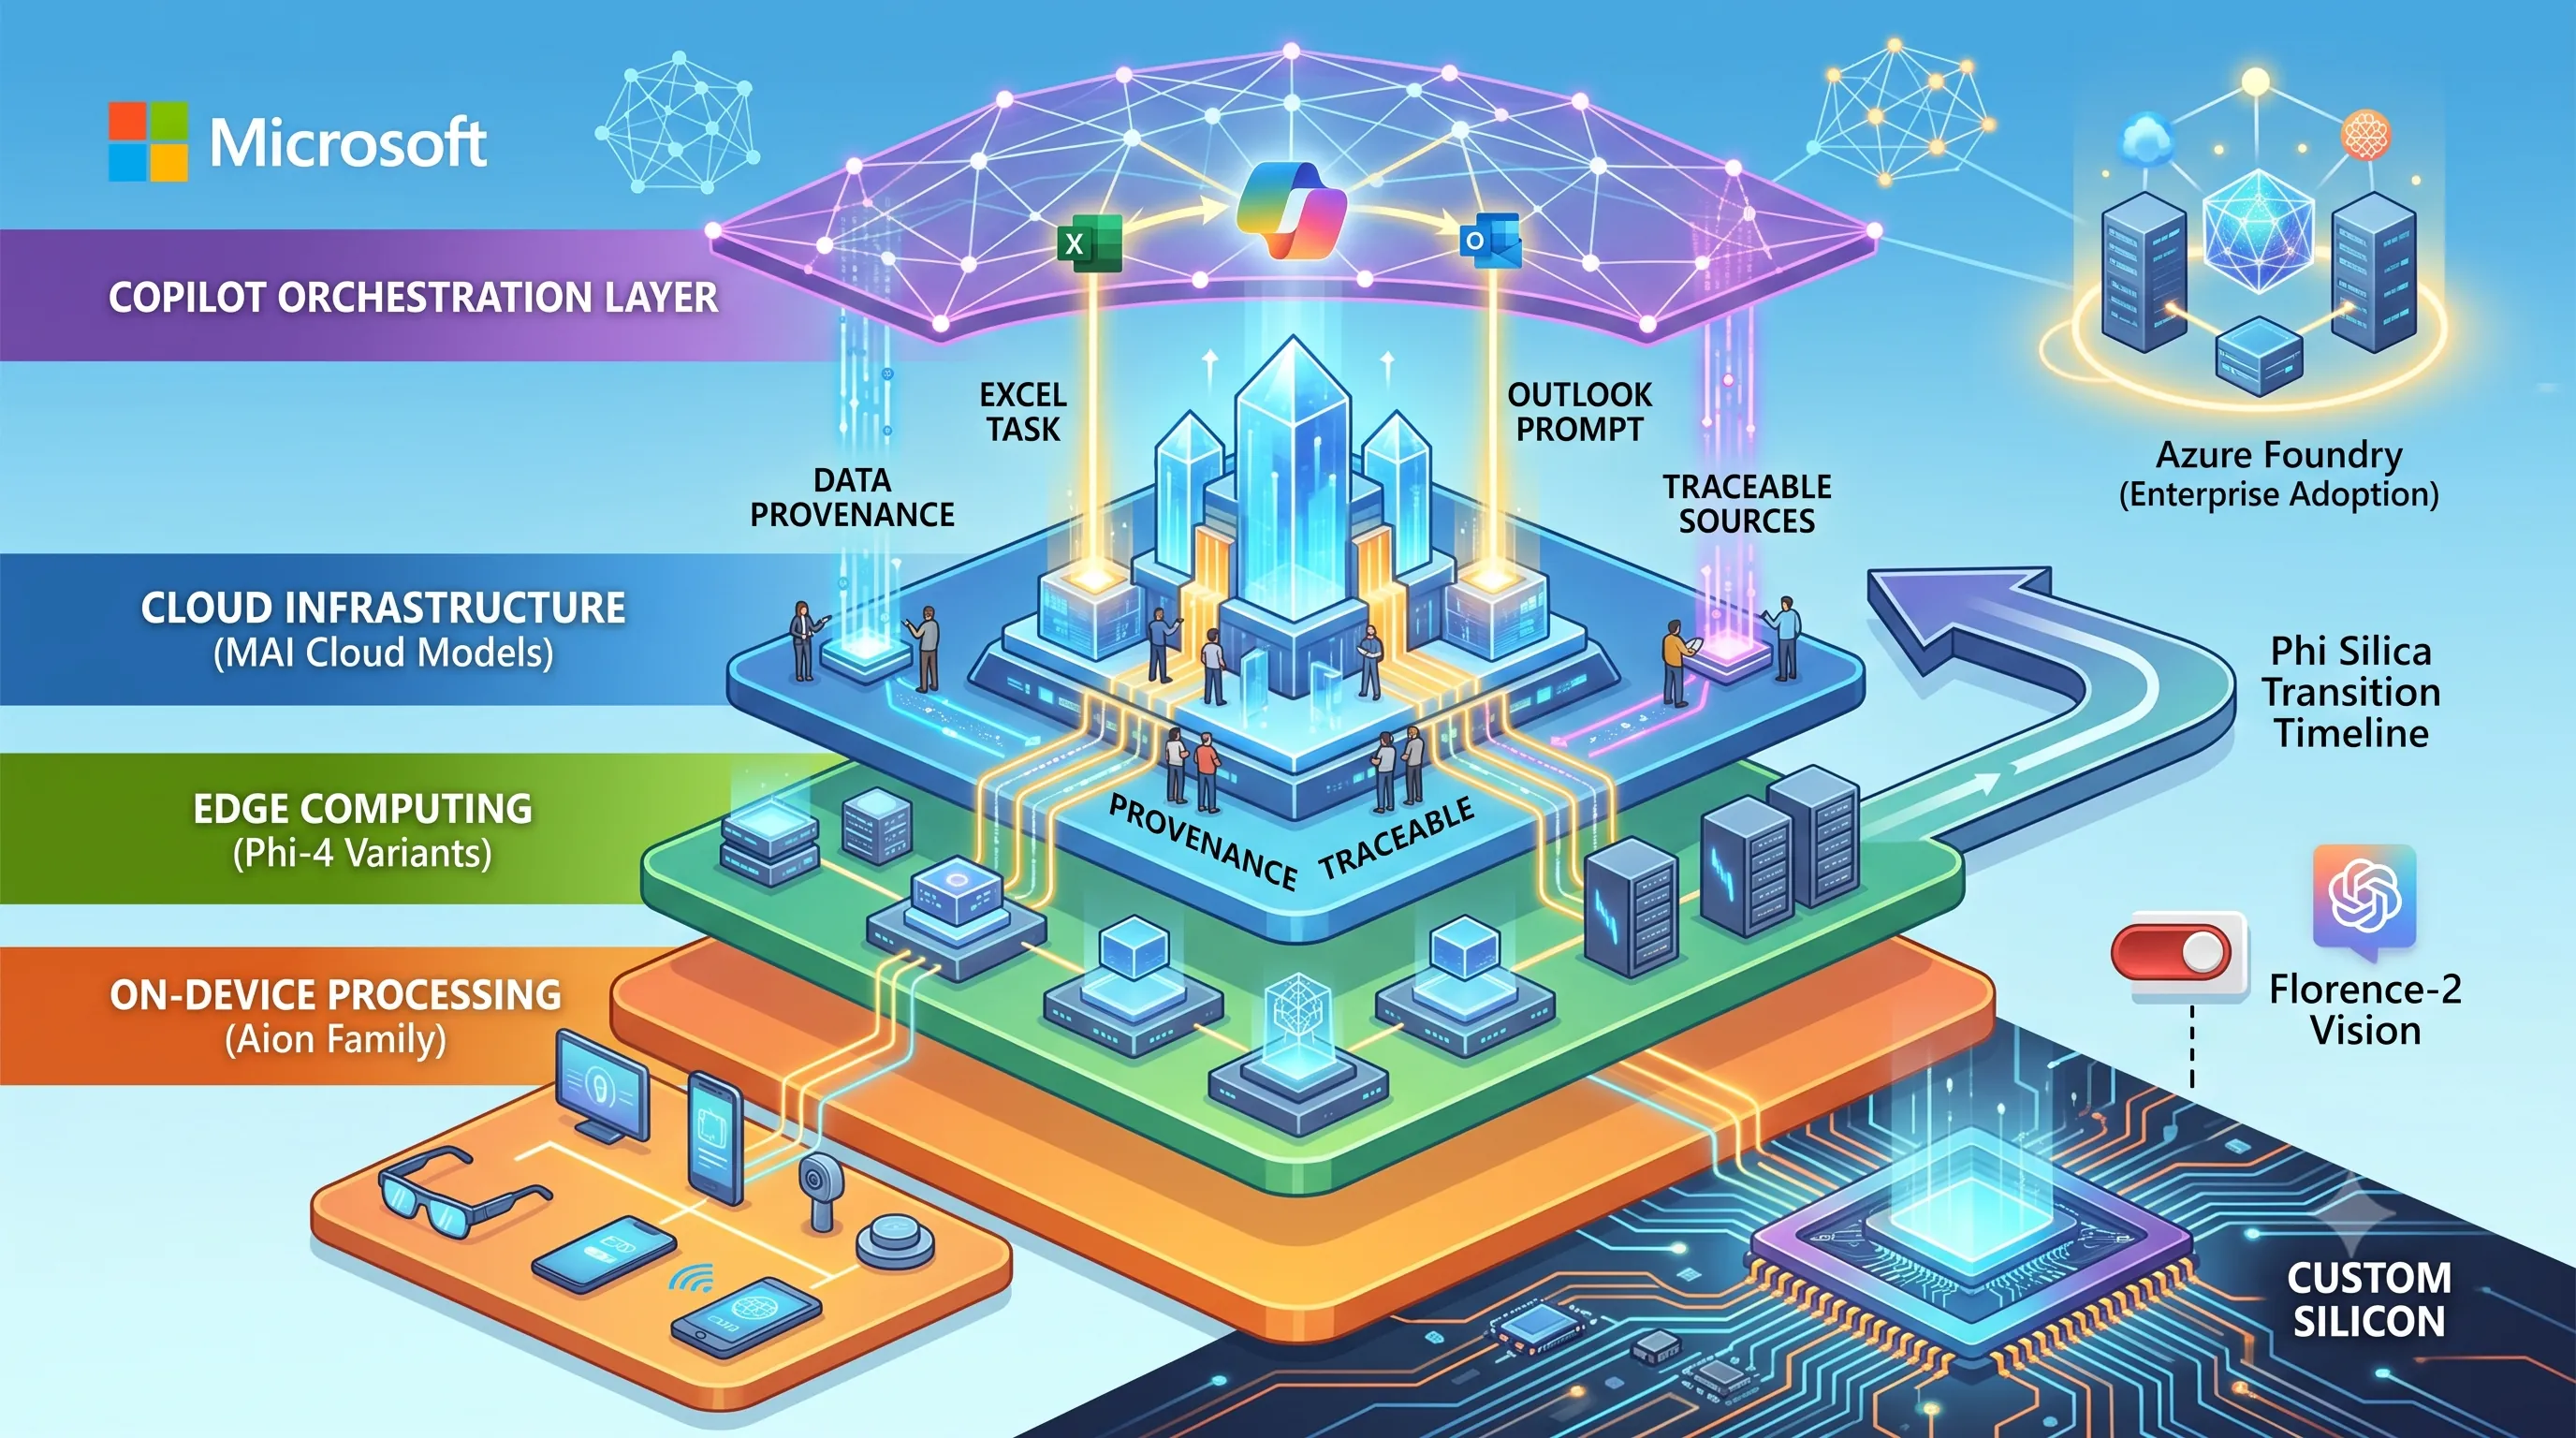
MAI-Thinking-1 is positioned as Microsoft's reasoning flagship model, designed for complex problem-solving and analytical tasks.It is built on a sparse Mixture-of-Experts (MoE) architecture.
This advanced design allows the model to be exceptionally large while remaining computationally efficient, utilizing approximately 35 billion active parameters from a massive pool of around 1 trillion total parameters for any given inference.
The model also features a substantial 256K token context window, enabling it to process and analyze extensive documents and complex prompts in a single pass.
| Specification | Detail |
|---|---|
| Model Type | Reasoning Flagship |
| Architecture | Sparse Mixture-of-Experts (MoE) |
| Total Parameters | ~1 Trillion |
| Active Parameters | ~35 Billion |
| Context Window | 256K Tokens |
Benchmark Performance and Market Position
MAI-Thinking-1 has demonstrated exceptional performance across multiple industry-standard benchmarks.In rigorous mathematical reasoning tests, it achieved a score of 97.0% on AIME 2025 and 94.5% on AIME 2026.
For software engineering and coding tasks, the model scored approximately 52.8% on the challenging SWE-Bench Pro benchmark, a result that puts it on par with the performance of Anthropic's Claude Opus 4.6.
Beyond quantitative metrics, the model also excelled in qualitative assessments.
In a blind human evaluation involving 1,276 distinct tasks, MAI-Thinking-1 was consistently preferred over Claude Sonnet 4.6, signaling strong user acceptance and real-world utility.
Availability and Rollout Timeline
As of early August 2026, MAI-Thinking-1 is currently available in a private preview exclusively on the Azure Foundry platform.Broader access is imminent, as a public preview is expected to be launched within weeks.
3. MAI-Code-1-Flash: Revolutionizing GitHub Copilot and VS Code
This section delves into MAI-Code-1-Flash, a key component of Microsoft's new first-party AI strategy, explaining how its superior performance, efficiency, and deep integration are transforming the company's core developer tools.Cost-Performance Leadership in Coding AI
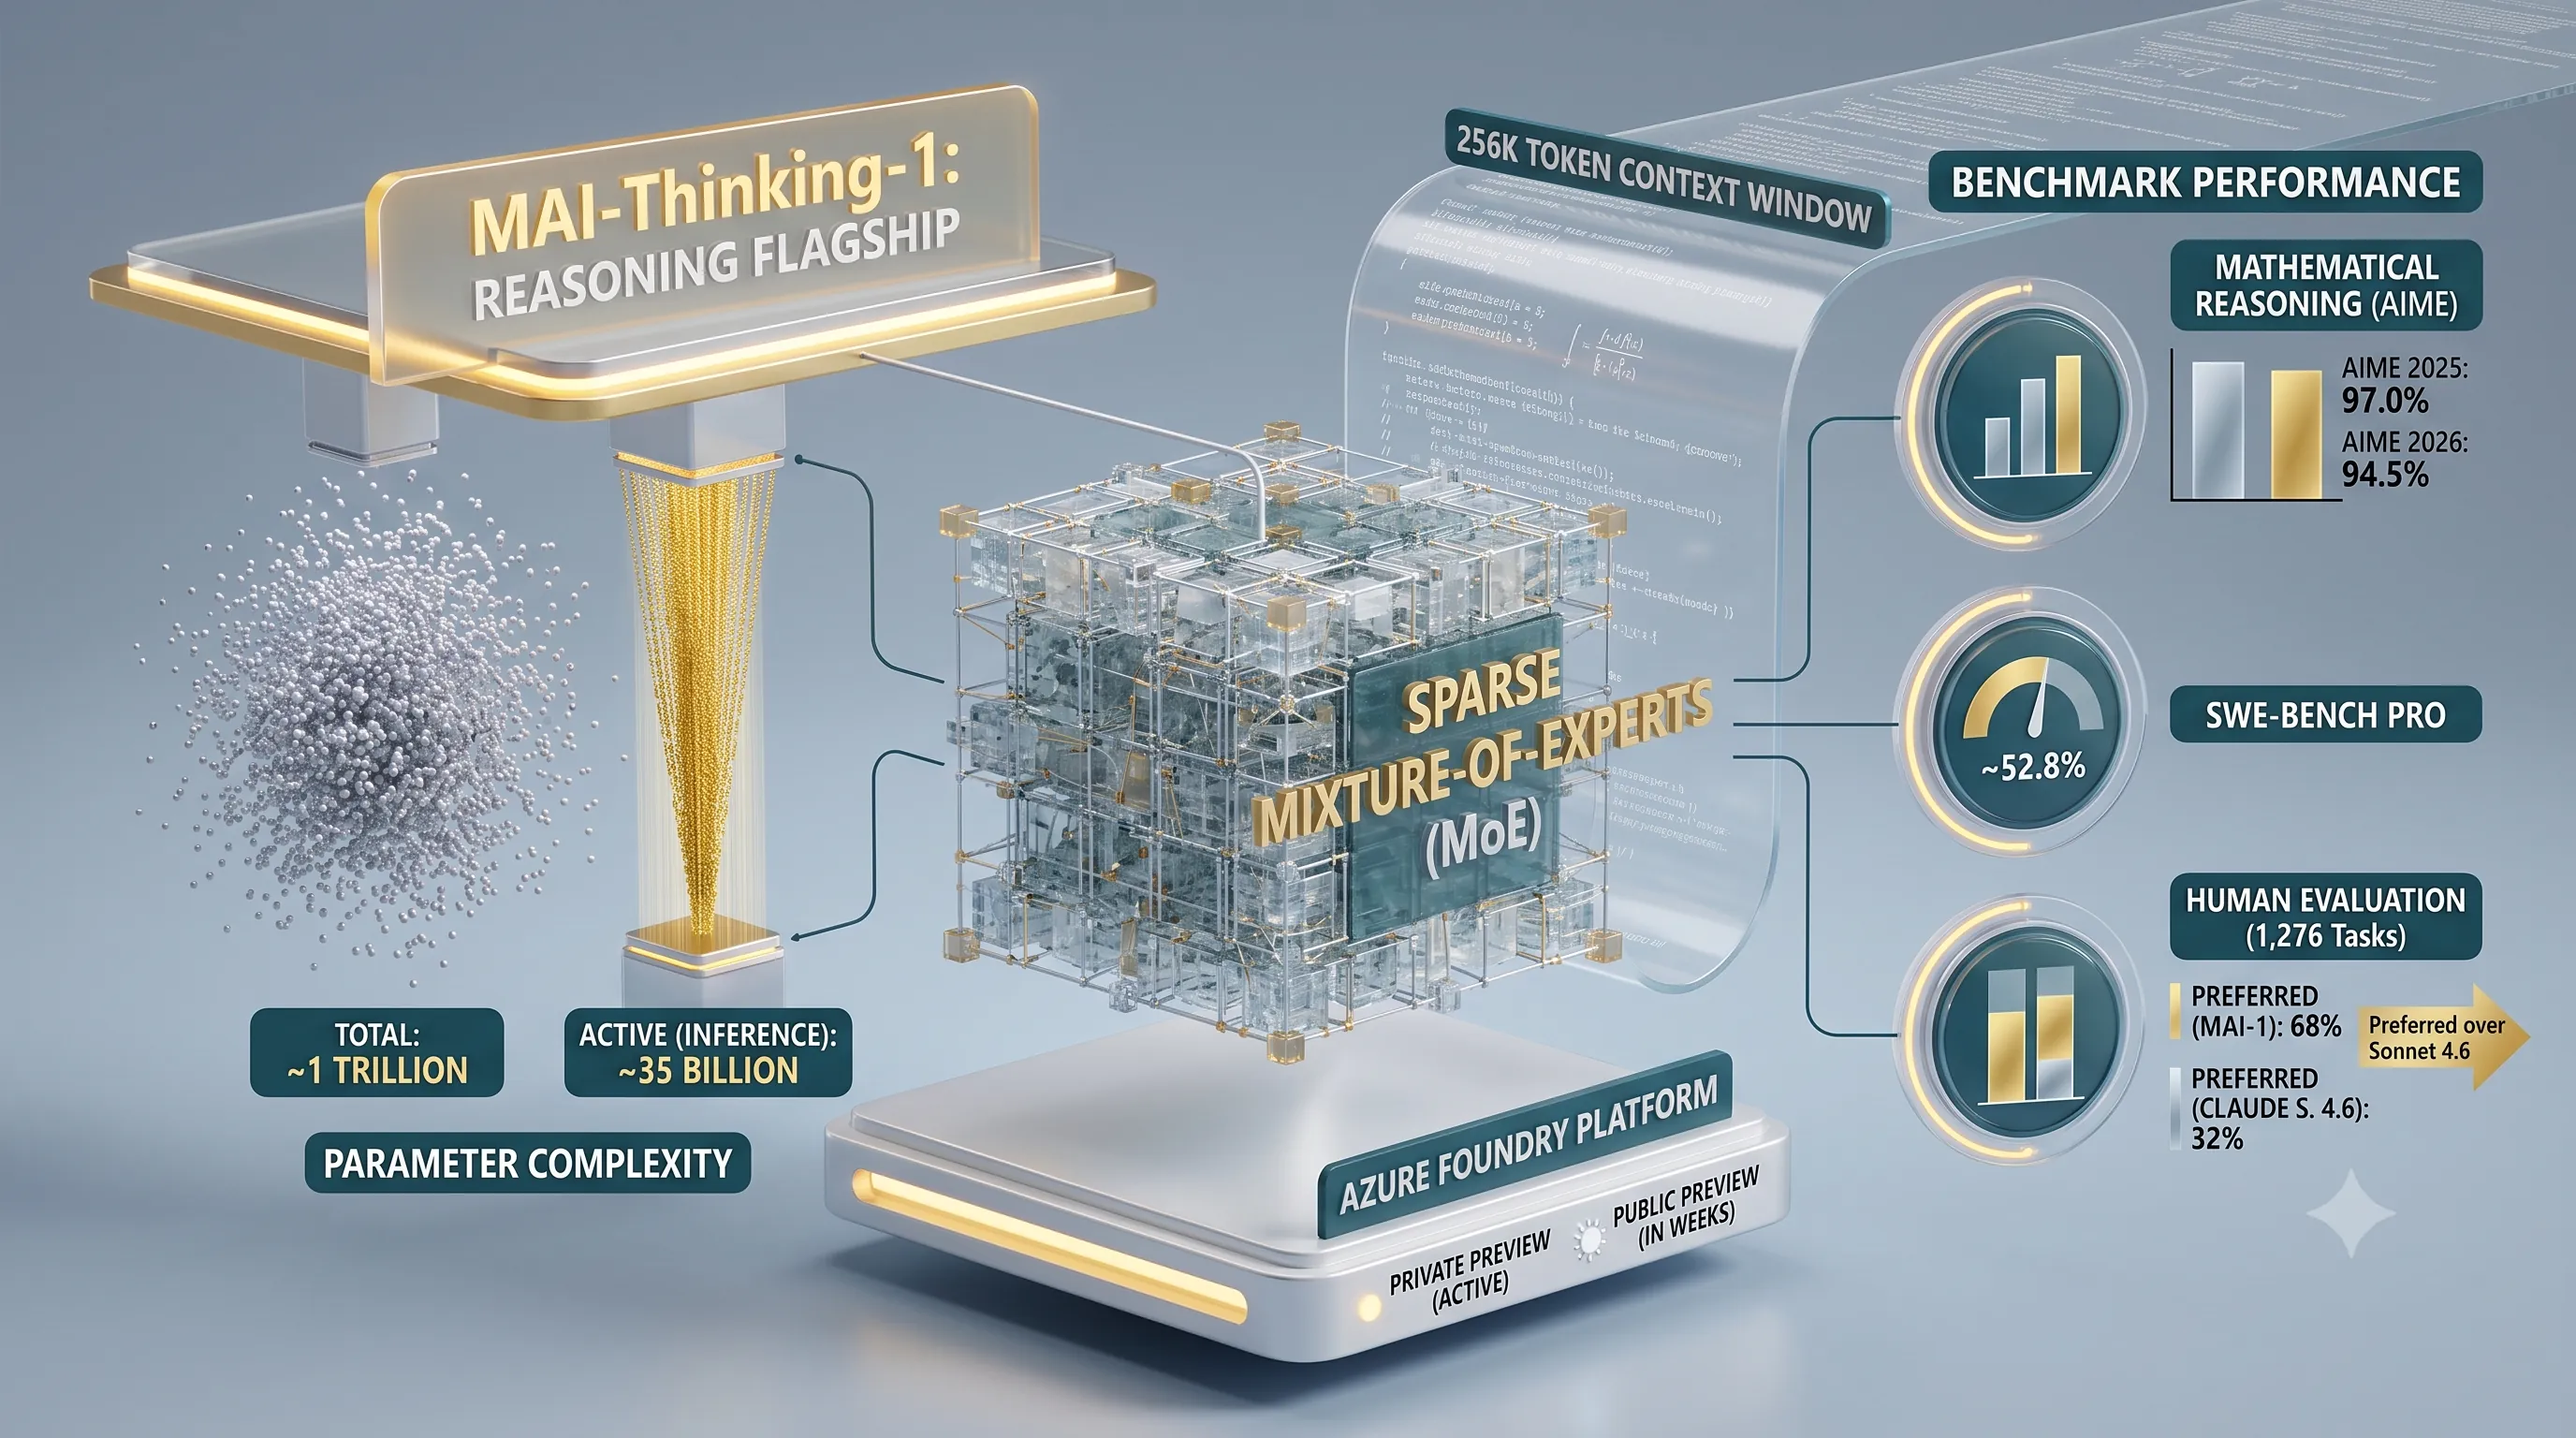
MAI-Code-1-Flash has established itself as a formidable new player in the specialized field of coding models, demonstrating a powerful combination of performance and cost-effectiveness.On the industry-standard SWE-Bench Pro benchmark, the model achieved a remarkable score of 51.2%.
This result is not just strong in isolation; it represents a significant leap over competitors, placing it a full 16 points ahead of Claude Haiku 4.5.
Beyond raw performance, the model is engineered for exceptional efficiency, a critical factor for large-scale deployment.
It manages to use up to 60% fewer tokens than comparable models to achieve its results, directly impacting operational costs and response latency.
This efficiency is reflected in its competitive pricing structure, set at $0.75 per 1 million input tokens and $4.50 per 1 million output tokens.
| Metric | Specification |
|---|---|
| SWE-Bench Pro Score | 51.2% |
| Input Token Price | $0.75 / 1M tokens |
| Output Token Price | $4.50 / 1M tokens |
| Token Efficiency | Uses up to 60% fewer tokens than comparable models |
Seamless Integration with Microsoft Developer Tools
Since it became generally available on June 26, 2026, MAI-Code-1-Flash has been rapidly integrated into Microsoft's developer ecosystem.Described as an inference-efficient agentic coding model, it was specifically created to power Microsoft's flagship coding assistants.
The model is tailor-made for and deeply integrated into GitHub Copilot and VS Code, moving beyond a simple API swap to a more fundamental re-architecture of these tools.
In a clear demonstration of this first-party strategy, it is actively replacing GPT-4 Turbo in GitHub Copilot.
This transition is comprehensive, with the model rolling out across all GitHub Copilot tiers.
Furthermore, MAI-Code-1-Flash has already become the default model in VS Code, bringing its performance and efficiency benefits directly to millions of developers.
4. MAI's Creative Suite: Image, Voice, and Transcription Models
This section of our analysis on Microsoft's first-party 'MAI' AI model transition focuses on the specialized creative and productivity models that complement the flagship generalist models.These tools for image generation, transcription, and voice synthesis demonstrate MAI's breadth and are being integrated directly into Microsoft’s core software ecosystem.
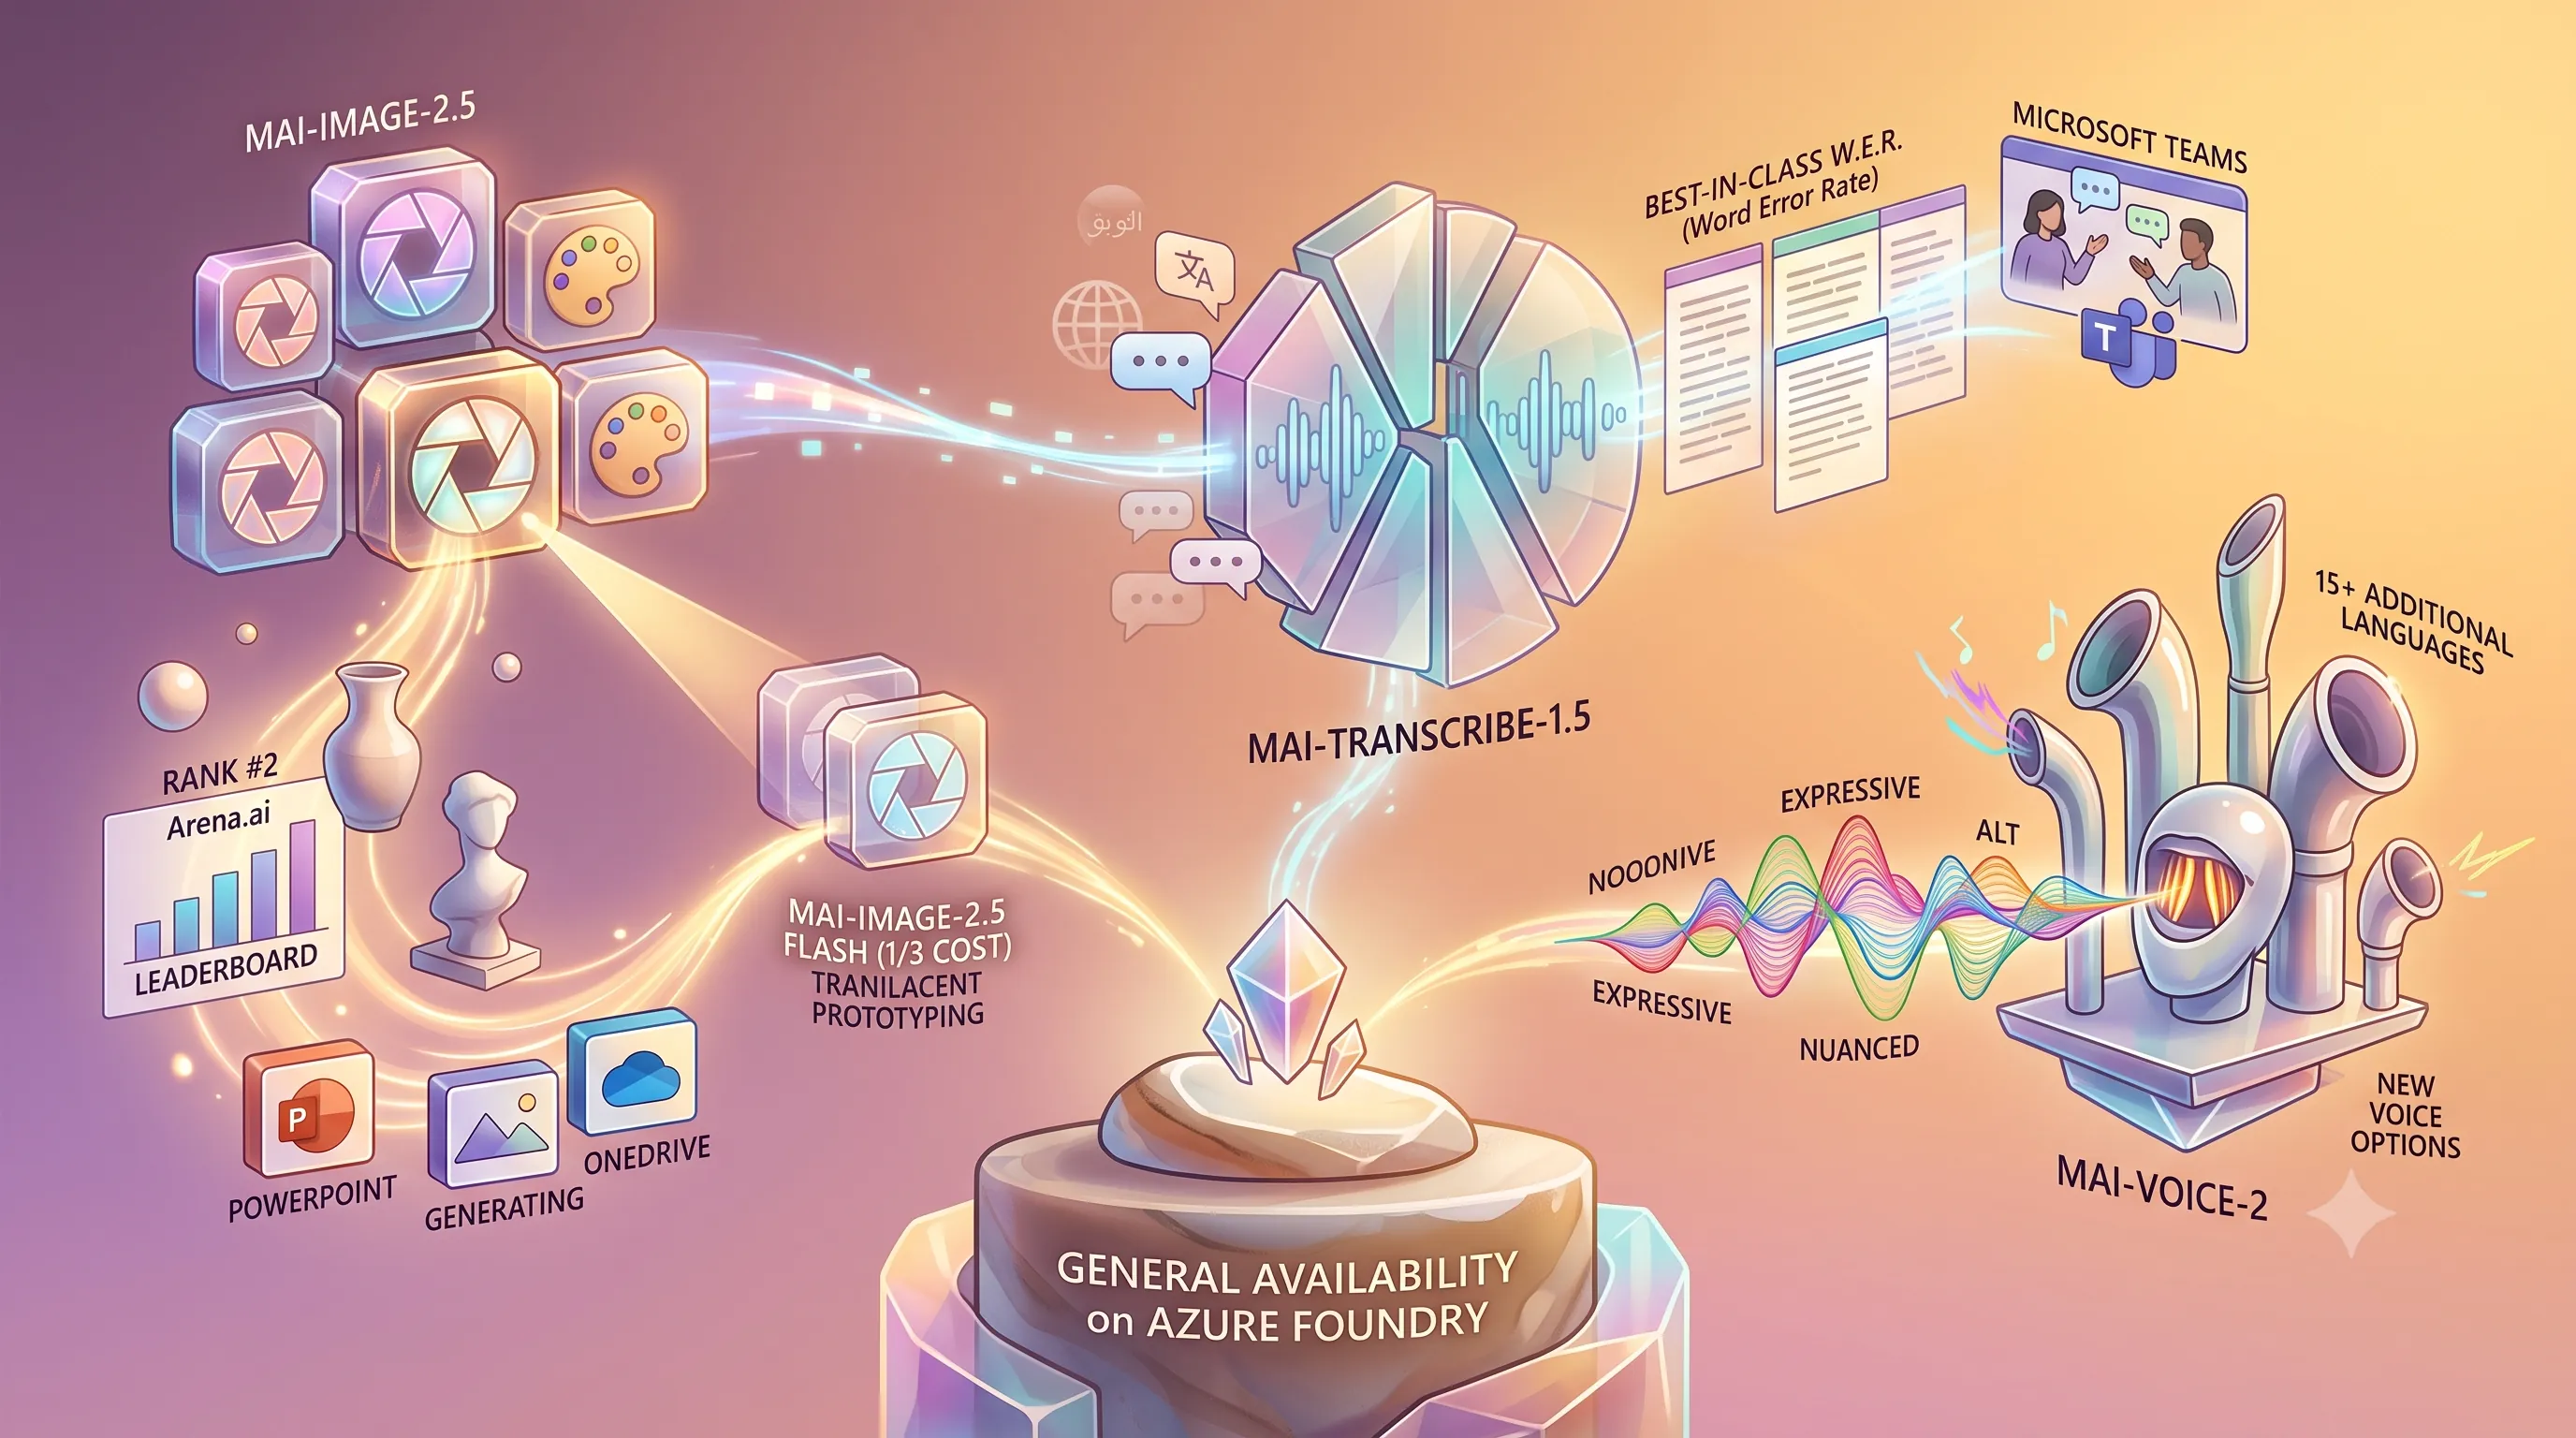
MAI-Image-2.5: Advanced Visual Creation
Microsoft's MAI-Image-2.5 has established itself as a formidable competitor in the visual generation space, securing the #2 rank on Arena.ai’s image editing leaderboard and notably surpassing the performance of Nano Banana Pro.This model is not just a benchmark performer; it is already integrated into key productivity applications like PowerPoint and OneDrive, bringing advanced image creation capabilities directly into user workflows.
For developers and creators focused on rapid iteration, Microsoft offers the MAI-Image-2.5 Flash variant (also known as MAI-Image-2-Efficient), which enables faster prototyping at a significantly lower operational cost.
This efficient version provides generation at roughly one-third the cost of the full model.
Both MAI-Image-2.5 and its Flash variant are now generally available for developers to build with on Azure Foundry.
MAI-Transcribe-1.5: Precision Speech-to-Text
In the domain of speech-to-text, MAI-Transcribe-1.5 sets a new standard for accuracy.Microsoft claims the model achieves a best-in-class Word Error Rate (WER) across 43 different languages, making it a highly reliable solution for global enterprise needs.
Reflecting this confidence, the model is currently rolling out within Microsoft Teams to power its transcription features, bringing this enhanced precision to millions of users' meetings and calls.
For custom applications, MAI-Transcribe-1.5 is also generally available on Azure Foundry.
MAI-Voice-2: Expressive Text-to-Speech
MAI-Voice-2 represents a significant leap forward in synthetic voice generation, positioned as Microsoft’s most expressive Text-to-Speech (TTS) model to date.The model focuses on delivering nuanced and natural-sounding audio for a wide range of applications.
Its global reach was also expanded, with the model and its variants now available in more than 15 additional languages, accompanied by new voice options.
Like its creative suite counterparts, MAI-Voice-2 is generally available on Azure Foundry for developers to integrate into their services.
| Model Name | Key Features & Performance | Availability |
|---|---|---|
| MAI-Image-2.5 | Ranks #2 on Arena.ai image editing leaderboard. Flash variant offers generation at 1/3 the cost for rapid prototyping. Integrated into PowerPoint and OneDrive. |
General Availability on Azure Foundry |
| MAI-Transcribe-1.5 | Claims best-in-class Word Error Rate across 43 languages. | General Availability on Azure Foundry; rolling out in Microsoft Teams. |
| MAI-Voice-2 | Microsoft’s most expressive TTS model to date. Available in 15+ additional languages with new voice options. |
General Availability on Azure Foundry |
5. Frontier Tuning with RLEs: Customizing MAI for Enterprise Excellence
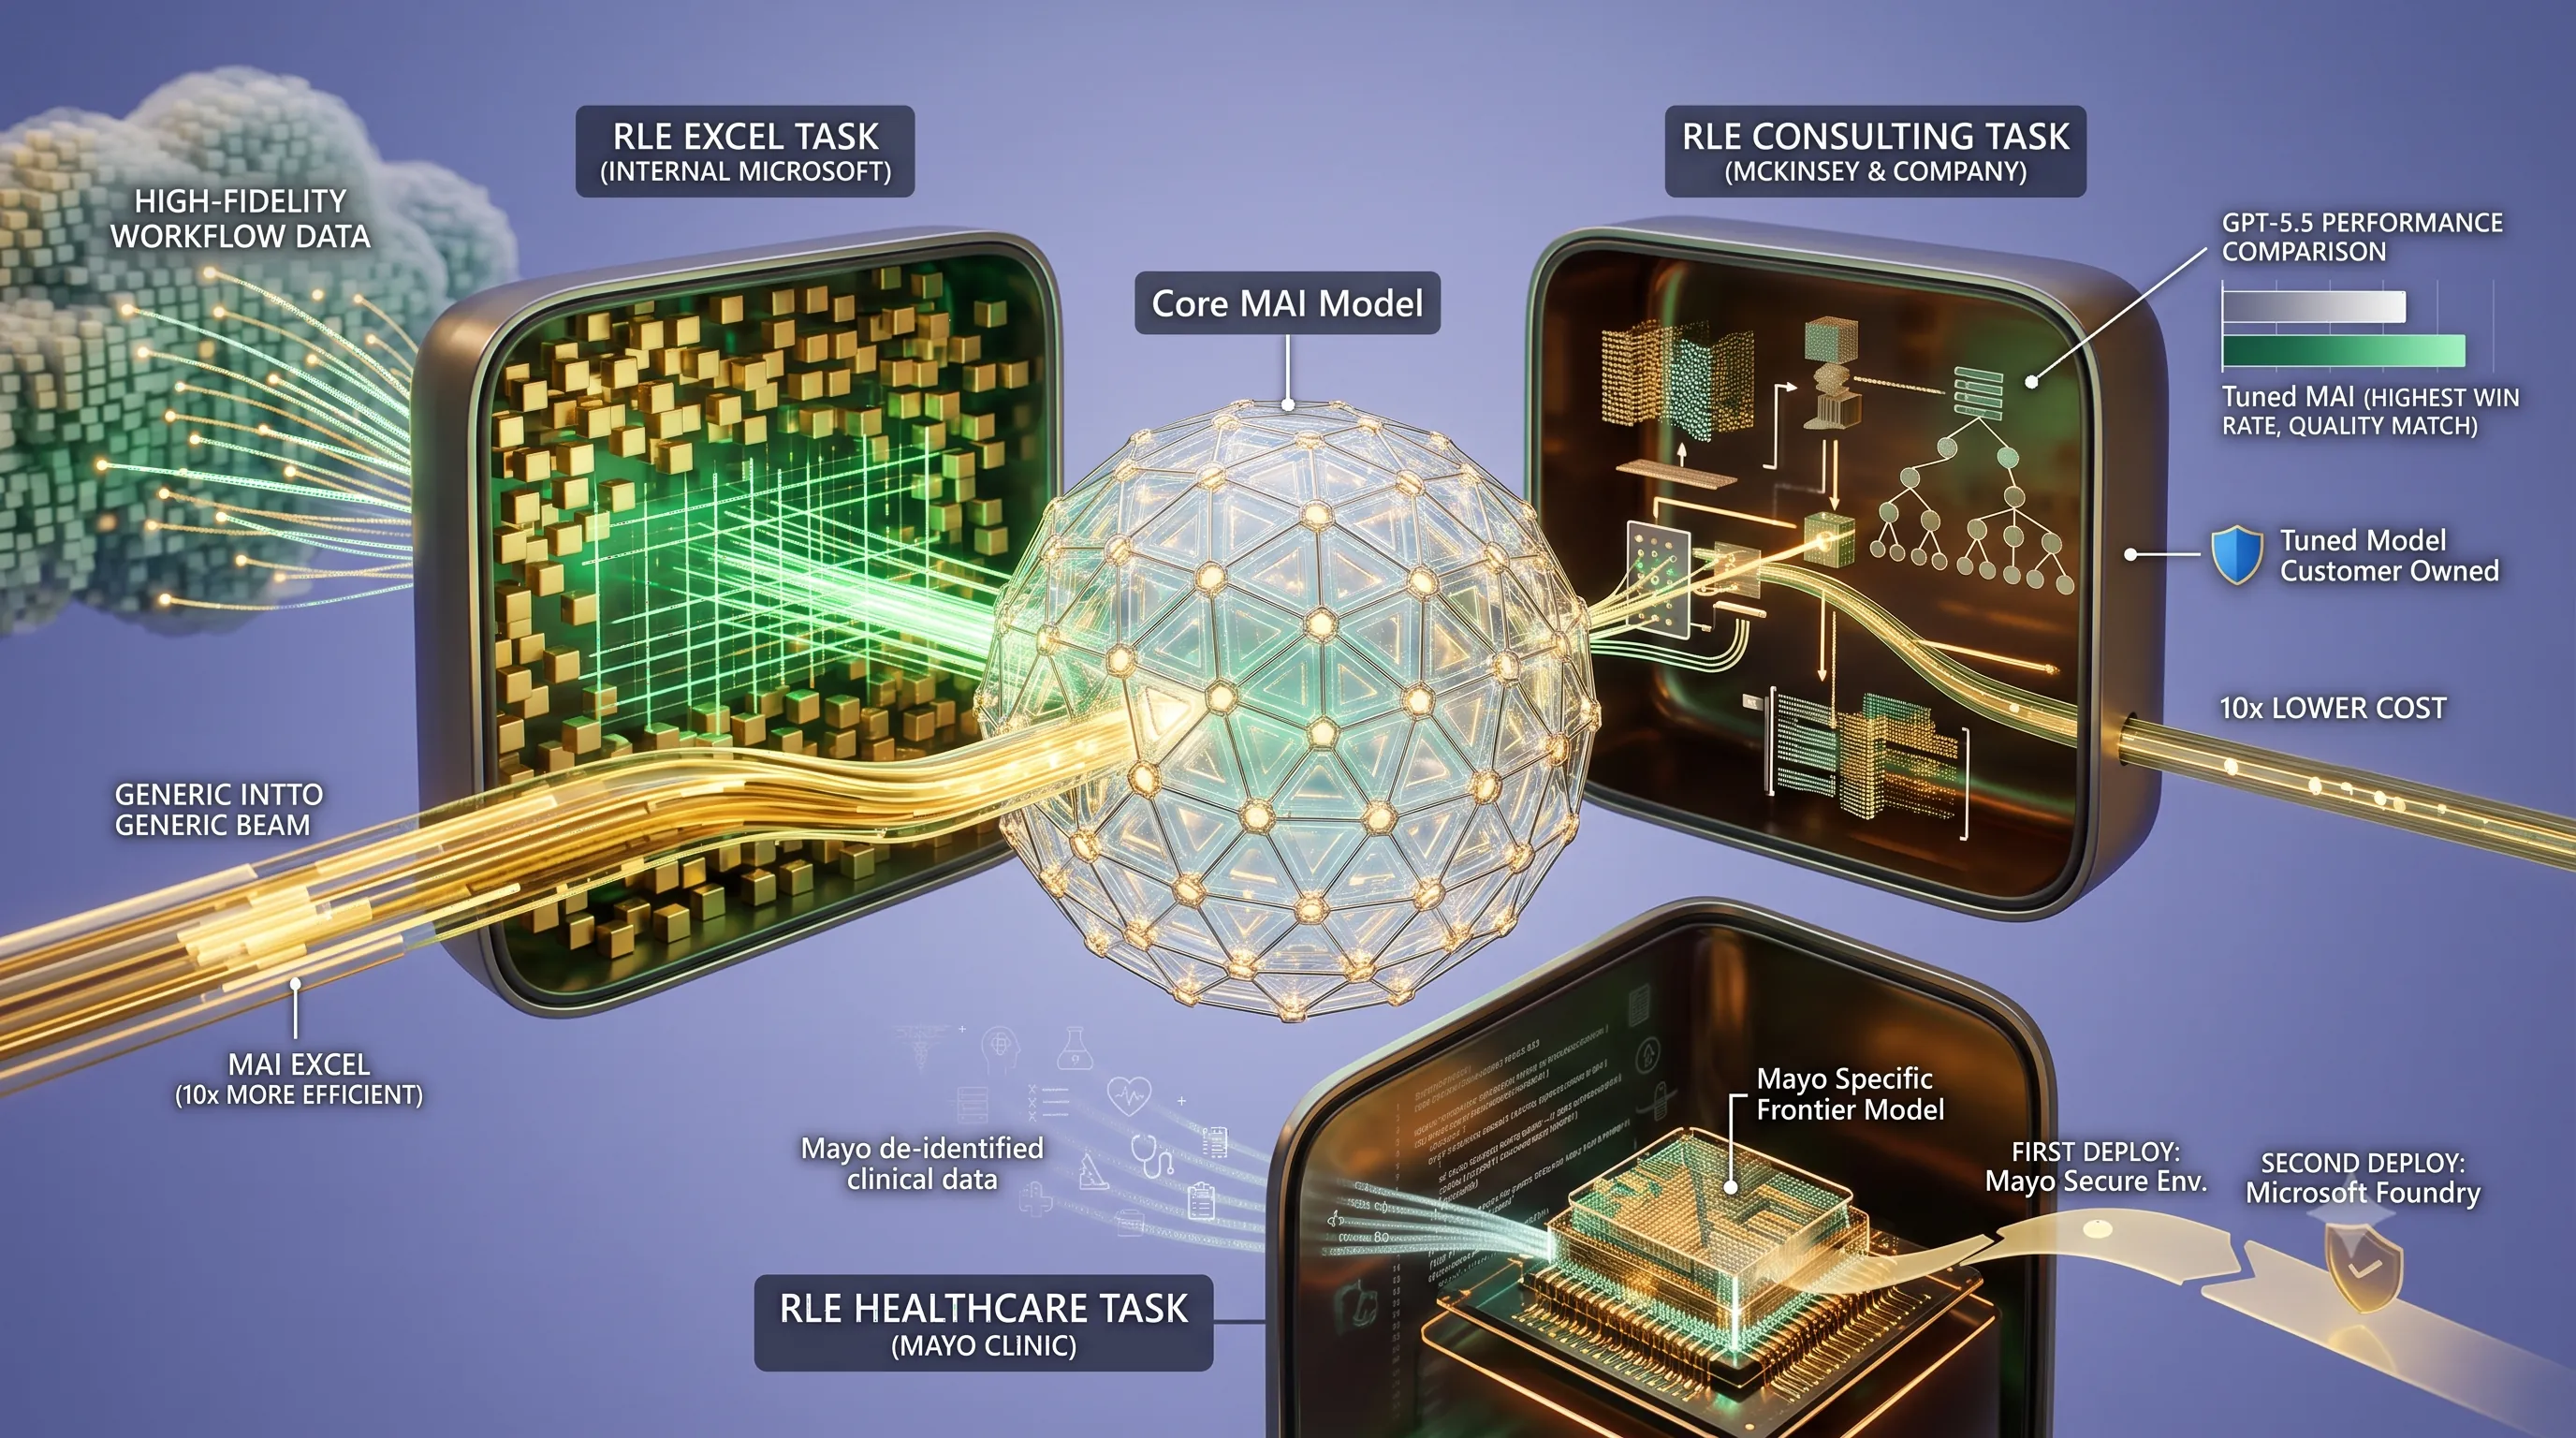
A core pillar of Microsoft's new first-party AI strategy is not just providing a powerful general model, but enabling enterprises to transform it into a highly specialized, proprietary asset.This is accomplished through Frontier Tuning, a process powered by Microsoft's Reinforcement Learning Environments (RLEs) that allows organizations to infuse the foundational MAI model with their unique data and expertise.
Empowering Enterprise Customization
Microsoft’s Reinforcement Learning Environments (RLEs) are the key mechanism for deep enterprise customization.These sophisticated environments allow organizations to tune the general-purpose MAI models using their own specific, high-fidelity workflow data.
By training the model on real-world internal processes and datasets, the RLEs effectively transform the AI into a bespoke tool.
This process goes beyond simple fine-tuning; it embeds an organization's deep institutional knowledge directly into the model itself, creating an AI that understands the nuances of the business in a way no off-the-shelf model can.
Efficiency Gains and Model Ownership
The results of this deep customization are substantial, delivering measurable improvements in performance and cost-effectiveness.Internally, Microsoft has demonstrated this power by creating a tuned MAI model for Excel that is up to 10x more efficient and matches the performance of GPT-5.4.
In a prominent enterprise case with McKinsey & Company, the benefits were even more pronounced.
According to Microsoft AI CEO Mustafa Suleyman, the tuned models developed for McKinsey's tasks not only delivered the highest win rate but also outperformed GPT-5.5 on quality metrics.
Financially, this specialization resulted in a model that was 10x lower on cost for the specific tasks.
Critically, Microsoft has structured this offering to ensure that any model tuned through an RLE remains fully owned by the customer, allowing them to retain their intellectual property and competitive advantage.
| Tuning Case Study | Key Performance & Cost Metrics | Ownership & Deployment |
|---|---|---|
| Microsoft Excel | Up to 10x more efficient; performance matches GPT-5.4. | Internal model demonstrating RLE capabilities. |
| McKinsey & Company | 10x lower cost; highest win rate, outperforming GPT-5.5 on quality. | Tuned model is owned by the customer. |
| Mayo Clinic | Healthcare-specific frontier model co-created with de-identified clinical data. | The model will be owned by Mayo Clinic and deployed first in their environment, then via Microsoft Foundry. |
Collaborative Innovation: The Mayo Clinic Example
The partnership with the Mayo Clinic serves as a landmark example of co-creating a specialized frontier model.In this collaboration, Mayo Clinic is combining its vast repository of de-identified clinical data with Microsoft’s foundational AI technology.
This deep integration is producing a new, healthcare-specific frontier model designed for complex medical applications.
Following the principle of customer empowerment, the resulting model will be owned entirely by Mayo Clinic.
The deployment strategy further reflects this, with the model set to be deployed first within the Mayo Clinic's own secure environment, and subsequently made available to the wider healthcare industry through the Microsoft Foundry platform.
6. Phi-4 Edge SLM Portfolio: Powering On-Device and Specialized AI
This section provides a deep dive into the Phi-4 family of small language models (SLMs), a cornerstone of Microsoft's strategy to deliver powerful, efficient AI directly on user devices and for specialized enterprise needs, tying directly into the company's broader shift towards its first-party MAI model portfolio.Comprehensive Open-Weight SLM Portfolio
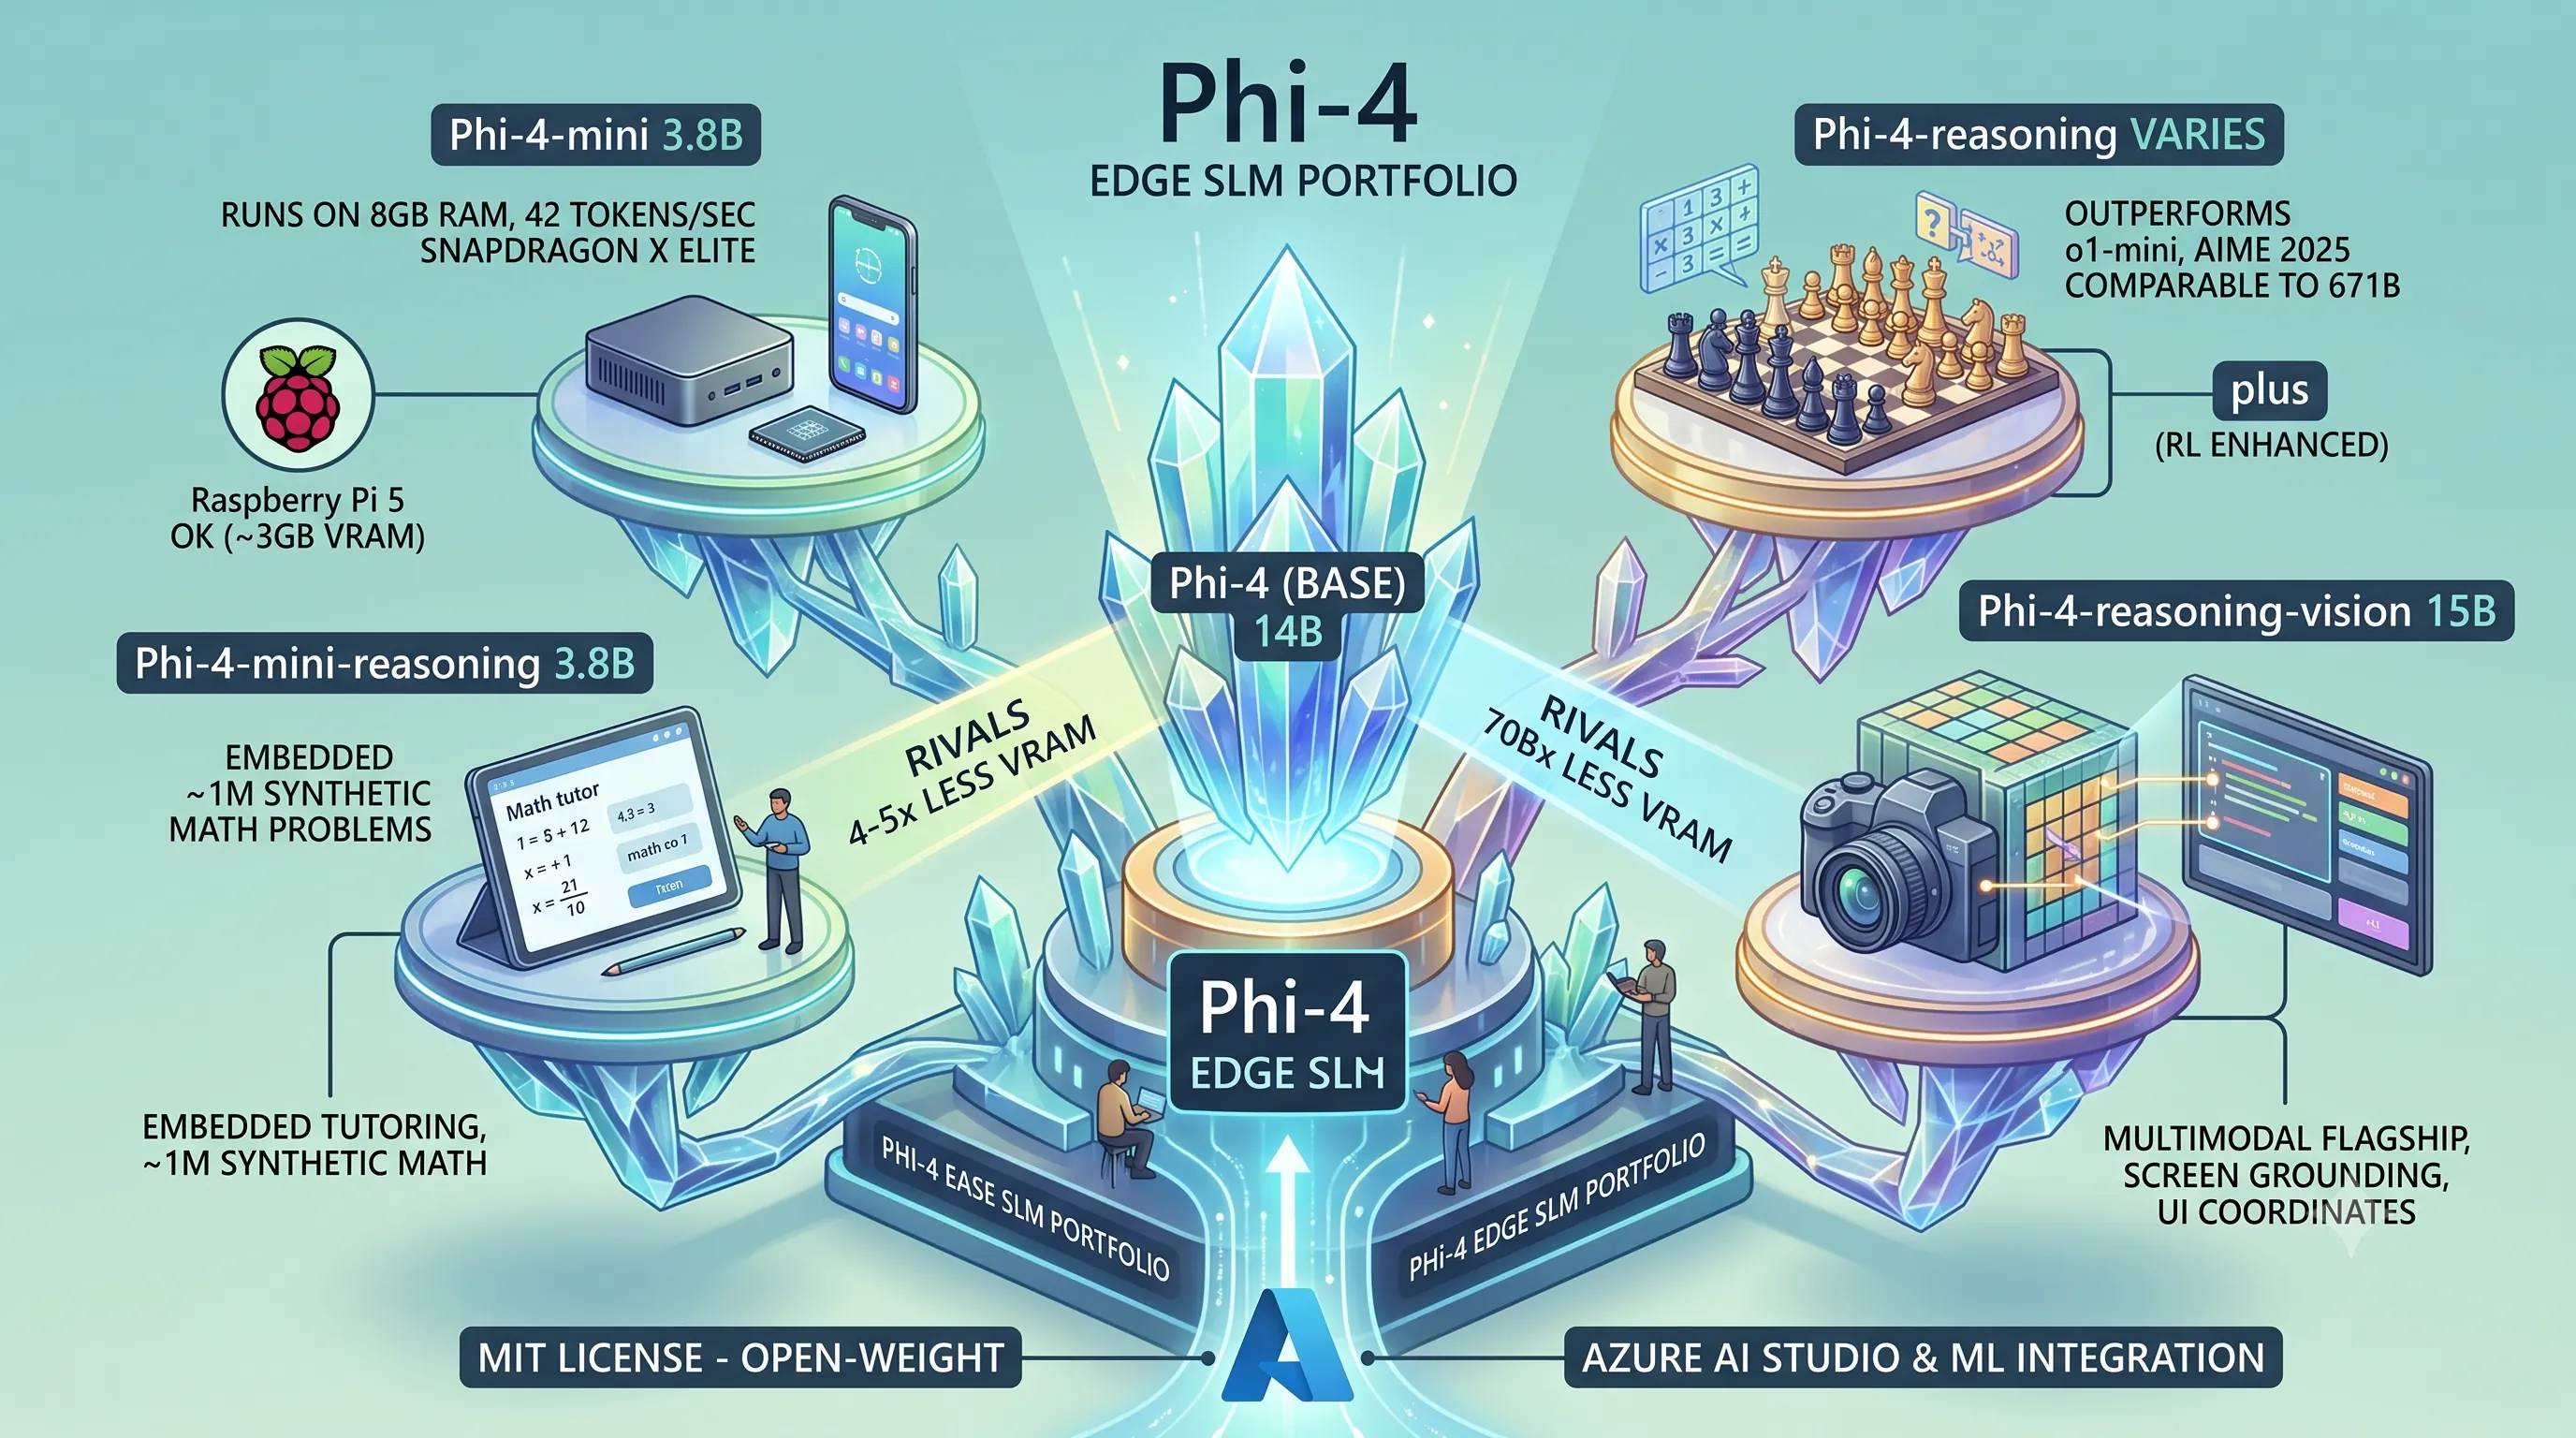
Microsoft has positioned the Phi-4 family as the industry's most compelling small language model portfolio, offering a diverse and accessible toolkit for developers and enterprises.The family consists of seven distinct variants, all released under the permissive MIT license, encouraging widespread adoption and innovation.
This portfolio is explicitly designed to cover a wide spectrum of applications, including advanced reasoning, computer vision, multimodal interactions, and critically, deployment in edge computing scenarios.
Underscoring its enterprise readiness, the base Phi-4 model is deeply integrated into Azure AI Studio, providing developers with a substantial 128K context window and robust fine-tuning support through Azure Machine Learning.
Performance and Efficiency Across Variants
The Phi-4 family achieves a remarkable balance between high performance and resource efficiency, enabling capabilities previously restricted to much larger models.The base Phi-4 model, with 14 billion parameters, was trained on a massive, curated dataset of 4.8 trillion tokens of web and code data.
This meticulous training allows it to rival the performance of significantly larger models like Llama 3.3 70B and Qwen 2.5 72B on the MMLU benchmark, while demanding a fraction of the resources.
Specifically, it requires 4–5x less VRAM and consumes 85% less compute than GPT-4o mini, making it a highly efficient choice for cloud and on-premise deployments.
At the smaller end of the spectrum, the Phi-4-mini (3.8B) model is engineered for on-device execution.
It is capable of running smoothly on machines with just 8GB of RAM and shipped on Windows 12 Copilot+ PCs on July 19th.
Its efficiency is further demonstrated by its ability to run on a Raspberry Pi 5 using only ~3GB of VRAM with Q4 quantization, and it achieves a swift 42 tokens per second on Snapdragon X Elite hardware.
Specialized Capabilities: Reasoning, Vision, and Edge Deployment
Beyond general-purpose performance, the Phi-4 portfolio includes highly specialized variants for advanced workloads.The lightweight Phi-4-mini model empowers new on-device experiences such as fully offline code completion and local image editing, ensuring privacy and responsiveness.
For complex problem-solving, the Phi-4-reasoning variant demonstrates exceptional capabilities, outperforming competitors like OpenAI’s o1-mini and DeepSeek-R1-Distill-Llama-70B on most reasoning benchmarks.
Remarkably, it is even comparable to the full DeepSeek-R1 model (671B parameters) on the AIME 2025 benchmark.
A further enhanced version, Phi-4-reasoning-plus, incorporates reinforcement learning for even greater performance.
The Phi-4-mini-reasoning (3.8B) model, trained on approximately 1 million synthetic math problems generated by DeepSeek R1, is specifically designed for applications like embedded tutoring on lightweight devices.
Released in March 2026, the Phi-4-reasoning-vision-15B model represents the portfolio's multimodal flagship.
It combines a SigLIP-2 vision encoder with the Phi-4-Reasoning backbone and introduces unique features like the ability to toggle between reasoning and non-reasoning modes.
Crucially for enterprise applications, it supports screen grounding—the ability to identify UI elements by their coordinates—making it the best candidate for sophisticated on-premise vision-reasoning workloads.
| Model Variant | Parameters | Key Features & Performance Highlights | Primary Use Case |
|---|---|---|---|
| Phi-4 (Base) | 14B | Rivals Llama 3.3 70B on MMLU; 4-5x less VRAM; 85% less compute than GPT-4o mini; 128K context window. | High-efficiency, general-purpose enterprise tasks in Azure. |
| Phi-4-mini | 3.8B | Runs on 8GB RAM devices; 42 tokens/sec on Snapdragon X Elite; Runs on Raspberry Pi 5 (~3GB VRAM). | On-device AI, offline code completion, local image editing. |
| Phi-4-reasoning | Varies | Outperforms o1-mini; comparable to 671B DeepSeek-R1 on AIME 2025; 'plus' version has RL enhancement. | Advanced, complex reasoning and problem-solving tasks. |
| Phi-4-mini-reasoning | 3.8B | Trained on ~1M synthetic math problems generated by DeepSeek R1. | Embedded tutoring and educational applications on lightweight devices. |
| Phi-4-reasoning-vision | 15B | Combines SigLIP-2 vision encoder; supports screen grounding (UI element identification); toggles reasoning modes. | On-premise, multimodal vision-reasoning workloads. |
7. Aion 1.0: Microsoft's Vision for Unmetered On-Device Intelligence
This section delves into Aion 1.0, the on-device pillar of Microsoft's overarching MAI first-party model strategy. It represents the company's answer to providing powerful, cost-free AI capabilities that run locally, complementing the larger, cloud-based MAI models and completing its end-to-end AI portfolio.Aion's Core Promise: Local and Cost-Free AI
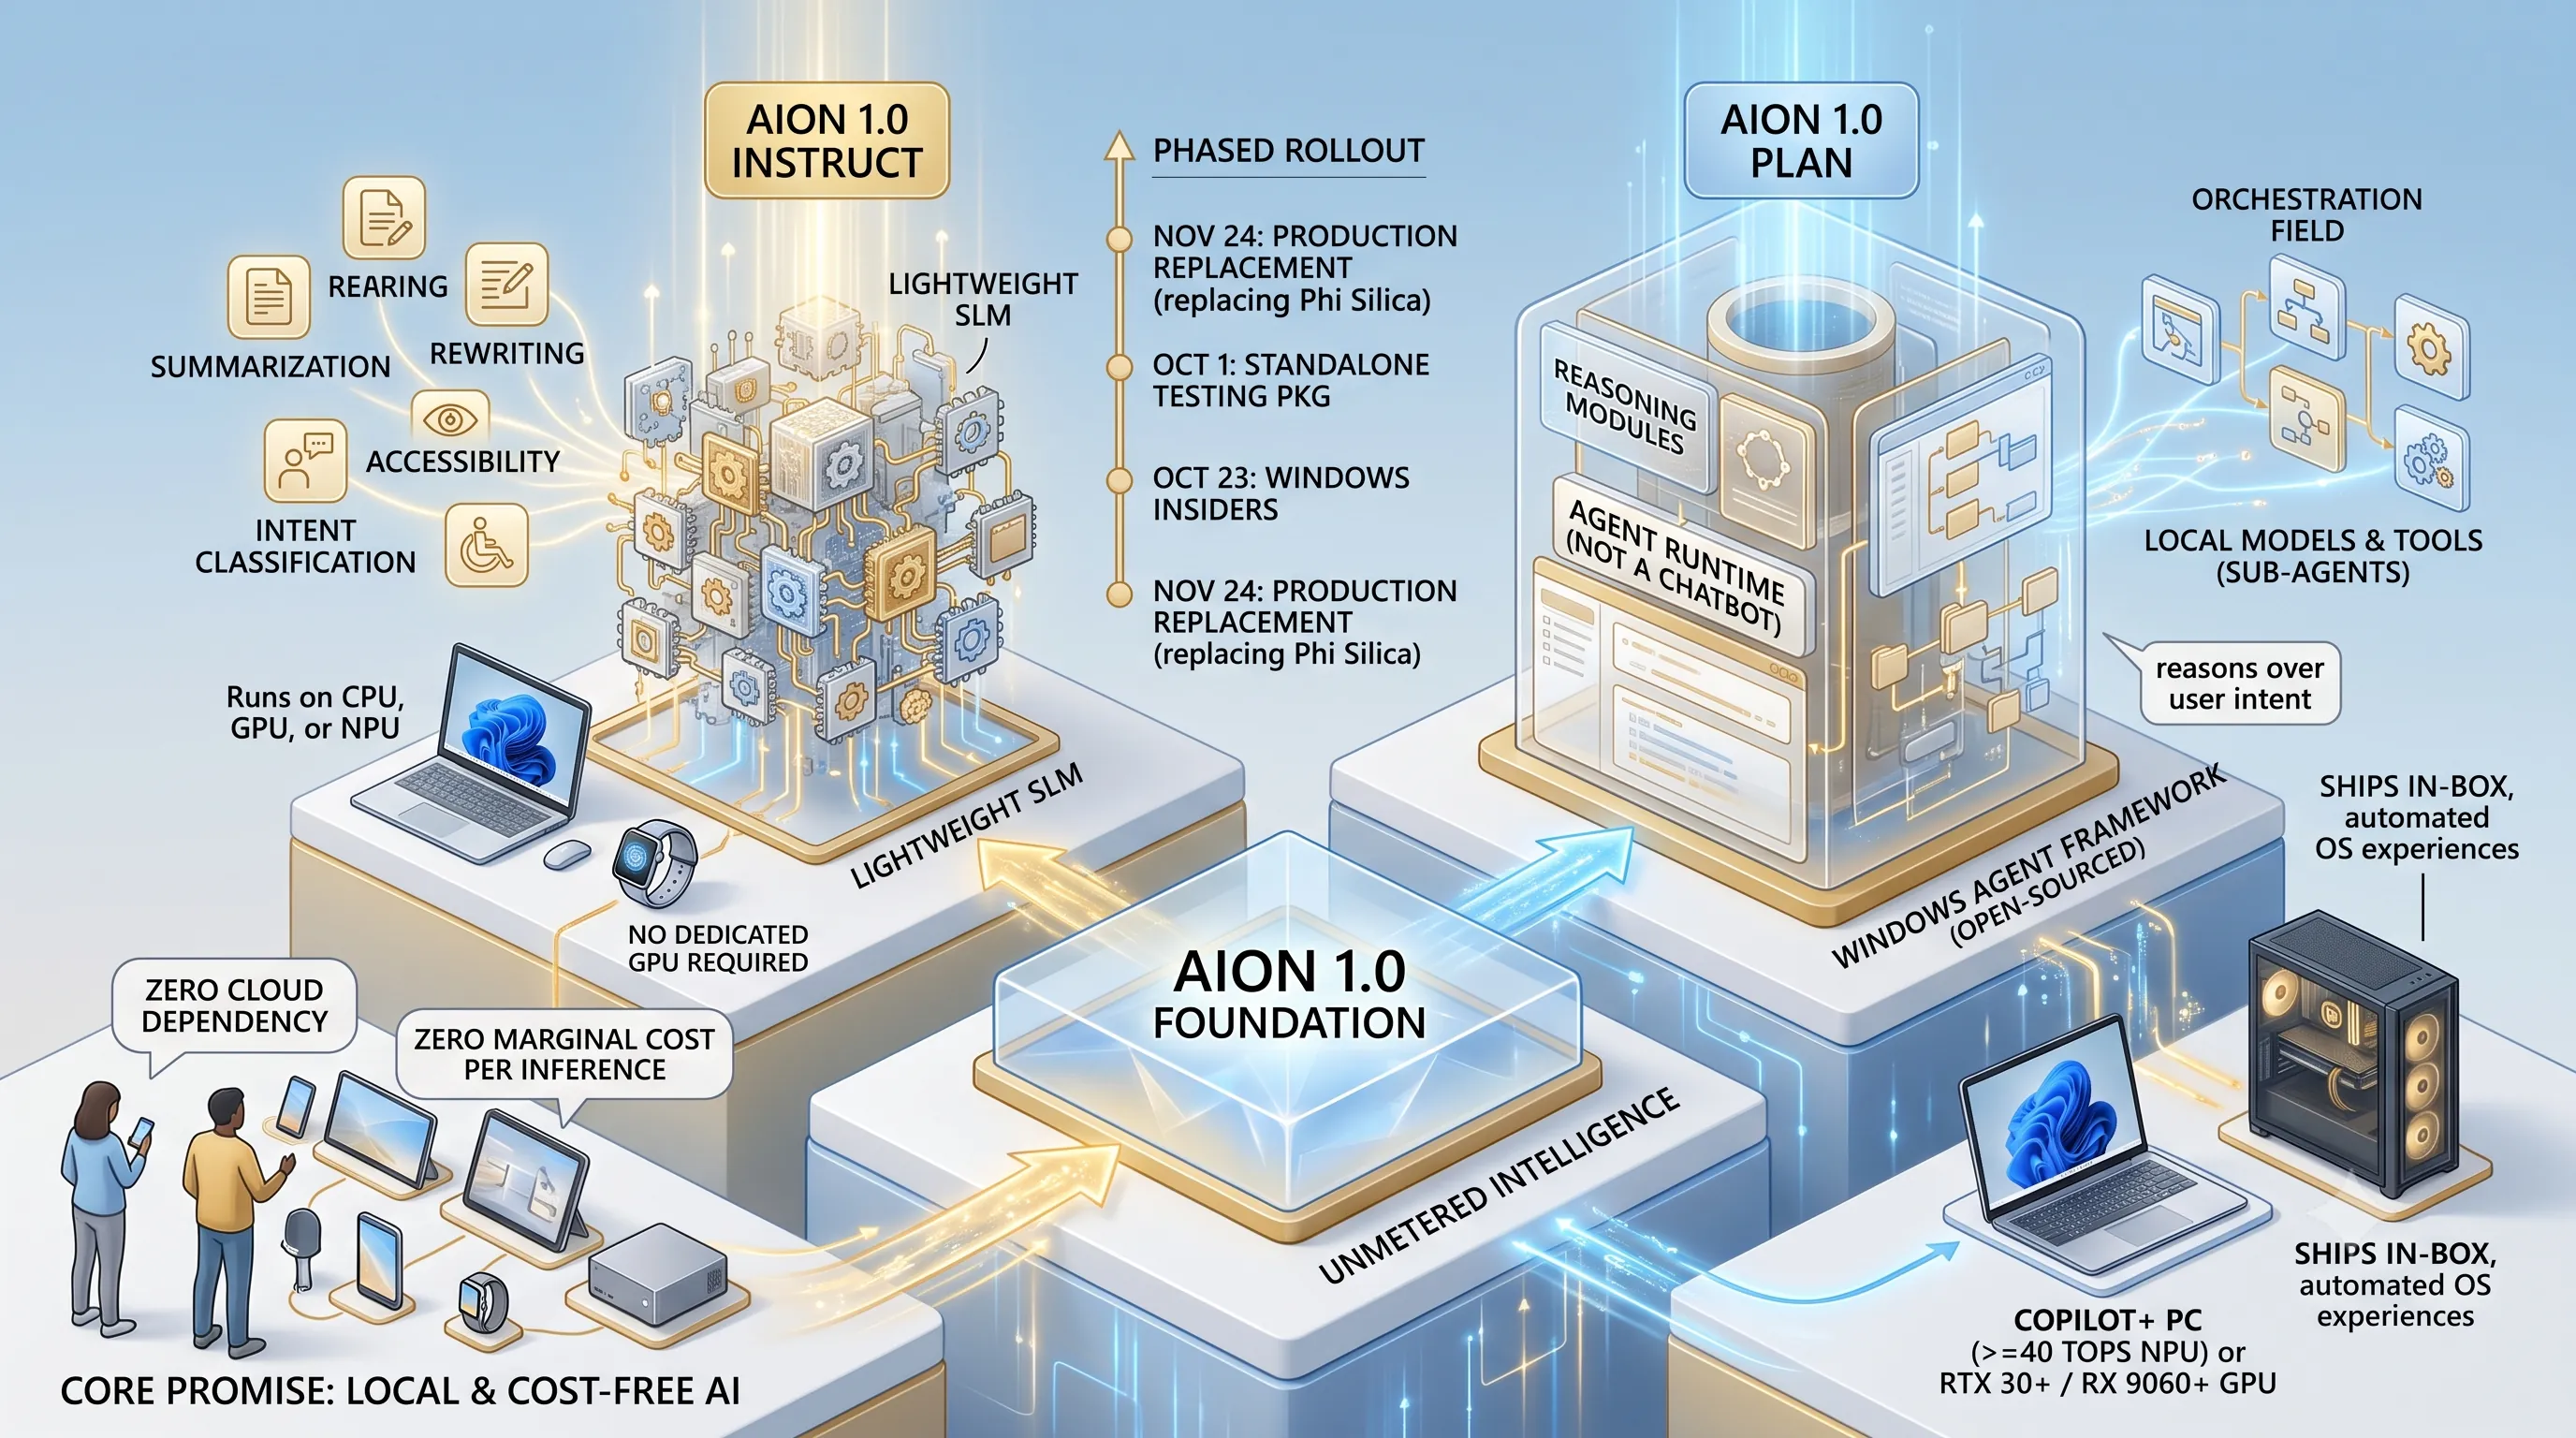
Announced at Build 2026, the Aion family of models is the foundation for what Microsoft calls 'unmetered intelligence'.The core principle is a complete departure from consumption-based AI: Aion is engineered for zero cloud dependency, meaning that once deployed on a user's device, its operations do not require a connection to Microsoft's servers.
This local-first approach directly leads to its most significant business implication: a zero marginal cost per inference.
By eliminating the need for server-side processing for a wide range of tasks, Microsoft can deliver continuous AI value without incurring ongoing computational expenses, a critical component of its strategy to embed AI deeply into the Windows operating system.
Aion 1.0 Instruct: Capabilities and Preview
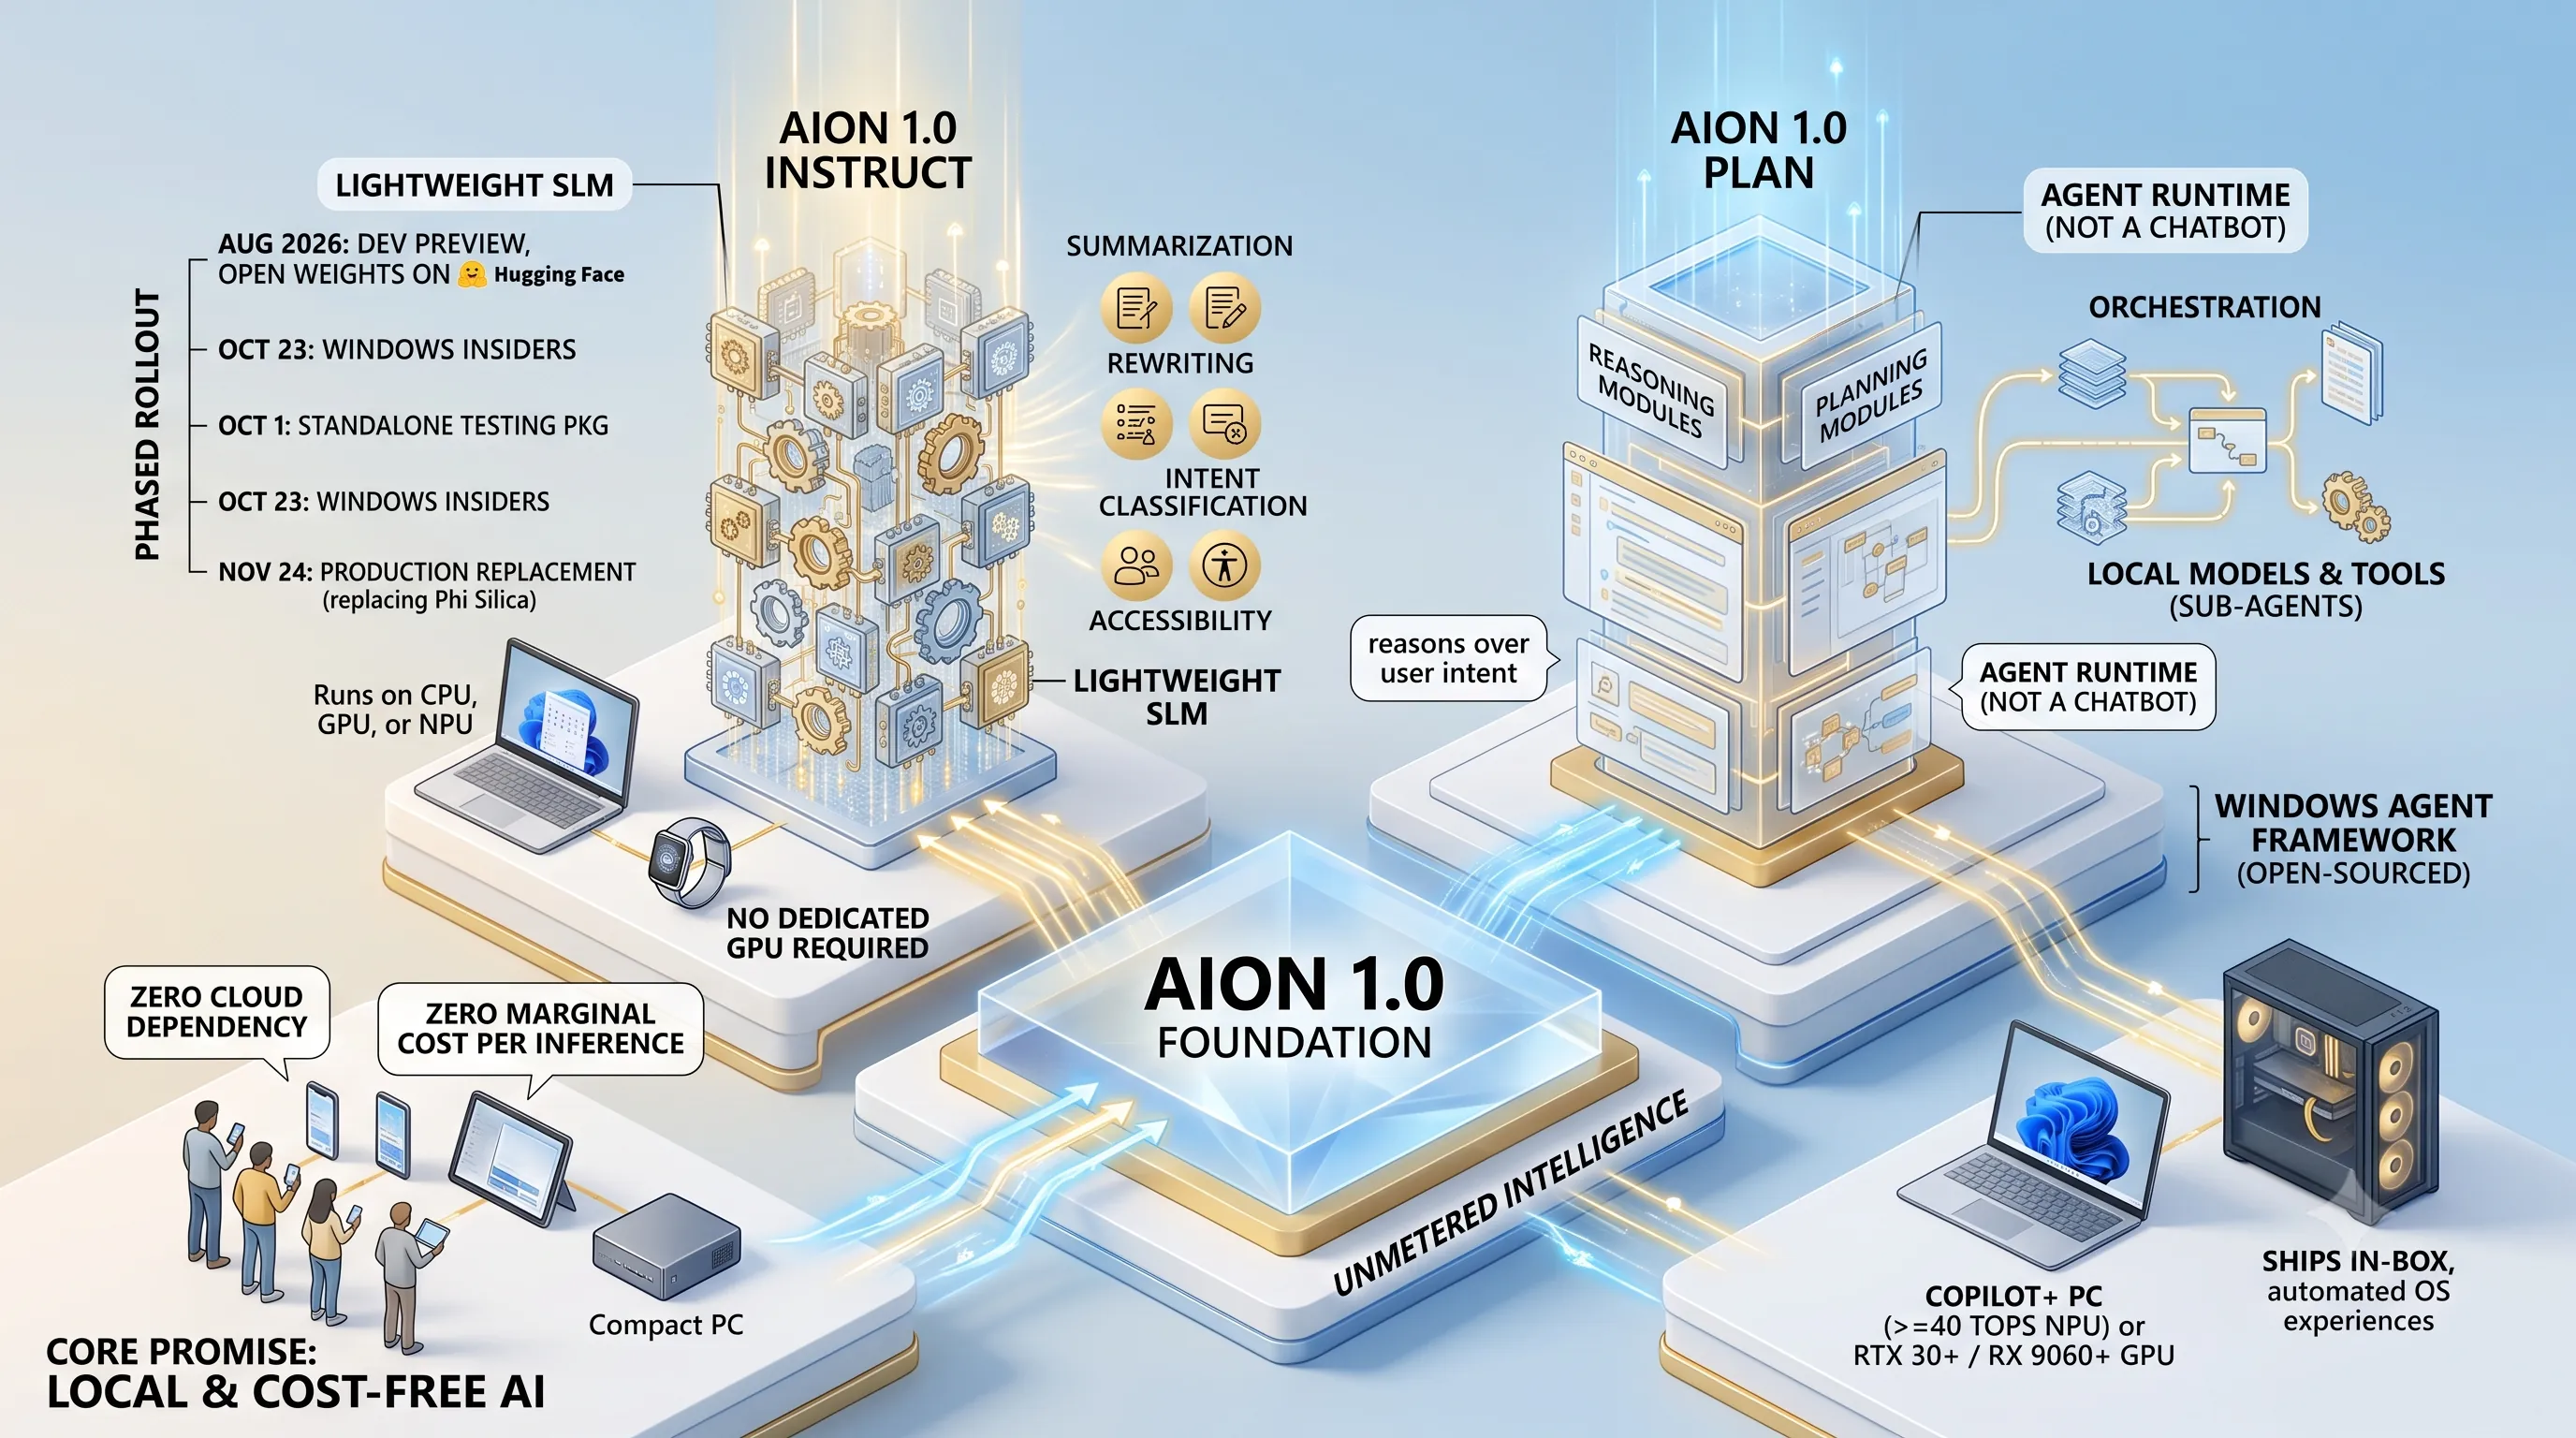
The first component of this vision is Aion 1.0 Instruct, a lightweight Small Language Model (SLM) designed for high-frequency, low-complexity tasks.Its primary functions include text summarization, rewriting, intent classification, and powering accessibility features.
A key design goal for Instruct was broad hardware compatibility; it is optimized to run efficiently on a device's CPU, GPU, or NPU, notably without requiring a dedicated or high-end GPU.
This ensures that its capabilities can be delivered across a vast spectrum of Windows hardware, not just elite-tier devices.
As of early August 2026, Aion 1.0 Instruct is currently available to developers in preview through the Edge Canary and Dev channels for testing and integration.
Aion 1.0 Plan: On-Device Agent Orchestration
While Instruct handles discrete tasks, Aion 1.0 Plan serves a more sophisticated purpose.It is explicitly not a chatbot; instead, it functions as an agent runtime that reasons over a user's intent and orchestrates complex workflows by coordinating other local models and tools, or "sub-agents."
This model is part of the Windows Agent Framework, which Microsoft open-sourced at Build 2026 to encourage ecosystem development.
Aion 1.0 Plan ships in-box on capable Windows devices, enabling a new class of proactive and automated user experiences directly within the OS.
| Feature | Aion 1.0 Instruct | Aion 1.0 Plan |
|---|---|---|
| Model Type | Lightweight SLM | Agent Runtime |
| Parameters | Not Specified | 14 Billion |
| Context Window | Not Specified | 32K |
| Core Function | Summarization, rewriting, accessibility | Reasons over user intent and orchestrates sub-agents |
| Hardware Requirements | Runs on CPU, GPU, or NPU without a dedicated GPU | Copilot+ PC (>=40 TOPS NPU) or NVIDIA RTX 30+ / AMD Radeon RX 9060+ GPU |
Phased Rollout and Future Impact
Microsoft has outlined a clear and rapid deployment schedule for Aion Instruct to replace its predecessor, Phi Silica.Following the current developer preview, the open weights for Aion 1.0 Instruct are expected on Hugging Face this month (August 2026), a significant move to engage the open-source community.
A standalone testing package for developers will be made available on October 1, 2026, followed by a broader rollout to Windows Insiders on October 23, 2026.
The final transition will occur on November 24, 2026, when Aion Instruct will formally replace Phi Silica as the production on-device model across the Windows ecosystem, cementing its role as the workhorse for unmetered intelligence.
8. Florence-2: Stable Vision Foundation and Critical API Migration
As Microsoft consolidates its AI strategy around its first-party MAI portfolio, the Florence-2 model stands out as the definitive foundation for computer vision. It is the core engine powering the Azure AI Vision Image Analysis 4.0 service, representing a significant leap in capability and a strategic shift for developers on the Azure platform.Florence-2: Robust Multi-Task Vision Capabilities
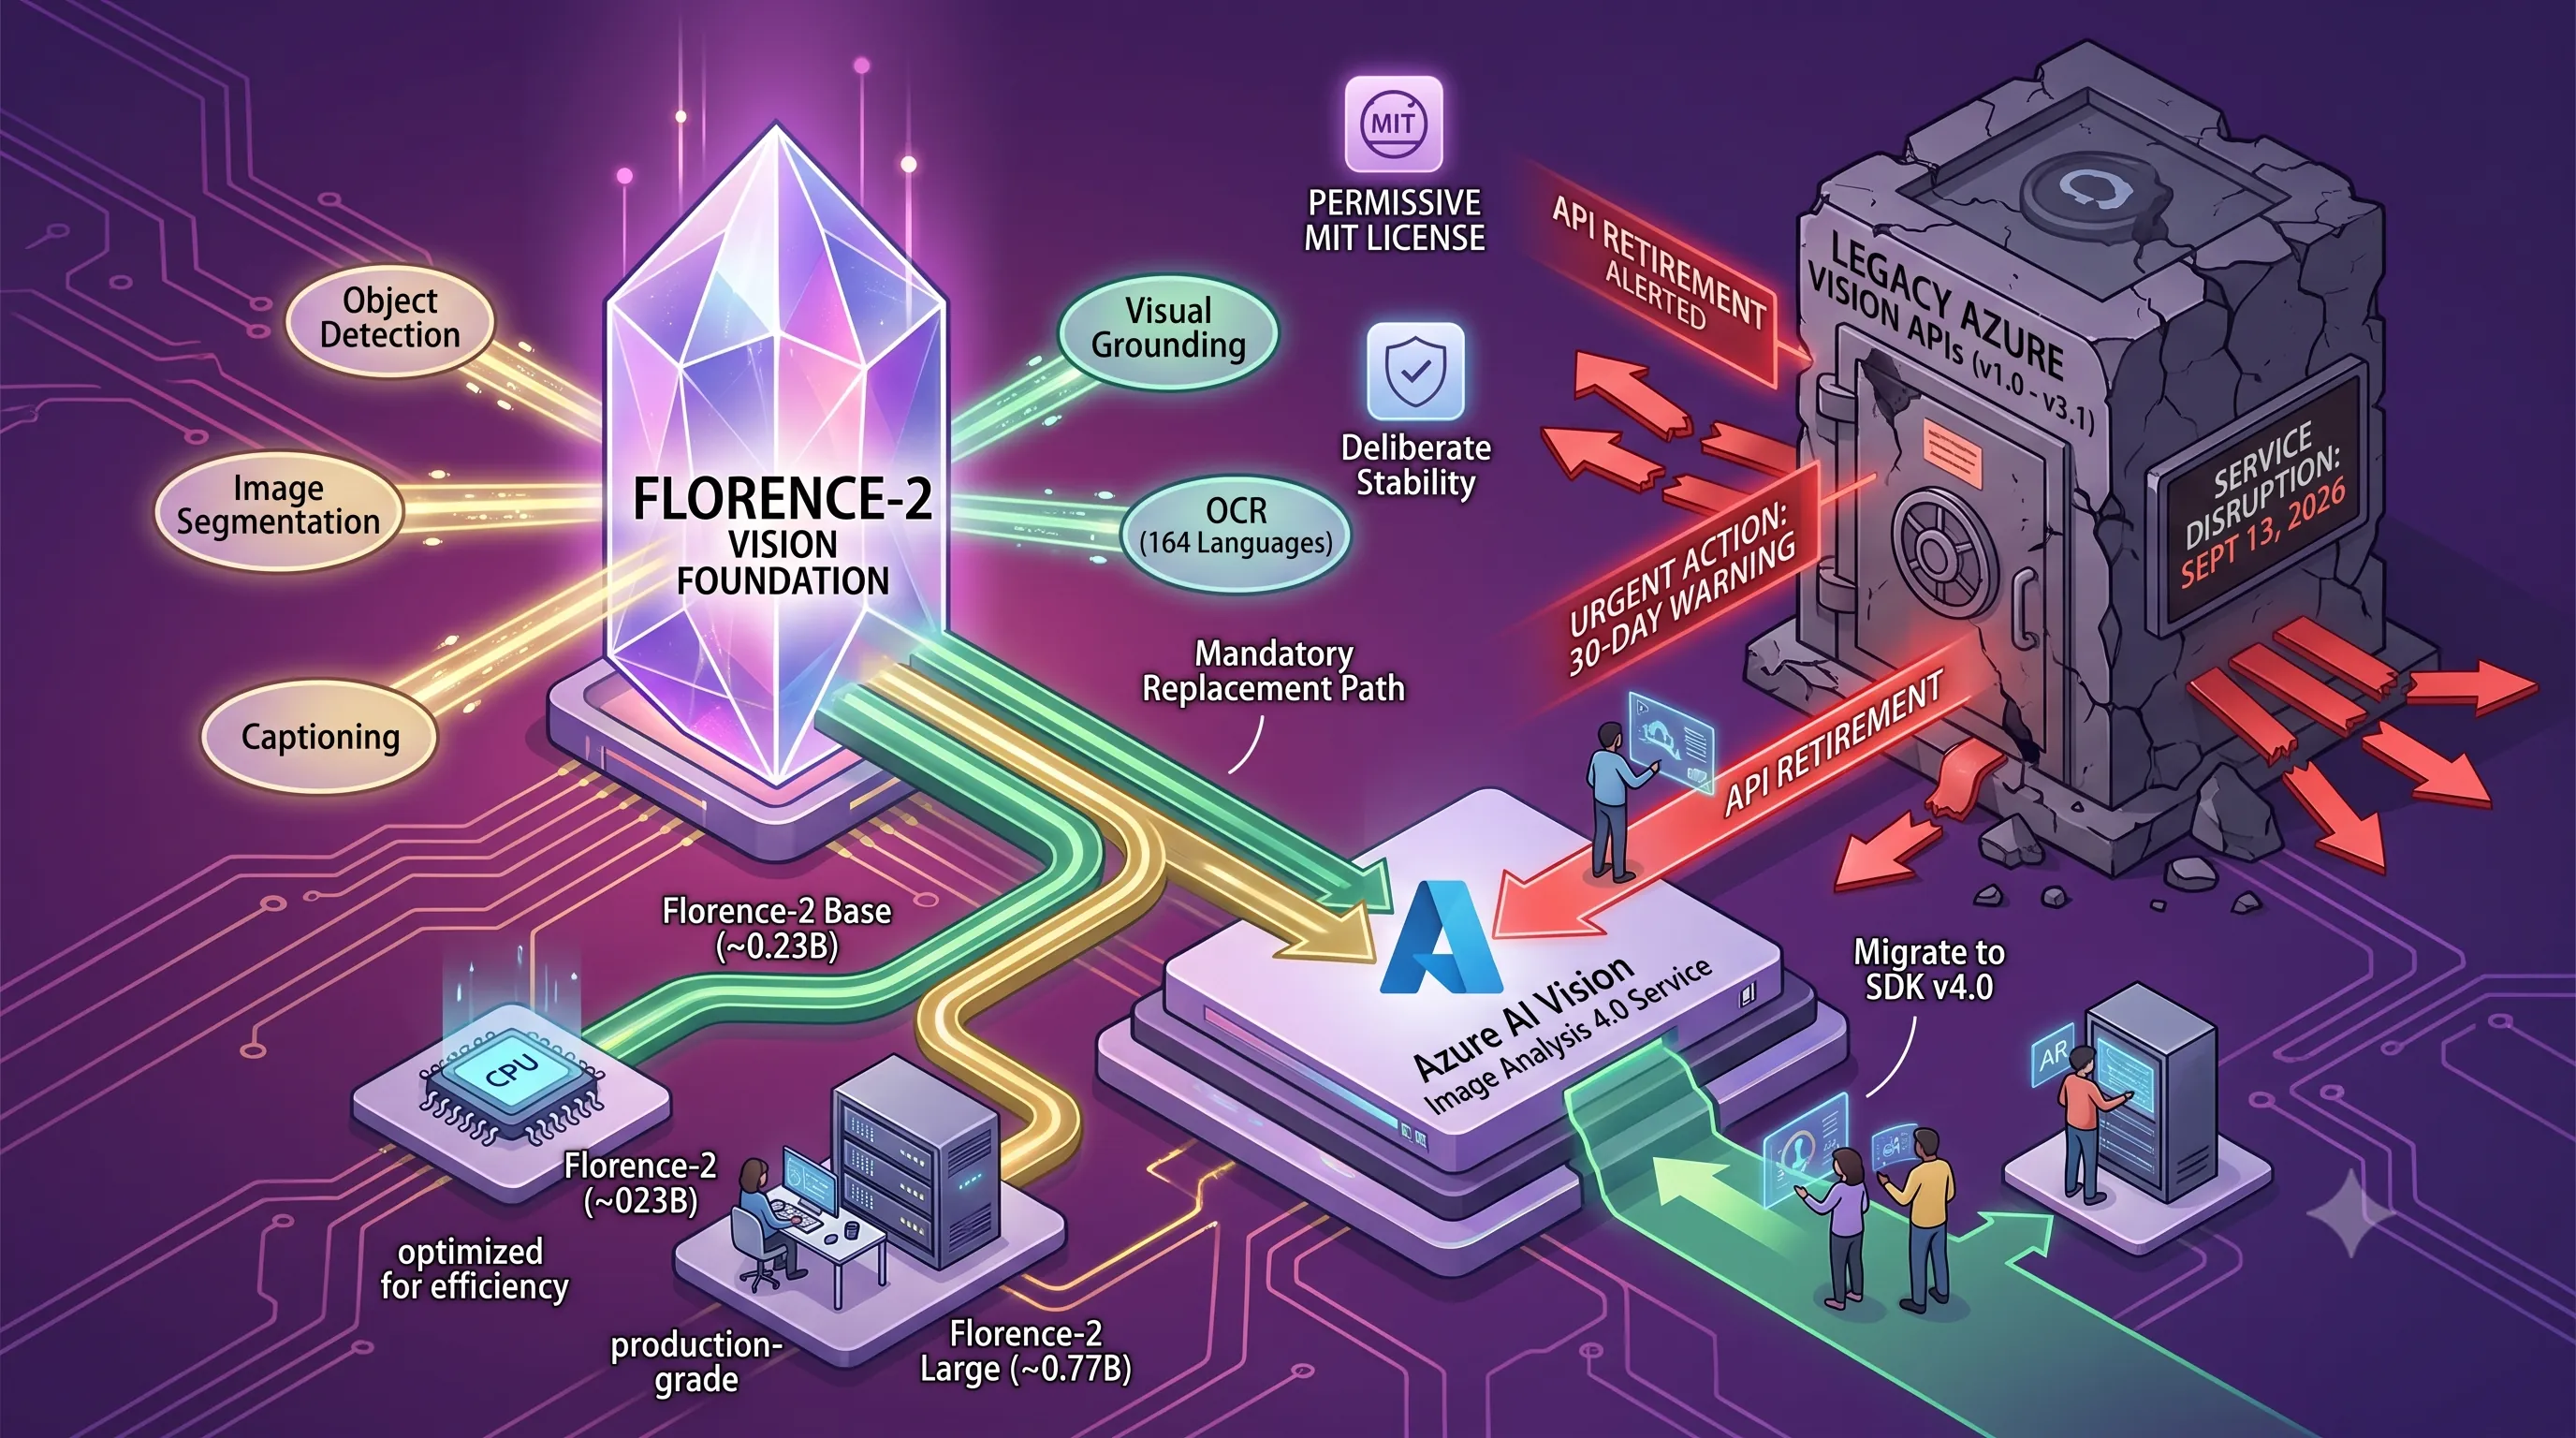
Florence-2 is engineered for versatility, capable of handling more than 12 distinct vision tasks from a single set of weights.This multi-task design streamlines development, allowing a single model to perform complex operations like object detection, image segmentation, captioning, and visual grounding without needing specialized endpoints for each function.
Its capabilities also extend to comprehensive text recognition, with Optical Character Recognition (OCR) support for an impressive 164 languages.
To cater to diverse deployment needs, Microsoft offers two primary variants of the model.
| Variant | Parameters | Key Characteristic |
|---|---|---|
| Florence-2 Base | ~0.23B | Optimized for efficiency and is CPU-deployable. |
| Florence-2 Large | ~0.77B | Production-grade model for maximum performance. |
Strategic Stability and Enterprise Utility
In a market often characterized by rapid, iterative releases, Microsoft's approach with Florence-2 has been one of deliberate stability.The company has prioritized broad enterprise utility over a rushed release cycle, a fact underscored by the continued focus on Florence-2 as the core vision model, with no Florence-3 having been announced.
This strategy provides a reliable and consistent foundation for businesses building long-term vision applications.
Further encouraging widespread adoption and integration, the model is available to the community under a permissive MIT license.
Urgent Action: Migrating from Legacy Azure Vision APIs
This strategic consolidation around Florence-2 necessitates a critical action for all existing Azure Vision users.Microsoft is officially retiring all legacy Azure Vision APIs, specifically versions v1.0 through v3.1, on September 13, 2026.
As of today's date, this serves as a final 30-day warning for developers and organizations.
Continued access to Azure's vision services requires an immediate migration to the Florence-2-based Image Analysis 4.0 SDK.
Failure to migrate before the deadline will result in service disruption.
This transition is the mandatory replacement path, ensuring that all applications benefit from the enhanced accuracy, multi-task capabilities, and long-term stability of the Florence-2 foundation model.
9. Copilot's Dynamic Orchestration: Routing AI for Optimal Performance and Cost
This section explains the sophisticated, multi-model architecture behind Microsoft Copilot, detailing how the new first-party MAI models are integrated into the service not as a replacement, but as a crucial component of a dynamic routing system designed to balance cost and performance. It connects directly to the main topic by showing the practical, large-scale implementation of Microsoft's new AI model strategy within its flagship productivity suite.
Copilot as a Multi-Model Orchestrator
Microsoft 365 Copilot is not a single, monolithic AI model but rather a sophisticated orchestration layer.At its core is an intelligent task categorization layer that classifies each user interaction based on several factors, including the task type, its complexity, and the required quality of the output.
Based on this classification, Copilot dynamically routes interactions to the most suitable model in its diverse portfolio.
This multi-layered approach also extends to local processing, where on-device inference tasks are handled by Phi Silica, a system that is currently transitioning to the next-generation Aion 1.0 model.
Intelligent Routing: Balancing First-Party and Frontier AI
The routing architecture is fundamentally pragmatic, engineered to capture significant cost savings by using first-party models where they are competitive while preserving access to best-in-class capabilities where they matter most.As of July 2026, high-volume commodity tasks were already being routed to Microsoft's first-party MAI models.
Simultaneously, the system ensures that more demanding requests are sent to powerful third-party models. Novel analysis across long unstructured documents, multi-step reasoning with complex dependencies, and creative generation requiring stylistic judgment are still routed to frontier models like GPT-5.6 and Claude.
This dual approach allows Microsoft to reduce its reliance on OpenAI for the bulk of its traffic while retaining cutting-edge performance for high-value tasks.
| Routed to First-Party MAI Models | Routed to Frontier Third-Party Models (e.g., GPT-5.6, Claude) |
|---|---|
| High-volume commodity tasks such as standard email drafting, conversation thread summarization, and spreadsheet formula generation. | Novel analysis across long, unstructured documents. |
| Common developer tasks like coding assistance in VS Code. | Multi-step reasoning involving complex dependencies between tasks. |
| Integrated content creation like image generation in PowerPoint and meeting transcription in Teams. | Creative generation that requires sophisticated stylistic judgment. |
Strategic Transition and Future Outlook
The implementation of this dynamic routing system marks a clear and strategic transition for the Copilot service, progressively shifting workloads to Microsoft's in-house MAI models.This move is aimed at significantly reducing both operational costs and the platform's heavy reliance on OpenAI for the majority of its query volume.
The transition is advancing steadily, with Microsoft providing a clear timeline for this architectural shift.
By the end of 2026, the company expects that most commodity Copilot tasks will run entirely and exclusively on its own MAI models.
10. Turing Model Family: A Concluding Chapter in Microsoft's AI Journey
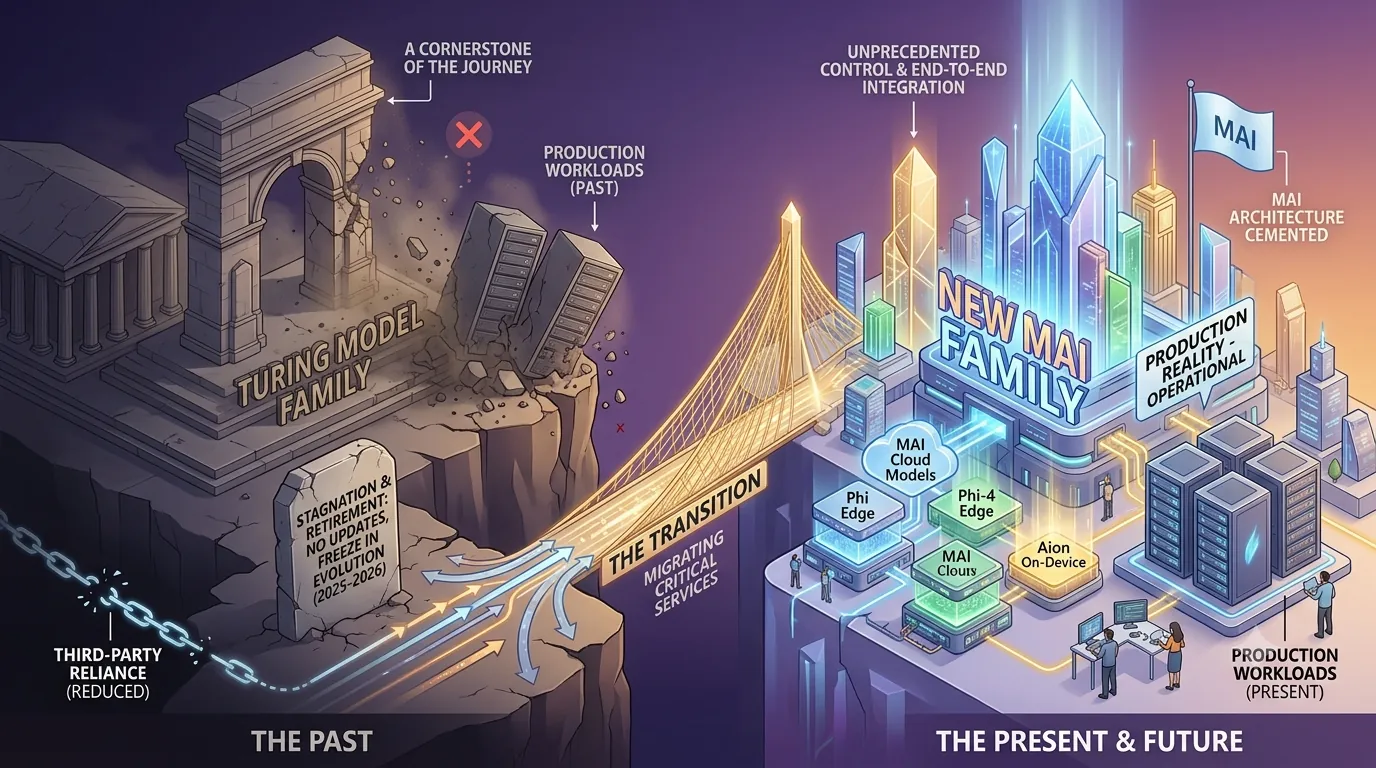
As Microsoft pivots its entire first-party AI strategy toward the new MAI family, the fate of its predecessor, the Turing model family, serves as a clear indicator of this strategic shift.The Turing models, once a cornerstone of Microsoft's AI efforts, have seen their development come to a halt.
Throughout 2025 and the first half of 2026, there were no significant updates or new releases for the Turing model family, signaling a deliberate freeze in its evolution.
This stagnation was not due to a lack of capability but a conscious decision to migrate critical services.
The newer, more efficient MAI family has now officially taken over the production workloads that were once the domain of Turing.
Consequently, the Turing model line is now effectively retired for all new development, marking the end of its chapter in Microsoft's AI journey and cementing the transition to the MAI architecture.
11. Microsoft's Comprehensive AI Portfolio: A Full-Stack Ecosystem
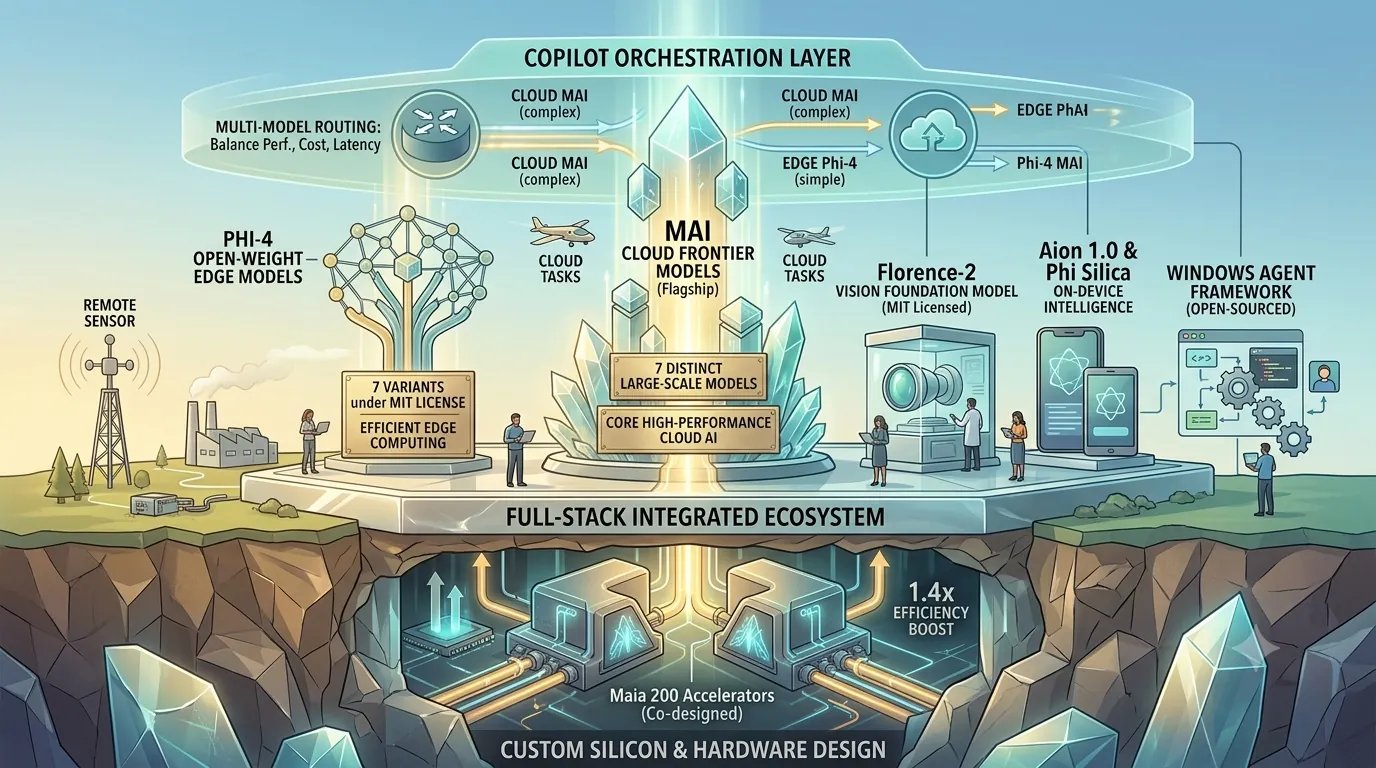
The strategic shift to the first-party MAI models is not an isolated event; it represents the culmination of Microsoft's effort to build a complete, vertically integrated AI stack.This full-stack approach positions Microsoft as one of the only companies, alongside Google and Apple, with a comprehensive AI portfolio that spans from custom silicon to developer frameworks.
The MAI cloud models are the flagship component, but they gain their strategic power from being part of this broader, meticulously designed ecosystem.
From Silicon to Cloud: Maia and MAI
At the very foundation of this ecosystem is custom hardware.Microsoft developed its own Maia 200 accelerators, custom silicon specifically designed to run its AI workloads.
This co-design of hardware and software models yields significant performance gains, providing a reported 1.4x efficiency boost compared to off-the-shelf alternatives.
Sitting atop this optimized hardware in the cloud are the new frontier models, the MAI family.
This family consists of 7 distinct large-scale models that serve as the high-performance core for complex, cloud-based AI tasks, representing the pinnacle of Microsoft's in-house model capabilities.
Edge, On-Device, and Foundational Vision
Microsoft's strategy extends far beyond the data center to devices at the edge.For this, the company developed the Phi-4 family, a versatile set of 7 model variants released under the permissive MIT license.
These open-weight models are designed for efficiency, making them suitable for edge computing scenarios where resources are more constrained.
For intelligence running directly on client hardware, Microsoft offers Aion 1.0 and Phi Silica, specialized components for on-device AI.
The portfolio also includes dedicated models for specific modalities, most notably Florence-2, a powerful vision foundation model, which is also open-sourced under an MIT license to encourage broader adoption and development.
| Component | Ecosystem Layer | Key Characteristic |
|---|---|---|
| Maia 200 | Custom Silicon | Hardware accelerators co-designed for a 1.4x efficiency boost. |
| MAI Family | Cloud Frontier Models | A family of 7 large-scale, first-party models for the cloud. |
| Phi-4 Family | Open-Weight Edge Models | A family of 7 variants under an MIT license for edge applications. |
| Aion 1.0 & Phi Silica | On-Device Intelligence | Solutions for running AI directly on client hardware. |
| Florence-2 | Vision Foundation Model | An open-source (MIT license) model for computer vision. |
| Copilot | Orchestration | Intelligently routes tasks to the most suitable model in the ecosystem. |
| Windows Agent Framework | Agent Framework | An open-sourced framework for building AI agents. |
Orchestration and Open Frameworks
Having a diverse set of models requires a sophisticated control plane to manage them effectively.This is the role of Copilot, which functions as an orchestration layer.
It provides multi-model routing, intelligently directing user prompts and tasks to the most appropriate model—whether a large MAI model in the cloud or a smaller Phi-4 model on the edge—to balance performance, cost, and latency.
Finally, to empower developers to build on top of this entire stack, Microsoft has open-sourced the Windows Agent Framework.
This gives the developer community the tools to create sophisticated AI agents that can leverage the full power of Microsoft's integrated hardware and software ecosystem.
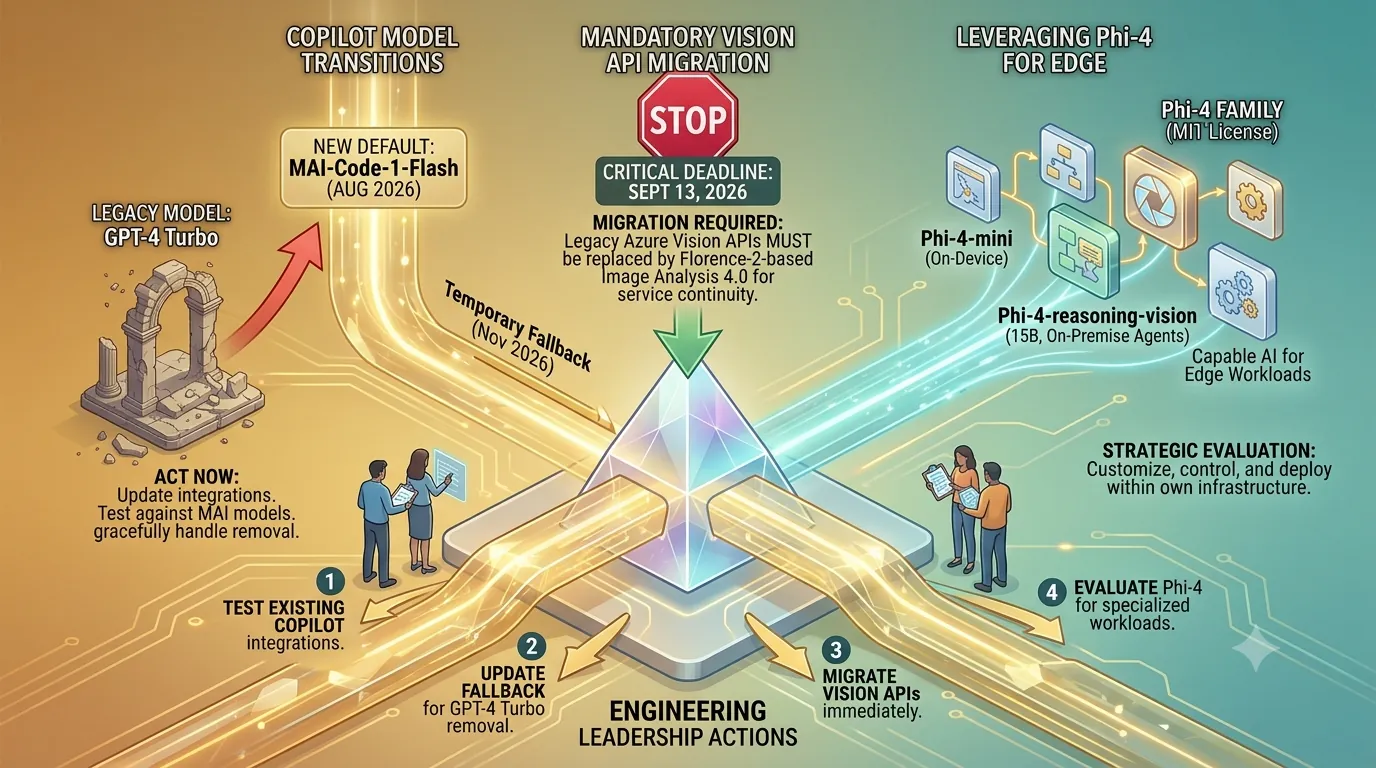
12. Actionable Takeaways for Engineering Leaders in Microsoft's AI Ecosystem
Navigating Copilot Model Transitions
With Microsoft's new MAI models moving to center stage, engineering leaders must take immediate action to ensure their Copilot integrations remain robust and performant.The transition is already underway, as MAI-Code-1-Flash is becoming the default model for Copilot this month, August 2026.
This necessitates a formal migration plan for any team leveraging Copilot.
A critical first step is to begin testing all existing Copilot integrations against the new MAI models immediately to identify any shifts in performance, accuracy, or behavior.
While this transition progresses, Microsoft is providing a temporary safety net: the GPT-4 Turbo fallback for Copilot remains available through November 2026.
However, leaders must update their fallback strategies now to prepare for when this window closes, ensuring systems can gracefully handle the eventual removal of the GPT-4 Turbo option.
Mandatory Migration for Azure Vision APIs
A non-negotiable deadline is rapidly approaching for teams using Microsoft's vision services.All applications and workflows relying on the legacy Azure Vision APIs must be migrated before September 13, 2026.
This is not an optional upgrade; it is a required transition to maintain service continuity.
The designated replacement path is the modern, Florence-2-based Image Analysis 4.0 service.
This migration aligns with Microsoft's broader strategy of consolidating its AI services onto its more powerful, first-party foundation models.
Leveraging Phi-4 for Edge and On-Premise Solutions
Beyond mandatory cloud service updates, engineering leaders should strategically evaluate Microsoft's Phi-4 family of models for new opportunities, particularly for edge and on-premise workloads.Phi-4's permissive MIT license and the breadth of its variant lineup make it a strong option for organizations that require capable AI models they can fully control and deploy in their own environments.
This allows for customization and integration without the restrictions of managed API-based services.
For teams focused on sophisticated on-premise tasks, the Phi-4-reasoning-vision variant, with its 15B parameters, is particularly compelling.
Its capabilities make it an ideal candidate for building powerful vision-reasoning agent workloads that can run entirely within an organization's own infrastructure.
Related Posts
AI Coding Agents: August 2026 Guide to Models, Benchmarks, Policy & PricingExplore the August 2026 AI coding agent landscape. Get insights on new models like GPT-5.6 & Claude...
Analysis of Illicit Industrial-Scale Model Distillation and Chain-of-Thought Extraction CampaignsA technical report on illicit industrial-scale distillation campaigns targeting Claude, detailing...
A Guide to Building Sovereign AI Infrastructure with Mistral Self-Hosted StacksLearn how to build sovereign, air-gapped AI infrastructure using Mistral's self-hosted enterprise...