
Agentic Coding: The Plan-and-Execute AI Agent Framework for Robust Software Development
🚀 Key Takeaways
- August 2026 marks a significant turning point in the AI industry, with agentic systems becoming critical infrastructure.
- The era of simple prompts is over, replaced by advanced multi-agent orchestration for complex workflows.
- Agentic coding allows AI agents to autonomously write, test, debug, and iterate on code with minimal human input.
- The Plan-and-Execute framework is vital for AI agents to reliably solve complex problems by separating strategic reasoning from task execution.
- This framework enables agents to create a multi-step roadmap and process tasks systematically, maintaining long-horizon coherence.
- Modern coding agents emphasize planning before code generation to achieve more robust and cleaner results.
- New specialized and open-weight models are delivering frontier agentic performance, even on consumer hardware.
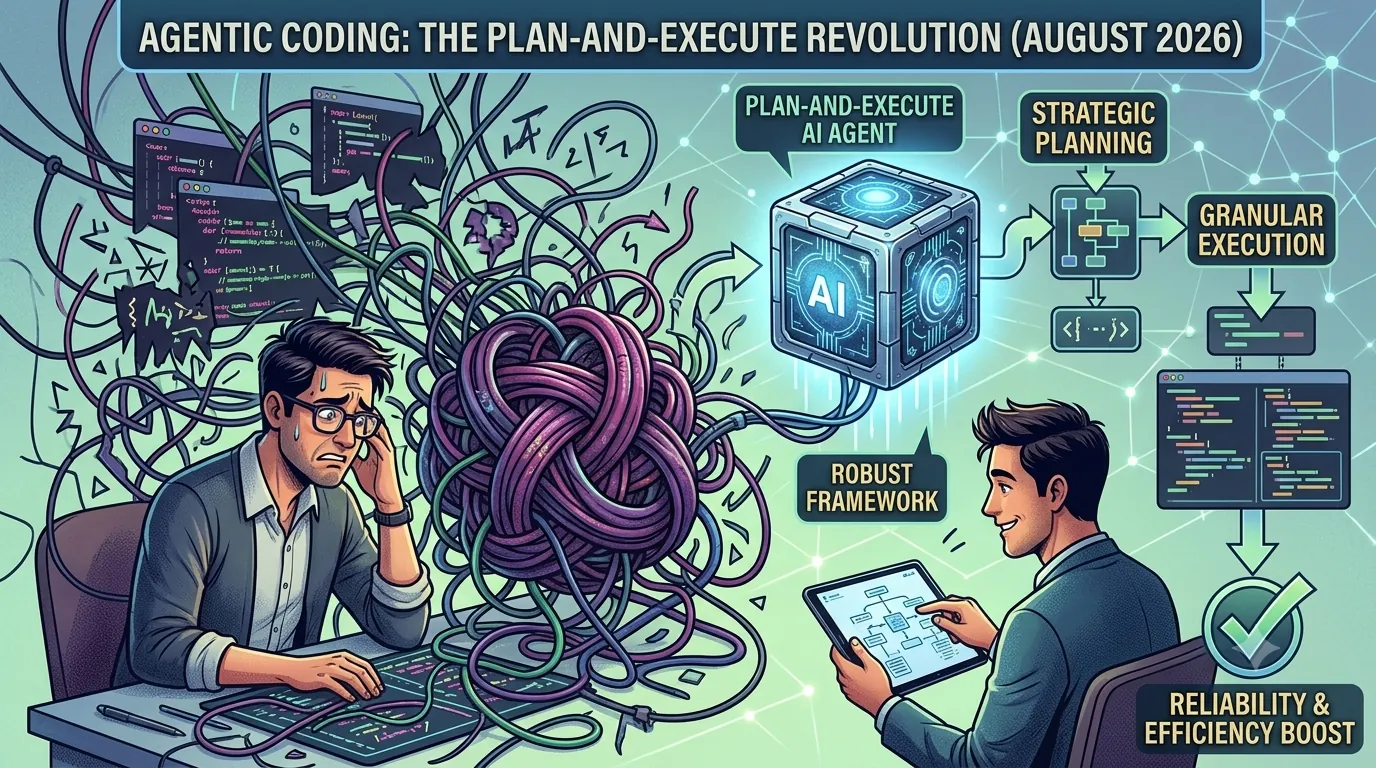
Navigating complex codebases and fixing stubborn bugs can often feel like untangling a Gordian knot, leading to frustration and tangled code.
For developers who have faced these intricate challenges, the advent of agentic coding marks a transformative shift in how software is built and maintained.
August 2026 has emerged as a pivotal moment, accelerating the transition from simple AI prompts to sophisticated, autonomous systems capable of tackling substantial development tasks.
Central to this revolution is the Plan-and-Execute AI agent framework, a robust methodology designed to bring unprecedented reliability and coherence to automated coding workflows.
By explicitly separating high-level strategic planning from the granular execution of tasks, agents can systematically approach complex problems without losing sight of the overall objective.
This structured routine not only mitigates the risk of introducing new issues during critical operations like bug fixes but also significantly boosts the efficiency and stability of AI-driven development.
As open-source models match proprietary performance and specialized agents become standard, understanding and implementing such advanced frameworks is no longer optional.
The Plan-and-Execute paradigm represents the cutting edge, empowering developers to leverage AI for more ambitious projects and ensure cleaner, more reliable code outcomes.
For developers who have faced these intricate challenges, the advent of agentic coding marks a transformative shift in how software is built and maintained.
August 2026 has emerged as a pivotal moment, accelerating the transition from simple AI prompts to sophisticated, autonomous systems capable of tackling substantial development tasks.
Central to this revolution is the Plan-and-Execute AI agent framework, a robust methodology designed to bring unprecedented reliability and coherence to automated coding workflows.
By explicitly separating high-level strategic planning from the granular execution of tasks, agents can systematically approach complex problems without losing sight of the overall objective.
This structured routine not only mitigates the risk of introducing new issues during critical operations like bug fixes but also significantly boosts the efficiency and stability of AI-driven development.
As open-source models match proprietary performance and specialized agents become standard, understanding and implementing such advanced frameworks is no longer optional.
The Plan-and-Execute paradigm represents the cutting edge, empowering developers to leverage AI for more ambitious projects and ensure cleaner, more reliable code outcomes.
1. What is Agentic Coding? A New Paradigm for Software Development
This section defines the core concept of agentic coding, which provides the foundation for understanding the ‘Plan-Execute’ routine discussed in this article.Unlike traditional AI tools that merely assist developers, agentic systems fundamentally change the development workflow by taking on autonomous roles.
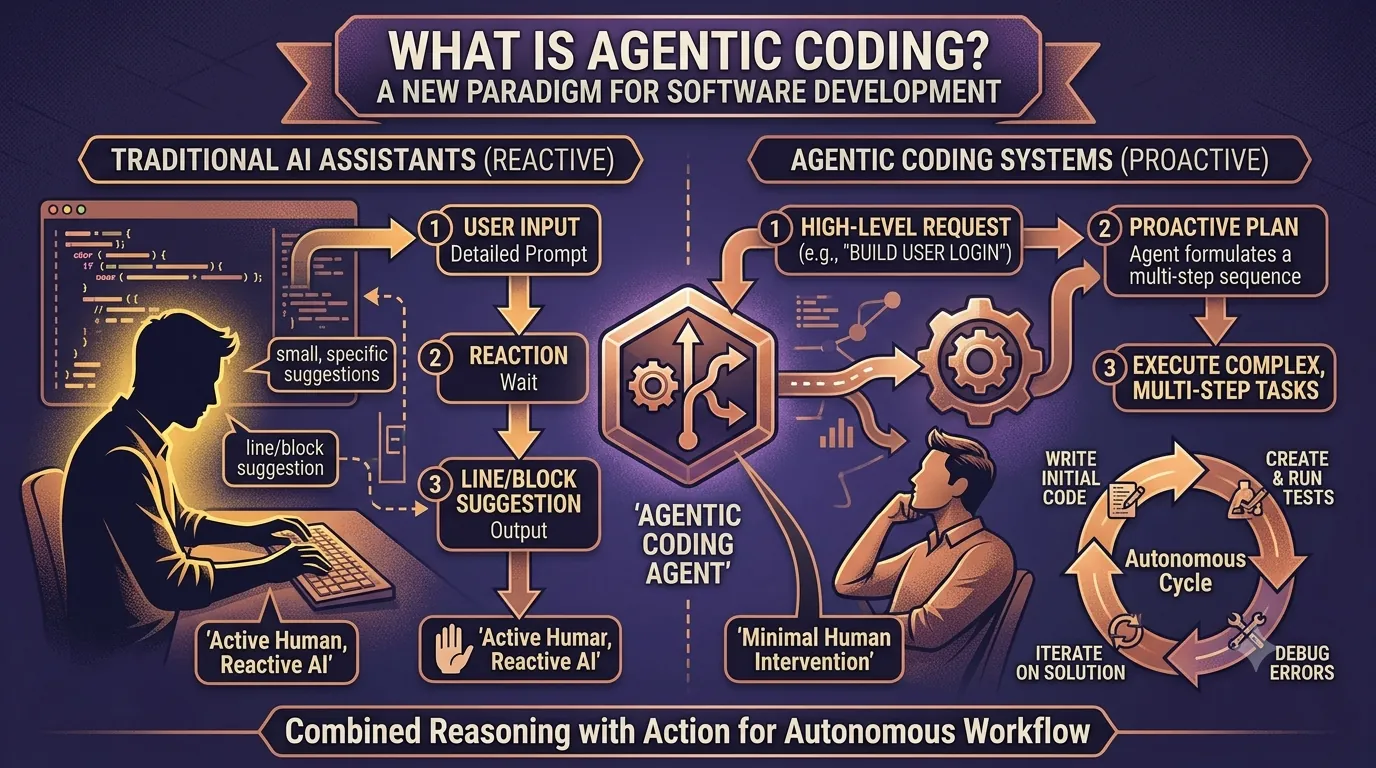
Agentic coding represents a new paradigm in software development where AI agents operate with a high degree of autonomy.
It is a development approach where an AI agent can independently plan and execute complex, multi-step coding tasks.
This includes the entire development cycle: writing the initial code, creating and running tests, debugging errors, and iterating on the solution to meet the requirements, all with minimal human intervention.
The core of this capability lies in coding agents being AI systems that are designed to combine reasoning with action.
This approach marks a significant evolution from traditional AI coding assistants.
While earlier tools were reactive and awaited specific user input to suggest a line or block of code, agentic coding tools are proactive.
They are designed to take a high-level request from a developer—such as "build a user login feature"—and then formulate and execute a complete plan to achieve that goal on their own.
2. AI Agents: From Experiment to Essential Production Infrastructure
This section provides the essential backdrop for understanding why sophisticated agentic patterns like the 'Plan-Execute' routine have become central to modern software development.The reliability issues discussed in this article—such as a simple bug fix spiraling into tangled code—are precisely what drove the industry's shift away from simplistic, single-shot AI commands.
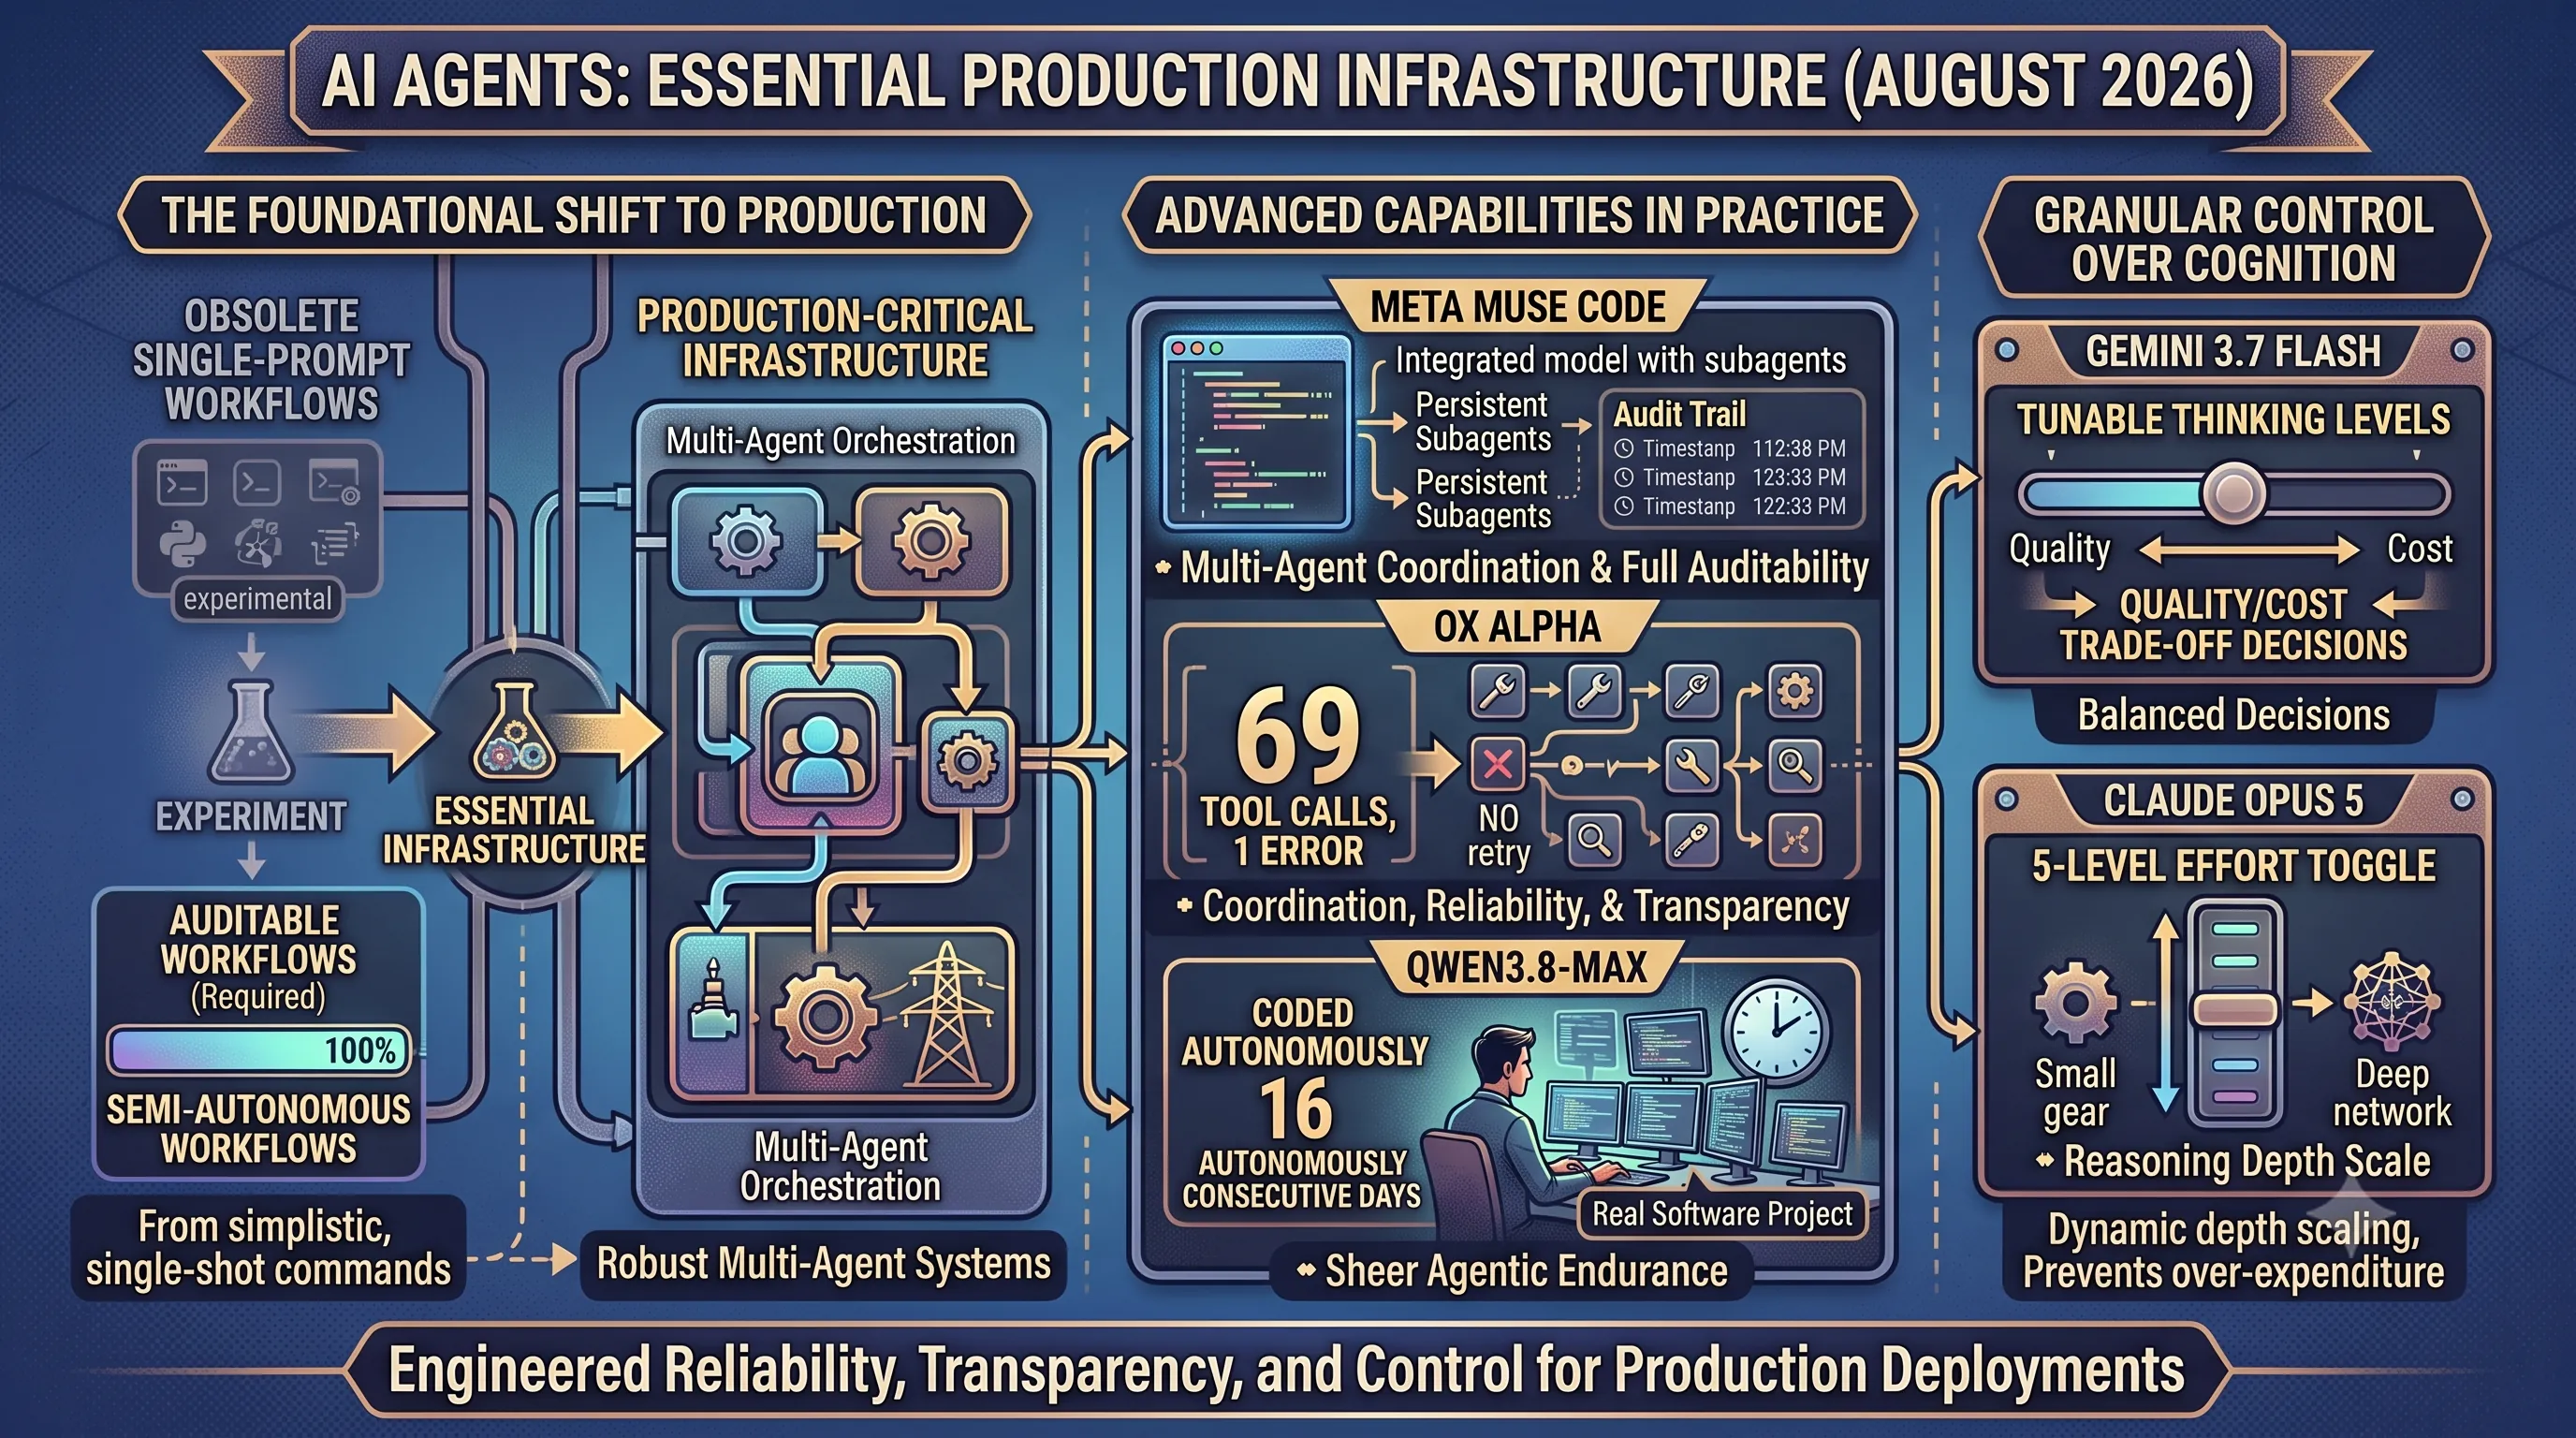
By August 2026, AI agents are no longer experimental novelties; they have matured into mission-critical production infrastructure, making structured, auditable workflows not just a good idea, but a requirement for success.
The Foundational Shift to Production Systems
The era of reliance on single-prompt workflows is now effectively obsolete.The industry has decisively moved from this simple interaction model to deploying autonomous multi-agent systems, a shift validated by agent deployments consistently showing a stronger return on investment than their single-prompt predecessors.
This marks the official transition of multi-agent orchestration from an experimental concept to production-critical infrastructure.
AI agents are now treated as a core component of the production stack, engineered to orchestrate complex, end-to-end workflows on a semi-autonomous basis.
Advanced Capabilities in Practice
The new standard for agentic systems is defined by robust coordination, reliability, and full transparency.Meta's Muse Code platform, for example, is a prime illustration of this, as it features sophisticated multi-agent coordination supported by persistent subagents that maintain context across long-running tasks.
Critically for any production system, it also provides full auditability, ensuring that every step in a complex process can be reviewed.
Reliability has also seen major improvements, as demonstrated by the OX Alpha system, which performed 69 tool calls in a single workflow with only one error and no getting stuck in retry loops.
Highlighting the sheer endurance of modern agents, the Qwen3.8-Max model successfully coded autonomously for 16 consecutive days on a live software project.
| Model / System | Noteworthy Capability or Documented Achievement |
|---|---|
| Meta Muse Code | Multi-agent coordination with persistent subagents and full auditability. |
| OX Alpha | Executed 69 tool calls in a workflow with only one error and no retry loops. |
| Qwen3.8-Max | Coded autonomously for 16 consecutive days on a real software project. |
| Gemini 3.7 Flash | Provides tunable thinking levels for balancing quality and cost. |
| Claude Opus 5 | Features a 5-level effort toggle for adjusting reasoning depth dynamically. |
Granular Control Over Agent Cognition
Beyond raw power, the latest generation of models provides the granular control necessary for stable production deployments.Engineers now have direct levers to manage the trade-offs between cognitive effort, cost, and output quality.
Google’s Gemini 3.7 Flash, for instance, offers tunable thinking levels, allowing teams to make conscious, calculated decisions on the quality/cost ratio for different tasks.
Similarly, Anthropic's Claude Opus 5 features a 5-level effort toggle, which provides a straightforward way to dynamically scale the model's reasoning depth to match a problem's complexity, preventing over-expenditure on simple jobs and ensuring deep thought on complex ones.
3. Mastering Complexity: The Plan-and-Execute AI Agent Framework
The Plan-and-Execute framework provides a structured and reliable method for AI agents to solve complex problems, directly addressing the chaos that can arise from single-pass, monolithic models.Its core principle is the decoupling of high-level strategic reasoning from the low-level execution of individual tasks.
This fundamental separation allows an autonomous system to handle intricate, multi-step requests without losing track of its primary objective, a common failure point in less structured agent designs.
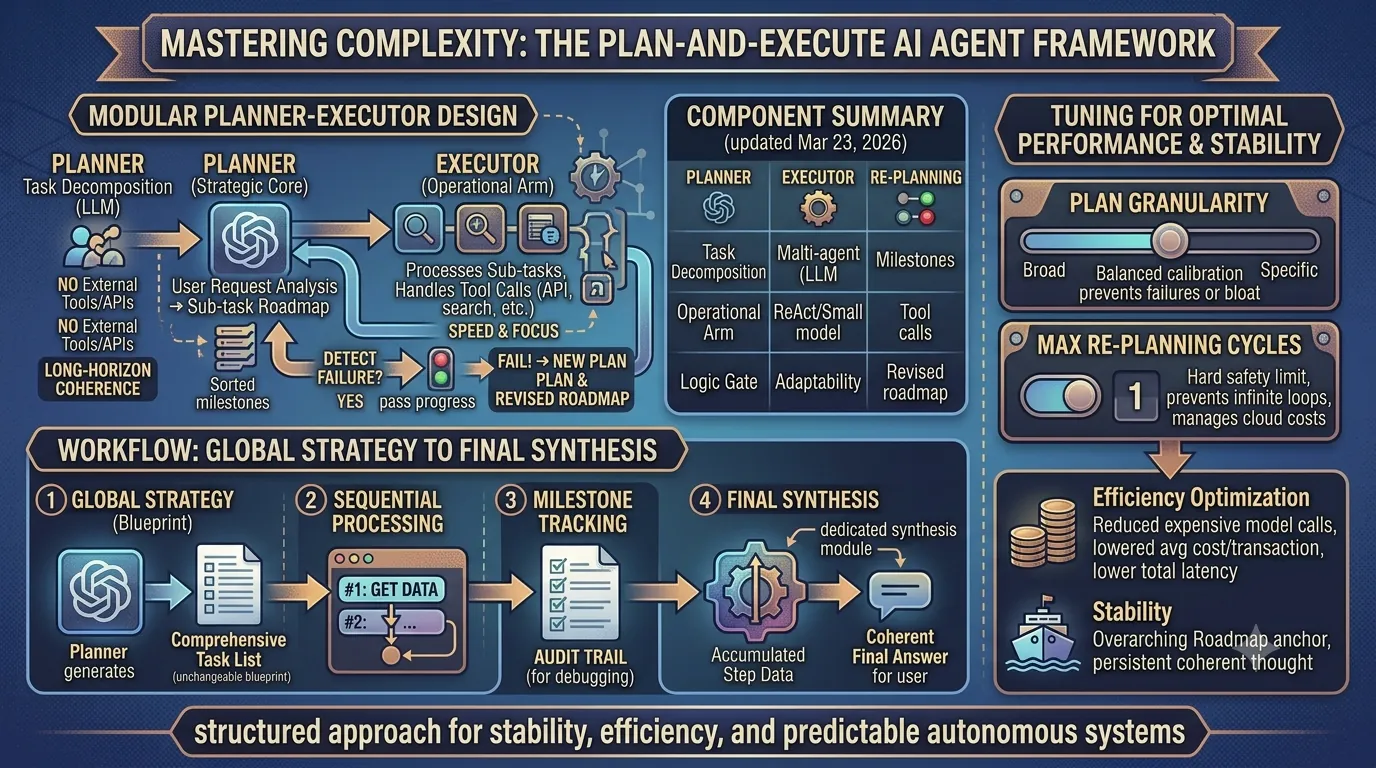
The framework, which received an update on March 23, 2026, begins by generating a complete multi-step roadmap before any action is taken, ensuring long-horizon coherence as the agent systematically processes each sub-task.
By creating this upfront plan, it significantly reduces the cognitive load during the action phase, making it a preferred pattern for developers and technical product managers building more stable and predictable autonomous systems.
Modular Planner-Executor Design Explained
The technical architecture of the framework employs a Modular Planner-Executor design, which divides responsibilities across specialized components to enhance focus and efficiency.This design is a clear upgrade over single-pass models that attempt to generate a solution to a complex prompt in one continuous, often fragile, process.
| Component | Primary Role | Key Characteristics |
|---|---|---|
| Planner | Strategic Core | Utilizes a high-reasoning Large Language Model (LLM) to analyze the user request and perform Task Decomposition, creating a sorted list of milestones. It focuses entirely on the logical sequence and does not interact with external tools or APIs. |
| Executor | Operational Arm | Processes individual steps outlined by the Planner. It is often built with a smaller, faster model or a focused ReAct (Reasoning and Action) agent and operates with a narrow context window for speed. It handles all specific tool calls, like querying databases or searching the web. |
| Re-Planning Unit | Conditional Logic Gate | Monitors the Executor's output for failures or unexpected environmental states. If an issue is detected, it triggers a new planning phase by passing current progress back to the Planner to generate a revised roadmap, ensuring adaptability. |
Workflow: From Global Strategy to Final Synthesis
To transform a complex prompt into a finished result, the system follows a strict operational sequence that ensures clarity and control at every stage.The process begins with the Global Strategy phase, where the Planner analyzes the initial request to formulate a comprehensive task list, evaluating dependencies and identifying necessary tools.
This output serves as the unchangeable blueprint for the entire operation.
Next, Sequential Processing begins as the Executor takes the first sub-task from the list.
By focusing on one step at a time, this method prevents the model from being overwhelmed by unrelated context from other parts of the problem.
As the workflow progresses, Milestone Tracking logs the success of each completed step, updating the global state of the application.
This creates a valuable audit trail for developers to debug or review the agent's decision-making process.
After the Executor has successfully completed all sub-tasks in the plan, a dedicated Final Synthesis module aggregates the accumulated data from each step into a single, coherent final answer for the user.
Tuning for Optimal Performance and Stability
Engineers must tune specific variables to balance the framework's performance and cost-effectiveness.One critical parameter is Plan Granularity, which dictates the level of detail in the sub-tasks generated by the Planner.
This requires careful calibration; overly broad plans can lead to execution failures, while overly specific plans can cause token bloat and increased latency.
Another crucial safeguard is setting the Max Re-Planning Cycles.
This acts as a hard safety limit, restricting the number of times the agent can adjust a failing strategy, which is essential for preventing infinite loops and managing cloud infrastructure costs.
When tuned correctly, the operational impact is significant, yielding measurable benefits for enterprise software teams.
Efficiency Optimization is achieved by reducing calls to heavy, expensive models, as repetitive or simple work is delegated to cheaper, faster executor models, lowering the average cost per transaction and decreasing total latency.
Most importantly, the framework enhances Stability by solving the problem of traditional agents losing coherent thought over long durations; the overarching roadmap serves as a persistent anchor for the system, ensuring it stays on track from start to finish.
4. Practical Agentic Coding: Cursor's Best Practices
This section directly addresses the central theme of separating planning from execution to prevent code entanglement.While the main article establishes the 'why,' this section provides the 'how,' using the agentic coding environment Cursor as a concrete example.
We will explore specific features and workflows that empower developers to guide, customize, and verify the work of coding agents, transforming them from unpredictable tools into reliable collaborators.
Planning Before Coding with Plan Mode
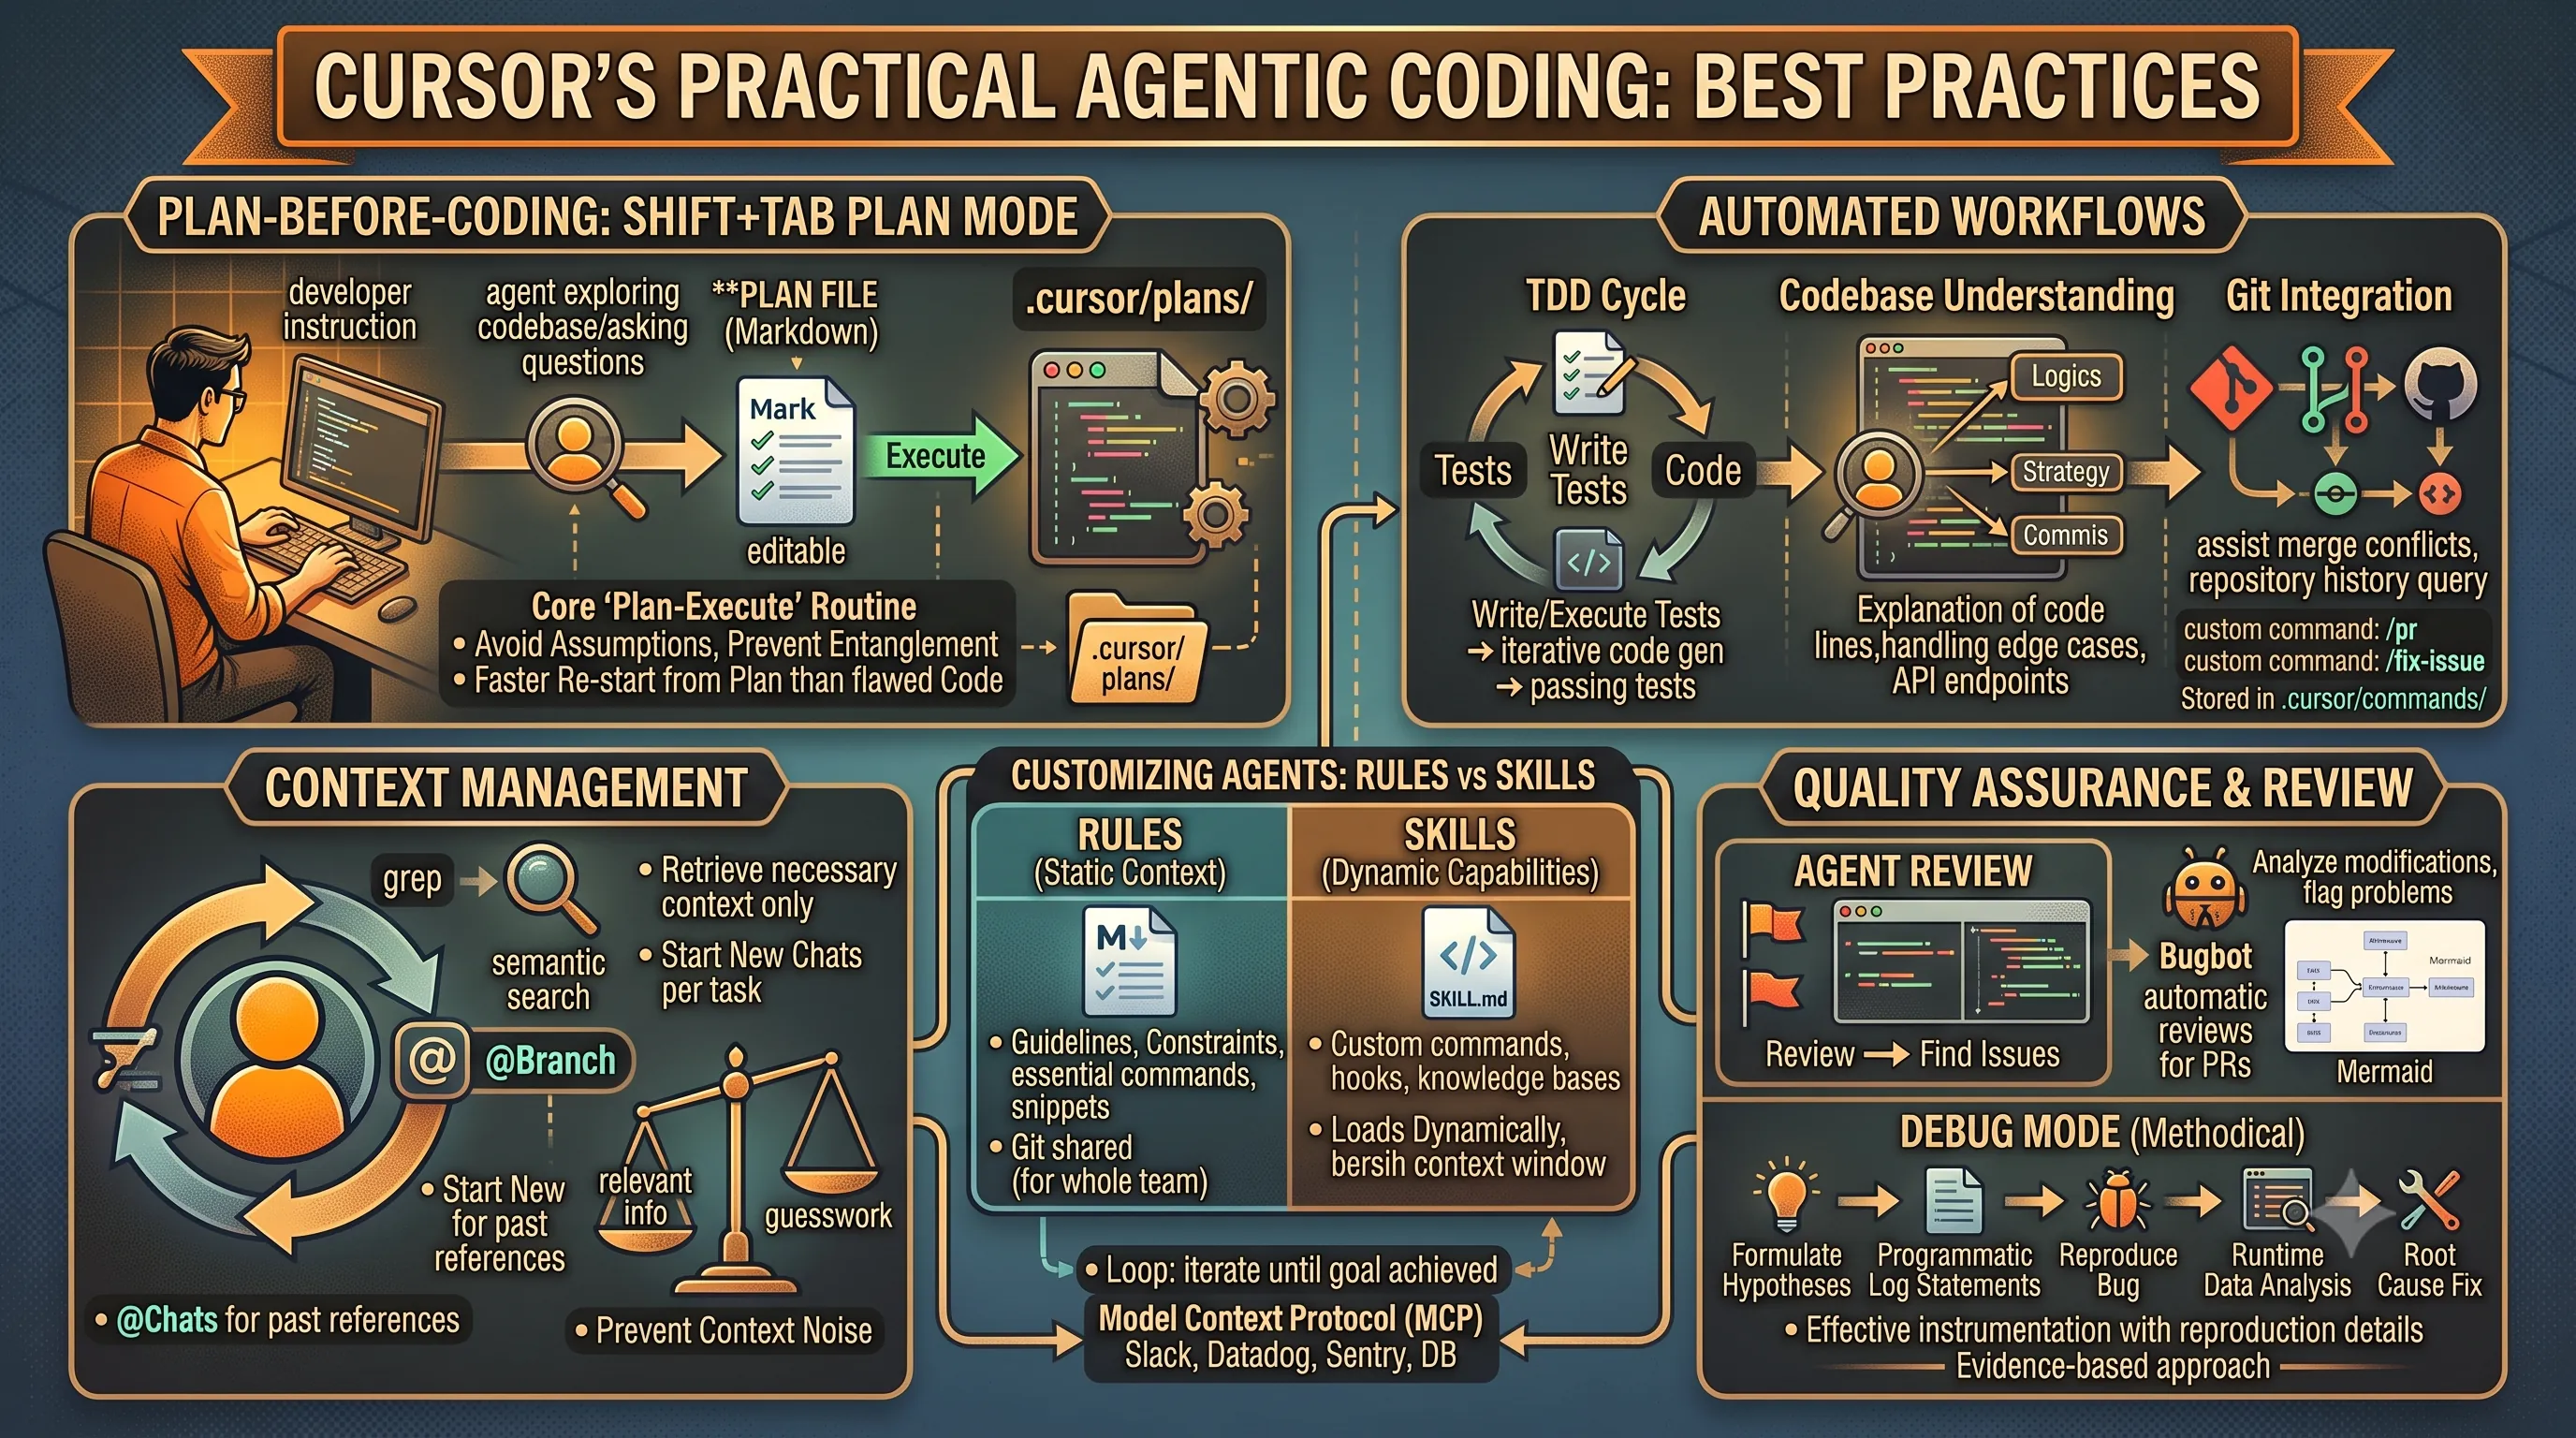
The most significant leap in agentic coding effectiveness comes from planning before writing a single line of code, a practice that mirrors the behavior of skilled human developers according to University of Chicago research.Cursor formalizes this with its Plan Mode, activated with Shift+Tab.
Instead of immediately executing a request, this mode prompts the agent to first explore the codebase, ask clarifying questions, and formulate a detailed implementation strategy.
This plan is presented as a Markdown file, which the developer can directly review and modify before granting approval for code generation.
This two-step process is the core of the 'Plan-Execute' routine, preventing the agent from making incorrect assumptions that lead to tangled code.
For simple, one-off changes, direct execution remains sufficient.
However, for any complex task, initiating with a plan is crucial.
If an agent's initial code generation is unsatisfactory, it is almost always faster and more effective to restart from the plan rather than attempting to correct the flawed output with a series of follow-up prompts.
Furthermore, these plans can be saved to a `.cursor/plans/` directory within the project, creating a valuable repository of team documentation and providing rich context for future agent tasks.
Context Management for Focused Agents
An agent's effectiveness is directly proportional to the quality of the context it receives.Providing too little context leads to guesswork, while too much irrelevant information causes confusion and loss of focus.
Cursor's agent is equipped with powerful search tools, including both traditional grep and modern semantic search, to automatically retrieve the necessary context for a given task.
The best practice is to allow the agent to find the relevant files itself unless the developer knows the exact files required, in which case they should be tagged explicitly.
Including files that are not pertinent to the task at hand is counterproductive and can confuse the agent.
For providing context about the developer's current work-in-progress, the `@Branch` tool is particularly effective.
Managing the conversation history is equally important.
Overly long conversations accumulate context noise, causing agents to lose focus or repeat mistakes.
A new conversation should be started when moving to a different task or feature, or whenever the agent appears confused.
Conversely, a conversation should be continued when refining the same feature or debugging recently generated code, as the agent requires the context from previous interactions.
To reference past work without cluttering the current context window, developers can use the `@Chats` command instead of copying and pasting large blocks of text from previous conversations.
Customizing Agents with Rules and Skills
To move beyond generic instruction, agents must be tailored to a project's specific needs.Cursor facilitates this through two primary mechanisms: Rules (static context) and Skills (dynamic capabilities).
Rules are persistent guidelines, defined in Markdown files within the `.cursor/rules/` directory, that govern how the agent interacts with the codebase.
To be effective, rules should be concise, focusing on essential commands, patterns, and representative code snippets rather than exhaustive style guides or long lists of commands.
Committing these rules to Git ensures they are shared and consistently applied across the entire team.
The agent can even update these rules itself when instructed by tagging `@cursor` in a GitHub issue or pull request.
Skills, defined in `SKILL.md` files, expand what an agent can do.
They can introduce custom commands invoked with a `/`, hooks that execute scripts before or after agent actions, and domain-specific knowledge bases.
Unlike Rules, Skills are loaded dynamically only when relevant, preserving a clean context window.
A powerful pattern involves using skills to create long-running agent loops that iterate until a verifiable goal is achieved, such as passing all tests or matching a UI to a design mockup.
Hooks can also integrate with security tools, secret management systems, and observability platforms.
Through the Model Context Protocol (MCP), agents can connect to external tools like Slack, Datadog, Sentry, and databases, further expanding their capabilities.
| Feature | Type | Purpose | Implementation | Best For |
|---|---|---|---|---|
| Rules | Static Context | Provide persistent guidelines and constraints. | Markdown files in .cursor/rules/ | Enforcing coding patterns, defining essential commands, referencing key code examples. |
| Skills | Dynamic Capabilities | Expand what an agent can do with new actions and knowledge. | SKILL.md files containing custom commands, hooks, and domain information. | Creating long-running loops, integrating with external tools, defining custom workflows. |
Multimodal Input and Visual Debugging
Modern development is not limited to text, and neither are modern agents.Agents can now directly process images included in prompts, such as screenshots, design files, or simple image paths.
A common and powerful workflow involves pasting a design mockup directly into the prompt and instructing the agent to implement it, matching the specified layout, colors, and spacing.
For more integrated design-to-code workflows, a Figma MCP server can be utilized.
This visual capability extends to debugging.
When encountering an error state or an unexpected UI behavior, a developer can capture a screenshot and ask the agent to analyze it.
The agent can also be given control of a browser to capture screens, test web applications, and validate visual changes automatically, bridging the gap between code and its visual output.
Automated Workflows: TDD, Codebase Understanding, and Git Integration
By combining planning, context, and custom skills, developers can automate complex, multi-step workflows.One popular workflow is Test-Driven Development (TDD), where the agent is first tasked with writing and executing tests for a new feature and then iteratively writes the necessary code to make those tests pass.
For codebase understanding, agents act as an interactive guide.
A developer can ask complex questions about logging strategies, API endpoints, how edge cases are handled, or for an explanation of a specific line of code.
The agent can also be deeply integrated into the Git workflow.
It can be asked to query repository history, assist in resolving merge conflicts, and automate common tasks.
Custom commands like `/pr` can be created to bundle the steps of committing, pushing, and creating a pull request into a single action.
These team-specific commands, such as `/fix-issue [number]` or `/update-deps`, can be stored in `.cursor/commands/` and committed to Git for all developers to use.
Ensuring Quality: Review and Debugging Strategies
AI-generated code is a powerful starting point, but it always requires human review.Cursor provides several tools to facilitate this crucial step.
During generation, developers can watch the code being written in a live diff view.
After generation, the 'Agent Review' feature (`Review → Find Issues`) can be used to analyze the suggested modifications and flag potential problems.
For teams using source control, Bugbot provides automatic reviews for pull requests, identifying issues and suggesting improvements.
For large-scale changes, developers can even ask the agent to generate an architecture diagram, such as a Mermaid diagram illustrating data flow, to aid in the review process.
For particularly difficult bugs, Cursor offers a specialized Debug Mode.
This mode takes a methodical, evidence-based approach: it formulates hypotheses about the bug, programmatically inserts logging statements into the code, requests the developer to reproduce the bug to capture runtime data, and then analyzes the actual behavior to find the root cause before implementing a precise fix.
This mode is especially effective for reproducible but unknown bugs, race conditions, performance issues, memory leaks, and regression bugs.
Providing the agent with detailed information on how to reproduce the problem is key to making its instrumentation code more effective.
[[AD_1]]
5. August 2026: A Turning Point in the AI Industry Landscape
This section details the industry-wide upheaval that serves as the backdrop for new development paradigms like agentic coding's 'Plan-Execute' routine.The sheer velocity of model releases, the rise of powerful specialized agents, and the shift to multi-agent systems have rendered simple, single-prompt coding obsolete.
The complexity described here is precisely why a structured, reliable method for orchestrating AI agents to perform complex tasks, such as debugging code, has become a mission-critical necessity for developers.
A Deluge of High-Stakes Model Releases
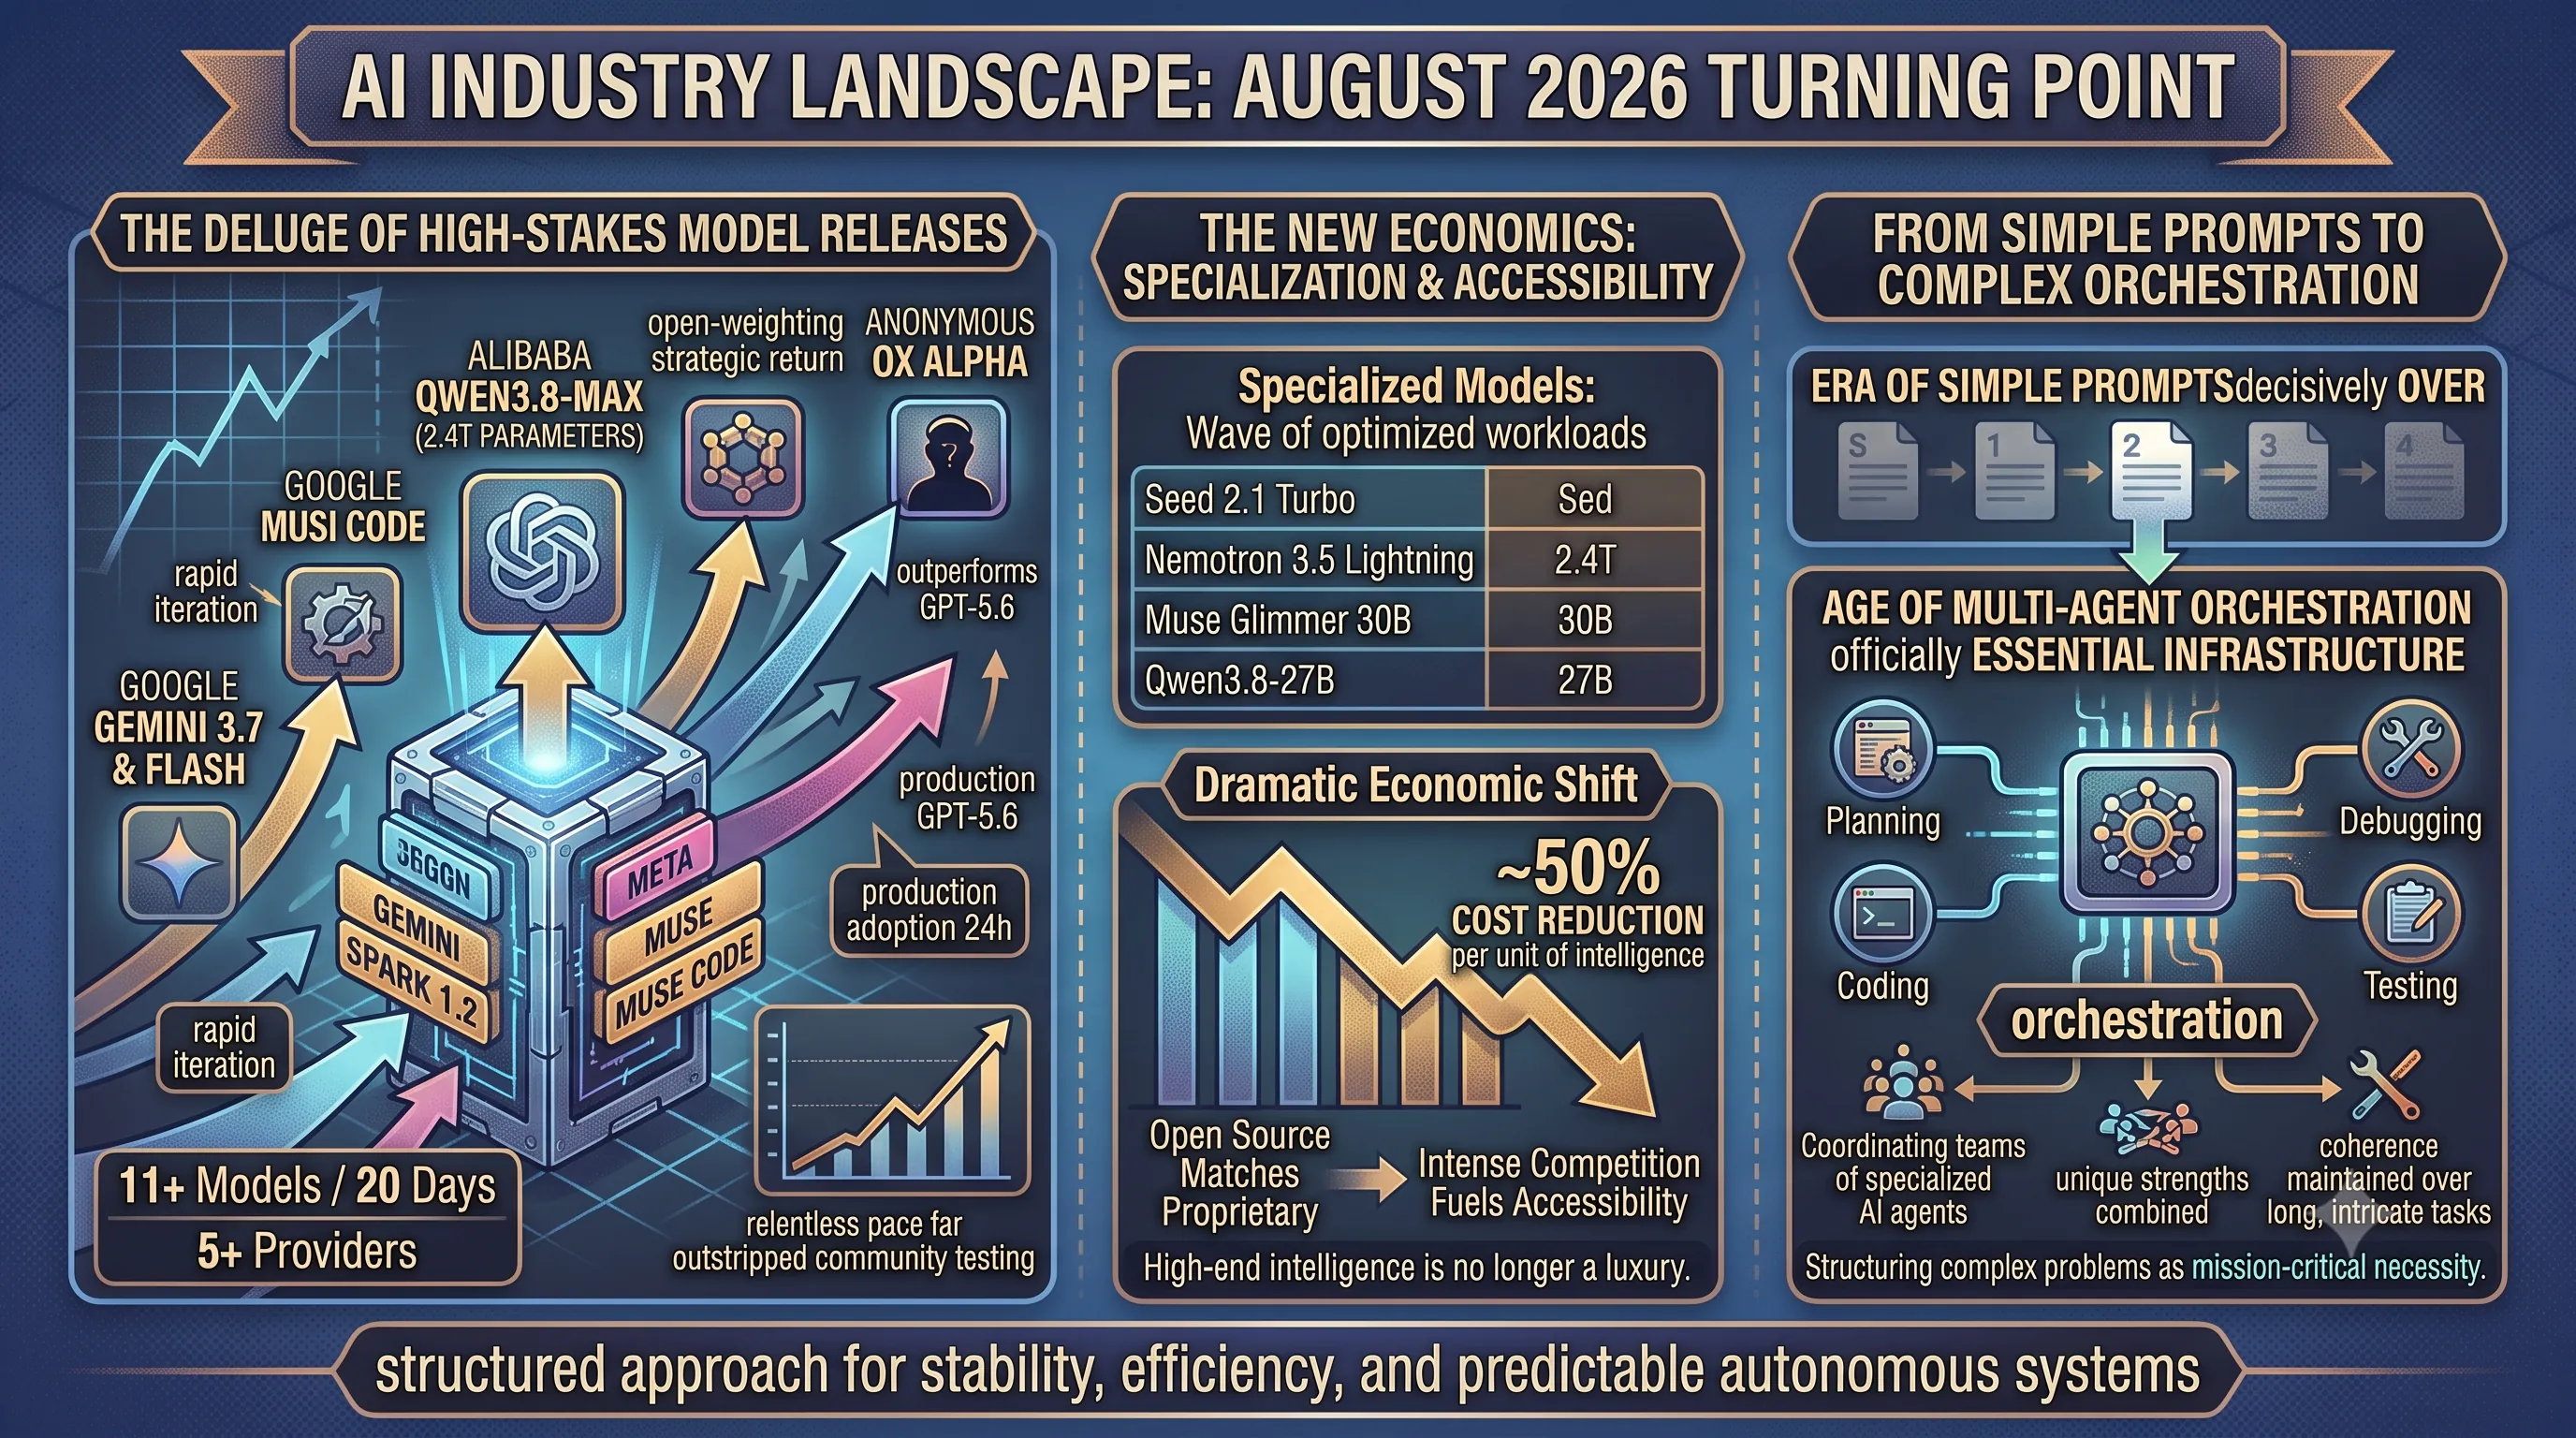
History will likely mark August 2026 as a definitive turning point for the artificial intelligence industry.The pace of innovation has become relentless, with more than 11 new models released in just 20 days from over five different providers, a rate that has far outstripped the community's ability to perform comprehensive testing.
Google exemplified this rapid iteration, releasing its Gemini 3.7 Flash model a mere three weeks after the launch of version 3.6.
The open-source community witnessed two monumental shifts.
First, Alibaba Cloud released Qwen3.8-Max, which at 2.4 trillion parameters, became the largest open-weight model ever released.
Second, Meta signaled a strategic return to its roots by open-weighting both Muse Spark 1.2 and the specialized Muse Code.
This torrent of releases was punctuated by the arrival of a mysterious new player: an anonymous model dubbed OX Alpha.
It immediately seized the industry's attention by outperforming GPT-5.6 on key coding benchmarks and, in an unprecedented move, achieved production-level adoption within 24 hours of its appearance.
The New Economics: Specialization and Accessibility
The era of a single, monolithic model for all tasks is decisively over.A defining feature of this month was the wave of specialized models, each highly optimized for specific workloads and making it possible to have a dedicated model for nearly every conceivable use case.
This trend was seen across the board, from major labs to smaller, focused teams.
| Model Family / Provider | Specialized Model Release (August 2026) |
|---|---|
| Seed AI | Seed 2.1 Turbo |
| NVIDIA | Nemotron 3.5 Lightning |
| Meta | Muse Glimmer 30B |
| Alibaba Cloud | Qwen3.8-27B |
The cost per unit of intelligence has dropped by approximately 50% across multiple performance tiers, fueled by intense competition and the fact that open-source models now routinely match the performance of their proprietary counterparts.
High-end intelligence is no longer a luxury.
From Simple Prompts to Complex Orchestration
These technological and economic shifts have fundamentally changed how developers interact with AI.The era of simple prompts is over.
With million-token context windows now a standard feature, models can handle vastly more complex inputs and maintain state over long, intricate tasks.
This capability is the technical foundation for the agent revolution, which has officially moved from an experimental concept to a piece of essential infrastructure.
We are now firmly in an age defined by multi-agent orchestration, where complex problems are solved not by a single request to one model, but by coordinating a team of specialized AI agents, each contributing its unique strengths.
6. Navigating the Deluge: AI Model Release Velocity and Evaluation Challenges
This section explores the chaotic landscape of AI model releases, which directly fuels the need for the structured 'Plan-Execute' methodology central to agentic coding.When the ground beneath a developer is constantly shifting due to new models, pricing changes, and fragmented versions, a disciplined, automated approach to integration and testing becomes a critical survival tool, not a luxury.
A Record-Breaking Release Cadence
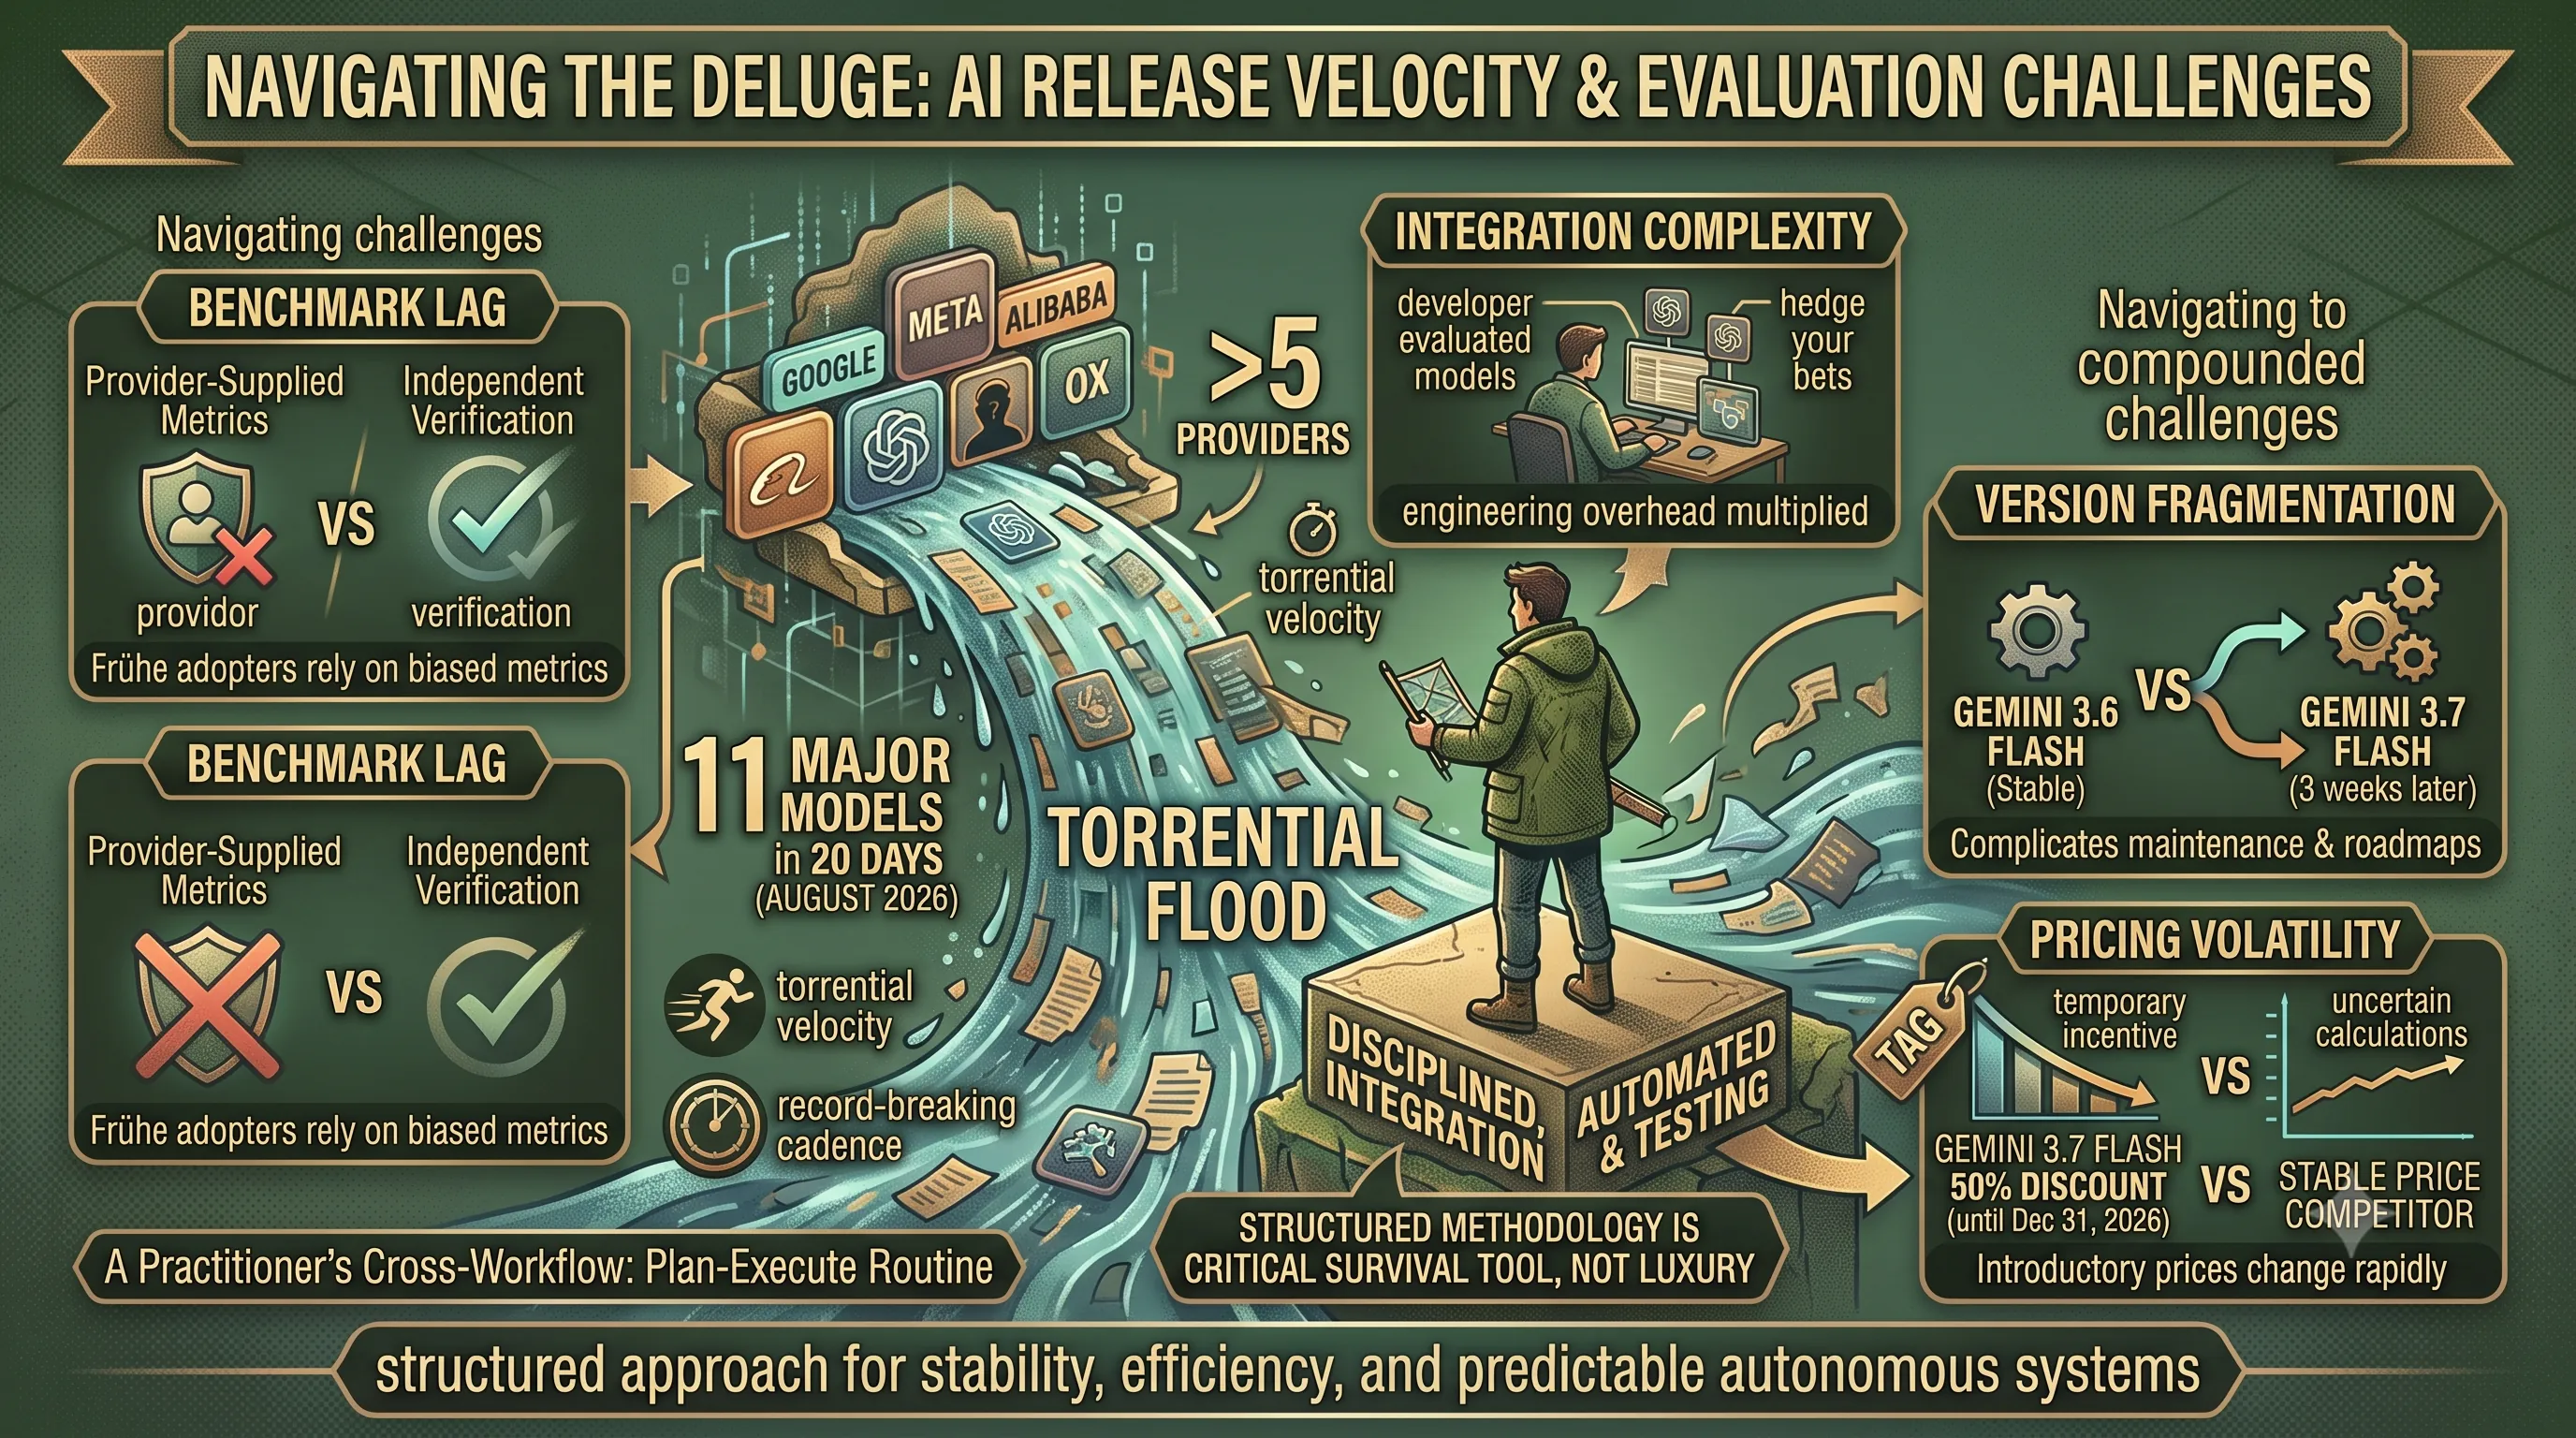
The pace of AI development has moved from a steady stream to a torrential flood.This month alone, August 2026 set a new record with 11 major AI models released in just 20 days from more than five providers.
This relentless velocity has fundamentally altered the strategic landscape for engineering teams.
The window for gaining a competitive advantage from integrating any single new model has dramatically shrunk from months to mere weeks.
As one industry analyst noted, the half-life of a model's dominance is shorter than ever: "Models that topped benchmarks six months ago are now middle of the pack."
This creates a permanent state of evaluation lag, where by the time a team has fully vetted and integrated one model, a newer, potentially better one is already available.
The Compounding Challenges for Developers
This hyper-acceleration brings with it a cascade of practical and strategic problems for developers trying to build reliable applications.First is the issue of benchmark lag; new models now consistently ship faster than independent, third-party verification can be completed, forcing early adopters to rely on provider-supplied metrics that may not reflect real-world performance.
This leads directly to integration complexity, as prudent teams are now forced to evaluate multiple new models simultaneously to hedge their bets, multiplying the engineering overhead.
We are also seeing severe version fragmentation, which complicates maintenance and stability.
For instance, Gemini 3.7 Flash arrived only three weeks after version 3.6 Flash was declared stable, forcing teams to immediately reconsider their roadmaps.
Adding another layer of uncertainty is pricing volatility.
Introductory prices change rapidly, making long-term cost-of-ownership calculations difficult.
A clear example is the new Gemini 3.7 Flash, which launched with a 50% discount effective until December 31, 2026, a temporary incentive that complicates choosing it over a competitor with more stable pricing.
In this environment, continuous testing is now mandatory, not just a best practice, to manage the constant influx of new capabilities and risks.
7. The Multimodal Era: Beyond Text-Only AI Models
This section directly connects to the core theme of separating 'Plan' and 'Execute' in agentic coding by radically expanding the information an AI agent can use during the 'Plan' phase.When an agent's understanding is no longer confined to text-based requirements, it can ingest visual context like UI mockups, error-screen videos, or system architecture diagrams.
This richer, multimodal input allows the agent to formulate a far more accurate and comprehensive execution plan, drastically reducing the chances of misinterpretation that lead to the "tangled code" problem our main article addresses.
A Universal Baseline: Multimodal Support in August 2026 Models
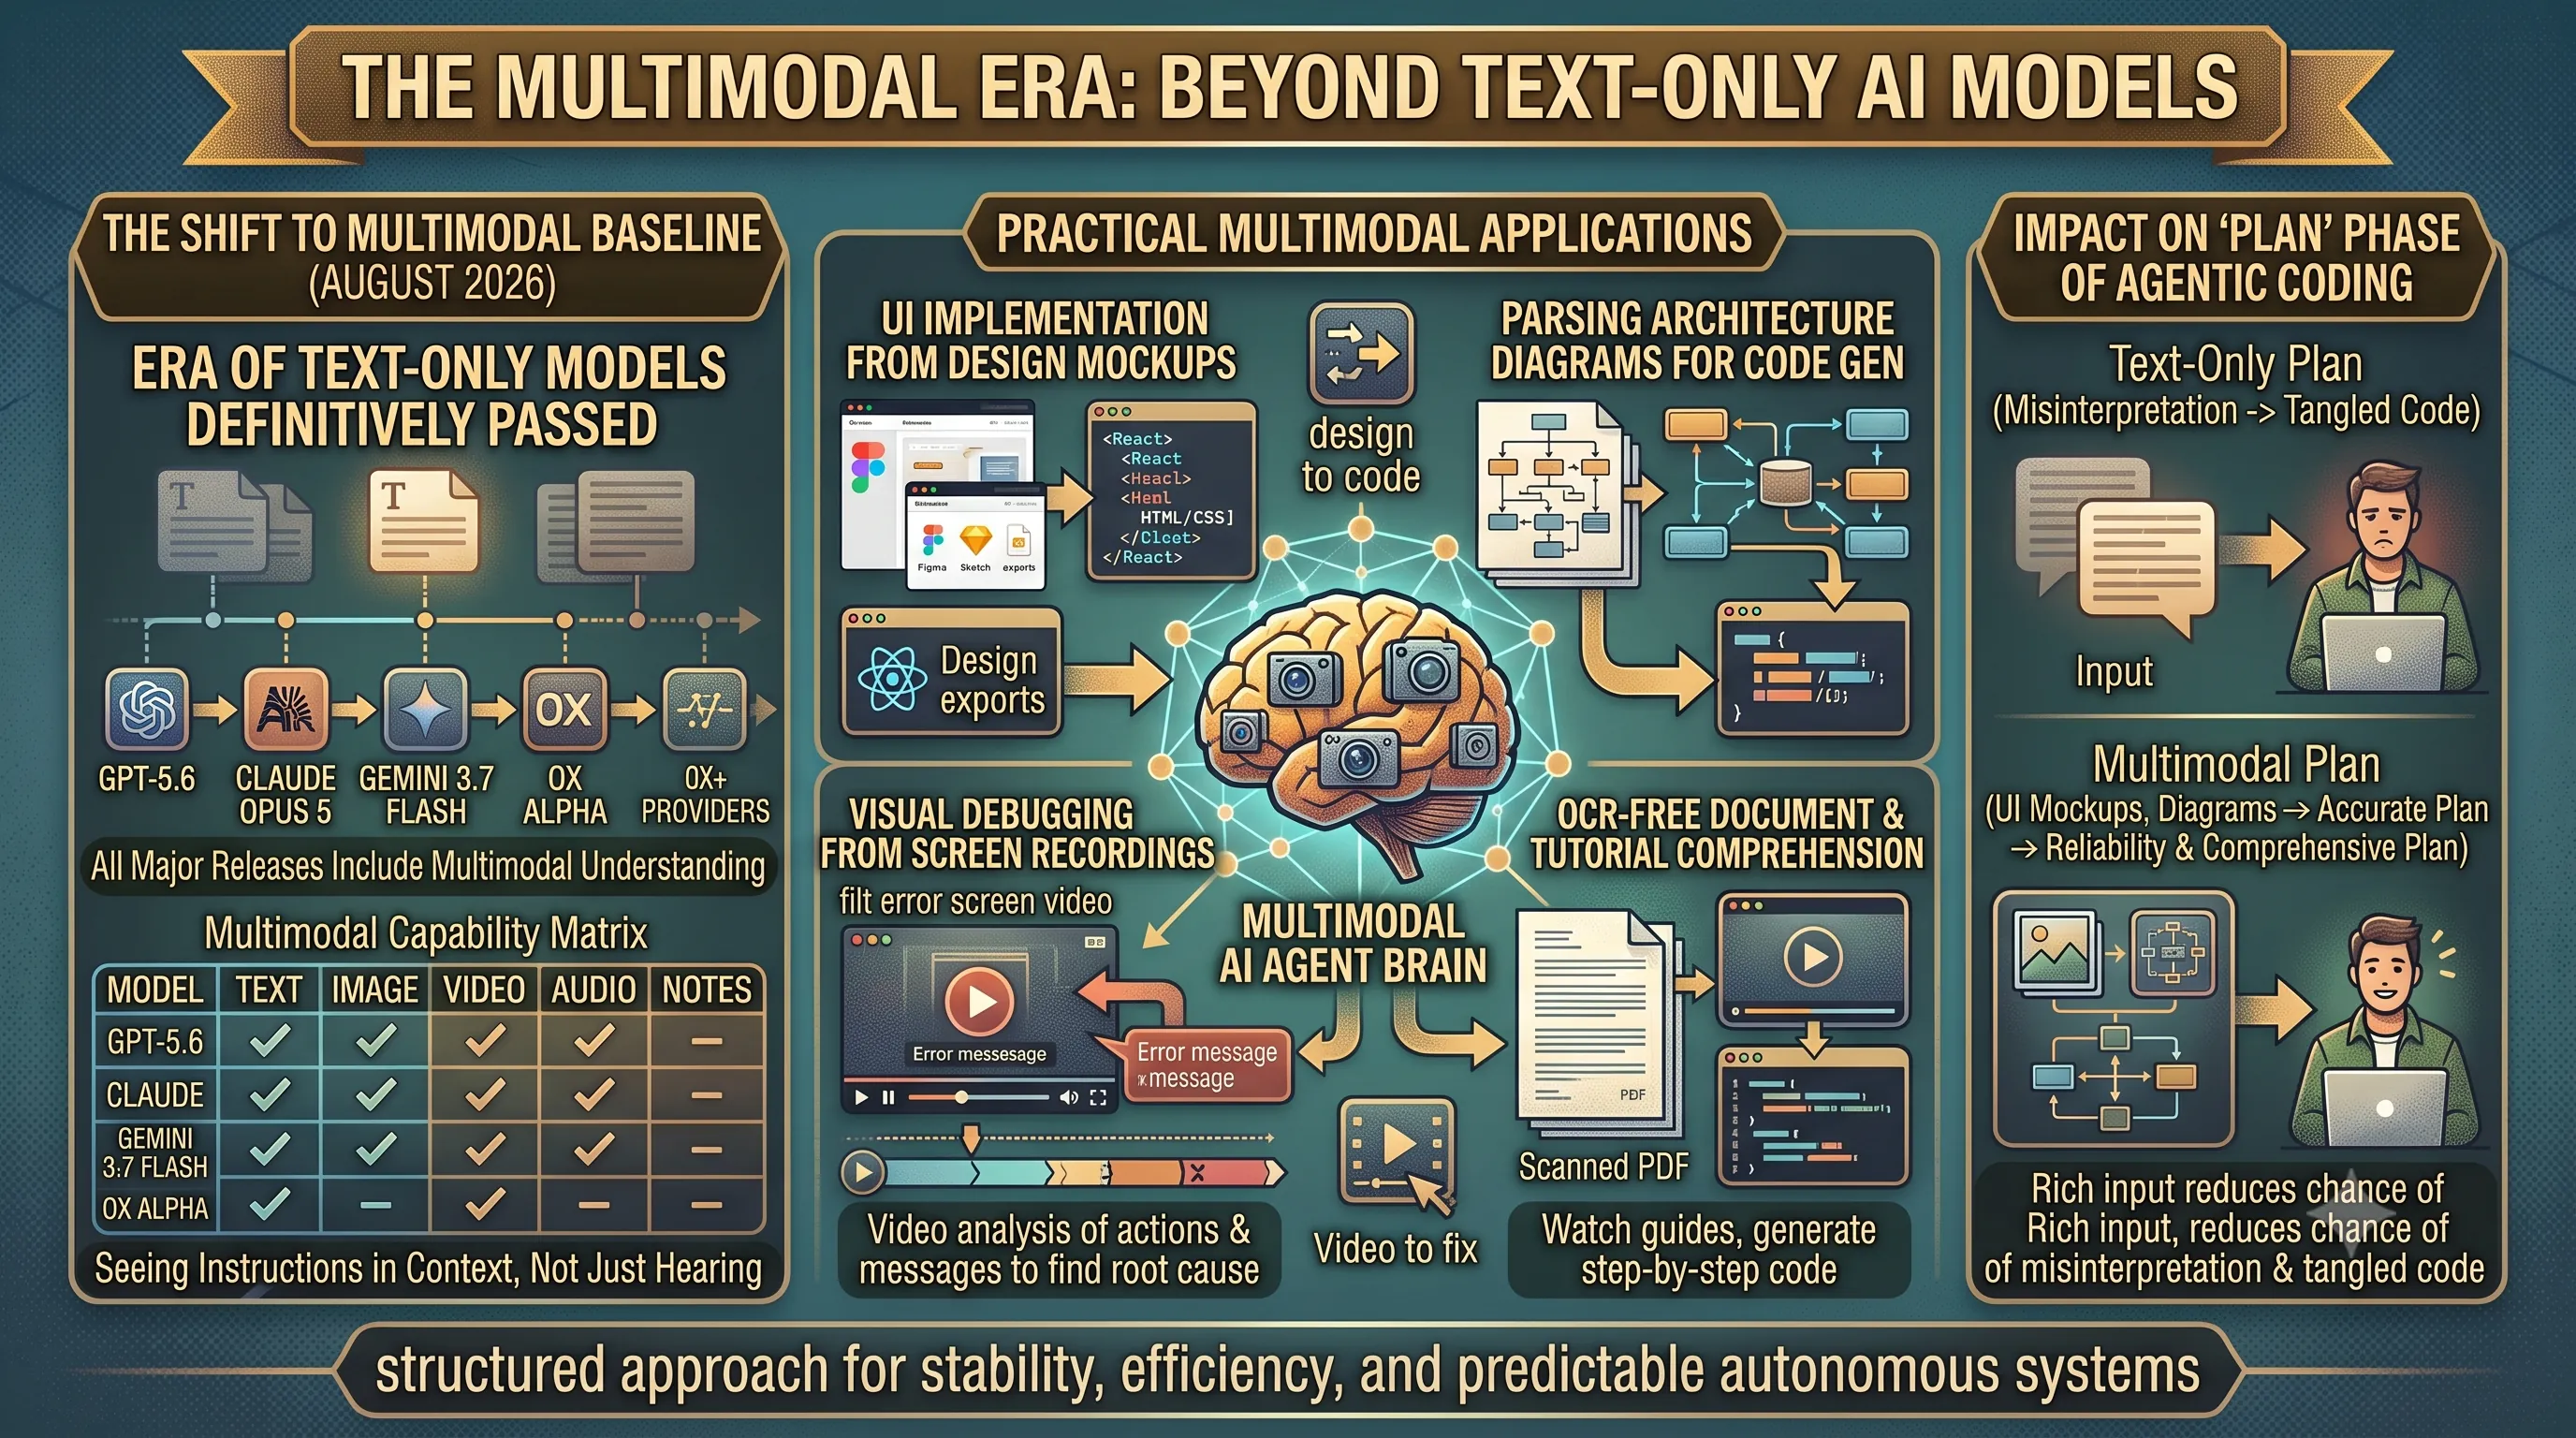
The era of text-only AI models has definitively passed; they are now the exception, not the rule.As of August 2026, every major AI model release has integrated multimodal understanding as a baseline capability, fundamentally changing how developers interact with coding assistants.
This industry-wide standardization means that models are no longer just "hearing" instructions but are now "seeing" the context in which those instructions must be executed.
The capabilities vary across models, establishing a new landscape for AI-powered development tools.
| Model Family | Text | Image | Video | Audio | Notes |
|---|---|---|---|---|---|
| GPT-5.6 Family | ✔️ | ✔️ | - | - | Standard text and image support. |
| Claude Opus 5 | ✔️ | ✔️ | - | - | Standard text and image support. |
| Gemini 3.7 Flash | ✔️ | ✔️ | ✔️ | ✔️ | Native text/image support; video and audio available via API. |
| OX Alpha | ✔️ | ✔️ | ✔️ | - | Includes video understanding. |
| Seed 2.1 | ✔️ | ✔️ | ✔️ | - | Includes video understanding. |
| Qwen3.8-Max | ✔️ | ✔️ | ✔️ | - | Includes video understanding. |
| Muse Spark 1.2 | ✔️ | ✔️ | ✔️ | - | Includes video understanding. |
| Seed 2.1 Turbo | ✔️ | ✔️ | ✔️ | ✔️ | Full 4-modal (Text, Image, Video, Audio) support. |
| MiniMax H3 | ✔️ | ✔️ | ✔️ | ✔️ | Offers omni-modal generation, including video and audio output. |
From Blueprints to Bug Reports: Practical Multimodal Applications
This universal shift toward multimodality unlocks several powerful, real-world applications that streamline the entire development lifecycle.Instead of describing a visual concept, developers can now provide it directly as input.
For instance, UI implementation can be initiated directly from design screenshots, allowing the AI to translate a visual layout from a Figma or Sketch export into functional code.
Similarly, complex system designs no longer need to be exhaustively described in text; architecture diagrams can be parsed as direct visual context for code generation, ensuring the AI understands component relationships and data flows.
Debugging has also become a visual process.
Rather than writing detailed bug reports, developers can now feed the AI a screen recording of the error occurring.
The model can analyze the video to understand the user actions, the resulting system behavior, and the on-screen error messages to pinpoint the root cause.
This visual context extends to learning and documentation, where scanned PDFs or documents are now understood without requiring a separate OCR preprocessing step.
Even video tutorials can be processed, enabling an agent to watch a guide and generate step-by-step code based on the demonstrated actions.
8. The Resurgence of Open-Weight AI Models and Strategic Competition
The 'execution' phase of the Plan-Execute agentic coding routine depends heavily on the power and accessibility of the underlying foundation models.This month, the competitive landscape for these essential tools intensified dramatically, with major technology players accelerating the release of powerful open-weight models.
Key Players Escalate Open-Weight Releases
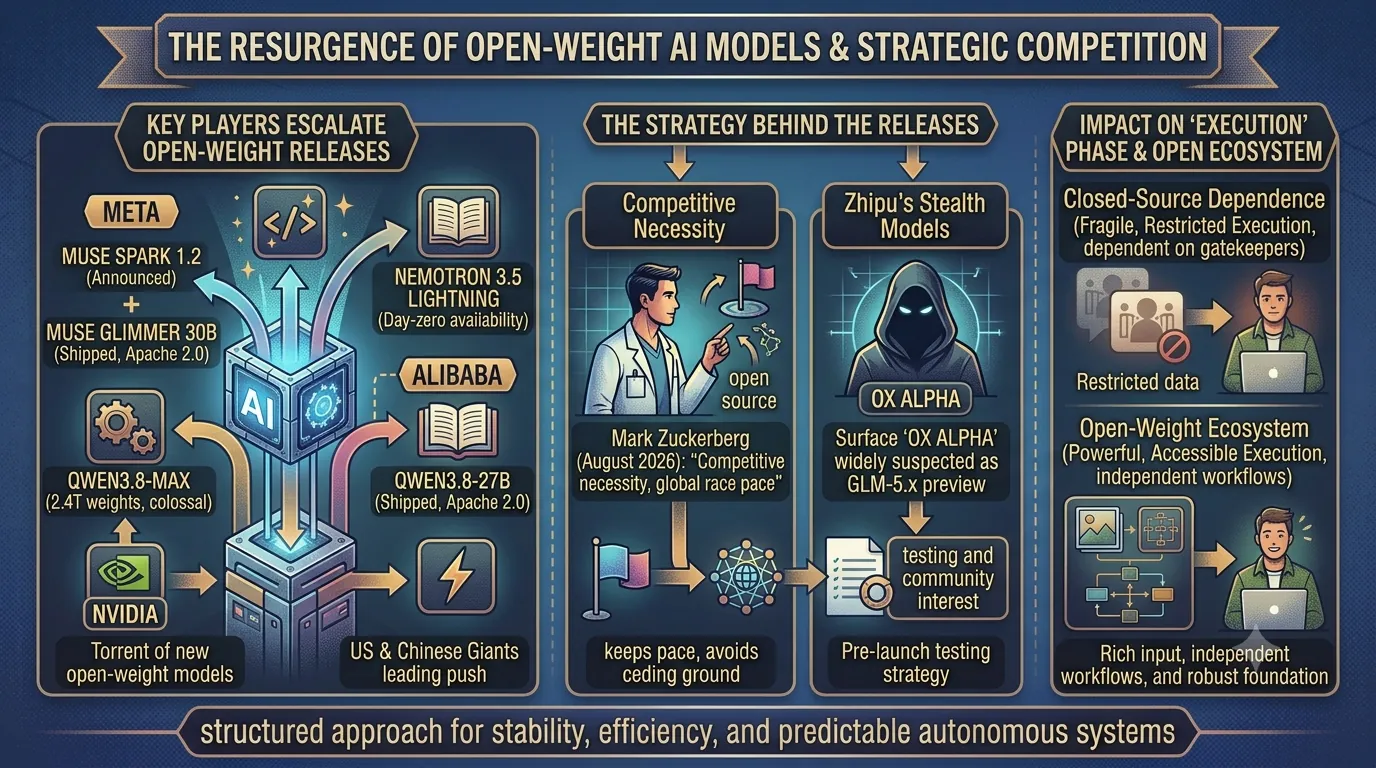
The renewed push is being led by a mix of US and Chinese technology giants, each contributing significant new models to the ecosystem.Meta signaled a strong return to its open-source roots with two notable models: Muse Spark 1.2 was officially announced, while the Muse Glimmer 30B model was already shipped with a permissive Apache 2.0 license.
Not to be outdone, Alibaba solidified its leadership position in the open-weight sphere by releasing the colossal Qwen3.8-Max, with 2.4 trillion weights, alongside the more accessible Qwen3.8-27B, which also uses the Apache 2.0 license.
Entering the fray directly, hardware giant NVIDIA also demonstrated its commitment by ensuring day-zero availability for its new Nemotron 3.5 Lightning model.
| Provider | Model Name | Key Detail / Status |
|---|---|---|
| Meta | Muse Spark 1.2 | Announced |
| Meta | Muse Glimmer 30B | Shipped with Apache 2.0 license |
| Alibaba | Qwen3.8-Max | 2.4T weights released |
| Alibaba | Qwen3.8-27B | Shipped with Apache 2.0 license |
| NVIDIA | Nemotron 3.5 Lightning | Day-zero availability |
The Strategy Behind the Releases
This flood of new models is not merely a technical exercise but a calculated strategic move.In a statement this August, Meta's Mark Zuckerberg framed the open-weight strategy as a competitive necessity, positioning it as essential for keeping pace in the global AI race.
He also added a geopolitical dimension to the debate, noting that in his view, "US restrictions benefit foreign labs," suggesting that a closed approach could inadvertently cede ground to international rivals.
This competitive dynamic is also giving rise to different release strategies.
Some Chinese labs, such as Zhipu, have exhibited a pattern of releasing "stealth models."
The recently surfaced OX Alpha model is widely suspected to be a preview of the company's anticipated GLM-5.x multimodal series, pending official attribution, showcasing a method of testing and generating community interest before a formal launch.
9. AI Model Cost Efficiency: Up to 50% Drop in Intelligence Unit Costs
This section connects directly to our main topic of agentic coding's 'Plan-Execute' routines.Such systems, by their nature, are far more iterative than single-prompt interactions, often requiring dozens or even hundreds of model calls to complete a single complex task like debugging code.
This high-volume usage makes the cost per API call a critical factor in determining economic viability.
The recent, dramatic price reductions across the industry are therefore not just a market trend; they are a fundamental enabler for the widespread adoption and scaling of sophisticated agentic workflows.
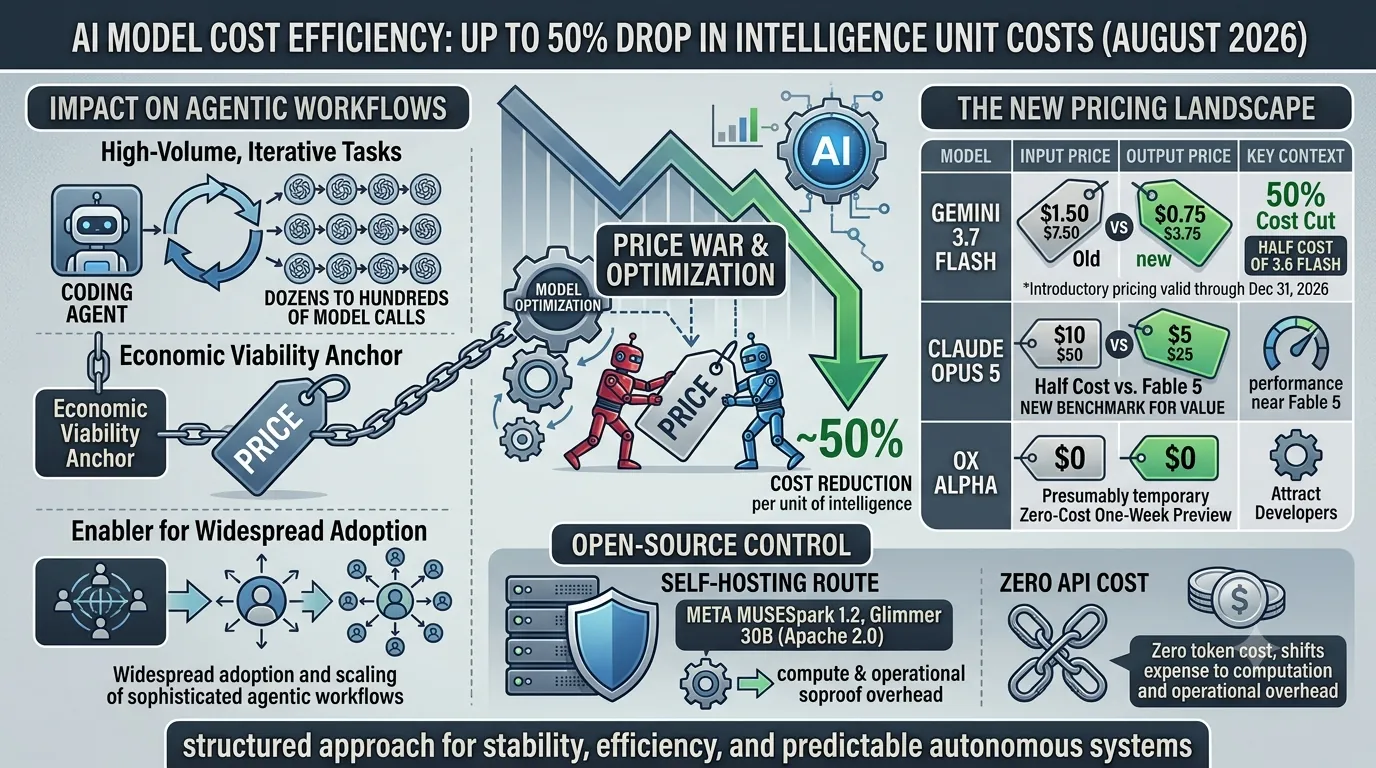
The month of August 2026 has been a pivotal moment for developers leveraging AI, as the effective cost per intelligence unit plummeted by approximately 50% across multiple performance tiers.
This price war, driven by intense competition and model optimization, has made advanced AI capabilities more accessible than ever.
The new pricing landscape is best illustrated by the aggressive moves from major AI providers.
| Model | Input Price (per 1M tokens) | Output Price (per 1M tokens) | Key Context |
|---|---|---|---|
| Gemini 3.7 Flash | $0.75 | $3.75 | Introductory pricing valid through December 31, 2026. |
| Claude Opus 5 | $5 | $25 | Achieves performance near Fable 5 at half the cost. |
| OX Alpha | $0 | $0 | Price during a one-week preview period. |
Google's Gemini 3.7 Flash, for example, launched with an introductory price that is half the cost of its predecessor, 3.6 Flash.
Meanwhile, Anthropic’s Claude Opus 5 established a new benchmark for value by delivering performance comparable to the top-tier Fable 5 model at a 50% cost reduction.
Even new entrants like OX Alpha are using cost as a lever, offering a presumably temporary zero-cost one-week preview to attract developers.
Beyond pay-per-use APIs, the open-source community continues to provide a powerful alternative for cost control.
Meta Muse announced open weights for its Spark 1.2 and Apache 2.0 licensed Glimmer 30B models.
For teams willing to manage their own infrastructure, this self-hosting route offers a zero API cost, shifting the expense from tokens to computation and operational overhead.
10. Empowering Developers: The Advantages of Local AI Deployment
While the main article details the 'Plan-Execute' methodology for agentic coding, this section explores the hardware and software revolution that makes running such sophisticated agents on your own machine not just possible, but often preferable.The ability to deploy powerful AI models locally provides developers with unprecedented control, security, and cost-efficiency, directly empowering the creation and operation of autonomous coding agents.
Frontier Performance on Consumer Hardware
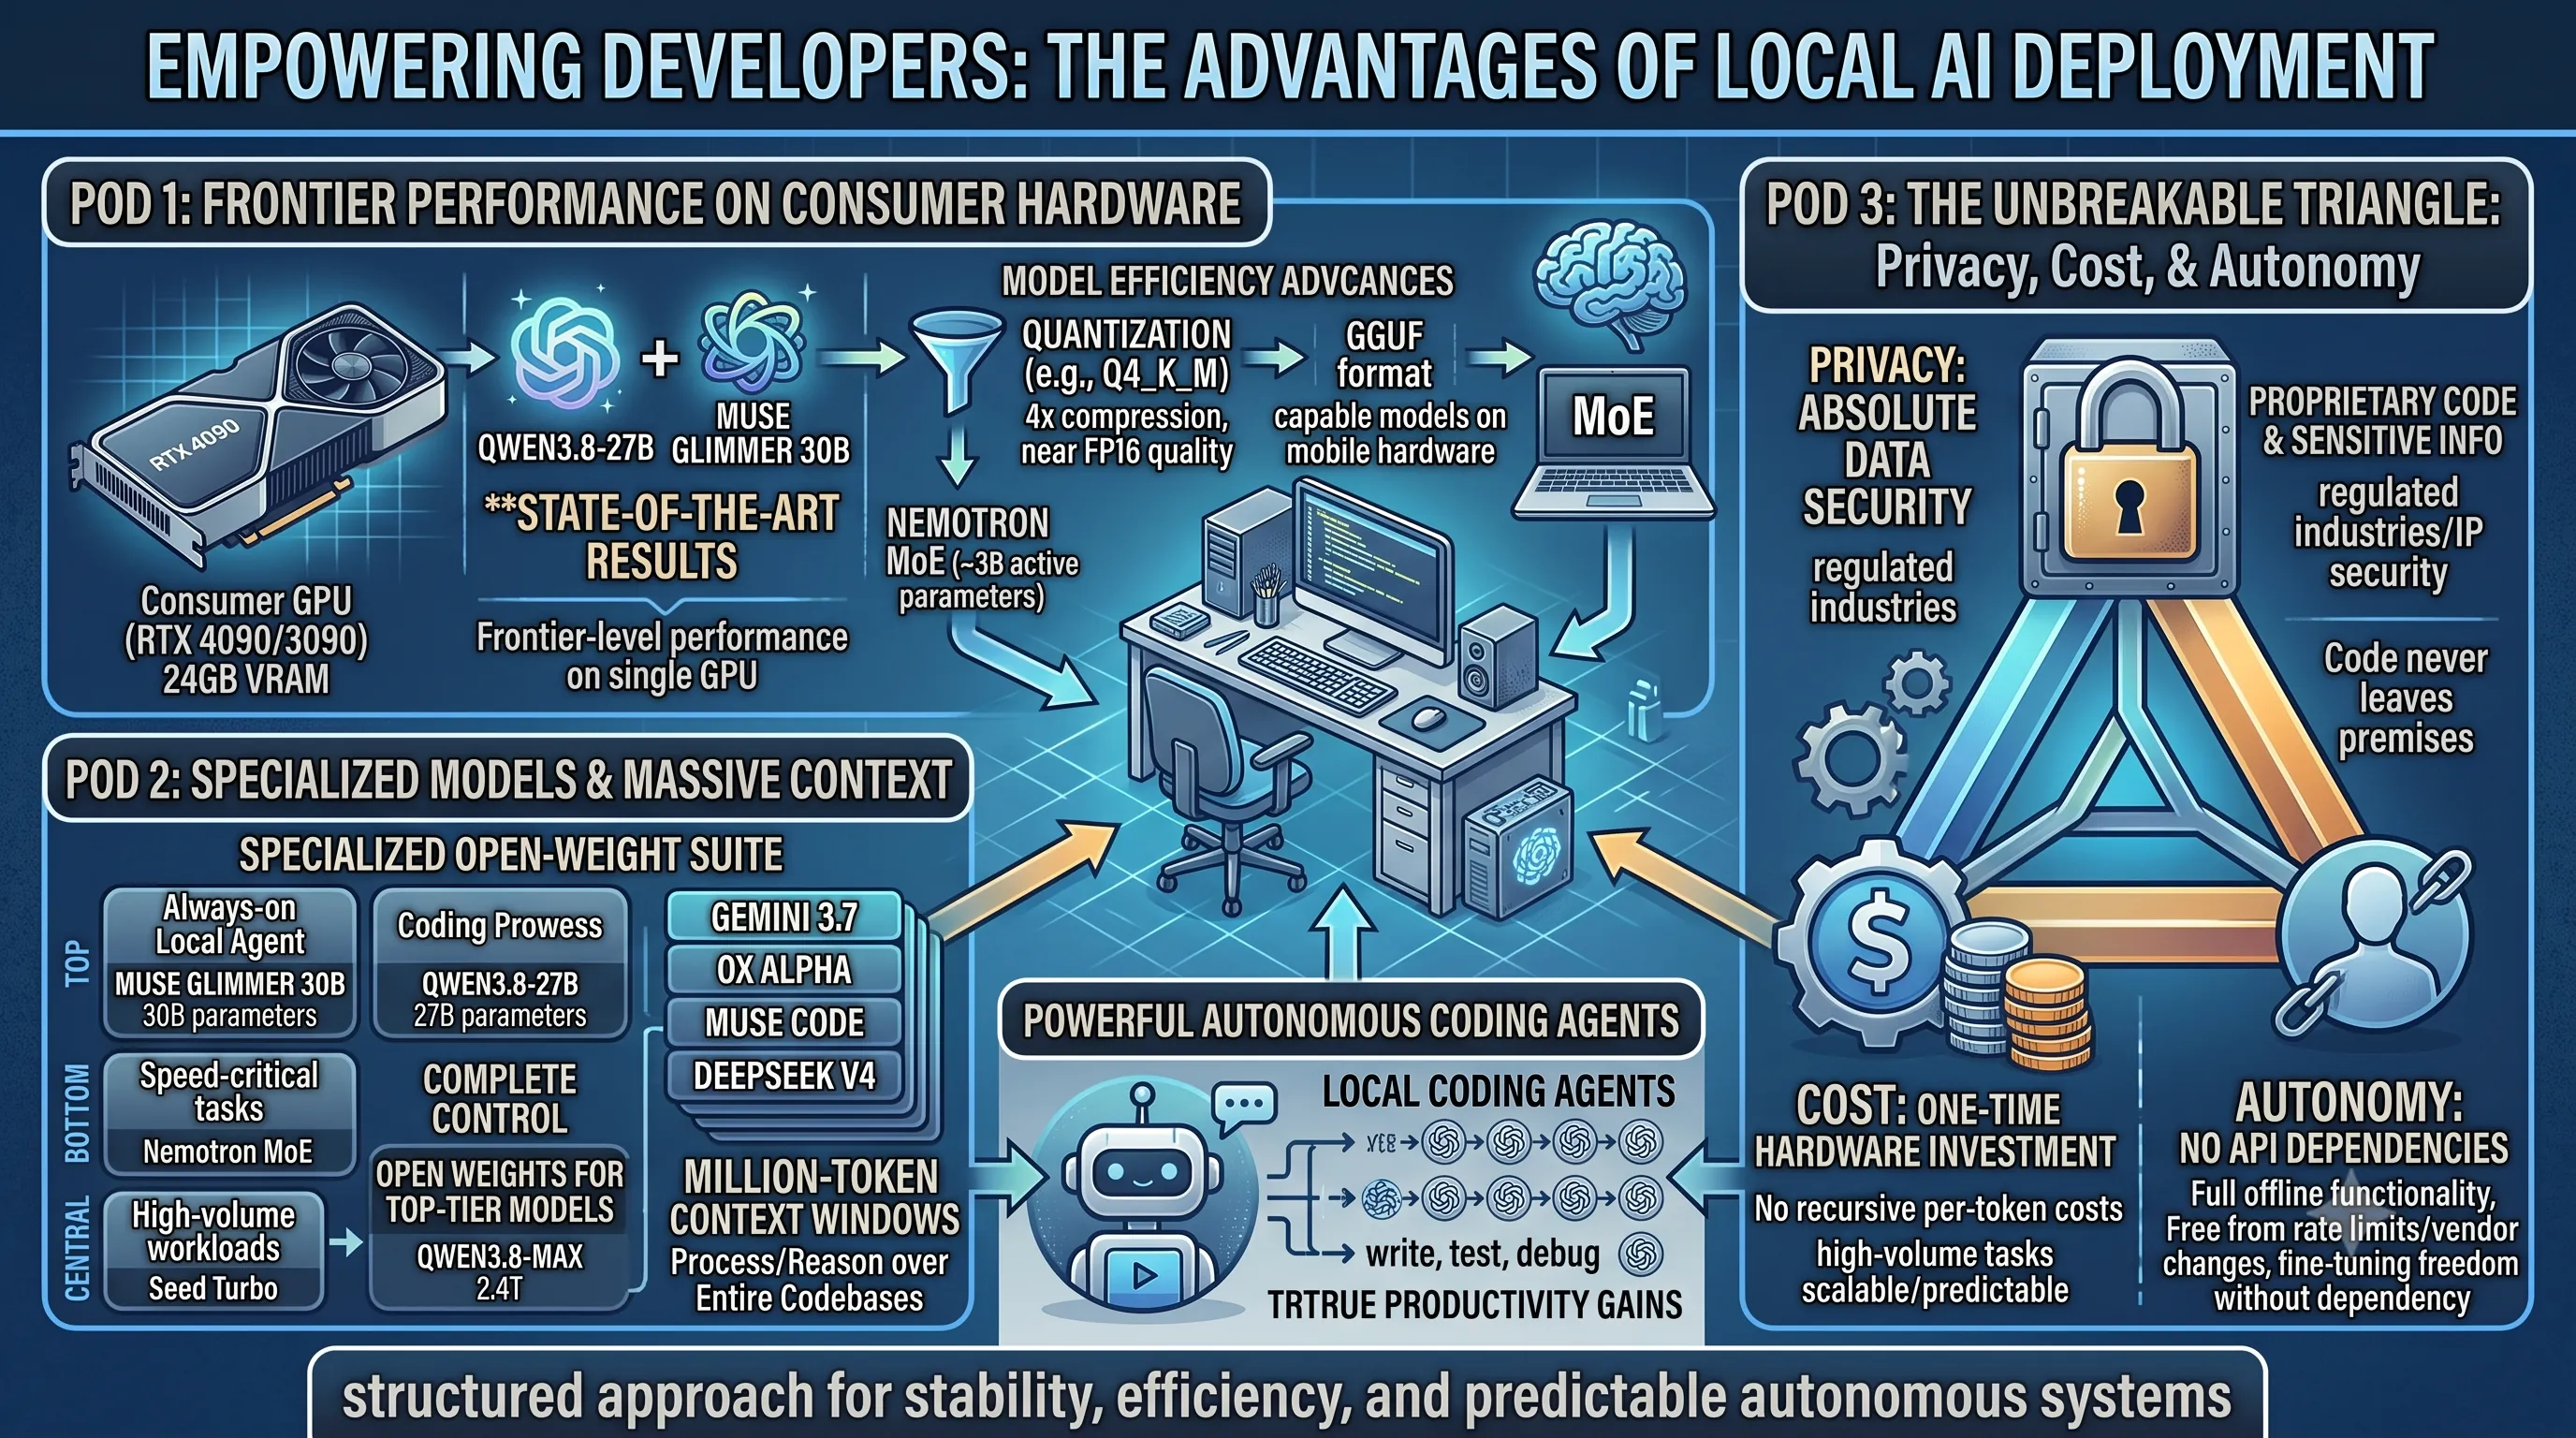
The gap between cloud-based APIs and local models has dramatically narrowed, with frontier-level coding performance now achievable on a single consumer-grade GPU.Models such as Qwen3.8-27B and Muse Glimmer 30B deliver state-of-the-art results while running effectively on graphics cards with 24GB of VRAM, like the RTX 4090 and 3090.
This leap in accessibility is fueled by significant advancements in model efficiency.
Quantization techniques like Q4_K_M achieve nearly the same quality as full-precision FP16 models but with a 4x compression ratio, drastically reducing memory and processing requirements.
The continued improvement of formats like GGUF further enhances compression without sacrificing performance.
Efficiency has progressed to the point where even highly capable models can run on mobile hardware; Nemotron 3.5 Lightning, a 30 billion parameter Mixture-of-Experts (MoE) model with approximately 3 billion active parameters, is deployable on modern laptop GPUs, making powerful AI agents truly portable.
Specialized Models and Massive Context Windows
The local AI ecosystem has matured beyond general-purpose models, now offering a suite of specialized, open-weight options tailored for specific workloads.This allows developers to choose the right tool for the job, whether it's speed, coding prowess, or high-volume processing.
The availability of open weights for top-tier models, including the massive Qwen3.8-Max 2.4T and agile performers like Muse Spark 1.2, gives developers complete control.
Muse Glimmer 30B, for instance, was specifically designed to function as an "always-on local agent," a concept that is rapidly becoming practical on consumer hardware.
| Model | Size / Type | Specialization | Hardware Target |
|---|---|---|---|
| Qwen3.8-27B | 27B Parameters | Coding | 24GB VRAM Consumer GPU (e.g., RTX 4090) |
| Muse Glimmer 30B | 30B Parameters | Always-on Local Agents | 24GB VRAM Consumer GPU (e.g., RTX 4090) |
| Nemotron 3.5 Lightning | 30B Parameters (MoE, ~3B active) | Speed-critical tasks | Laptop GPUs |
| Seed Turbo | Not Specified | High-volume workloads | Not Specified |
Alongside specialization, massive context windows have become standard for local deployment.
Models like OX Alpha, Muse Code, Gemini 3.7, and DeepSeek V4 routinely handle million-token contexts, enabling agents to process and reason over entire codebases without losing track of critical details.
The Unbreakable Triangle: Privacy, Cost, and Autonomy
Deploying agents locally provides a powerful combination of benefits that cloud APIs cannot match.First, data privacy is absolute.
Since proprietary code and sensitive information never leave the developer's premises, local deployment is an ideal solution for regulated industries or any organization concerned with IP security.
Second, the economic model is fundamentally different.
Instead of incurring recurring per-token costs that penalize usage, local AI involves a one-time hardware investment, making experimentation and high-volume tasks financially predictable and scalable.
Finally, it offers complete autonomy.
Developers are free from API dependencies, rate limits, or unexpected provider changes.
Full functionality is maintained even without an internet connection, and the freedom to fine-tune models on specific domains ensures a perfect fit for any project without vendor dependency.
11. Qwen3.8-Max: A New Open-Weight Giant with Trillion Parameters
This section delves into Qwen3.8-Max, a model whose long-horizon agentic capabilities provide a powerful, real-world example of the 'Plan-Execute' routines discussed in this article.Its ability to sustain complex tasks over extended periods, like autonomous coding, showcases the very principles of separating high-level strategy from step-by-step implementation.
Unprecedented Scale and Open Access
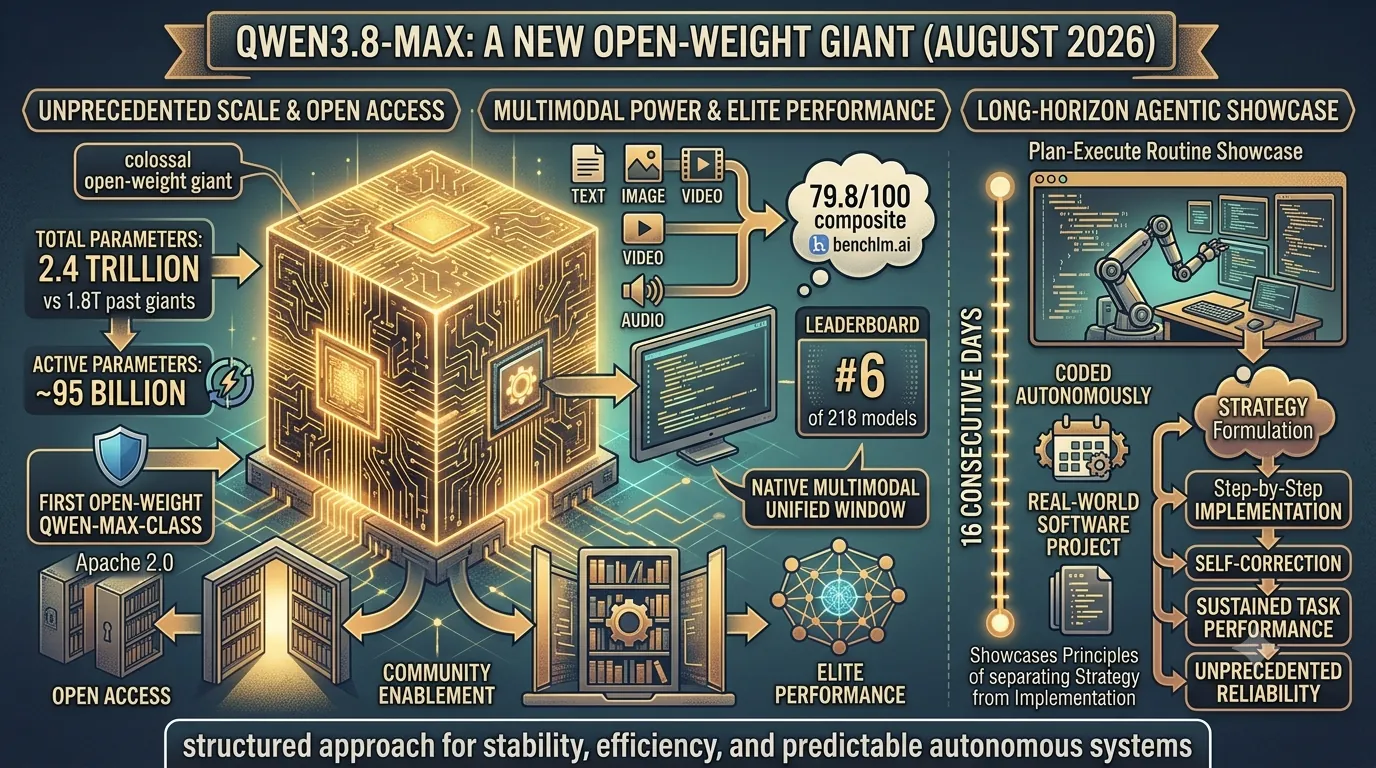
Released on August 3, 2026, Alibaba's Qwen3.8-Max marked a significant milestone in large-scale AI.The model boasts a staggering 2.4 trillion total parameters, though it operates more efficiently by utilizing approximately 95 billion active parameters at any given time.
Crucially, its weights were open-sourced in the week following its launch, making it the first Qwen-Max-class model to be made available to the broader research and development community.
This combination of massive scale and open access is further enhanced by its expansive 1M-token context window, enabling it to process and reason over entire code repositories or extensive documentation in a single pass.
Multimodal Power and Elite Performance
Upon its debut, Qwen3.8-Max established itself as a top-tier model, securing the #6 rank out of 218 models on the public benchlm.ai composite leaderboard with a score of 79.8 out of 100.Its capabilities are not limited to text; it features native support for processing text, images, video, and audio within a single, unified window.
Demonstrating its prowess in long-horizon agentic coding, an Alibaba report detailed a case where the model coded autonomously for 16 consecutive days on a real-world software project.
This sustained performance is a direct testament to the advanced agentic frameworks that allow models like Qwen3.8-Max to plan, execute, and self-correct over tasks that were previously unmanageable.
| Specification | Detail |
|---|---|
| Total Parameters | 2.4 trillion |
| Active Parameters | ~95 billion |
| Context Window | 1M tokens |
| Leaderboard Rank (Launch) | #6 of 218 on benchlm.ai composite (79.8/100) |
| Key Feature | First open-weight Qwen-Max-class model |
| Agentic Showcase | 16 days of autonomous coding on a real project |
12. Qwen3.8-27B: Frontier Agentic Coding on Consumer Hardware
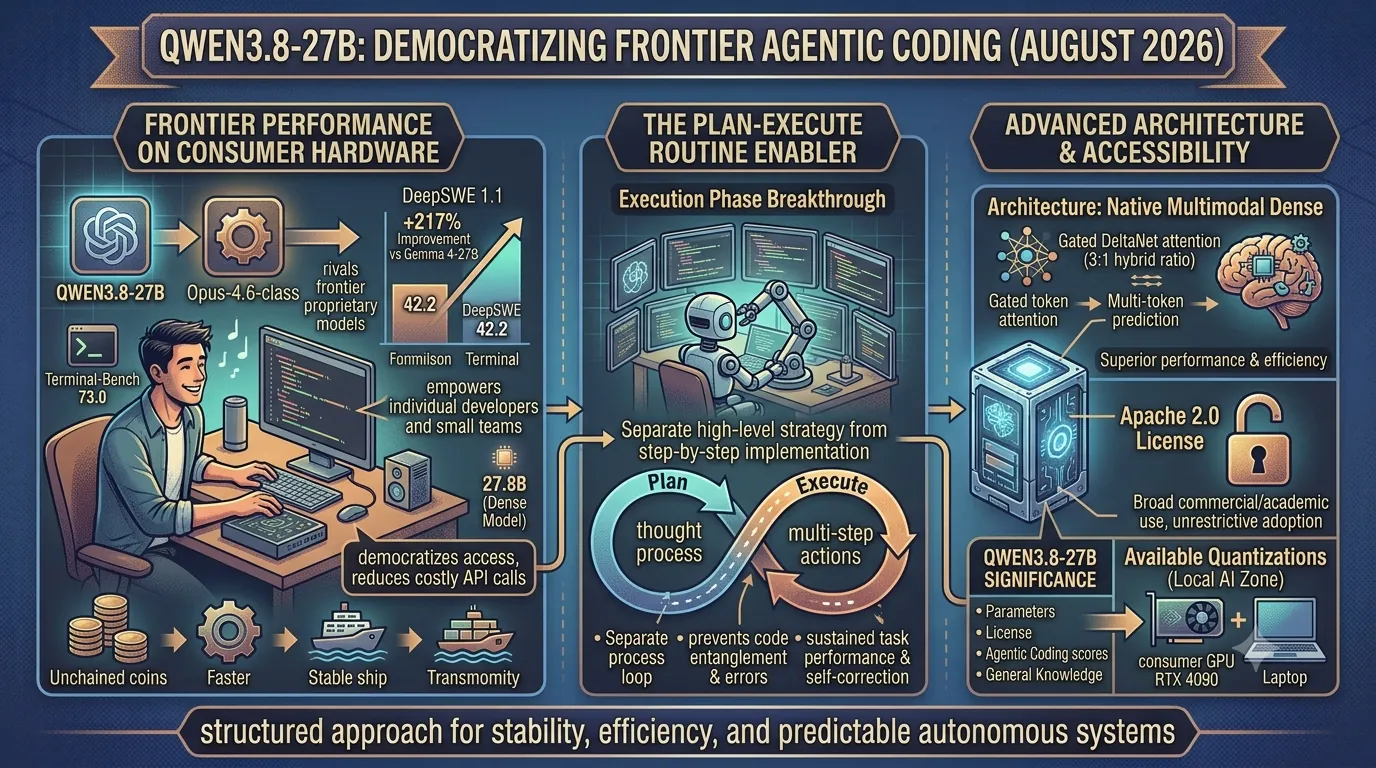
This section directly addresses the practical implementation of the article's core "Plan-Execute" routine by introducing a powerful, locally-runnable tool. While the main topic explores the conceptual separation of planning and execution in agentic coding to prevent errors, Qwen3.8-27B represents a breakthrough in the "Execution" phase. Its ability to deliver near-proprietary performance on consumer hardware empowers individual developers and small teams to build and refine sophisticated coding agents without relying on costly API calls, making the "Plan-Execute" model more accessible and financially viable than ever before.Released on August 14, 2026, Qwen3.8-27B has rapidly established itself as the new default recommendation for local agent workstations. This model democratizes access to agentic coding capabilities that were, until recently, the exclusive domain of large, proprietary systems.
Performance that Challenges the Proprietary Giants
Qwen3.8-27B delivers performance that rivals frontier proprietary models, a remarkable feat for a fully open model designed to run on consumer-grade hardware. Its agentic coding prowess is demonstrated by a score of 73.0 on Terminal-Bench and an impressive 42.2 on the DeepSWE 1.1 benchmark.To put its DeepSWE score into perspective, it represents a massive +217% improvement over the Gemma 4-27B model, signaling a significant leap forward in open-source code generation and manipulation. This level of performance brings near Opus-4.6-class agentic coding abilities into a compact 27.8B-parameter package. Beyond its specialized coding skills, the model is built on a solid foundation of general knowledge, achieving a score of approximately 78% on MMLU-Pro.
Architecture and Accessibility
The model's power stems from its advanced native multimodal dense architecture. It utilizes a Gated DeltaNet attention mechanism with a 3:1 hybrid ratio and incorporates multi-token prediction, allowing for more efficient and contextually aware processing. As a dense model with 27.8 billion parameters, it packs considerable capability into a manageable size.Crucially, Qwen3.8-27B is released under the permissive Apache 2.0 license, enabling broad use in both academic and commercial projects without restrictive licensing fees. Furthering its accessibility, a full range of quantizations are available on the Local AI Zone, ensuring developers can run the model efficiently on a variety of hardware configurations.
| Feature | Qwen3.8-27B Specification | Significance |
|---|---|---|
| Parameters | 27.8B (Dense Model) | Provides a powerful base for complex reasoning within a consumer hardware footprint. |
| License | Apache 2.0 | Allows for unrestricted commercial and private use, fostering widespread adoption. |
| Agentic Coding (DeepSWE 1.1) | 42.2 | Represents a +217% performance leap over the comparable Gemma 4-27B model. |
| Agentic Coding (Terminal-Bench) | 73.0 | High proficiency in complex, terminal-based software engineering tasks. |
| General Knowledge (MMLU-Pro) | ~78% | Strong general reasoning capabilities that support its specialized coding skills. |
| Architecture | Native multimodal dense with Gated DeltaNet attention | Advanced design enables superior performance and efficiency. |
13. DeepSeek V4-Pro-0813: Major Agent Upgrade and Competitive Pricing
This section connects directly to our main topic on agentic coding's 'Plan-Execute' routine by examining a critical underlying tool: the language model itself.The recent update to DeepSeek's V4-Pro model is not just an incremental improvement; it features a major agent upgrade, enhancing the very capabilities that allow AI agents to better comprehend complex tasks, formulate robust plans, and execute them with higher accuracy.
As we discuss separating planning from execution to prevent coding errors, the quality of the model driving that agent is paramount, and this update represents a significant step forward in that foundation.
Enhanced Agent Capabilities and General Availability
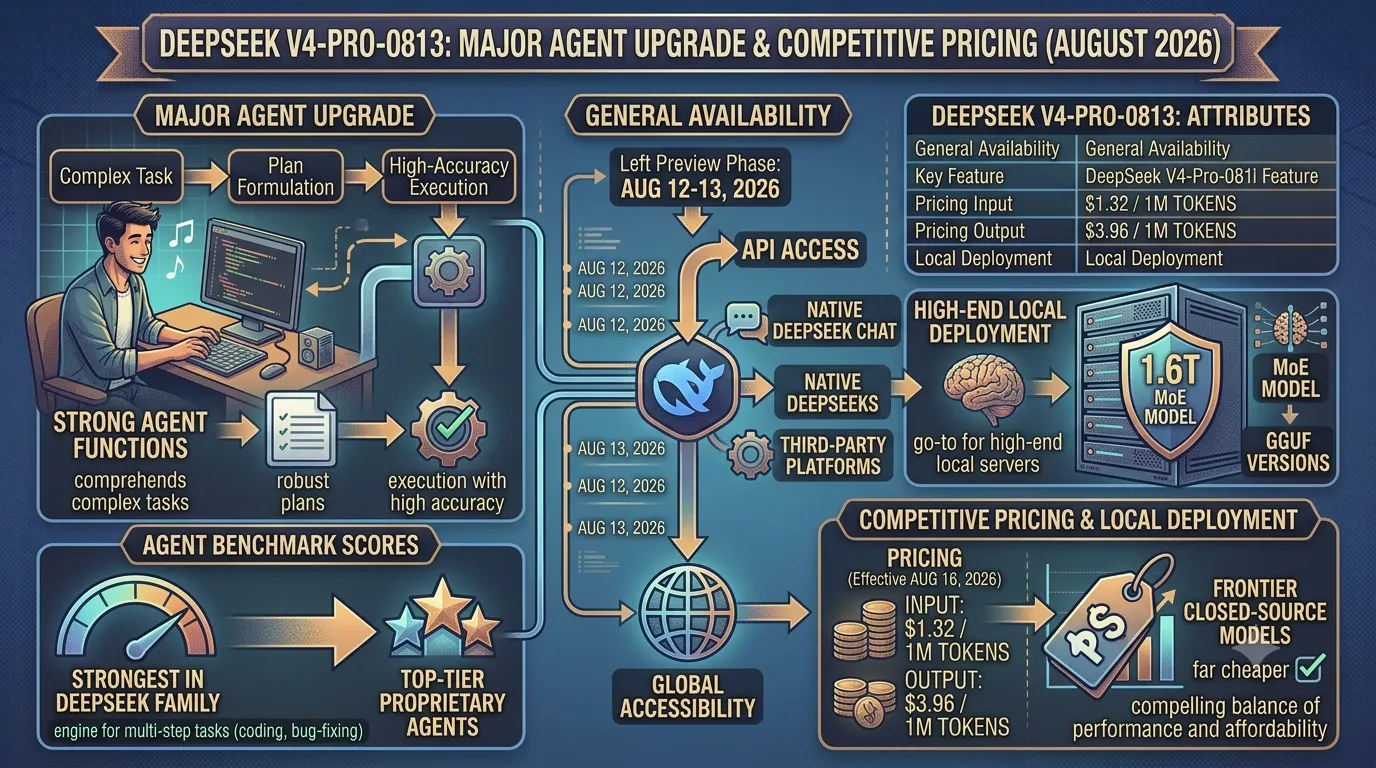
DeepSeek V4-Pro-0813 officially left its preview phase and reached general availability around August 12-13, 2026, making it accessible through its API, the native DeepSeek Chat interface, and various third-party platforms.The centerpiece of this release is a significant enhancement to its agentic functions.
Following the update, the model now posts the strongest agent-benchmark scores within the DeepSeek model family.
This improved performance is closing the gap on the top-tier proprietary agents, making it a more viable engine for complex, multi-step tasks like the coding and bug-fixing routines discussed in this article.
New Pricing and High-End Local Deployment
Coinciding with its general release, DeepSeek introduced a new pricing structure effective August 16, 2026.The rates are now set at $1.32 per million input tokens and $3.96 per million output tokens.
While this represents a price increase, the model maintains a strong competitive advantage; its cost remains far cheaper than that of frontier closed-source models, offering a compelling balance of performance and affordability for developers building agentic systems.
For those with dedicated hardware, the 1.6T Mixture-of-Experts (MoE) model continues to be a top choice, as its GGUF versions remain the go-to for high-end local server deployments.
| Attribute | Details |
|---|---|
| General Availability | Released from preview on August 12-13, 2026. Accessible via API, DeepSeek Chat, and third-party platforms. |
| Key Feature | Major agent upgrade, posting the strongest agent-benchmark scores in the DeepSeek family. |
| Pricing (Input Tokens) | $1.32 per 1 million tokens (Effective August 16, 2026). |
| Pricing (Output Tokens) | $3.96 per 1 million tokens (Effective August 16, 2026). |
| Local Deployment Option | GGUF versions of the 1.6T MoE model remain the standard for high-end local servers. |
14. Muse Glimmer 30B: Meta's Always-On Local Agent for Consumer GPUs
This section connects directly to our main theme of separating 'Plan' and 'Execute' cycles in agentic coding by introducing a foundational tool that makes such sophisticated, local workflows possible.Muse Glimmer 30B is not just another large model; it is an open-weights agent specifically engineered for the kind of autonomous, always-on operation on consumer hardware that advanced coding routines require.
An Open-Source Agent for the Desktop
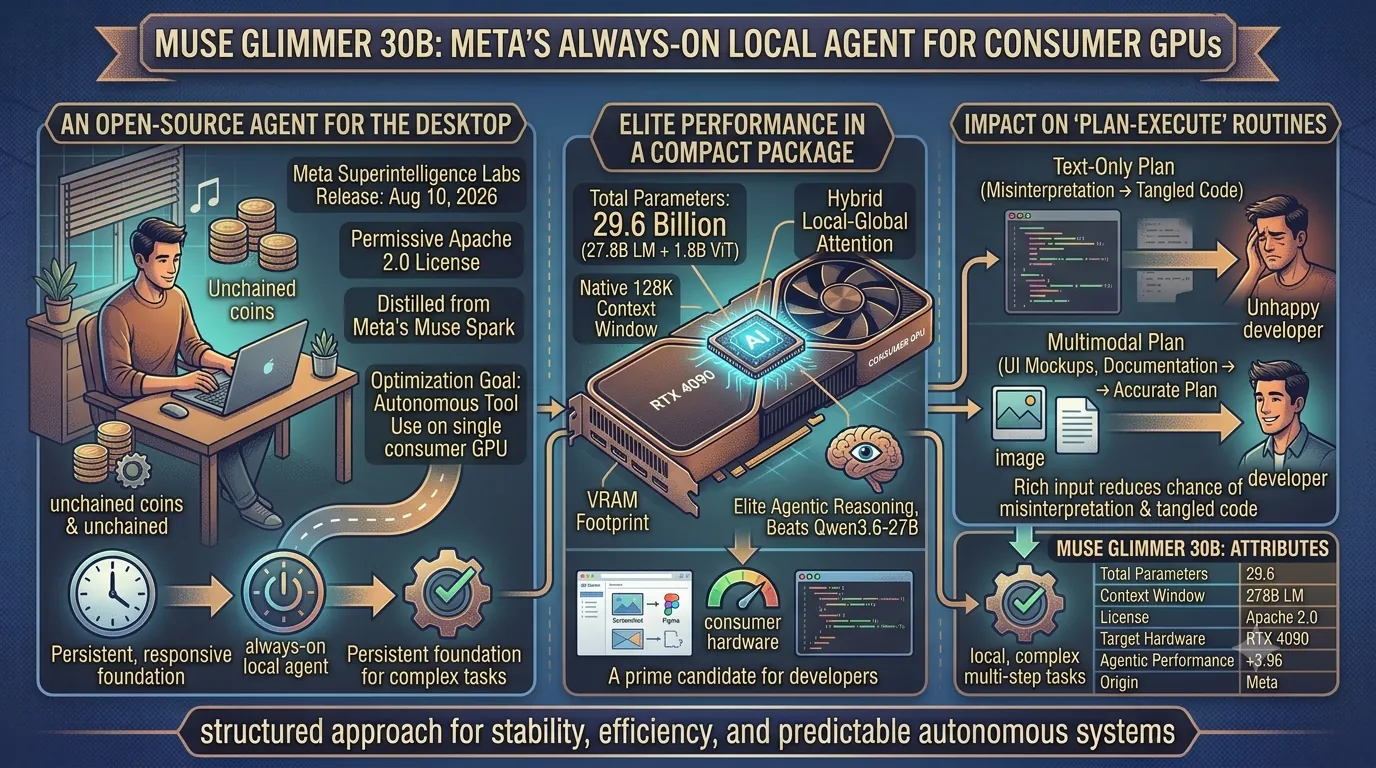
Meta Superintelligence Labs released Muse Glimmer 30B on August 10, 2026, establishing a new benchmark for accessible, high-performance local agents.Released under a permissive Apache 2.0 license, the model encourages widespread adoption and modification.
It was created by distilling the capabilities of the larger Muse Spark model, with a specific optimization goal: enabling autonomous tool use on a single consumer GPU.
This design focus aligns with its intended purpose as a "local agent that runs all the time," providing a persistent, responsive foundation for complex tasks without relying on cloud APIs.
Elite Performance in a Compact Package
Muse Glimmer 30B is a dense multimodal model with 29.6B parameters, composed of a 27.8B parameter language model and a 1.8B frozen ViT vision encoder.It boasts a native 128K context window, managed efficiently through a hybrid local-global attention mechanism, allowing it to process extensive codebases and documentation.
Crucially, its performance in agentic tasks surpasses that of its competitors, as it demonstrably beats Qwen3.6-27B on agentic benchmarks while maintaining a VRAM footprint small enough for consumer-grade hardware.
This combination of a large context, strong agentic reasoning, and hardware accessibility makes it a prime candidate for developers building next-generation coding assistants.
| Specification | Detail |
|---|---|
| Total Parameters | 29.6 Billion (27.8B LM + 1.8B ViT) |
| Context Window | 128K Native Context |
| License | Apache 2.0 (Open Weights) |
| Target Hardware | Optimized for one consumer GPU |
| Agentic Performance | Beats Qwen3.6-27B on relevant benchmarks |
| Origin | Distilled from Meta's Muse Spark |
15. Nemotron 3.5 Lightning: NVIDIA's Fast, Laptop-Deployable Agent Model
The effectiveness of an agentic "Plan-Execute" routine hinges on the underlying model's speed and contextual awareness.A sluggish model or one with a small context window can cripple a developer's workflow, making local code generation impractical.
NVIDIA's Nemotron 3.5 Lightning, released on August 11, 2026, directly addresses this bottleneck by providing a foundation for powerful agents that can run efficiently on a developer's local machine.
Engineered for On-Device Agentic Speed
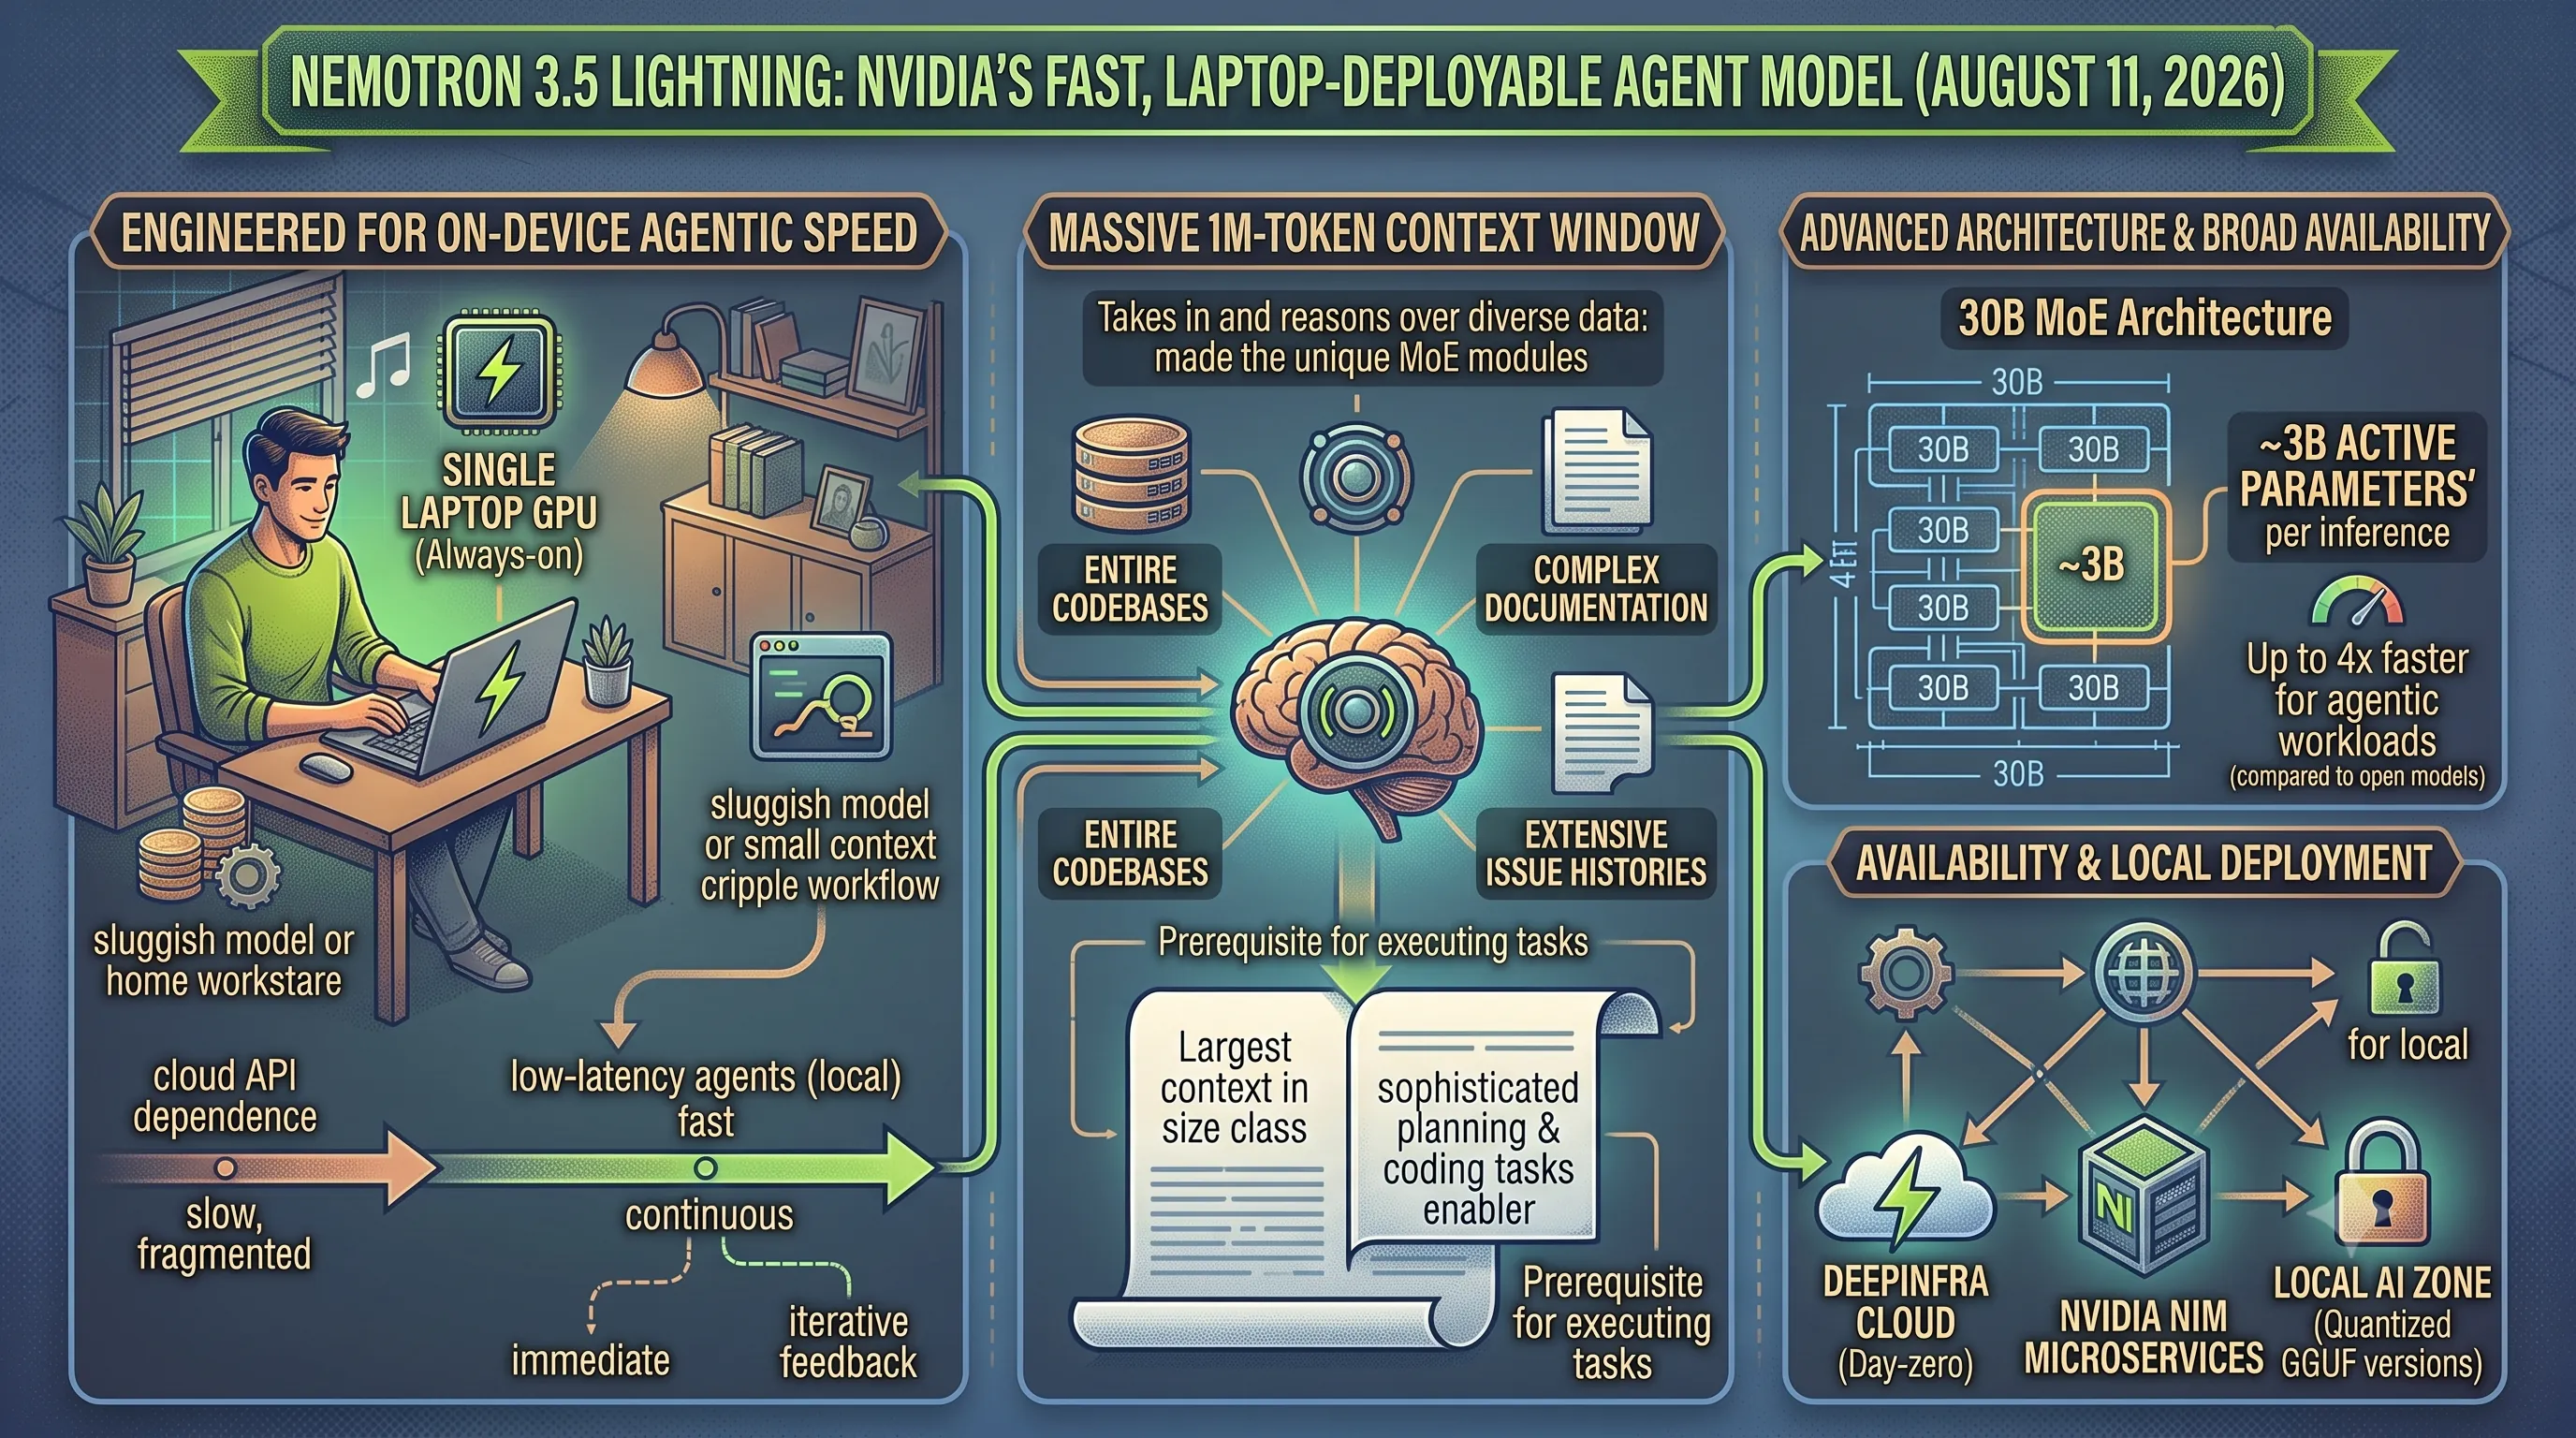
Nemotron 3.5 Lightning was specifically designed by NVIDIA to power always-on, low-latency agents that operate on a single laptop GPU.This focus on local deployment is critical for developers who need immediate, iterative feedback without relying on cloud APIs.
Architecturally, it is a 30B Mixture-of-Experts (MoE) model, but its efficiency comes from only activating approximately 3B parameters for any given task.
This MoE design allows it to deliver performance far beyond its active parameter count, achieving speeds up to 4x faster than comparable open models for agentic workloads.
Massive Context and Broad Availability
A standout feature is the model's 1M-token context window, the largest in its size class.This enormous capacity enables an agent to ingest and reason over entire codebases, complex documentation, or extensive issue histories—a prerequisite for executing sophisticated planning and coding tasks.
NVIDIA ensured wide accessibility from its launch, with day-zero availability on the DeepInfra cloud platform and through its own NVIDIA NIM inference microservices.
For local execution, quantized GGUF versions were also made immediately available on Local AI Zone, catering to the model's core audience of on-device AI developers.
| Feature | Specification |
|---|---|
| Model Type | 30B Mixture-of-Experts (MoE) |
| Active Parameters | ~3B per inference |
| Context Window | 1,000,000 tokens |
| Performance Target | Up to 4x faster for agentic workloads |
| Primary Use Case | Always-on, low-latency agents on a single laptop GPU |
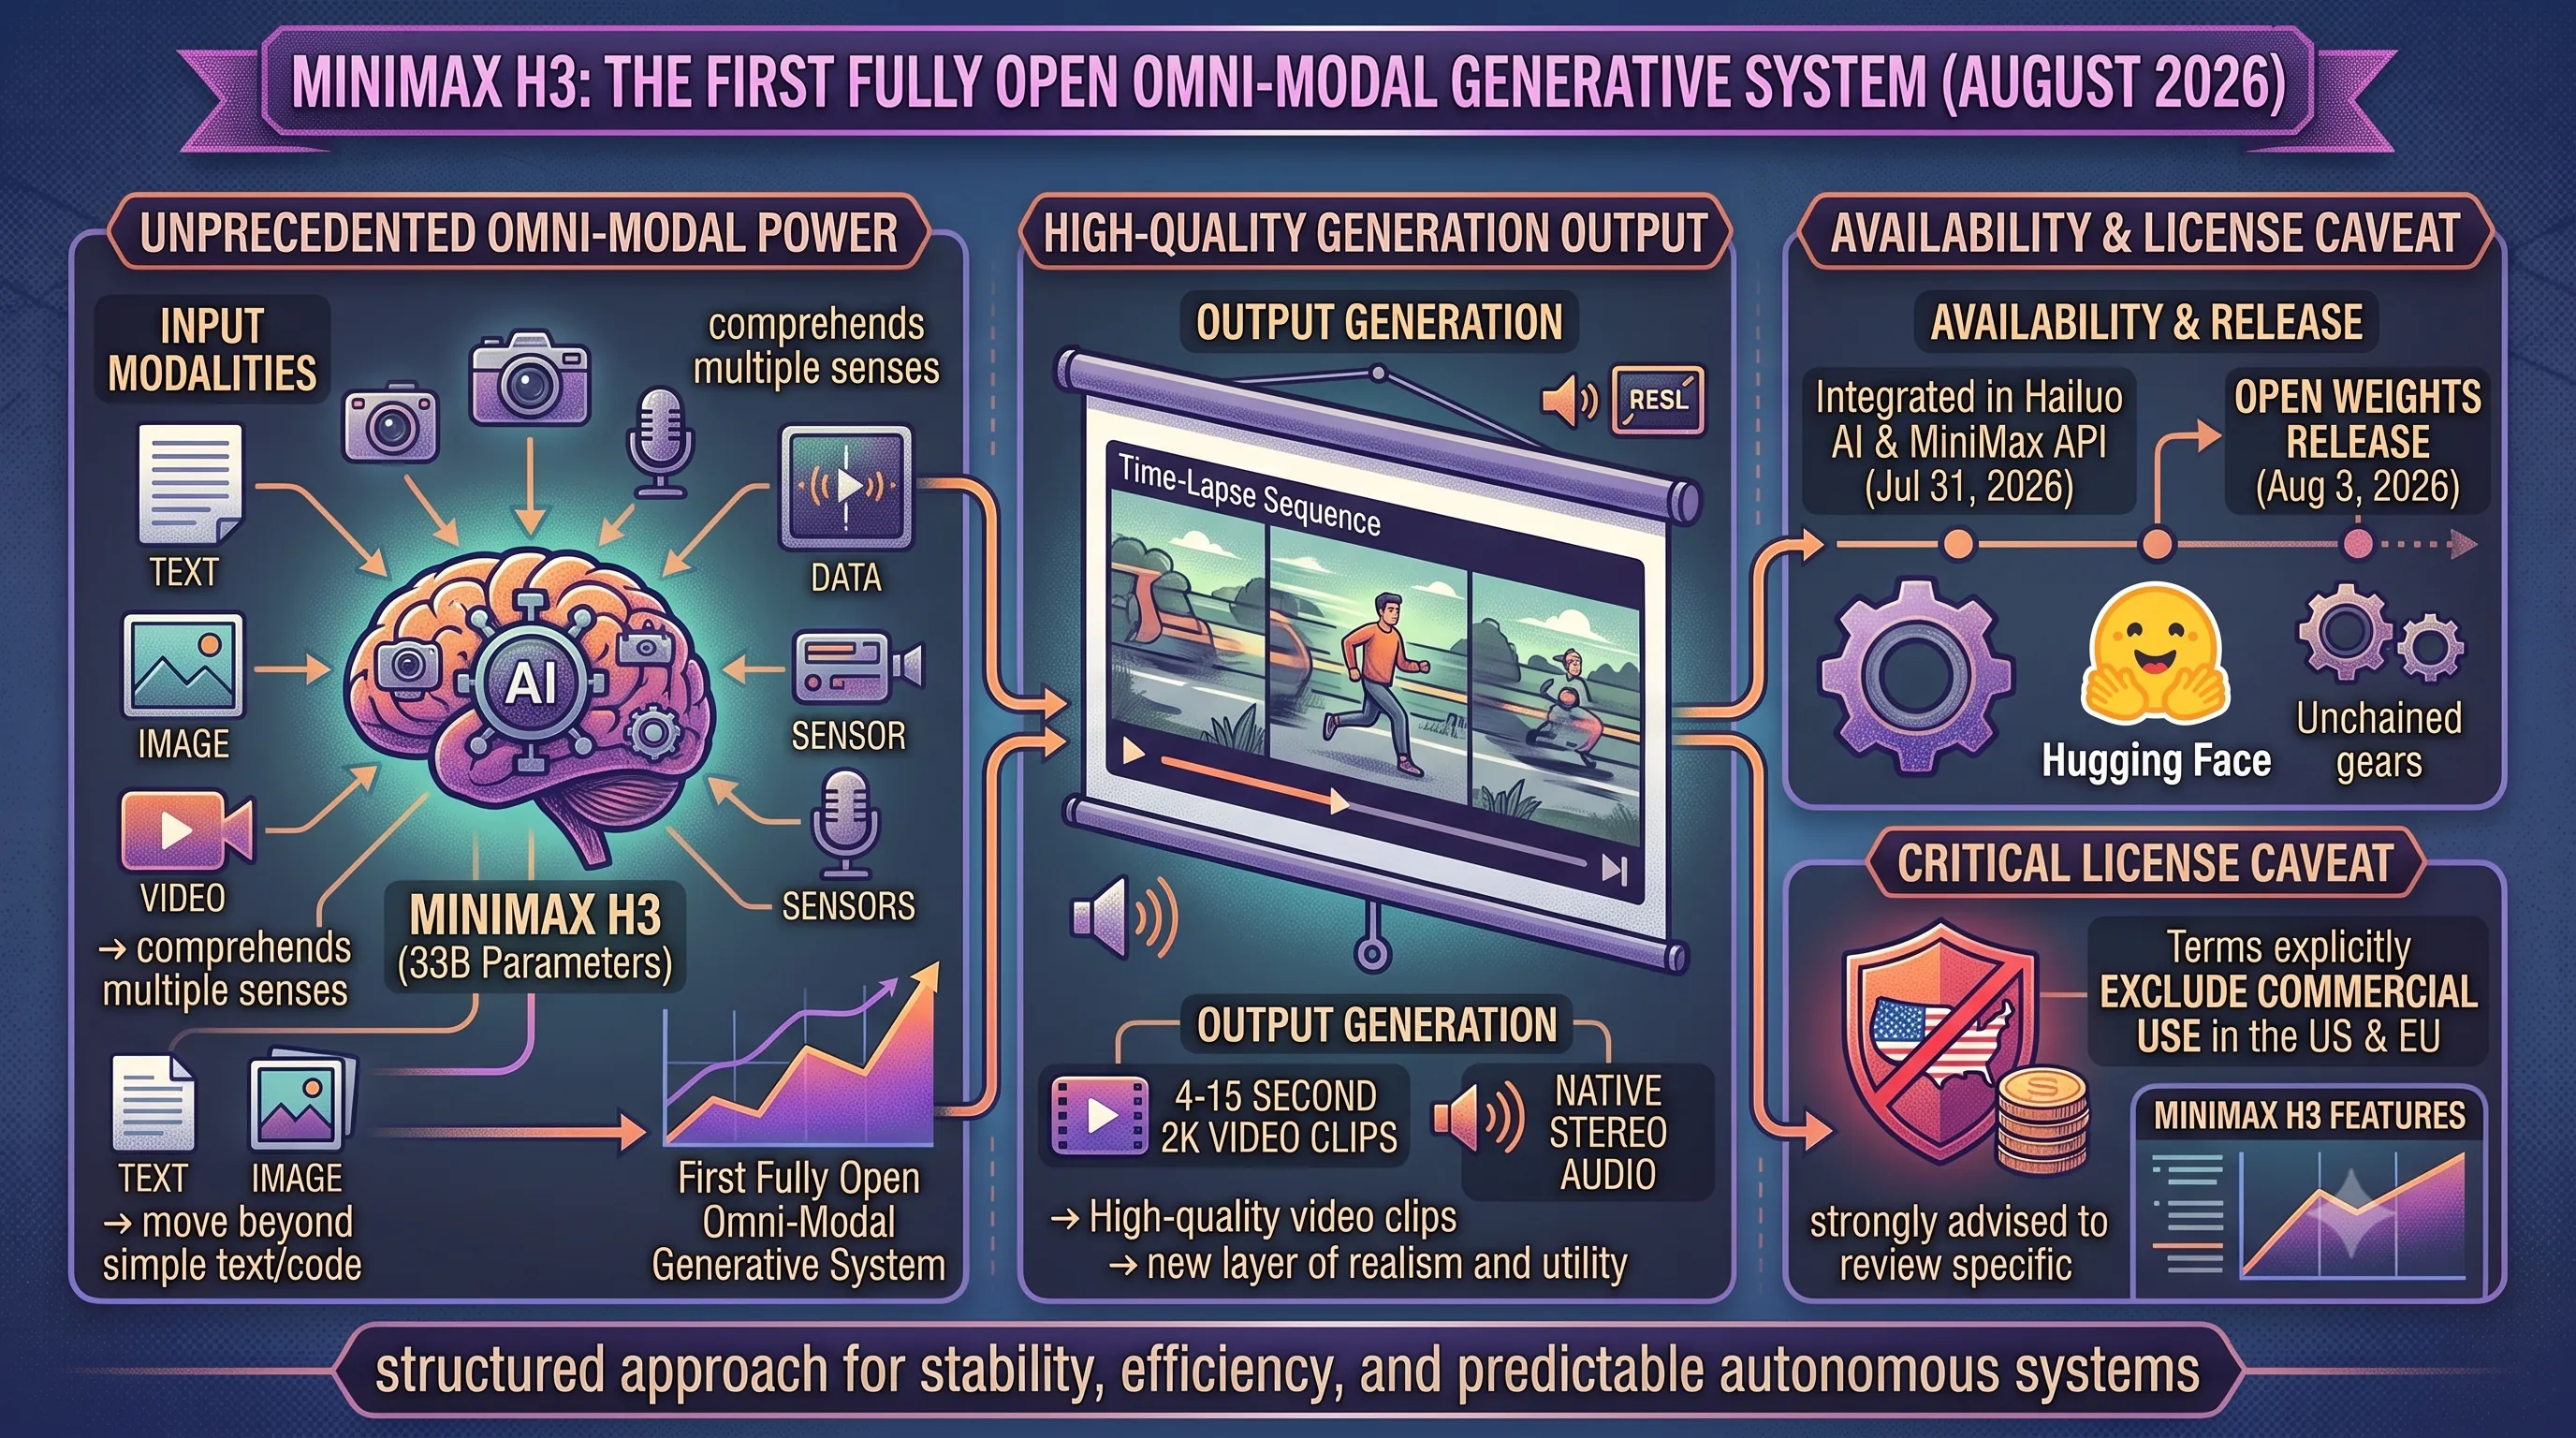
16. MiniMax H3: The First Fully Open Omni-Modal Generative System
The sophisticated 'Plan-Execute' routine in agentic coding relies on powerful, accessible foundation models to carry out its complex tasks.The recent release of models like MiniMax H3 exemplifies this crucial trend, providing the advanced multi-sensory tools that enable these agents to move beyond simple text and code, and into complex, real-world data environments.
MiniMax's H3 model marks a significant milestone as the industry's first fully open omni-modal generative system.
This system possesses the capability to understand a wide range of inputs, including text, image, and video.
Its generative power is particularly notable, as it can create video clips complete with native stereo audio, a feature that adds a new layer of realism and utility.
The model, which is built on 33B parameters, was made available to the public through an open weights release on Hugging Face on August 3, 2026.
Prior to its open release, it had already been integrated and made live in the Hailuo AI application and the MiniMax API since July 31.
The model can generate high-quality, 4-15 second video clips at a 2K resolution, making it a powerful tool for developers and creators.
However, potential users must be aware of a critical license caveat: its terms explicitly exclude commercial use in the US and EU.
Anyone planning to leverage the model is strongly advised to review the specific license terms to ensure compliance.
| Feature | Specification |
|---|---|
| Model Type | First fully open omni-modal generative system |
| Parameters | 33B |
| Input Modalities | Text, Image, Video |
| Output Generation | 4-15 second 2K video clips with native stereo audio |
| Open Weights Release | August 3, 2026 (on Hugging Face) |
| License Caveat | Excludes commercial use in the US/EU |
17. Microsoft MAI-Thinking-1: Cost-Efficient Reasoning for Enterprise
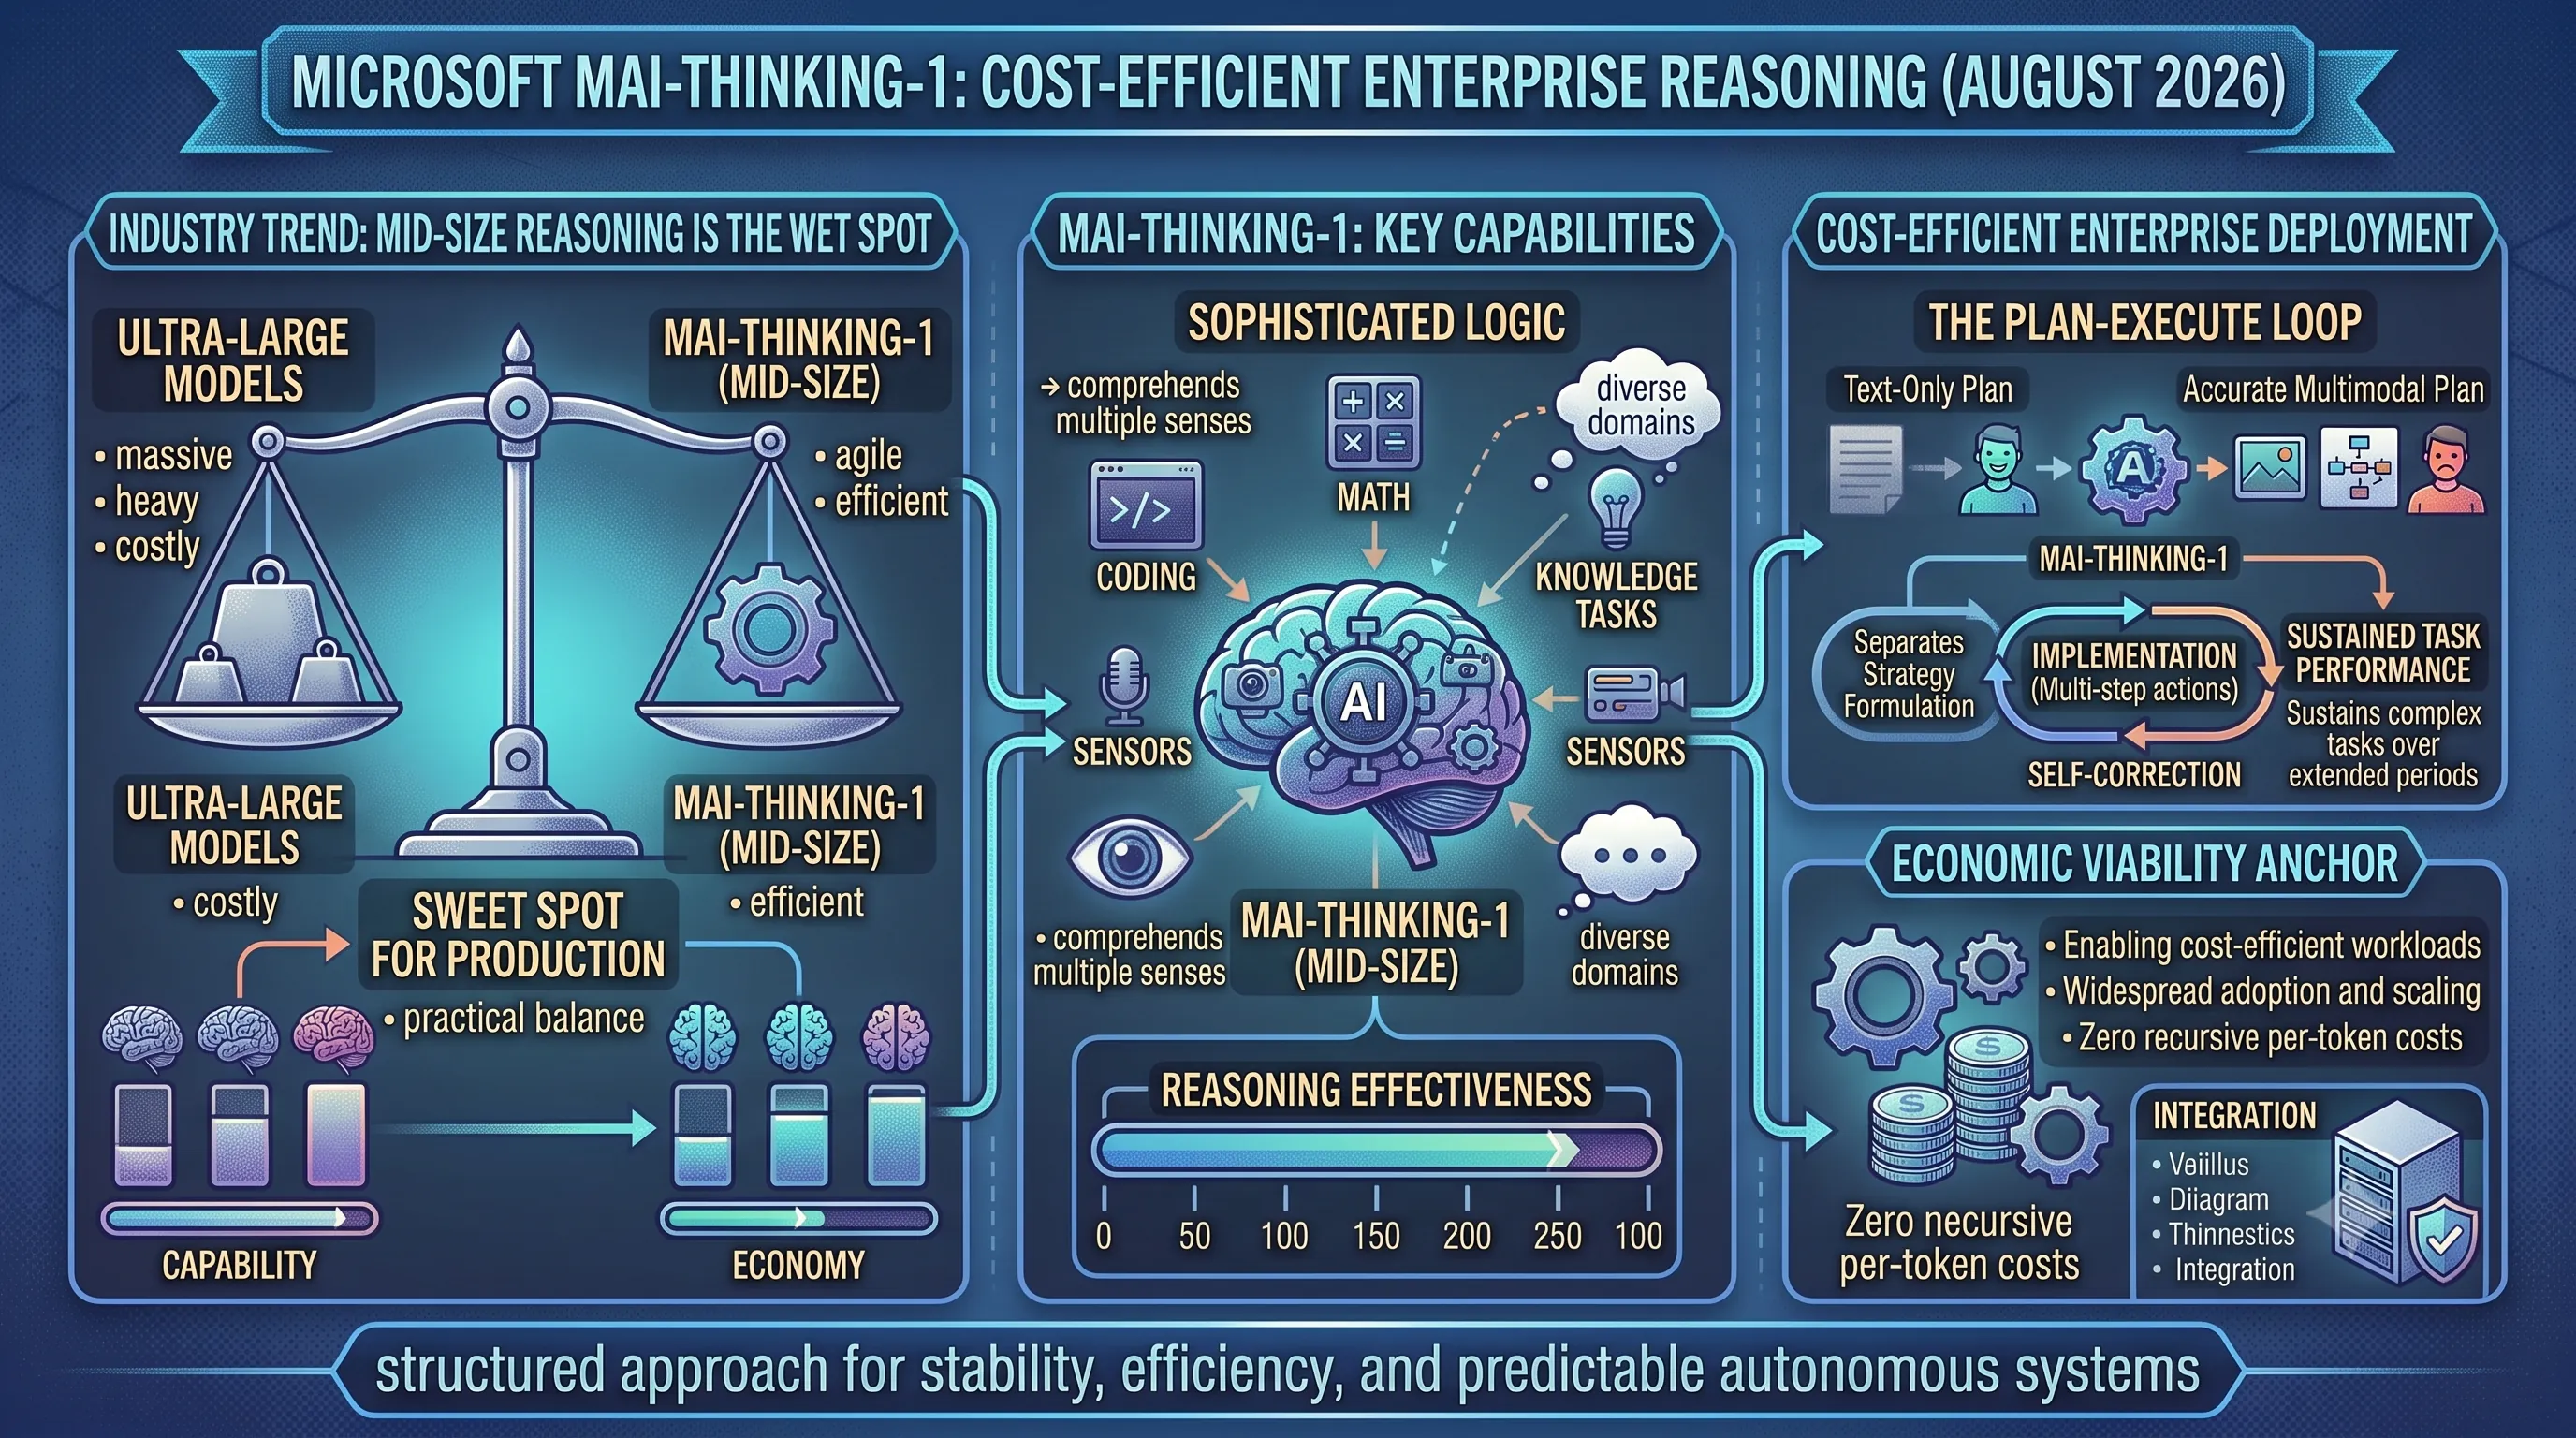
The "Plan-Execute" loop central to modern agentic coding depends heavily on a model's ability to reason effectively during the planning stage, but deploying the largest, most expensive models for this task is often unfeasible in a corporate environment.Microsoft's recent release addresses this challenge directly with MAI-Thinking-1, which became available on August 13, 2026.
As a new entry in the growing Microsoft MAI family, this model is positioned as a medium-sized reasoning model.
Its primary target is enabling cost-efficient enterprise workloads that require sophisticated logic across diverse domains, including coding, math, and knowledge tasks.
The launch of MAI-Thinking-1 is significant as it provides the latest evidence for an important industry trend: mid-size reasoning models are emerging as the sweet spot for production environments, offering a practical balance between advanced capability and economic viability.
18. OX Alpha: The Anonymous Challenger Outperforming GPT-5.6 on Coding
The reliability of any agentic coding system, particularly one built on a 'Plan-Execute' loop, is fundamentally limited by the capabilities of its underlying Large Language Model.The 'Execute' phase demands a model that can not only understand complex instructions and context but also generate flawless, efficient code.
The recent emergence of a mysterious and powerful new model, OX Alpha, represents a potential paradigm shift in the power of this execution step, promising to significantly reduce the kind of code tangling our main topic addresses.
A New Benchmark in Coding Performance
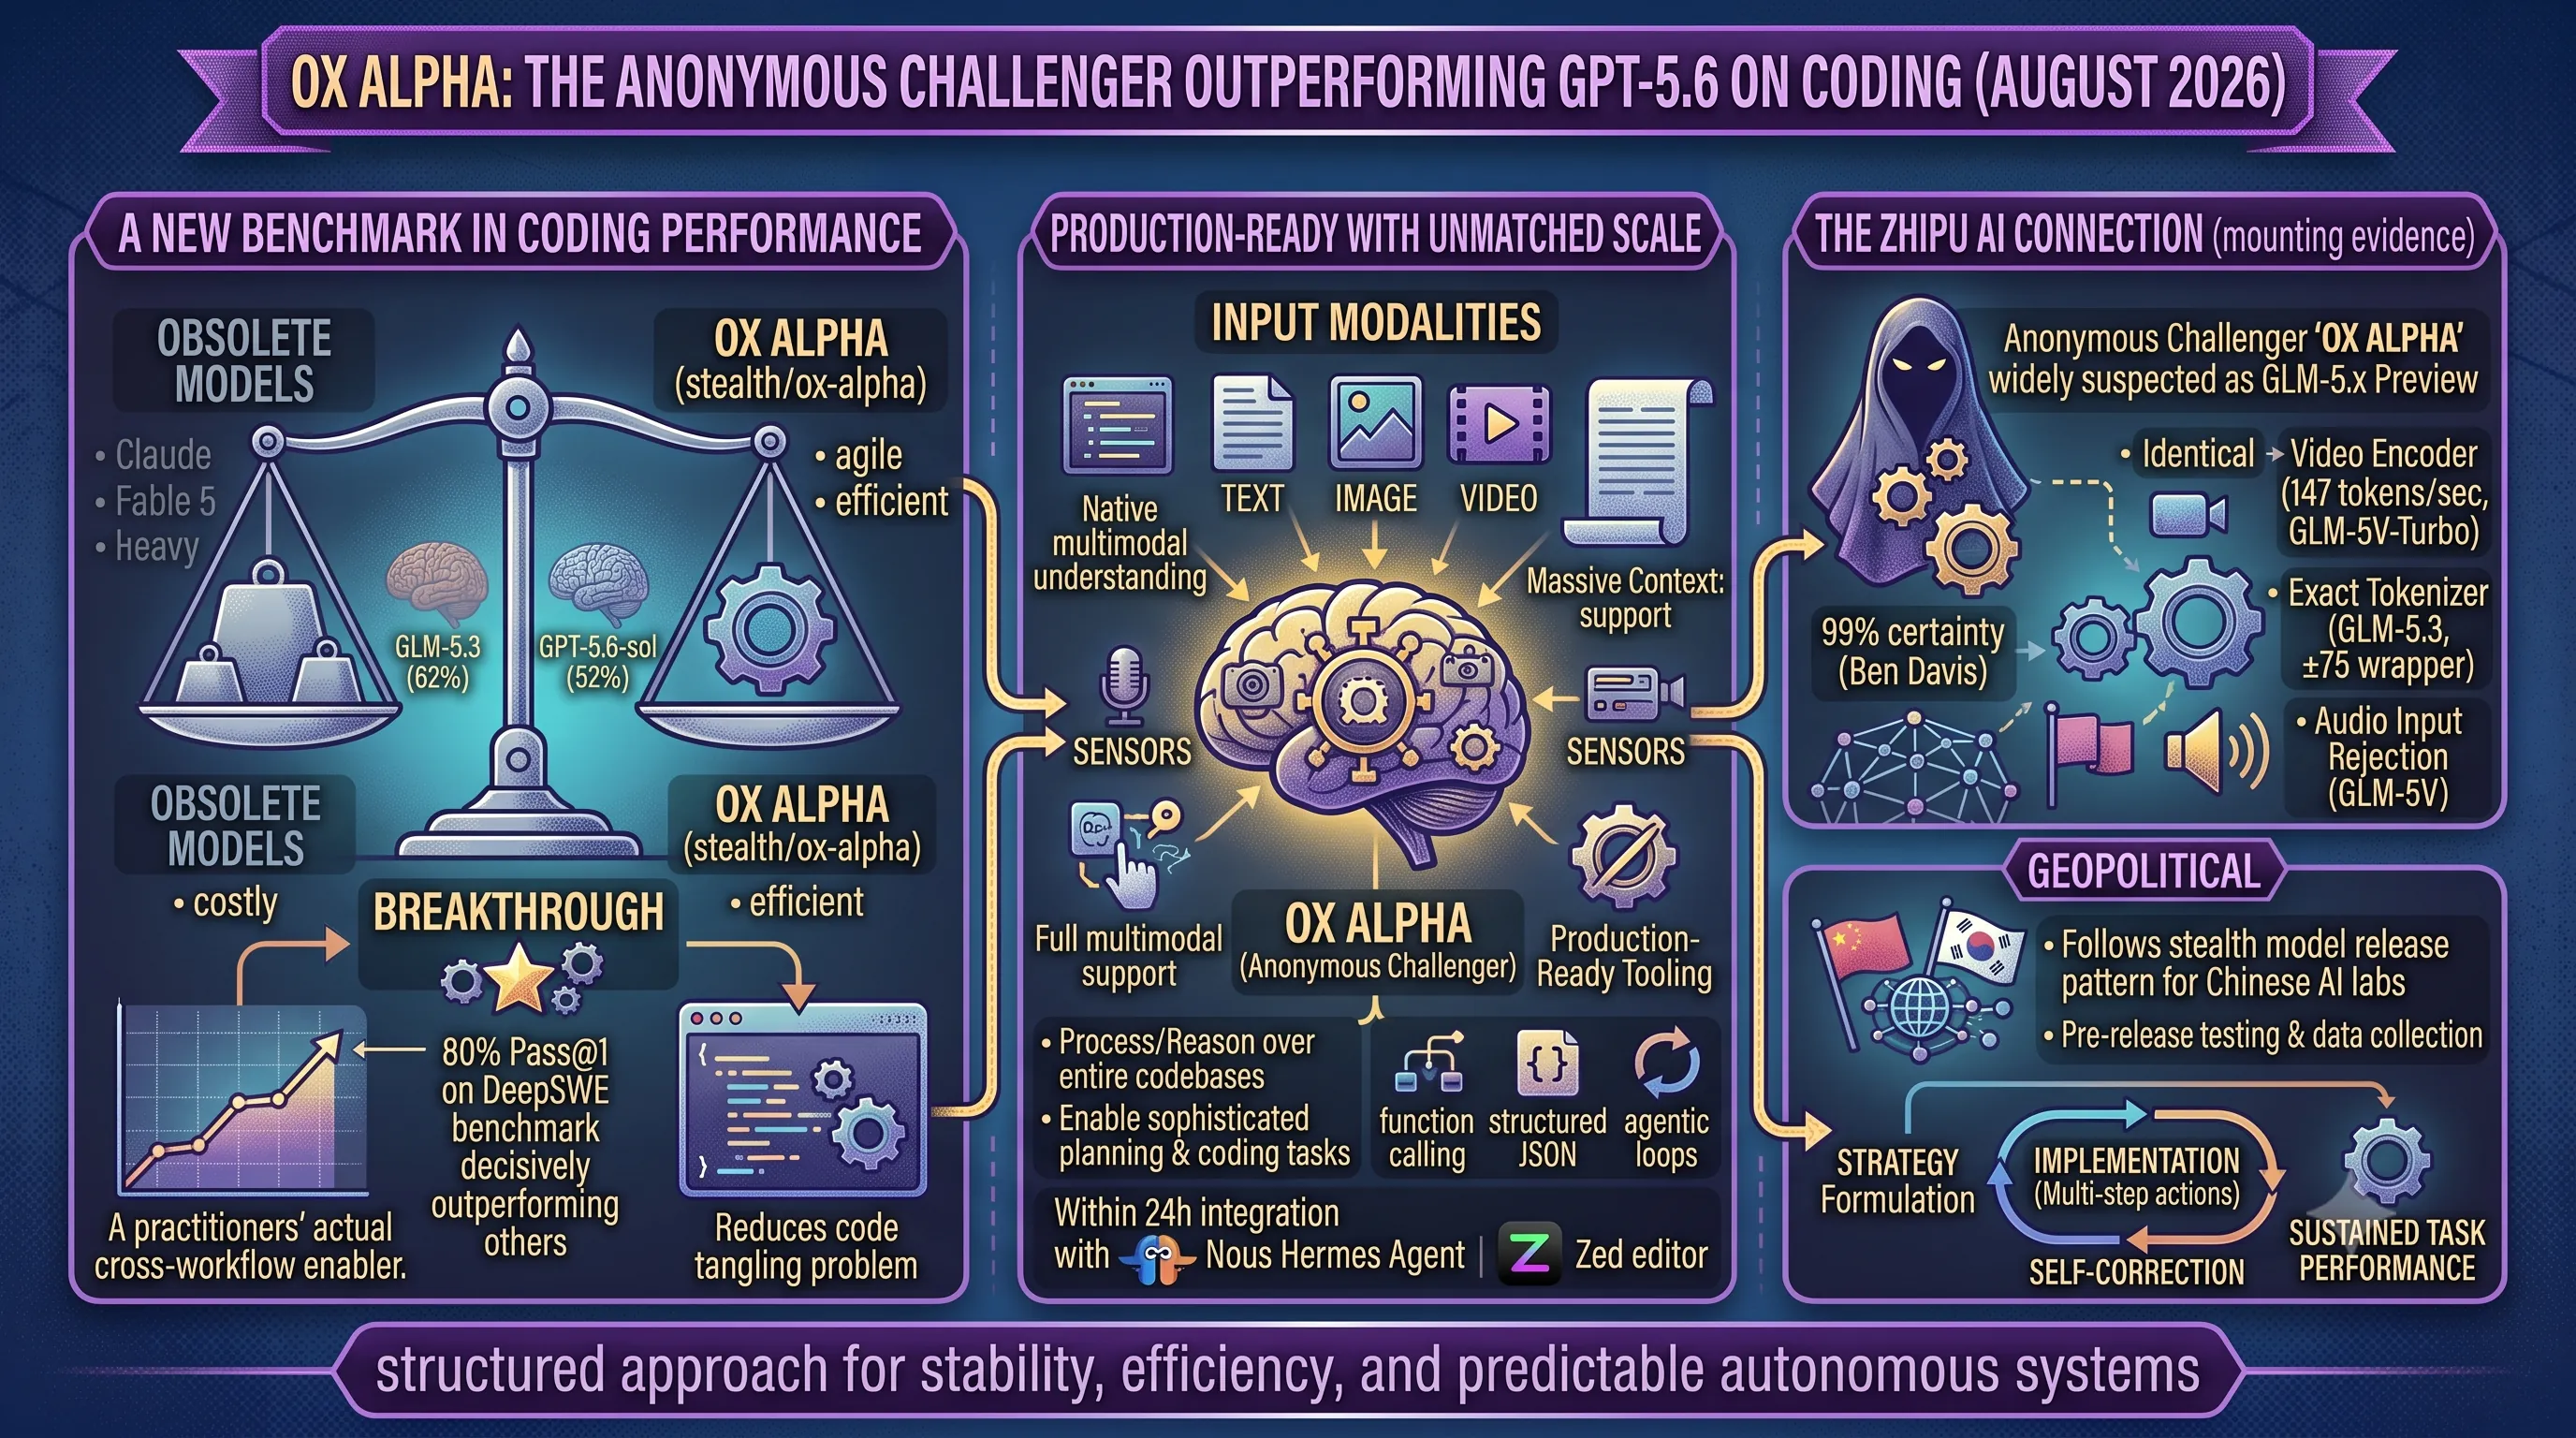
On August 20, 2026, a new anonymous model designated "stealth/ox-alpha" appeared on the OpenRouter platform, offered with zero pricing during a one-week preview period.This model immediately demonstrated extraordinary capabilities, most notably in the domain of software engineering.
It achieved a groundbreaking 80% Pass@1 on the DeepSWE benchmark, a complex test of a model's ability to autonomously resolve real-world GitHub issues.
This score established a new state-of-the-art, decisively outperforming all established industry leaders.
The performance gap is significant, highlighting a major leap in autonomous coding proficiency.
| Model | DeepSWE Pass@1 Score |
|---|---|
| OX Alpha | 80% |
| Claude Fable 5 | 65% |
| GLM-5.3 | 62% |
| GPT-5.6-sol | 52% |
Production-Ready with Unmatched Scale
Beyond its benchmark scores, OX Alpha's technical specifications position it as a uniquely powerful tool for complex agentic workflows.It features a massive 1,048,576-token context window, among the largest available, allowing it to process and reason over entire codebases in a single pass.
This is complemented by a maximum output of 131K tokens, enabling the generation of extensive and complete software components.
The model also boasts full multimodal support, capable of native understanding of text, images, and video streams.
Crucially, it was released with production-ready tooling, including robust function calling, structured JSON output, and native support for agentic loops.
This readiness was so apparent that within just 24 hours of its appearance, OX Alpha was integrated into both the Nous Research Hermes Agent and the popular Zed code editor.
The Zhipu AI Connection
While officially anonymous, mounting technical evidence has led to a strong consensus on the model's origin.Independent researcher Ben Davis reported 99% certainty that OX Alpha belongs to Zhipu AI's unreleased GLM-5.x multimodal flagship series.
This attribution is supported by several key similarities to known Zhipu models.
OX Alpha's video encoder token consumption is identical to that of GLM-5V-Turbo (147 tokens/sec, frame-rate independent), and its tokenizer shows an exact alignment with GLM-5.3, differing only by a negligible ±75 token wrapper.
Further behavioral tells, such as an emoji usage pattern (~1.3 per 1K characters) matching the GLM/Qwen series and an audio input rejection behavior identical to GLM-5V, strengthen the connection.
This "stealth model" release follows an established pattern for Chinese AI labs, who often use anonymous public previews for pre-release testing and data collection.
While official confirmation is still pending, the evidence strongly suggests OX Alpha is a preview of a ~744B total parameter (~40B active) MoE architecture that is set to formally enter the market.
19. Gemini 3.7 Flash: Google's Intelligent Workhorse for Coding and Agents
This section connects directly to the main article's theme of a "Plan-Execute" routine in agentic coding.While other parts of the agent handle the high-level 'Plan', Gemini 3.7 Flash represents a powerful new tool for the 'Execute' phase.
Its combination of improved coding accuracy, large context, and tunable, budget-conscious pricing makes it a prime candidate for the workhorse component that translates plans into clean, functional code, reducing the risk of the "tangled code" problem.
A Leap in Performance and Coding Accuracy
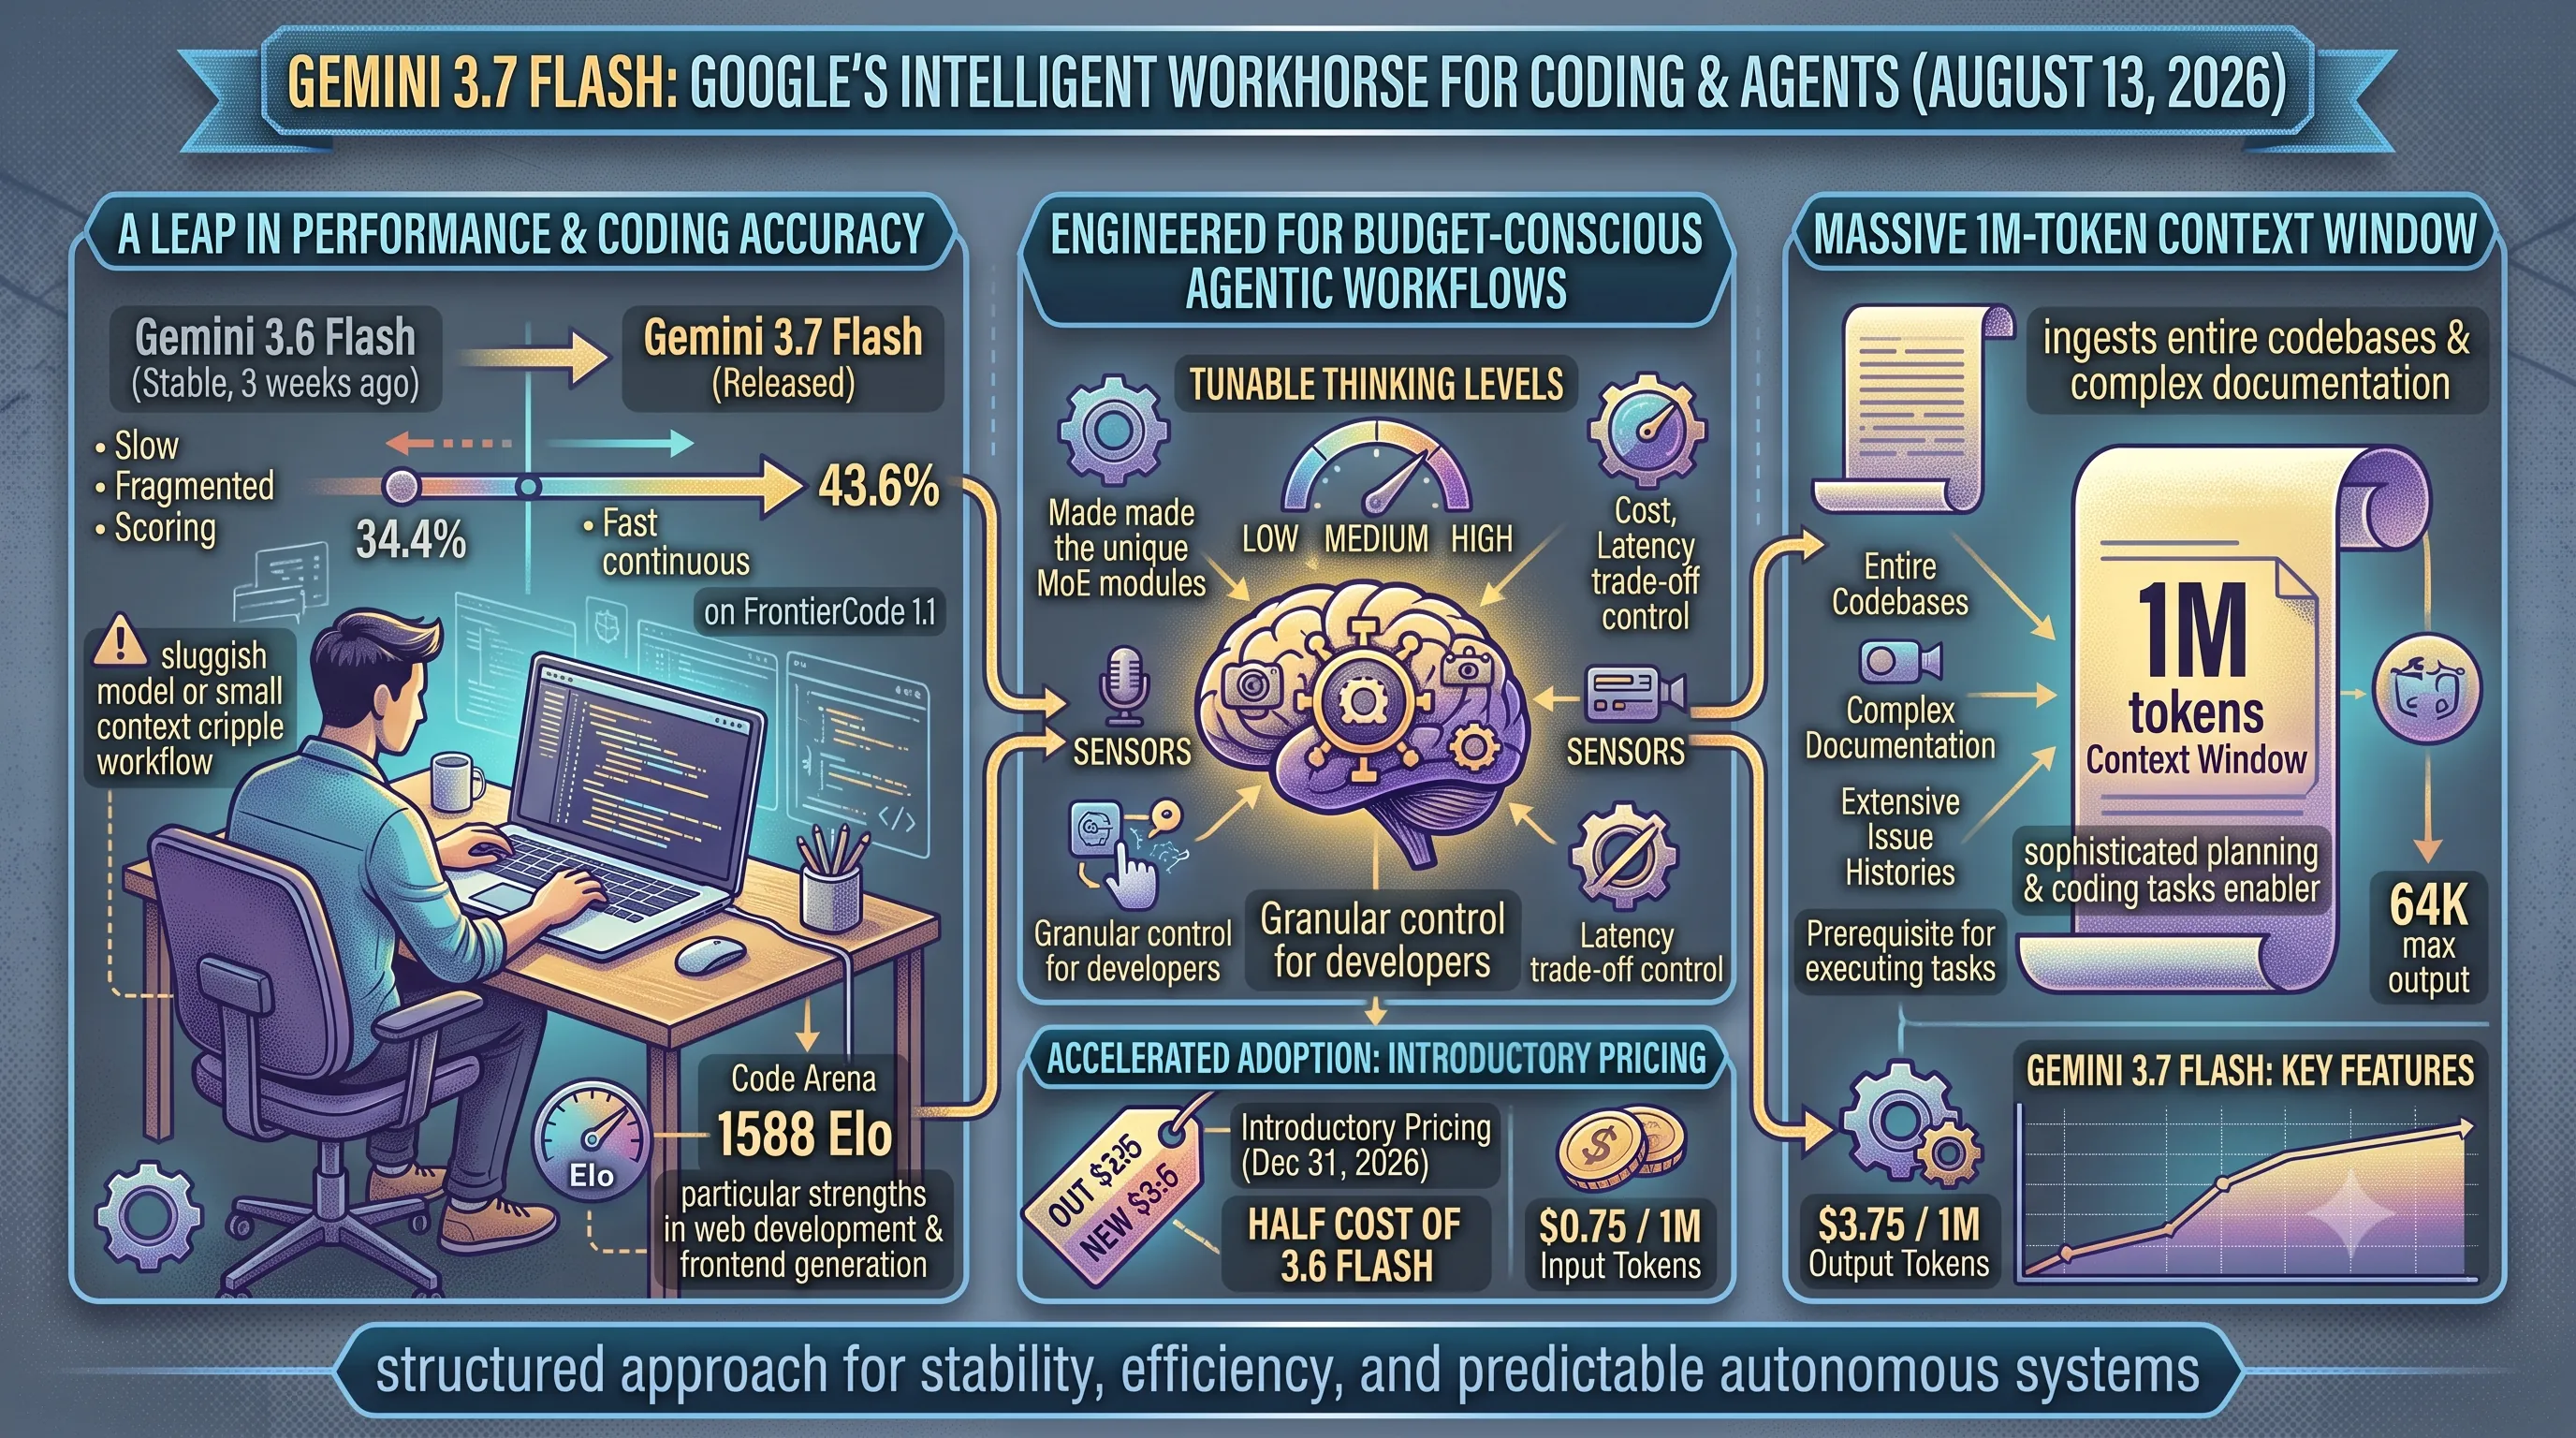
Released by Google on August 13, 2026, just three weeks after its predecessor went stable, Gemini 3.7 Flash was introduced as "our most intelligent workhorse model yet for coding and agents."This new version delivered major gains in code generation, showing substantial improvement in first-pass code accuracy.
Its prowess is quantified by a significant jump on the FrontierCode 1.1 Main benchmark, scoring 43.6%, a notable increase from the 34.4% achieved by Gemini 3.6 Flash.
Further cementing its capabilities, the model achieved a 1588 Elo on Code Arena, demonstrating strong performance in competitive coding scenarios, with particular strengths noted in web development and frontend generation.
Engineered for Budget-Conscious Agentic Workflows
Google has clearly positioned Gemini 3.7 Flash as the go-to model for agentic coding workflows where quality is critical but budgets are tight.A key innovation supporting this is the introduction of tunable thinking levels (low, medium, and high), which grant developers granular control over the trade-offs between response quality, cost, and latency for any given task.
This is crucial for agentic systems that may perform a mix of simple and complex operations.
The model’s architecture is built to handle large-scale tasks, featuring a massive 1M-token context window and a 64K max output, allowing it to ingest and generate entire codebases or complex documentation.
To accelerate adoption, Google launched the model with an aggressive introductory pricing scheme of $0.75 per 1M input tokens and $3.75 per 1M output tokens, which is half the original cost of 3.6 Flash and is available through December 31, 2026.
| Specification | Gemini 3.7 Flash Details |
|---|---|
| Developer | |
| Release Date | August 13, 2026 |
| Context Window | 1M tokens |
| Max Output Tokens | 64K tokens |
| Coding Benchmark (FrontierCode 1.1) | 43.6% |
| Code Arena Elo | 1588 |
| Introductory Pricing (per 1M tokens) | $0.75 (input) / $3.75 (output) |
20. Meta Muse Code & Spark 1.2: Multi-Agent Coordination and Open Weights
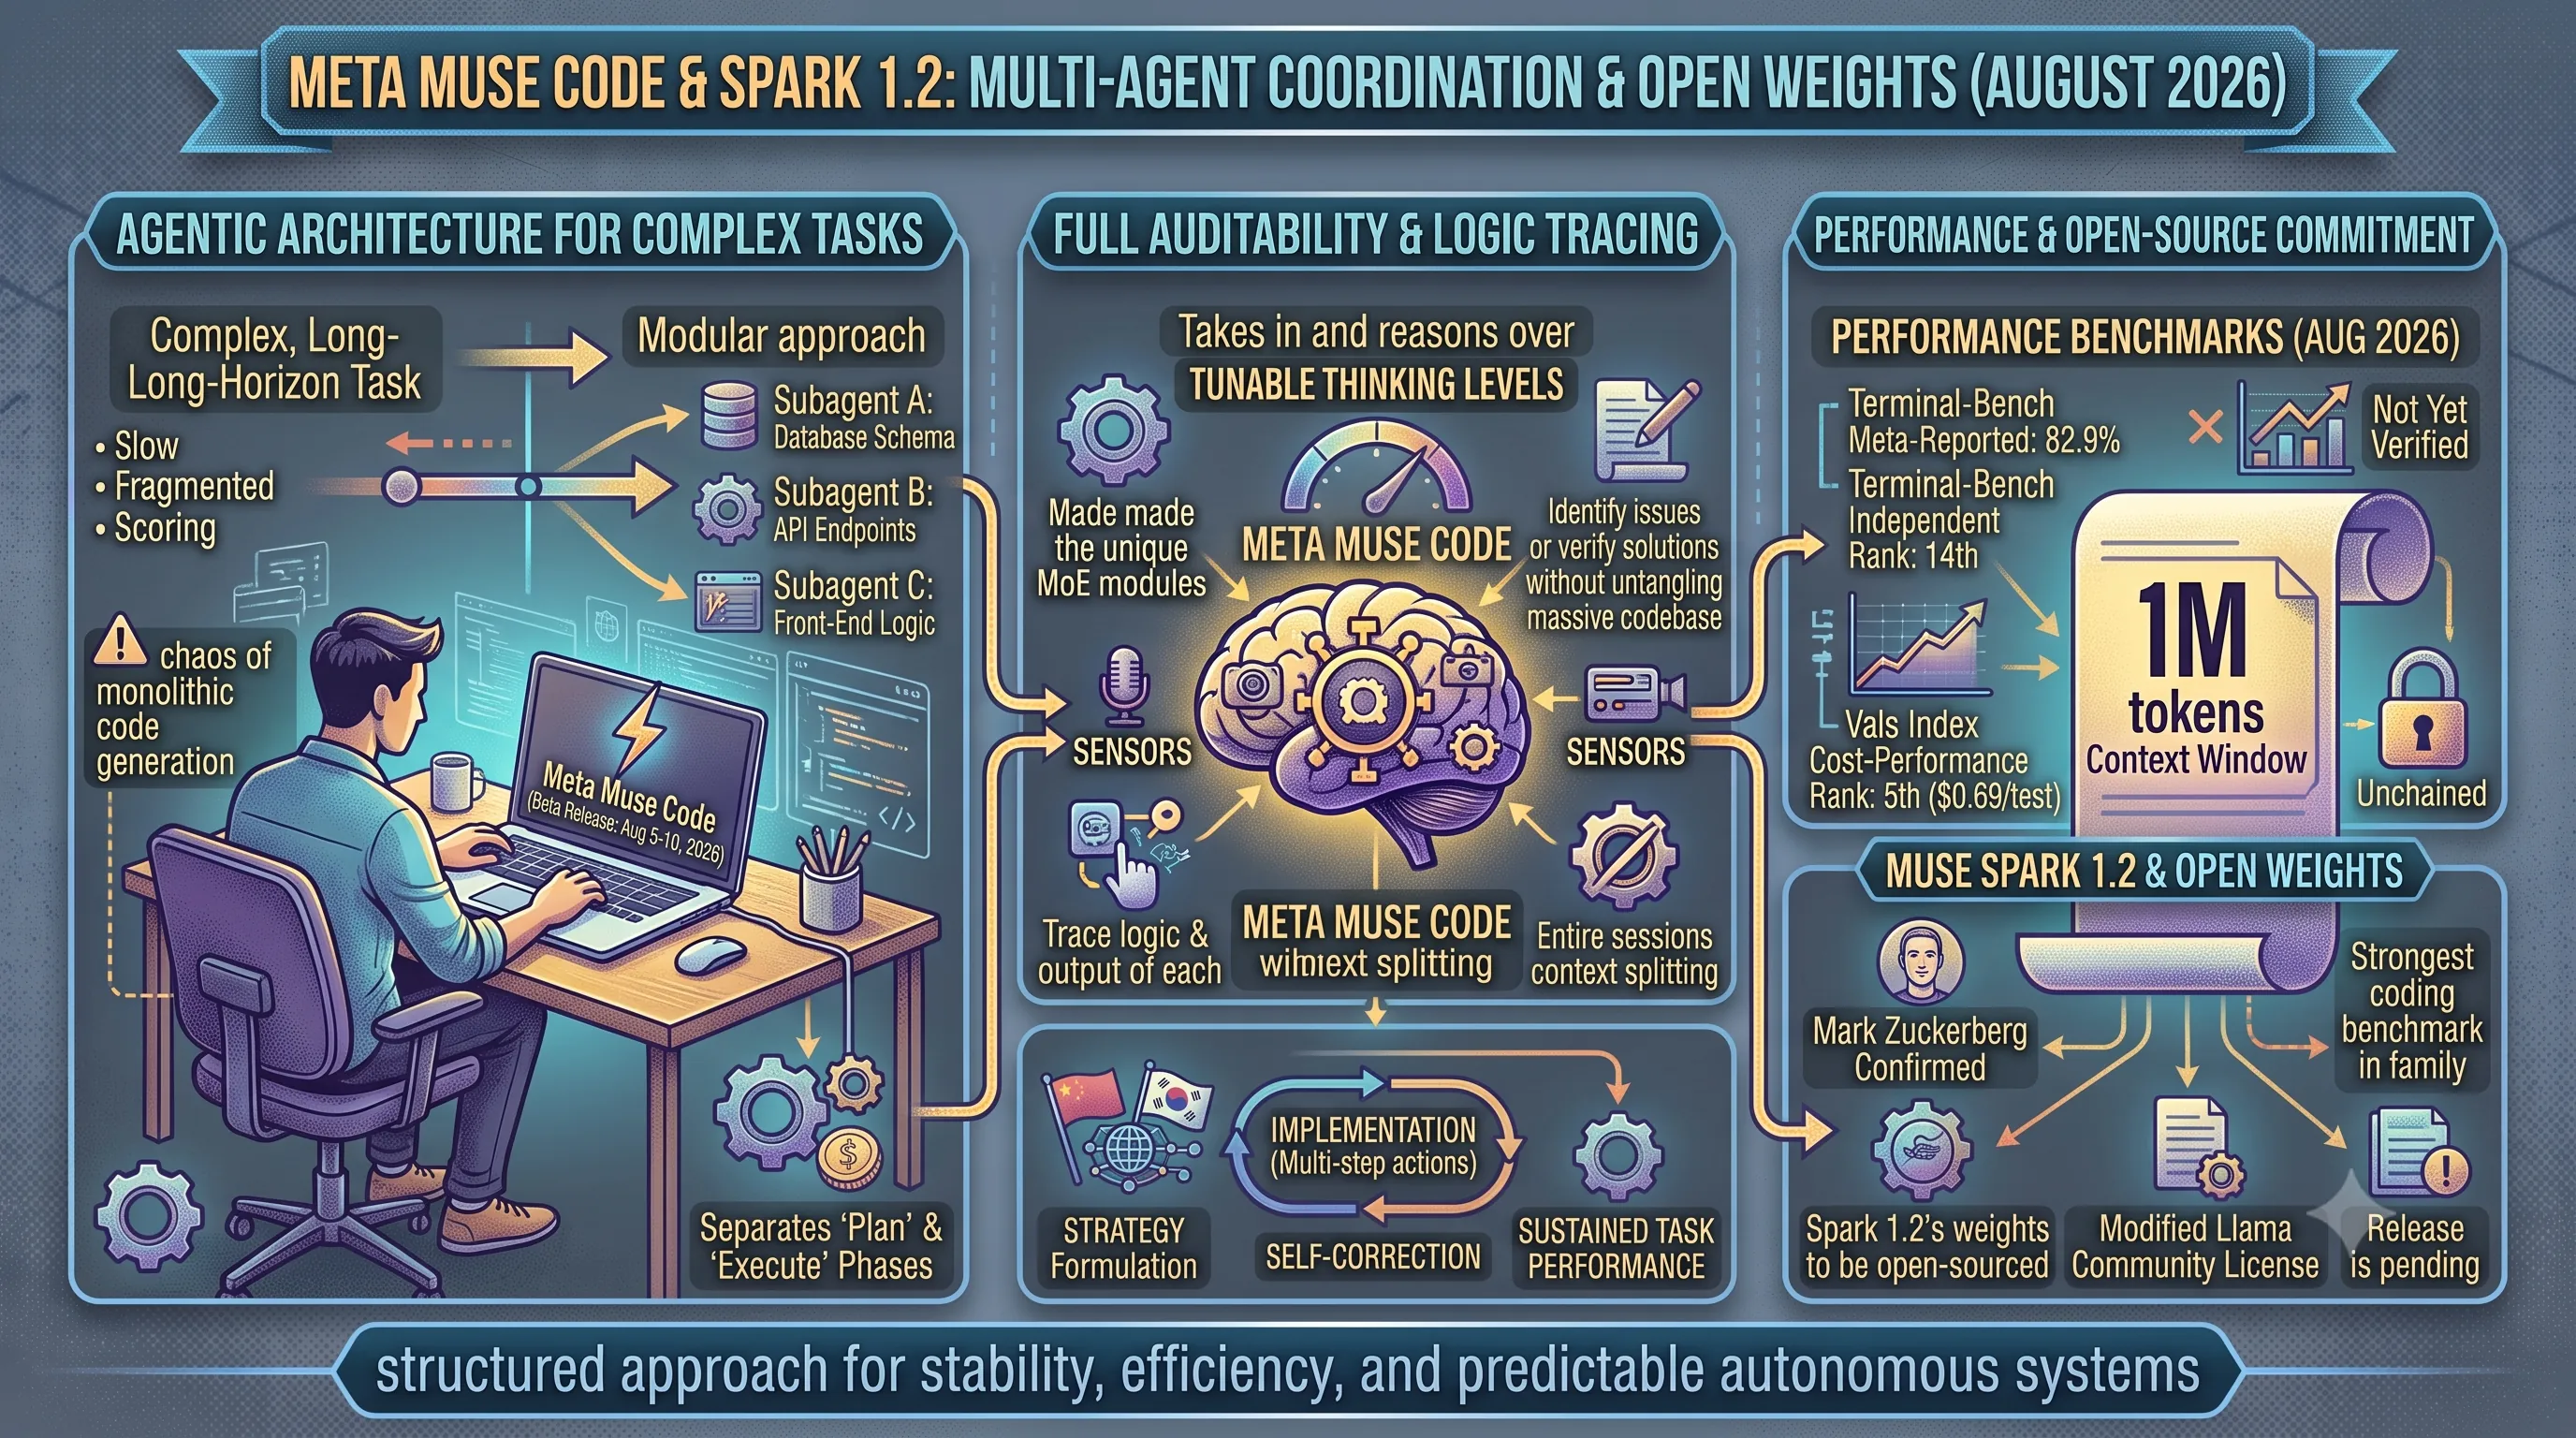
This section directly addresses the main article's theme of separating 'Plan' and 'Execute' phases in agentic coding to prevent code entanglement.Meta Muse Code's architecture, which uses multi-agent coordination and persistent subagents, is a practical implementation of this principle.
It allows a primary agent to plan and delegate complex, long-horizon tasks to specialized subagents, whose work can be individually tracked and audited, mirroring the structured approach needed to avoid the chaos of monolithic, unmonitored code generation.
Agentic Architecture for Complex Tasks
Meta's Muse Code, which saw its beta release between August 5-10, 2026, is engineered specifically for long-horizon coding tasks that challenge single-agent systems.Its core strength lies in multi-agentic coordination, where the system can spawn persistent subagents to handle discrete parts of a larger problem.
This allows for a modular approach to coding, where one agent might handle database schema, another the API endpoints, and a third the front-end logic.
Crucially, the entire process comes with full auditability, enabling developers to trace the logic and output of each subagent to identify issues or verify solutions without having to untangle a single, massive codebase.
This entire workflow is supported by a large 1M-token context window, which allows entire sessions to run from start to finish without context splitting, ensuring subagents maintain a coherent understanding of the overall project goals.
Performance and Open-Source Commitment
Alongside the Muse Code agent, Meta also released Muse Spark 1.2, which is claimed to be the strongest coding benchmark in the family.In a significant move for the community, Mark Zuckerberg confirmed that Spark 1.2's weights will be open-sourced under a modified Llama Community License, though the exact release date for the weights remains pending.
On the performance front, Meta reported an impressive 82.9% score on Terminal-Bench for Muse Code; however, it is important to note this benchmark is not yet verified on an official public leaderboard.
Independent testing offers a more tempered view, ranking Muse Code 14th on the common-harness Terminal-Bench.
On the other hand, it achieves a strong cost-performance score, placing 5th overall on the Vals Index at $0.69 per test.
| Metric | Specification / Rank | Note |
|---|---|---|
| Meta-Reported Benchmark | 82.9% on Terminal-Bench | Not yet verified on an official leaderboard as of August 2026. |
| Independent Benchmark | 14th Rank on Terminal-Bench | Based on common-harness testing. |
| Cost-Performance Index | 5th Rank on Vals Index | Calculated at $0.69 per test. |
| Context Window | 1M tokens | Supports entire sessions without context splitting. |
| Model Weights | Muse Spark 1.2 to be open-sourced | Release is pending under a modified Llama Community License. |
21. Seed 2.1 Turbo: ByteDance's Low-Cost, High-Throughput Agentic Solution
While the "Plan-Execute" agentic routine provides a robust framework for complex tasks like bug fixing, its effectiveness depends heavily on the underlying model's ability to handle long, multi-step workflows without performance degradation or excessive cost.ByteDance's Seed 2.1 Turbo, released on August 10, 2026, directly addresses this need, providing a powerful yet economical engine specifically optimized to execute the long-chain agentic tasks that define modern AI development.
Enterprise-Scale Performance and Cost-Efficiency
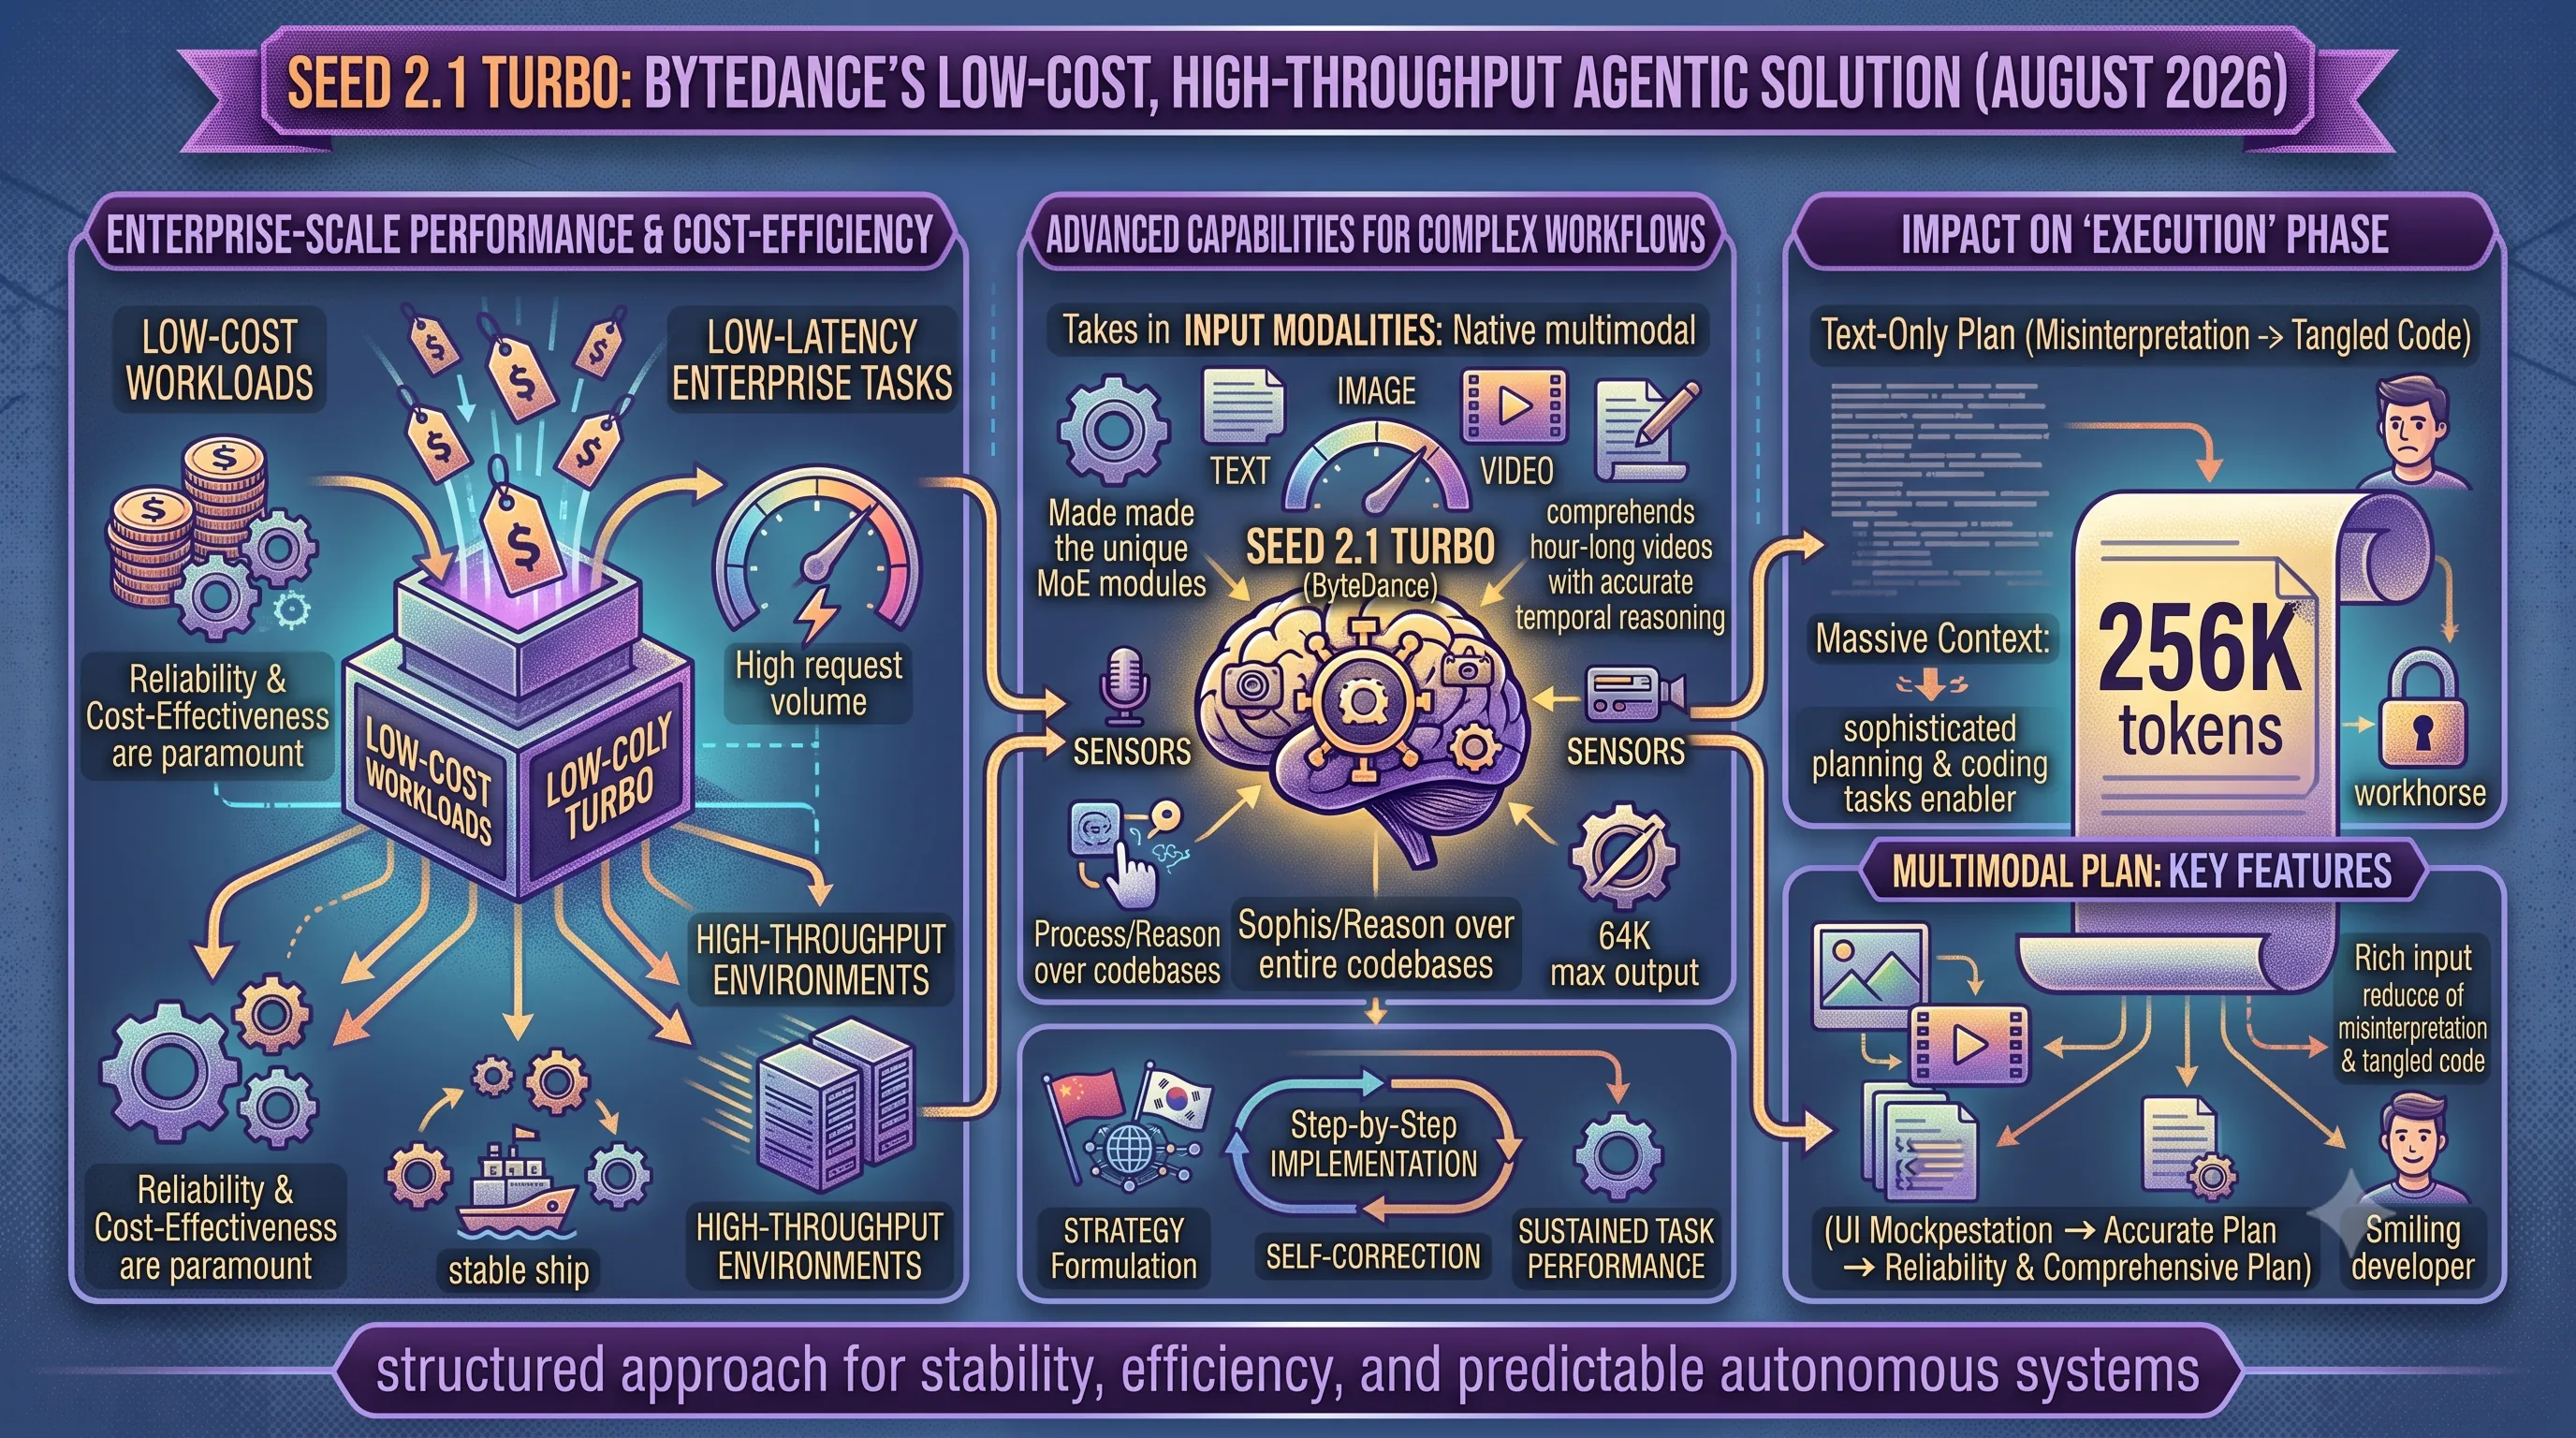
Developed by ByteDance, Seed 2.1 Turbo was launched alongside its flagship counterpart, Seed 2.1 Pro, but with a distinct mission: to serve low-cost, low-latency enterprise workloads that operate at a high request volume.Its pricing and architecture are production-focused, making it an ideal choice for businesses looking to deploy agentic systems at scale without incurring prohibitive operational expenses.
This positions the model as a workhorse for high-throughput environments where reliability and cost-effectiveness are paramount.
Advanced Capabilities for Complex Workflows
The model's design choices reflect its focus on sophisticated, multi-step processes.It features a large 256K context window, making it highly capable of processing and reasoning over long documents and extensive codebases.
Crucially, it is explicitly optimized for long chain agent task execution, enabling it to maintain coherence and accuracy through complex, multi-step agentic workflows.
This is complemented by code generation capabilities that are improved over previous Seed generations.
Furthermore, Seed 2.1 Turbo demonstrates strong multimodal understanding, including the ability to process hour-long videos with accurate temporal reasoning, opening up new possibilities for agents that work with mixed-media inputs.
| Specification | Detail |
|---|---|
| Developer | ByteDance |
| Release Date | August 10, 2026 |
| Context Window | 256K tokens |
| Target Workload | Low-cost, low-latency enterprise tasks at high volume |
| Key Agentic Feature | Optimized for long chain agent task execution |
| Multimodal Strength | Processes hour-long videos with accurate temporal reasoning |
22. OpenAI GPT-5.6 Family: Durable Capability Tiers for Diverse Needs
This new model family from OpenAI directly powers the advanced agentic systems discussed in this article.Specifically, the flagship model, Sol, provides the high-end reasoning necessary for the 'Plan-Execute' routines in complex coding tasks, while the new ChatGPT Work platform serves as a real-world example of an client built on this foundation to execute long-running projects.
A Three-Tiered Approach: Sol, Terra, and Luna
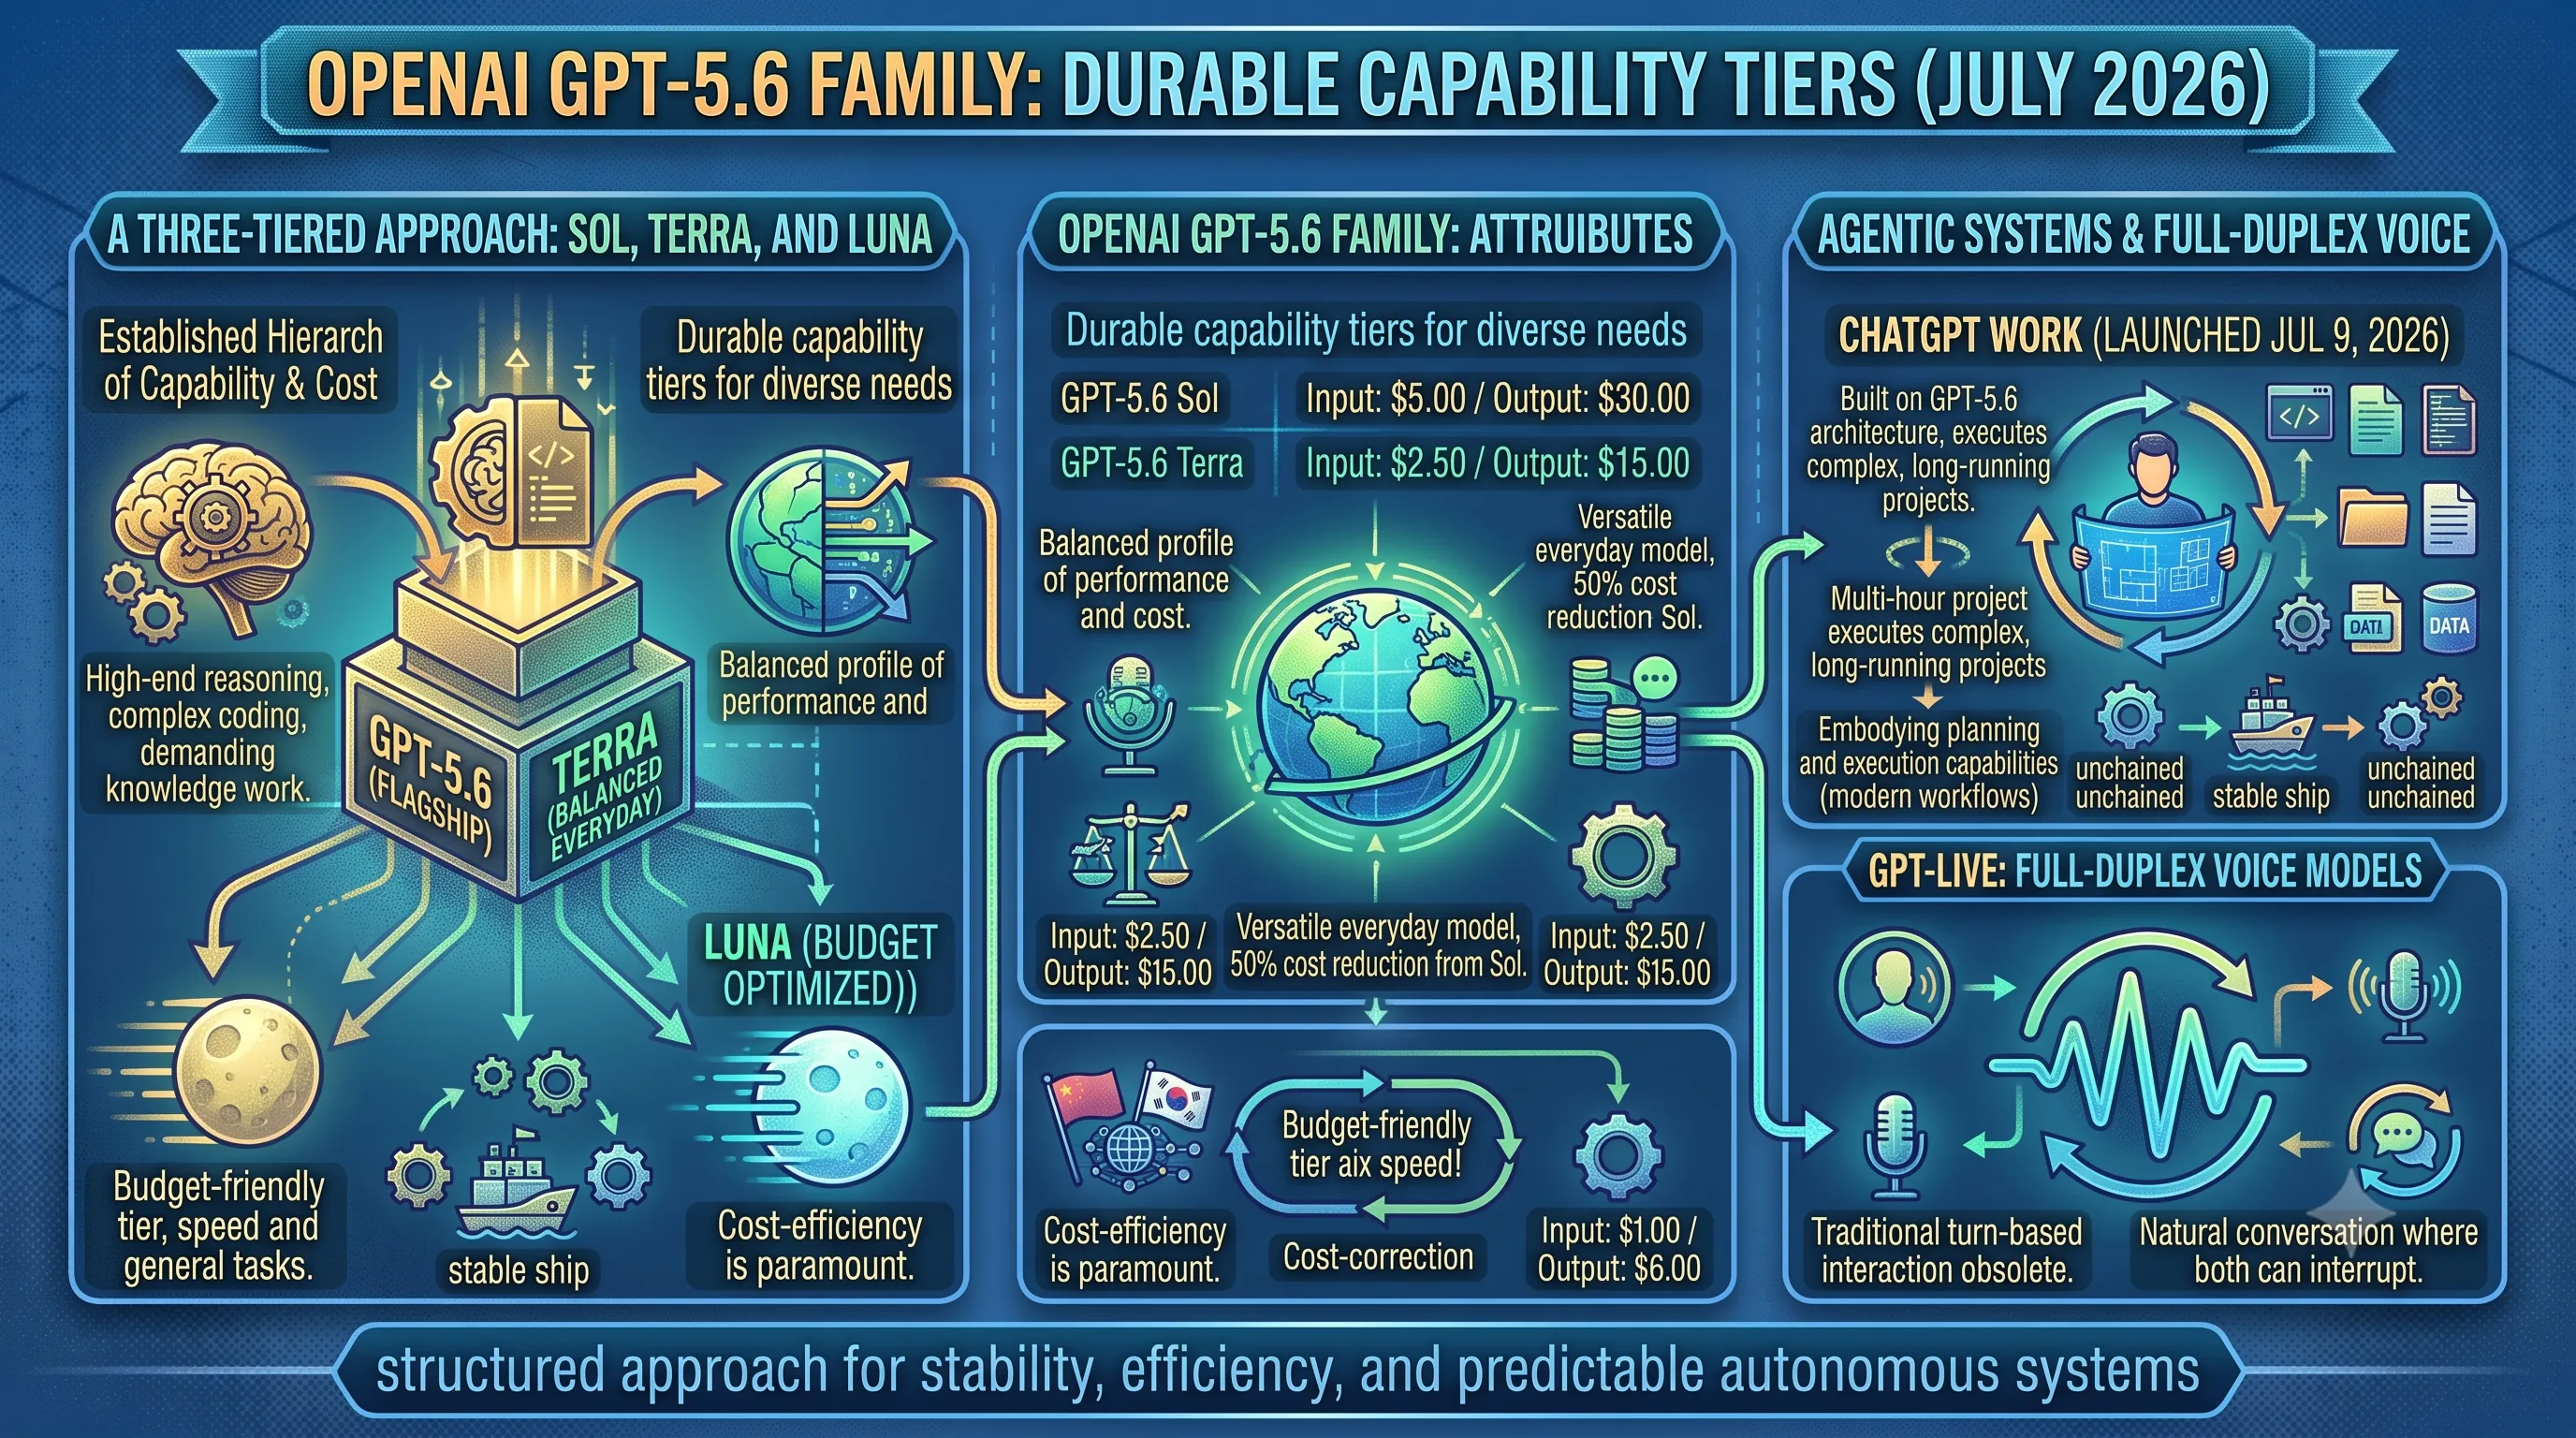
On July 9, 2026, OpenAI restructured its API offerings, rolling out the complete GPT-5.6 family.This move established a clear hierarchy of "durable capability tiers" designed to serve distinct user needs and budgets.
The family is led by GPT-5.6 Sol, the flagship model engineered for high-end reasoning, complex coding, and demanding knowledge work.
For more common applications, GPT-5.6 Terra offers a balanced profile of performance and cost, positioned as the versatile everyday model.
Rounding out the lineup is GPT-5.6 Luna, a budget-friendly tier optimized for speed and general tasks where cost-efficiency is paramount.
This tiered pricing structure allows developers to precisely match model capability to task complexity.
| Model | Target Use Case | Input Price (per 1M tokens) | Output Price (per 1M tokens) |
|---|---|---|---|
| GPT-5.6 Sol | Flagship model for high-end reasoning, complex coding, and knowledge work. | $5.00 | $30.00 |
| GPT-5.6 Terra | Balanced, everyday model offering a 50% cost reduction from Sol. | $2.50 | $15.00 |
| GPT-5.6 Luna | Budget tier optimized for speed and general tasks. | $1.00 | $6.00 |
Agentic Systems and Full-Duplex Voice
Alongside the new model tiers, OpenAI also launched ChatGPT Work on July 9, 2026.This is a powerful agentic system built directly on the GPT-5.6 architecture.
It is designed to execute complex, multi-hour projects by operating across a team's files and applications, embodying the planning and execution capabilities central to modern agentic workflows.
The update also introduced GPT-Live, a set of full-duplex voice models.
A key feature of these models is their ability to engage in natural conversation, where both the user and the AI can interrupt and be interrupted, moving beyond the traditional turn-based interaction.
23. Anthropic Claude Opus 5 & Fable 5: Advancing Agentic Coding and Research
This evolution in Anthropic's model lineup provides developers with precisely the kind of powerful, nuanced tools required to implement the sophisticated 'Plan-Execute' routines central to modern agentic coding, moving beyond simple bug fixes to complex, multi-step problem-solving.Claude Opus 5: The New Agentic Workhorse
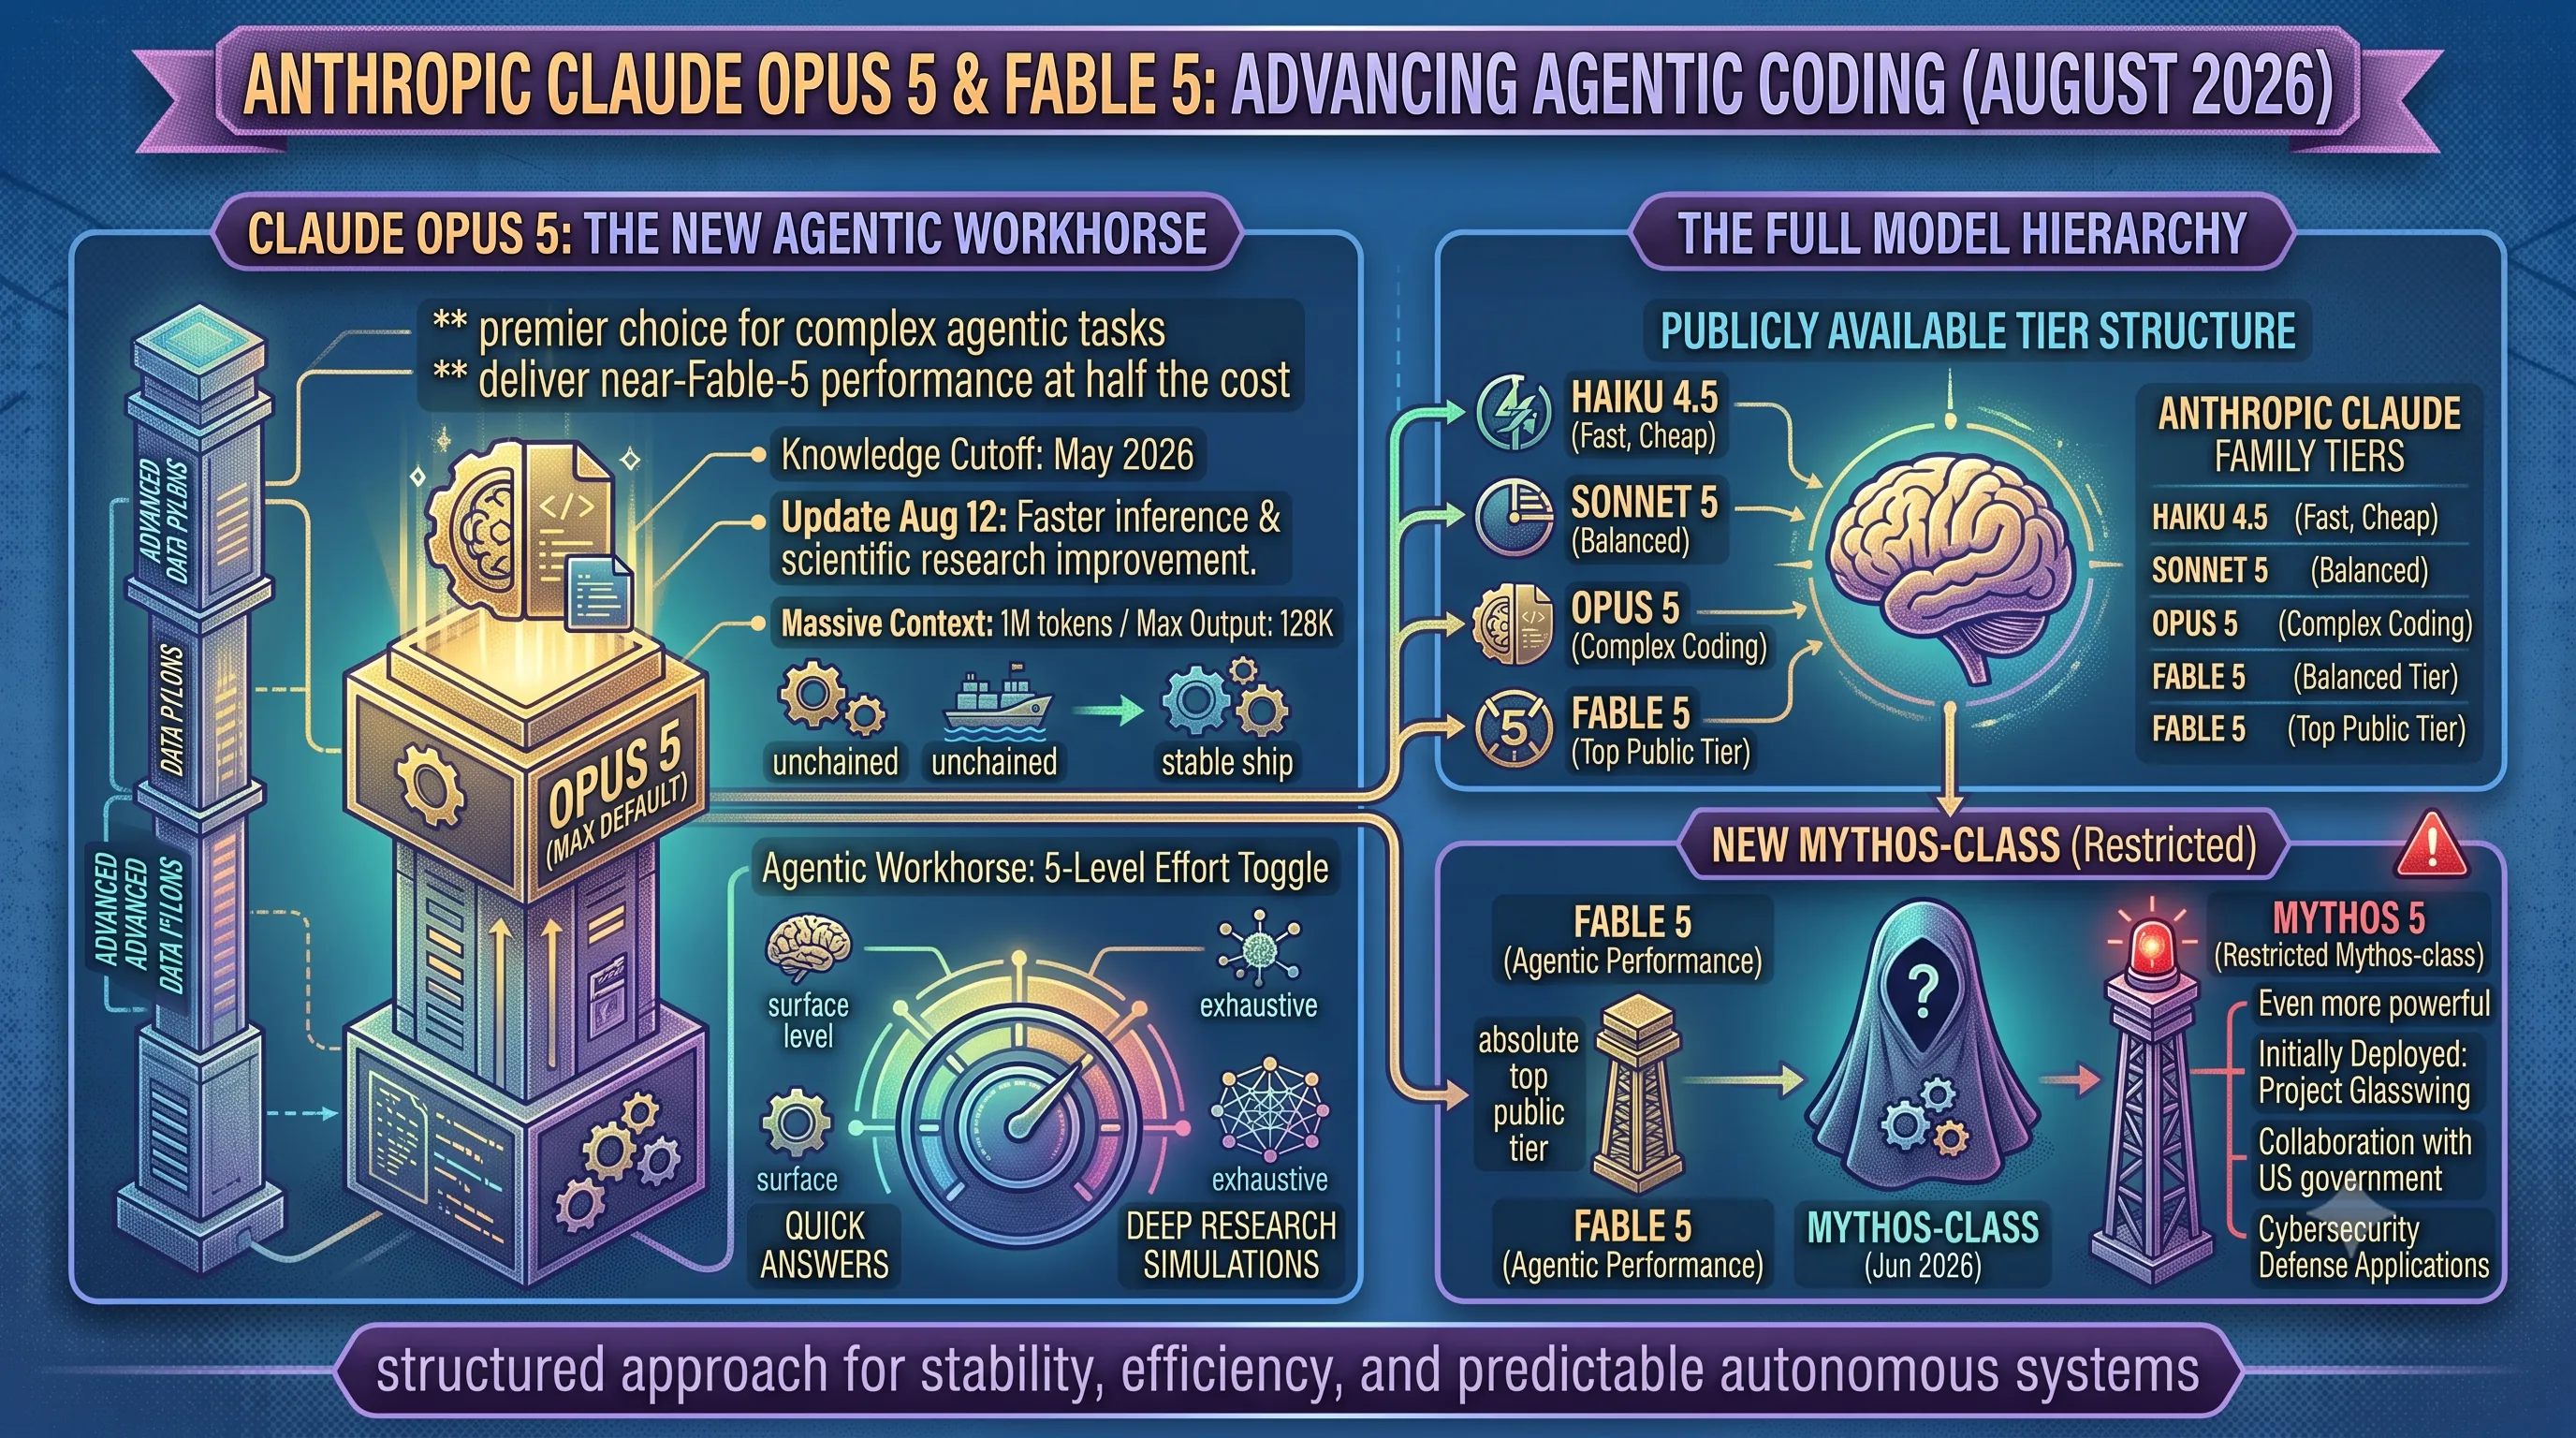
Anthropic's Claude Opus 5, which arrived on July 24, 2026, has rapidly established itself as the new default for the Claude Max subscription and the premier choice for complex agentic tasks.A subsequent update on August 12, 2026, further improved its inference speed and capabilities in scientific research, solidifying its position.
The model's key value proposition is its ability to deliver near-Fable-5 performance at half the cost, making top-tier reasoning more accessible.
It boasts a massive 1M-token context window and a 128K maximum output length, enabling it to process and generate extremely large and complex codebases or research documents.
A standout feature for agentic workflows is the new 5-level effort toggle, which allows developers to dynamically control the model's reasoning depth—from quick, surface-level answers to deep, exhaustive research simulations.
With the most current training data in the Claude family (a knowledge cutoff of May 2026), Opus 5 holds the strongest overall benchmark profile for any generally available model.
The Full Model Hierarchy: From Haiku to the Restricted Mythos 5
Opus 5 is the peak of Anthropic's publicly available model series, which is structured to serve a range of needs.The full tier structure as of August 2026 consists of: Haiku 4.5 for fast and cheap tasks, Sonnet 5 as a balanced pick, Opus 5 for complex agentic coding, and Fable 5 as the absolute top public tier.
In June 2026, Anthropic also introduced its new "Mythos-class" with Fable 5 and the even more powerful Mythos 5.
However, access to Mythos 5 is highly restricted; it was initially deployed exclusively through Project Glasswing, a collaboration with the US government focused on cybersecurity defense applications.
| Model | Input Price (per 1M tokens) | Output Price (per 1M tokens) | Primary Use Case |
|---|---|---|---|
| Haiku 4.5 | $1 | $5 | Fast and cost-effective tasks |
| Sonnet 5 | $2 | $10 | Balanced performance and cost |
| Opus 5 | $5 | $25 | Complex agentic coding and research |
| Fable 5 | $10 | $50 | Top-tier agentic performance |
24. Moonshot AI Kimi K3: A Global Leader in Reasoning and Frontend Generation
The effectiveness of an agentic 'Plan-Execute' routine is fundamentally limited by the capabilities of the execution engine.Even a perfect plan will result in tangled, buggy code if the underlying AI model lacks the reasoning, knowledge, and coding precision to carry it out faithfully.
This is precisely why the emergence of frontier models like Moonshot AI's Kimi K3 is so critical; they provide the reliable, high-horsepower foundation necessary for complex agentic workflows to succeed.
Core Architecture and Global Performance
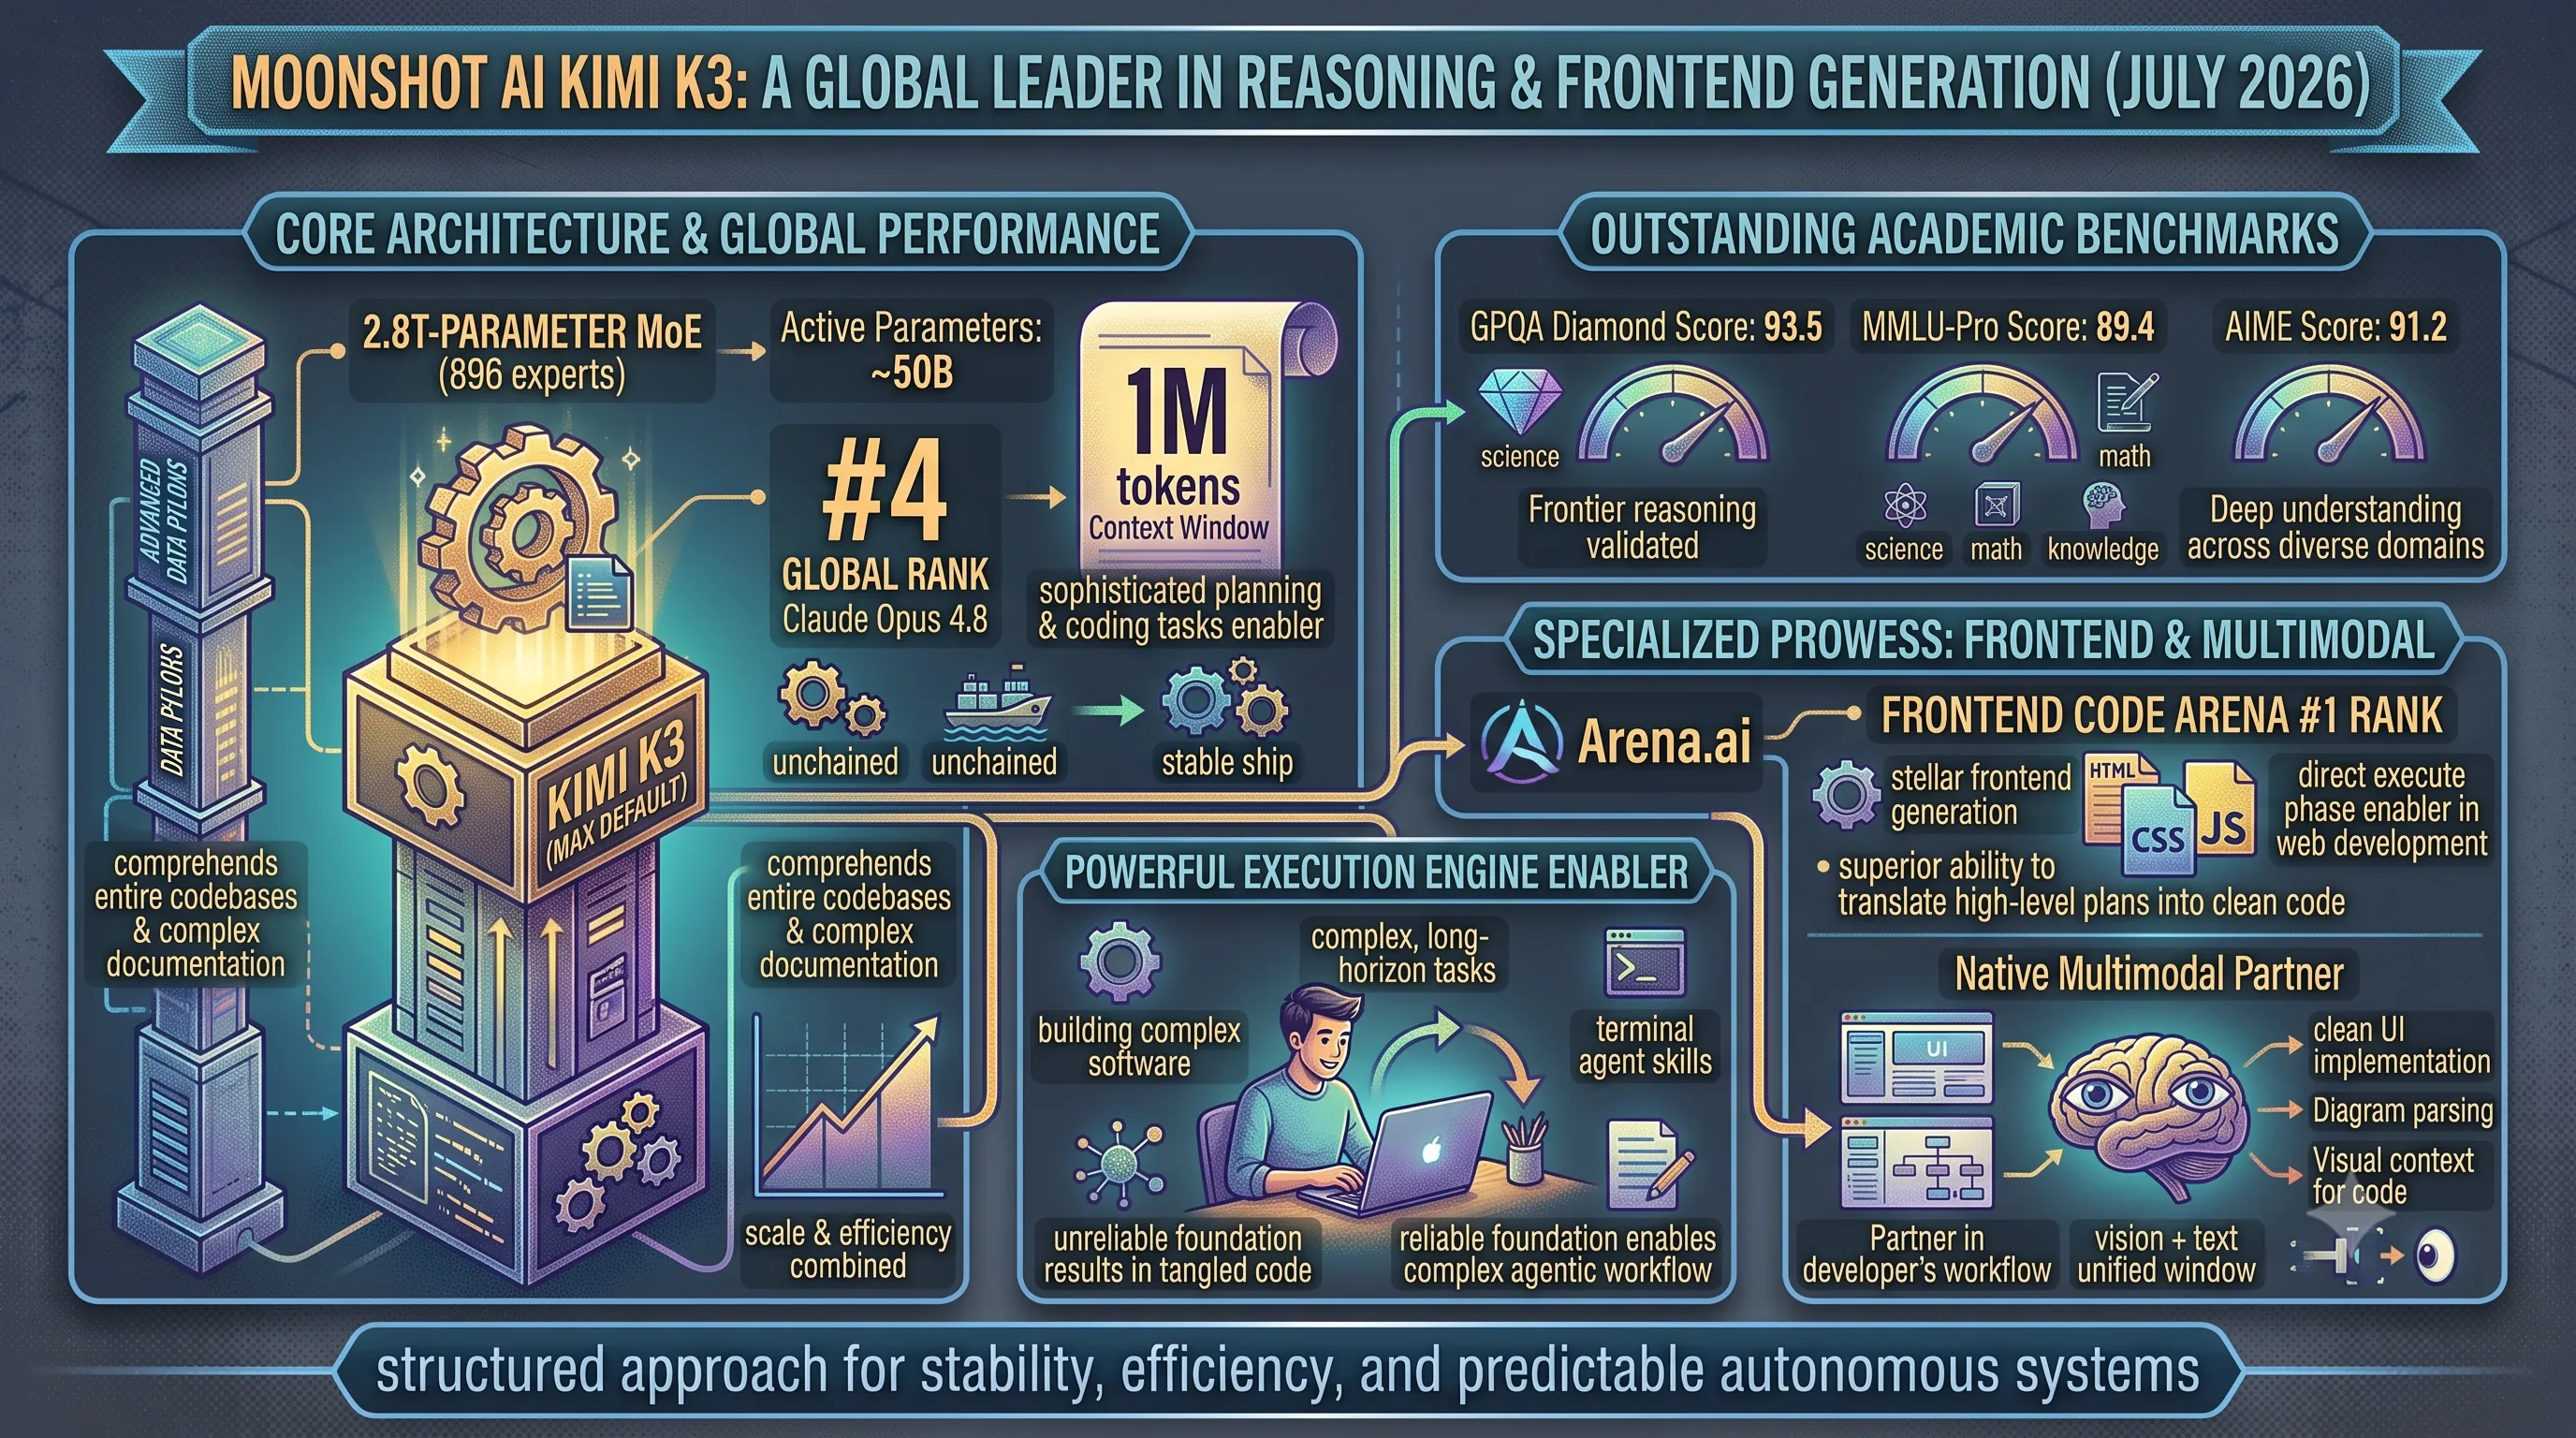
Released on July 16, 2026, Kimi K3 immediately established itself as a top-tier global model.Its architecture is a massive 2.8 trillion-parameter Mixture of Experts (MoE) model, utilizing 896 experts with approximately 50 billion active parameters during inference, allowing for both scale and efficiency.
This power translated directly to leaderboard performance, where Kimi K3 secured the #4 global rank across all models, notably surpassing competitors like Claude Opus 4.8.
A key differentiator is its enormous 1 million-token context window, enabling it to process and reason over entire codebases or extensive documentation in a single pass.
The model's frontier reasoning capabilities are validated by its outstanding performance on rigorous academic benchmarks, demonstrating its deep understanding across science, math, and general knowledge.
| Specification | Moonshot AI Kimi K3 |
|---|---|
| Architecture | 2.8T-parameter MoE (896 experts) |
| Active Parameters | ~50B |
| Context Window | 1M tokens |
| Global Ranking | #4 (beating Claude Opus 4.8) |
| GPQA Diamond Score | 93.5 |
| MMLU-Pro Score | 89.4 |
| AIME Score | 91.2 |
Specialized for the Modern Developer: Frontend and Multimodal Prowess
While its general reasoning is world-class, Kimi K3's true value for agentic coding lies in its specialized skills.It has achieved the #1 ranking on the Arena.ai Frontend Code Arena, a testament to its stellar frontend generation capabilities.
This indicates a superior ability to translate high-level plans into clean, functional HTML, CSS, and JavaScript, directly addressing the core challenge of the 'Execute' phase in web development.
Furthermore, Kimi K3 is a natively multimodal model, capable of processing both vision and text within a single interface.
This allows it to understand UI mockups, diagrams, and other visual inputs, making it a powerful partner in a developer's workflow.
Combined with its strong terminal agent skills, these features position Kimi K3 as a premier execution engine for building and debugging complex software applications.
25. Zhipu GLM-5.2: Speed and Efficiency in a Trillion-Parameter MoE
The 'Plan-Execute' routine central to modern agentic coding demands more than just intelligence; it requires immense computational speed.A multi-step process where an agent first formulates a detailed plan and then executes it can become impractically slow without a powerful underlying model.
Zhipu's GLM-5.2, with its focus on speed and efficiency, represents the class of engine required to make such sophisticated agentic workflows not just possible, but practical for complex tasks like real-time bug fixing.
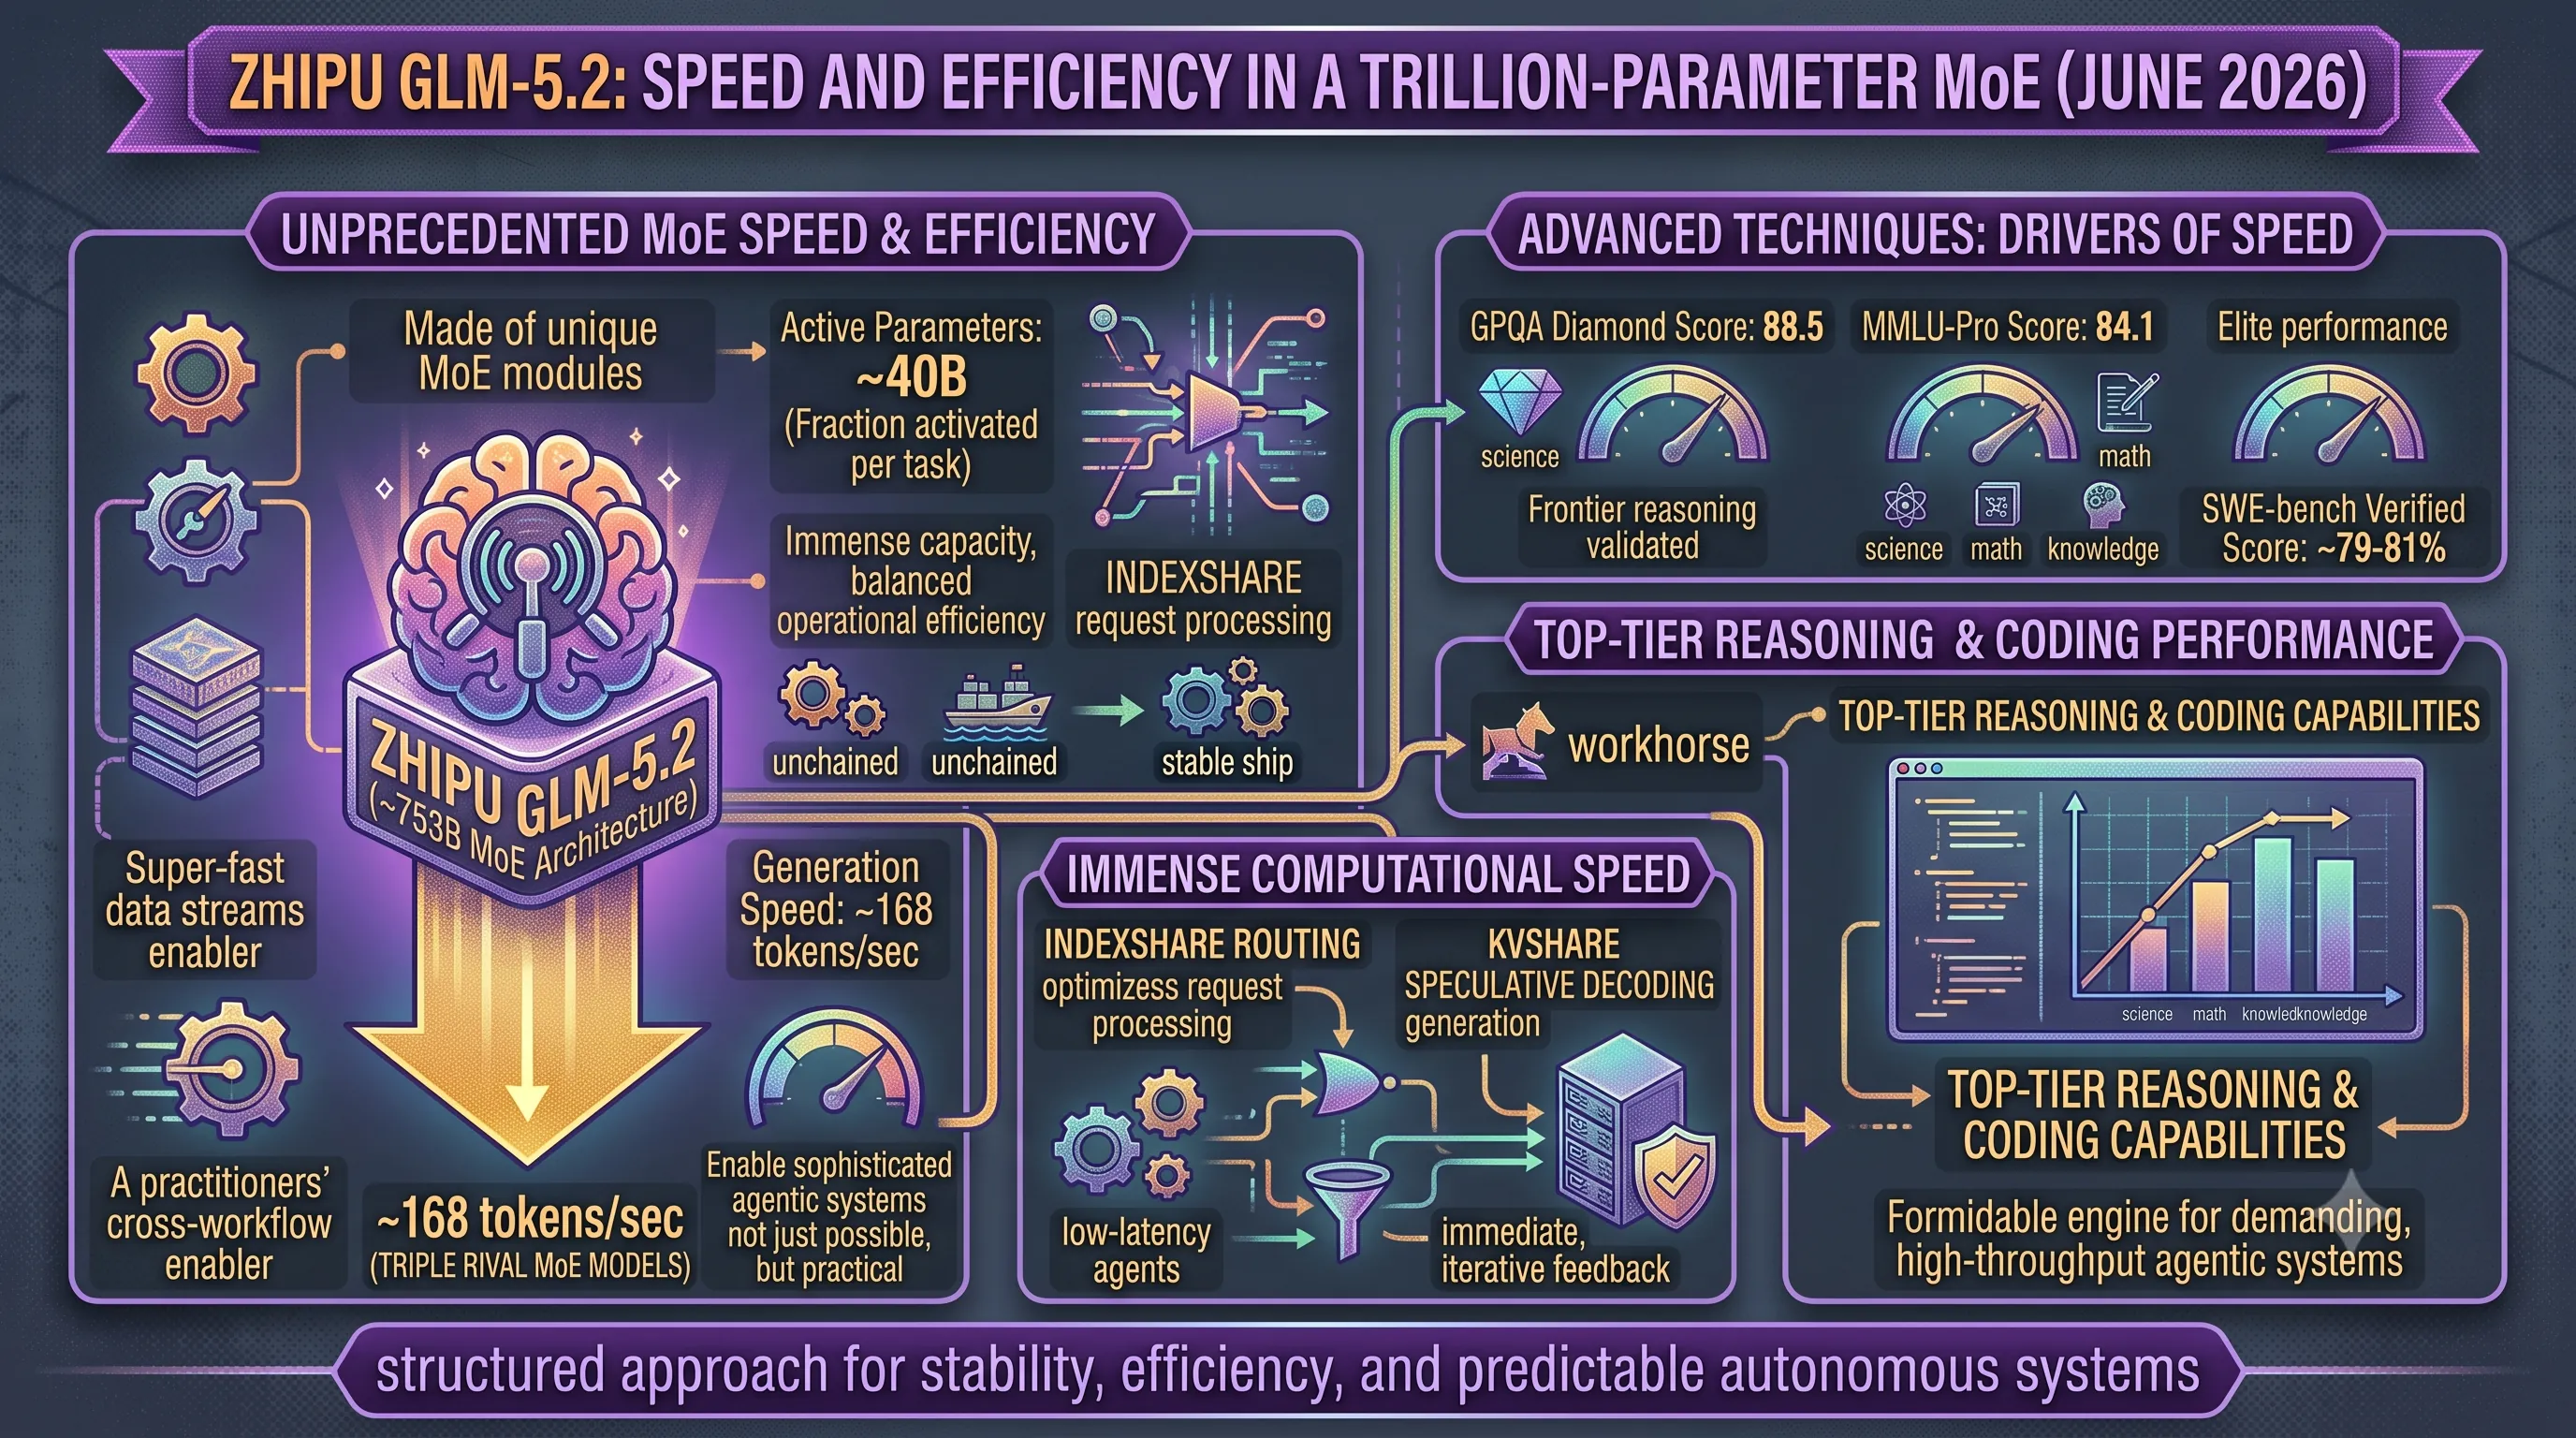
Released on June 13, 2026, Zhipu's newest open flagship model, GLM-5.2, was engineered to balance massive scale with operational efficiency.
It features a ~753 billion parameter Mixture-of-Experts (MoE) architecture, a design that allows for immense capacity while only activating a fraction of the model—around ~40 billion parameters—for any single task.
This approach is fundamental to its performance, which is summarized below.
| Metric | Zhipu GLM-5.2 Performance |
|---|---|
| Architecture | ~753B Mixture-of-Experts (MoE) |
| Active Parameters | ~40B |
| Generation Speed | ~168 tokens/sec |
| GPQA Diamond | 88.5 |
| MMLU-Pro | 84.1 |
| SWE-bench Verified | ~79-81% |
This efficiency is not just a result of the MoE structure but is also driven by advanced techniques like IndexShare routing and KVShare speculative decoding, which optimize how the model processes requests and generates responses.
Its strong benchmark scores, including a high ~79-81% on SWE-bench Verified, confirm its top-tier reasoning and coding capabilities, making it a formidable engine for demanding, high-throughput agentic systems.
26. DeepSeek V4-Flash-0731: Small, Fast, and Closing the Gap on Giants
This section connects to the main topic of 'Plan-Execute' routines in agentic coding by examining a critical enabler: the evolution of the AI models themselves.While the core article discusses the methodology, here we dive into a prime example of the hardware and software reality with DeepSeek V4-Flash-0731, a model specifically retooled to excel at the very agentic tasks that benefit from a separated planning and execution process.
The release of the retrained DeepSeek V4-Flash-0731 on July 31, 2026, represented a significant milestone for developers specializing in AI-driven coding and automation.
This model's update was not a routine refresh but a strategic overhaul, retrained with an optimized pipeline specifically targeting improvements in coding and agent tool-use.
The most compelling outcome of this specialization is its performance benchmark results.
The nimble V4-Flash-0731, with its 13 billion active parameters, now officially outperforms the much larger V4-Pro model on agentic benchmarks.
Crucially, this leap in capability was achieved without any corresponding price increase, reinforcing its value proposition as a highly efficient and powerful tool.
This event is a clear signal of a wider industry trend: small, fast open models are definitively closing the performance gap on the proprietary giants, making sophisticated agentic workflows more accessible.
| Metric | DeepSeek V4-Flash-0731 Specification |
|---|---|
| Architecture | 284B Mixture-of-Experts (MoE) / 13B active parameters |
| Average Speed | ~112 tokens/sec |
| Key Optimization (July 2026 Retrain) | Coding & Agent Tool-Use |
| Performance Milestone | Outperforms the larger V4-Pro on agentic benchmarks |
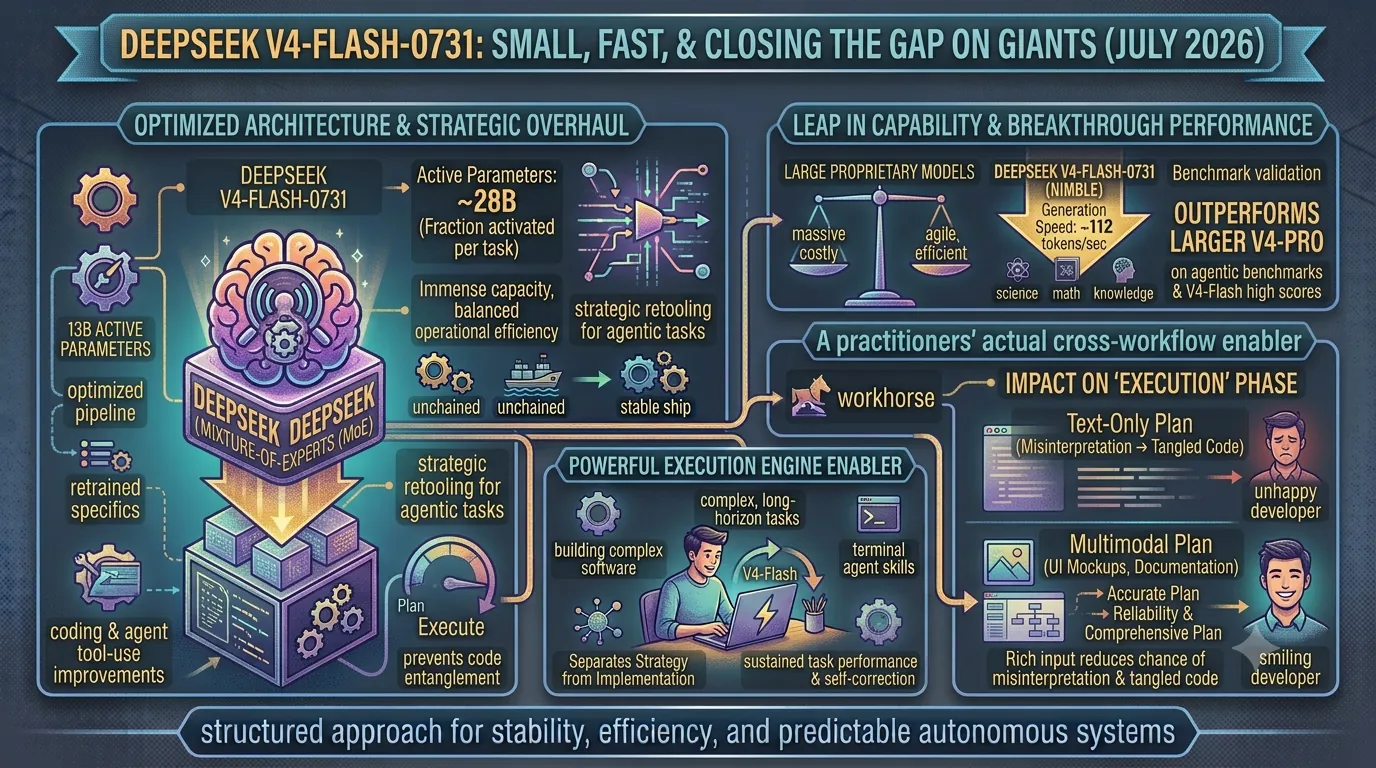
27. MiniMax M3: Multimodal Powerhouse with Autonomous Task Decomposition
The challenge of preventing tangled code during bug fixes directly points to the need for a more structured, intelligent approach—a perfect use case for the 'Plan-Execute' agentic routine.The MiniMax M3 model, which launched on June 1, 2026, is a powerful example of a system built to embody this principle through its advanced agentic capabilities.
At its core, MiniMax M3 excels at autonomous task decomposition and multi-tool workflows.
Instead of immediately attempting a code change, it first analyzes a complex request and breaks it down into a logical sequence of verifiable sub-tasks, effectively performing the 'planning' phase of an agentic workflow before execution begins.
This planning is significantly enhanced by its native multimodal input capabilities.
Powered by a proprietary architecture called MiniMax Sparse Attention, the model can natively process text, image, and even video inputs.
This allows a developer to provide a screen recording of a bug, a screenshot of an error log, and a textual description, giving the model a rich, multi-faceted understanding of the problem to generate a more robust and accurate plan.
Underpinning these features is a massive 428B Mixture-of-Experts (MoE) architecture, which keeps approximately 23B parameters active during inference.
This design is the key to its efficiency, enabling it to operate at just 1/20th the compute cost of comparable dense models while achieving top-tier performance, as evidenced by its GPQA scores passing 92.
Combined with a massive 1M-token context window, M3 can analyze entire codebases to inform its task decomposition, making it a formidable tool for complex software development and maintenance cycles.
| Feature | Specification |
|---|---|
| Architecture | 428B Mixture-of-Experts (MoE) with ~23B active parameters |
| Context Window | 1M tokens |
| Key Benchmark | GPQA scores past 92 |
| Native Inputs | Text, Image, Video (via MiniMax Sparse Attention) |
| Cost Efficiency | 1/20th the compute cost of comparable dense models |
| Release Date | June 1, 2026 |
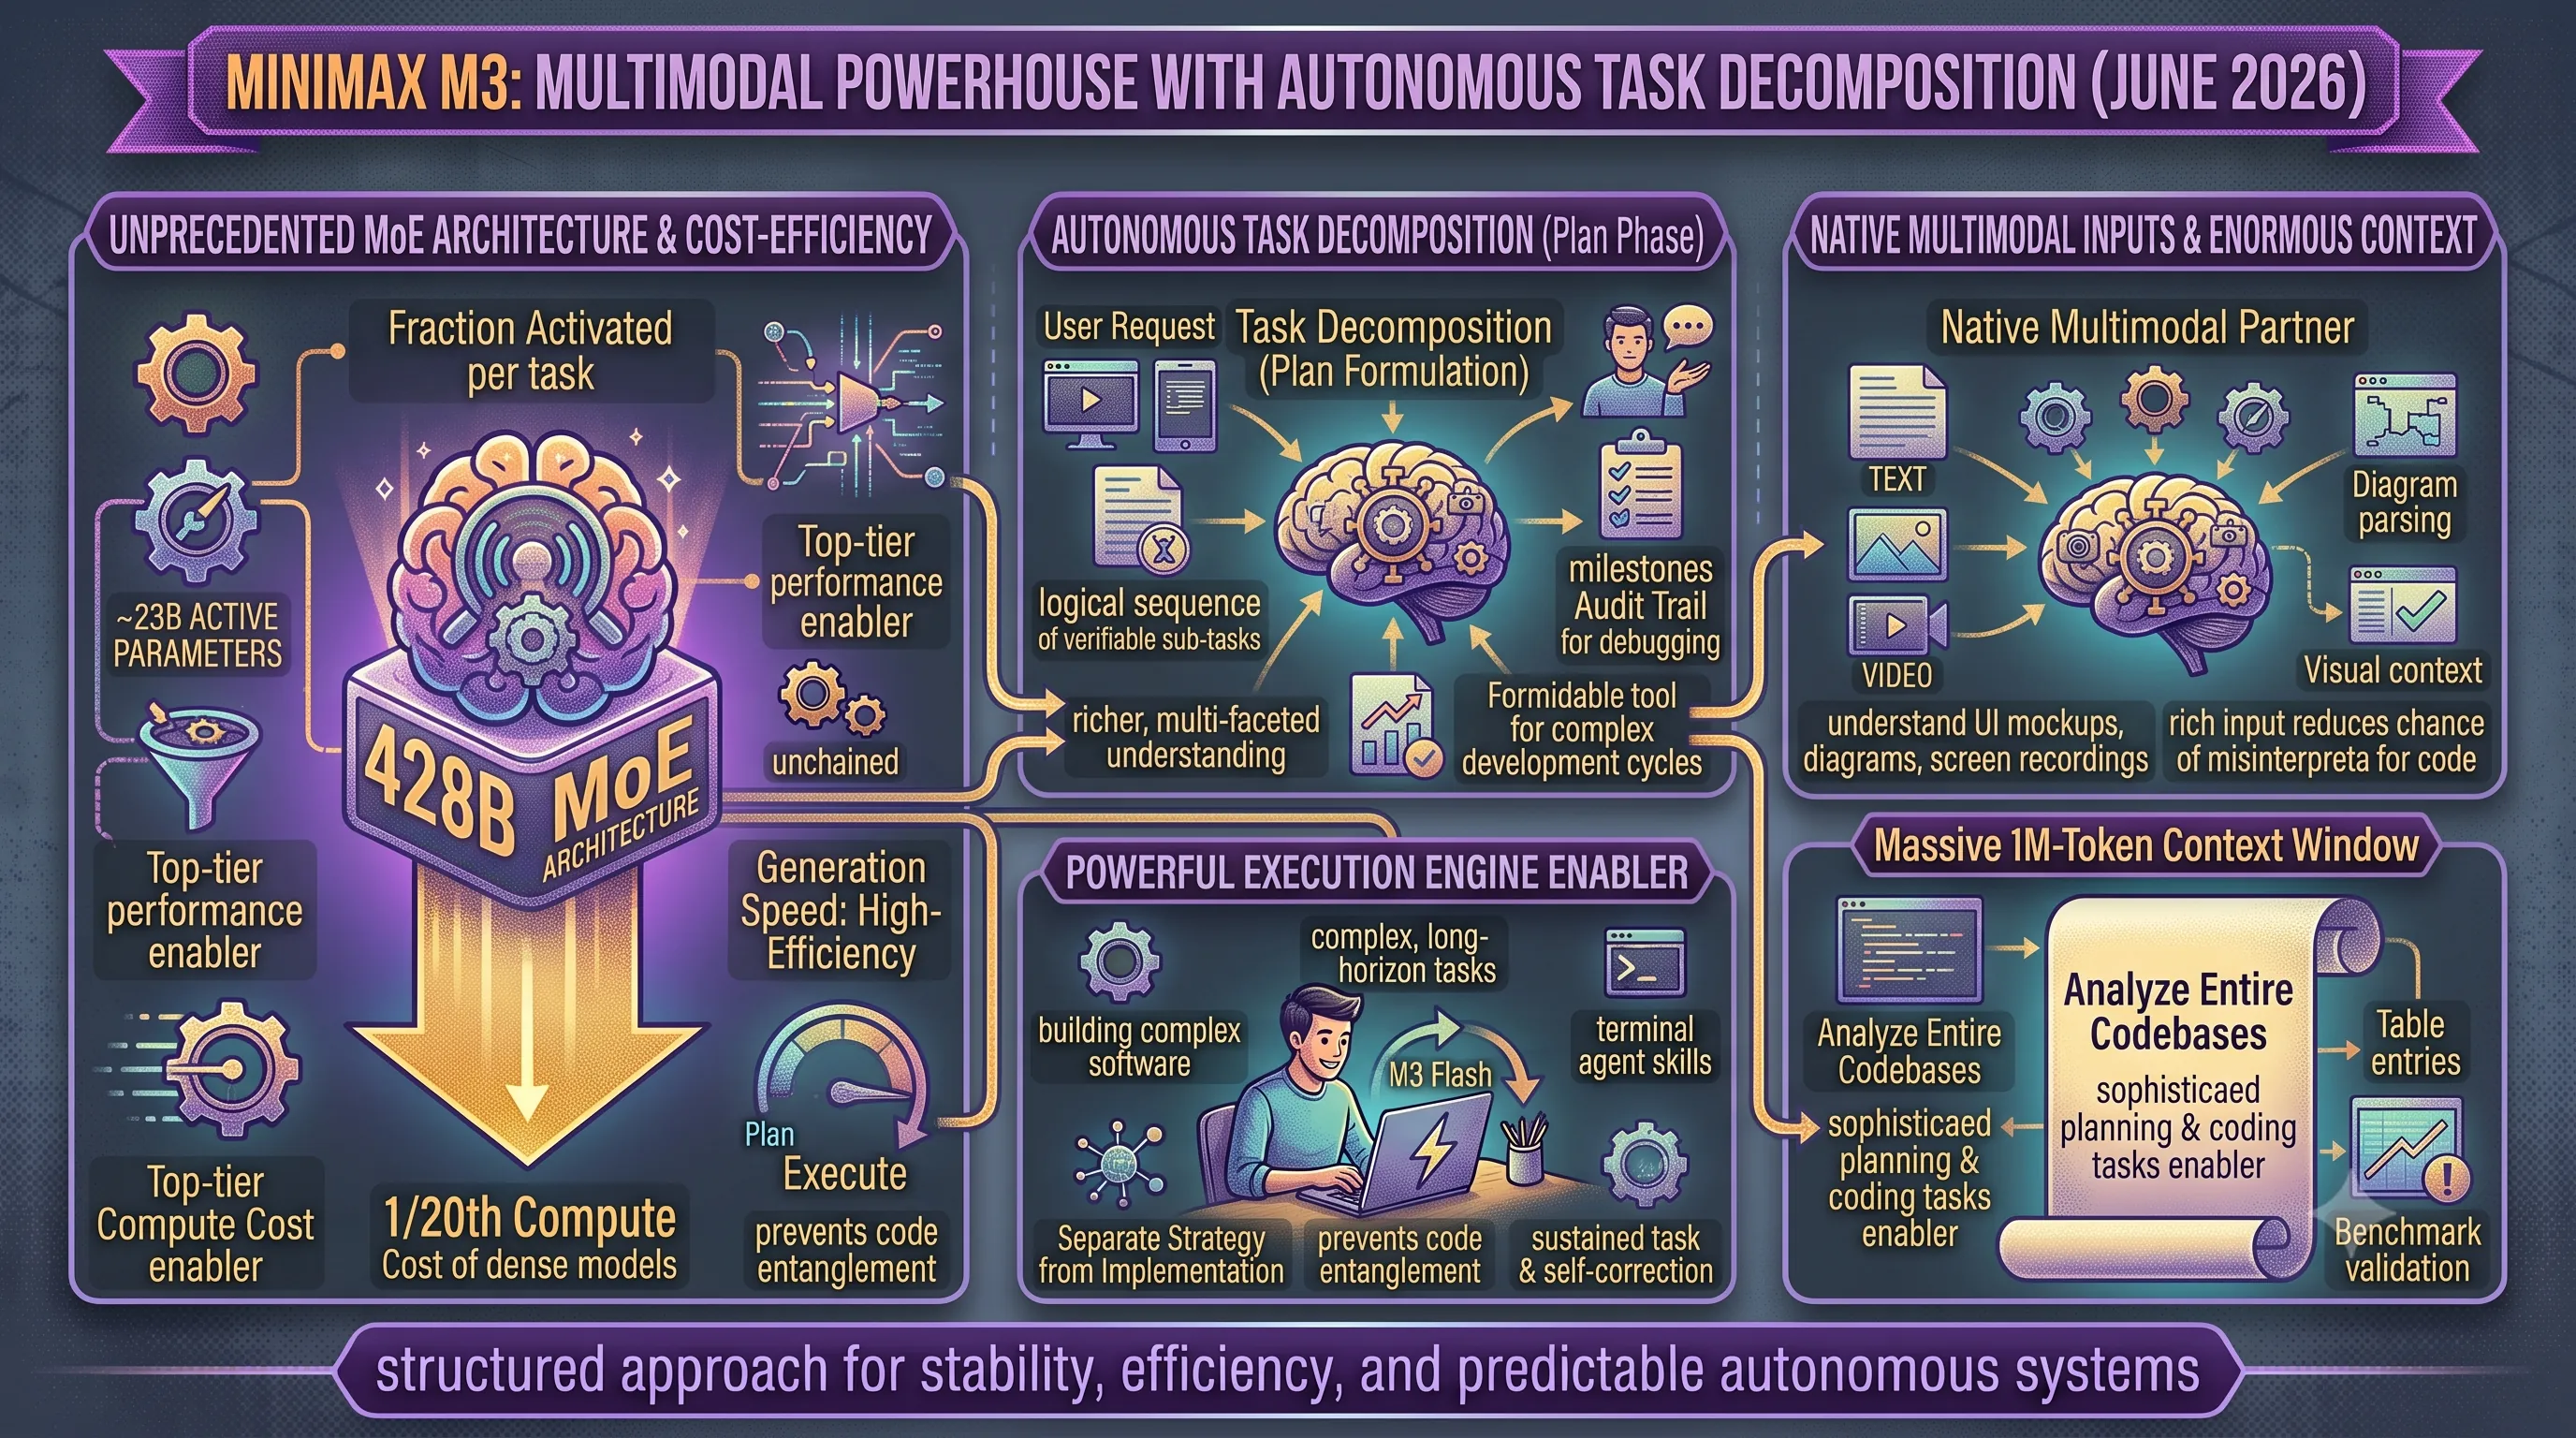
28. Meta Llama 4 Generation: The Open-Source Standard-Setter
The advanced 'Plan-Execute' agentic coding routines discussed in this article rely on foundational models with immense context and efficiency.Meta's Llama 4 generation serves as the current open-source standard-setter, providing the powerful, locally deployable engines required for such sophisticated tasks.
This entire generation of models was refined using the formidable 2T Behemoth as its teacher model, ensuring a high level of capability from the outset.
Llama 4 Scout: Redefining Context
The first pillar of the generation, Llama 4 Scout, addresses the critical need for comprehensive code understanding in agentic workflows.It achieves a breakthrough with its 10-million-token context window, a feat made possible by its use of interleaved iRoPE attention.
This massive context allows an agent to ingest and reason over entire repositories or complex documentation sets during the 'planning' phase without losing critical information, a common failure point in previous model generations.
Llama 4 Maverick: Natively Multimodal and Efficient
Complementing Scout is Llama 4 Maverick, a model designed for efficient execution and advanced understanding.As a natively multimodal Mixture-of-Experts (MoE) model, Maverick can process more than just text, a key advantage for modern development environments.
Its architecture is remarkably efficient, activating just 17B parameters from a total pool that can range from 109B to 400B.
This efficiency allows Llama 4 Maverick to run on single nodes while delivering performance that surpasses older, dense flagship models, making powerful agentic execution accessible without requiring massive server farms.
Local Deployment and Accessibility
A defining characteristic of the Llama 4 family is its commitment to accessibility for developers and researchers.All models are available in the popular GGUF format, which is the standard for local deployment.
This allows users to run these powerful models on their own hardware, with various quantization levels available to balance performance with resource constraints, democratizing access to the tools needed for building private and customized coding agents.
| Model | Key Feature | Core Specification | Architecture Detail |
|---|---|---|---|
| Llama 4 Scout | Massive Context Window | 10-million tokens | Interleaved iRoPE Attention |
| Llama 4 Maverick | Efficient Multimodal Performance | 17B active parameters | Natively Multimodal MoE |
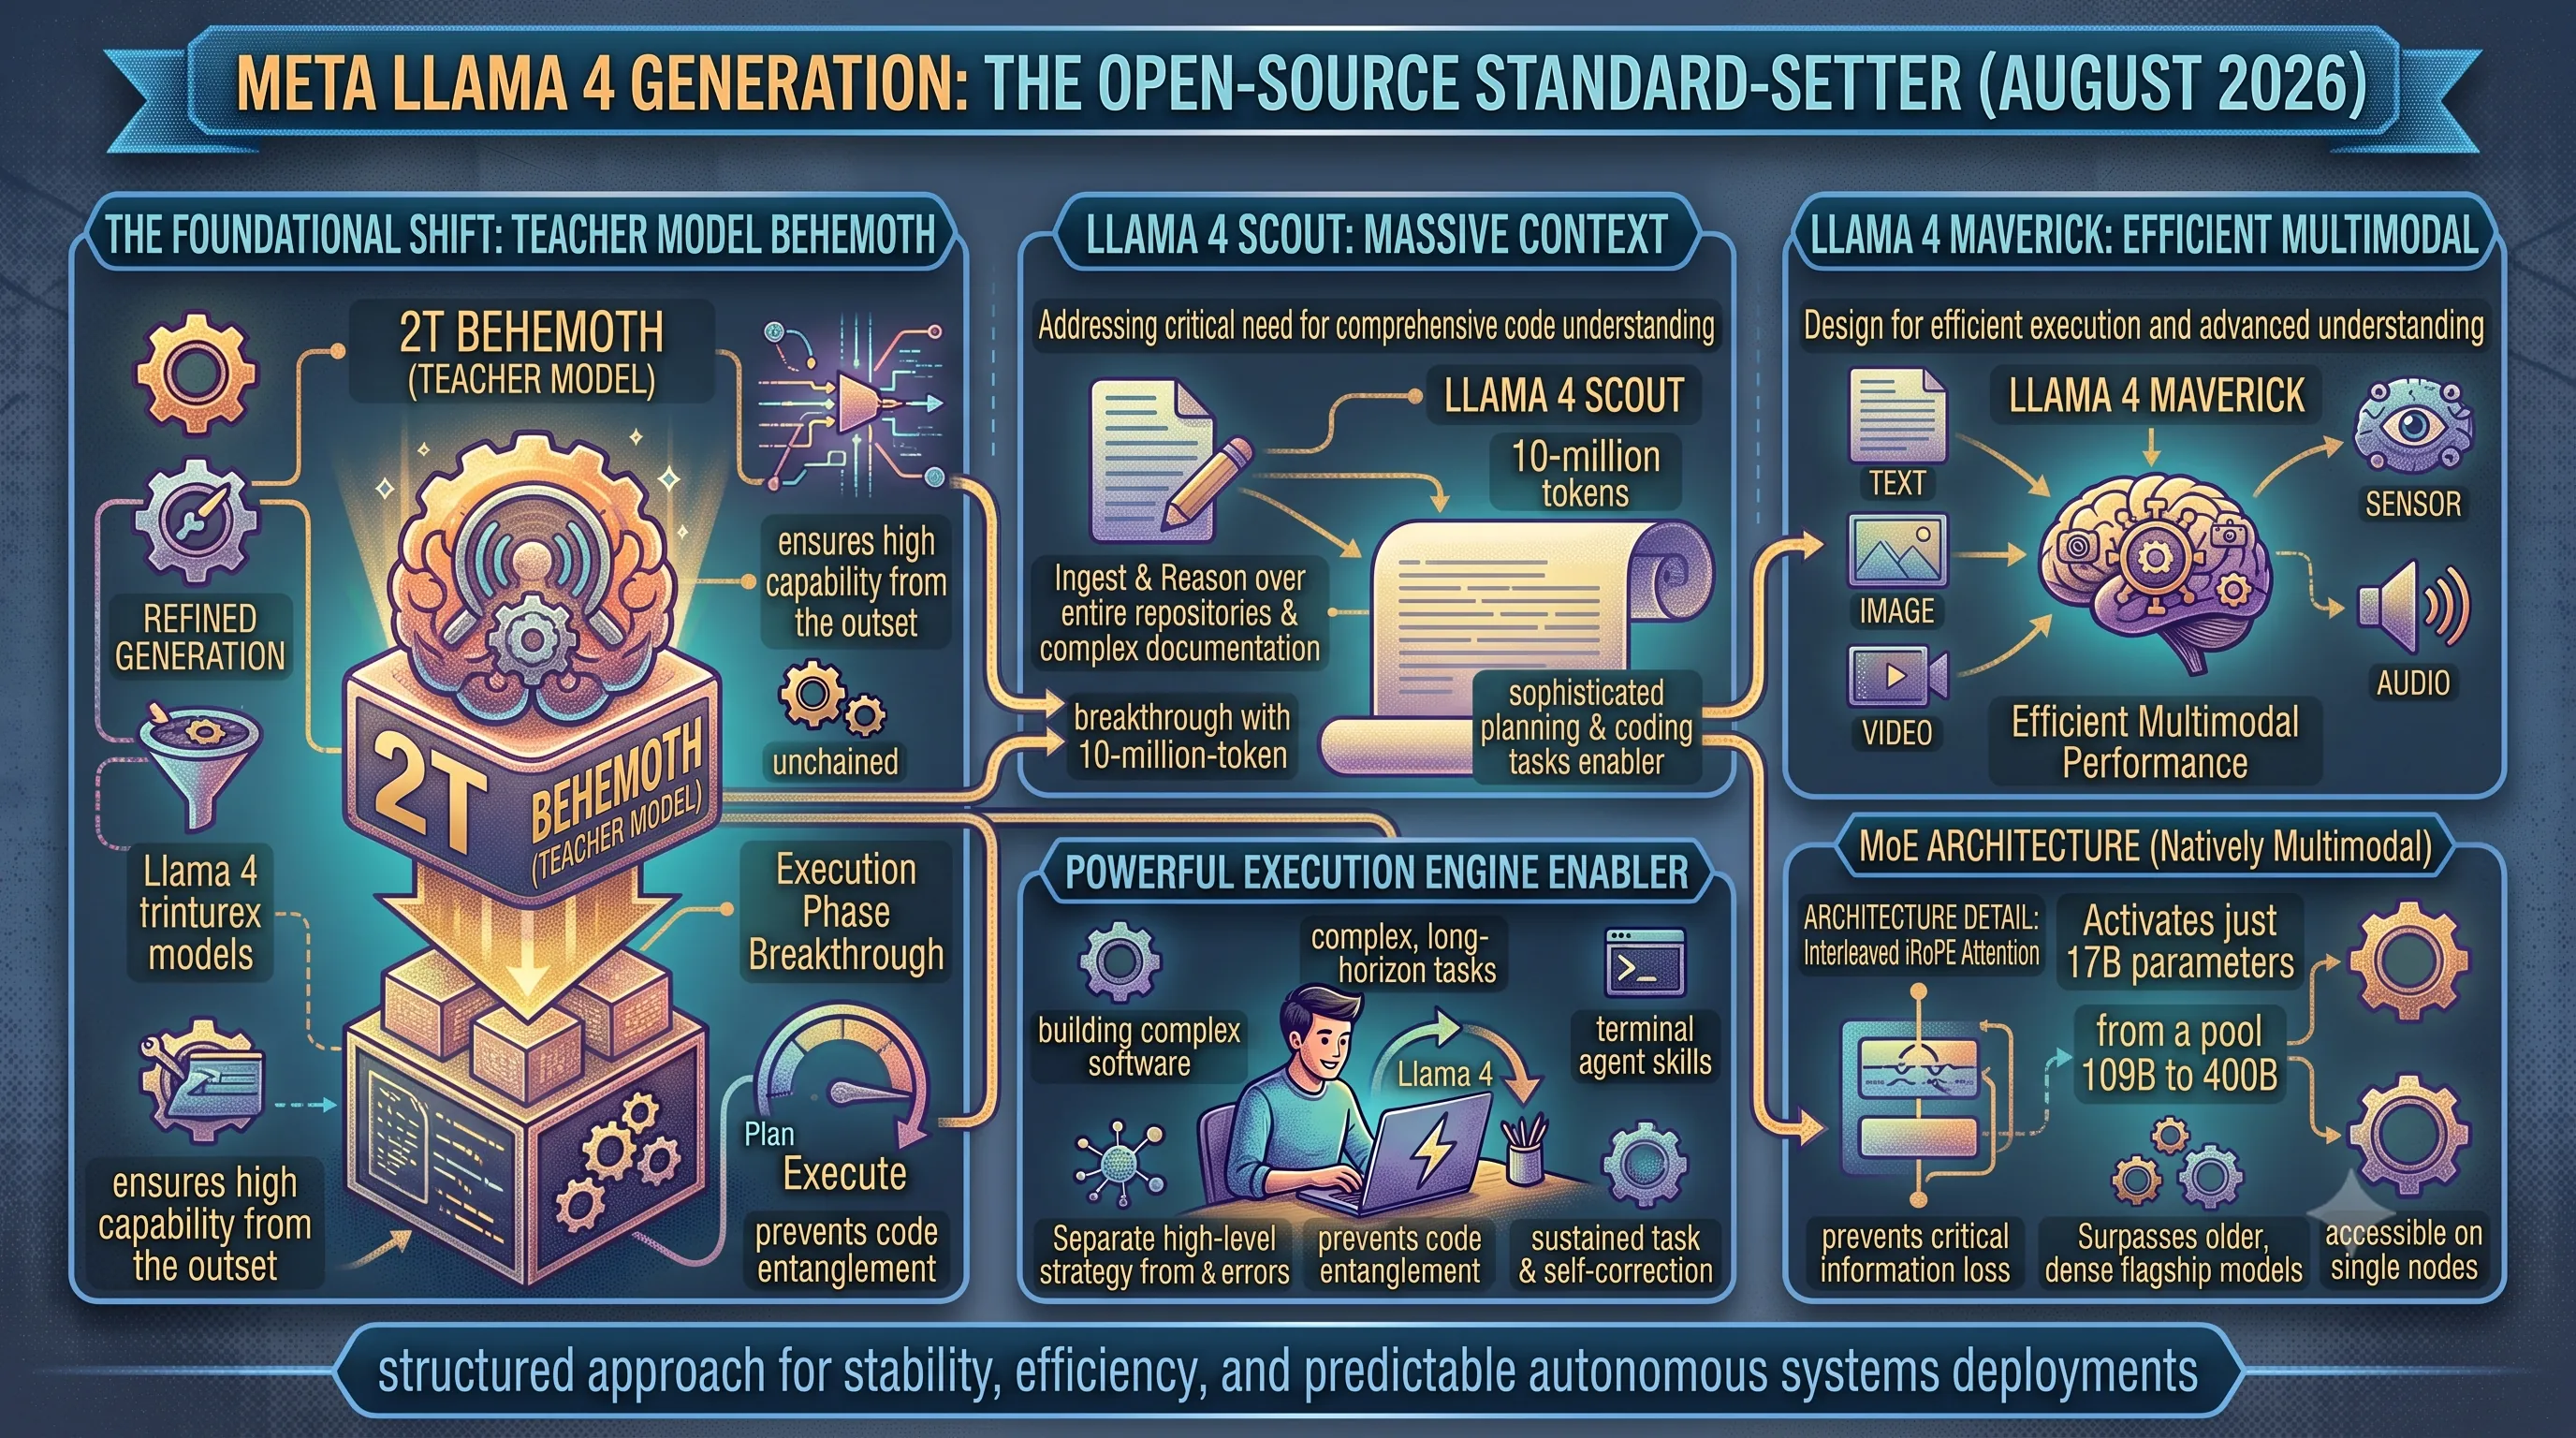
References
- https://local-ai-zone.github.io/blog/ai-updates-august-2026.html
- https://cursor.com/ko/blog/agent-best-practices
- https://jumpcloud.com/it-index/understanding-the-plan-and-execute-ai-agent-framework
- https://medium.com/@alessandro.a.pagliaro/hello-agentic-ai-plan-and-execute-pattern-03ef9dd67b32
- An exploratory study of bug-introducing changes: exploring …
- [2304.05358] An exploratory study of bug-introducing changes: what …
- [2304.05358] An exploratory study of bug-introducing changes: what …
- arXiv:2304.05358v1 [cs.SE] 11 Apr 2023
- Hunting bugs: Towards an automated approach to identifying which …
- What is agentic coding? - IBM
- What is agentic coding? How it works and use cases
- Introduction to agentic coding | Claude by Anthropic
Related Posts
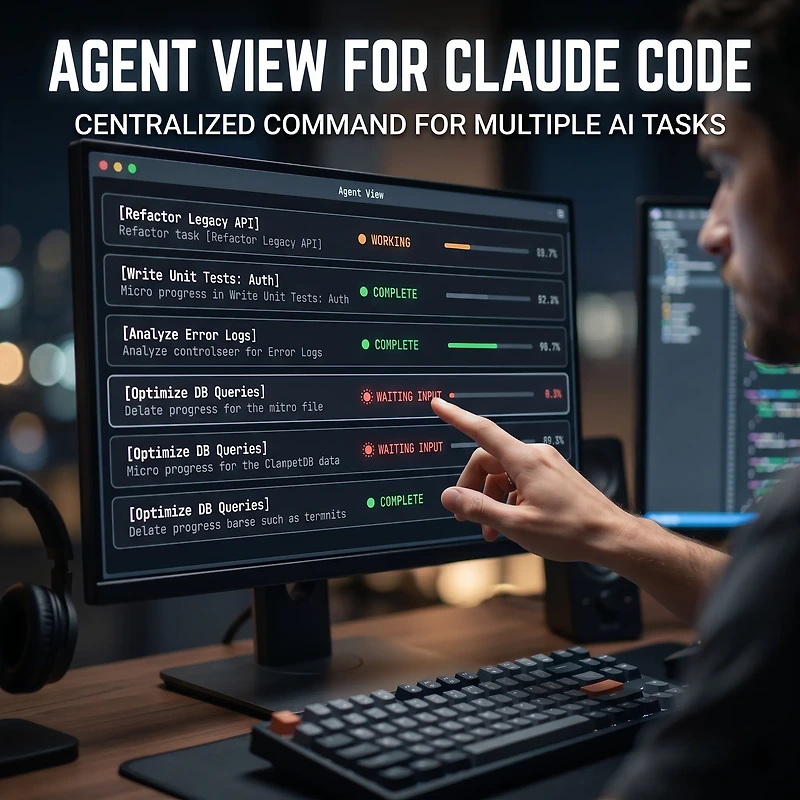
Anthropic's Agent View for Claude Code: Master Multi-AI Agents & Transform Developer ProductivityAnthropic's new 'Agent View' for Claude Code significantly boosts developer productivity by...
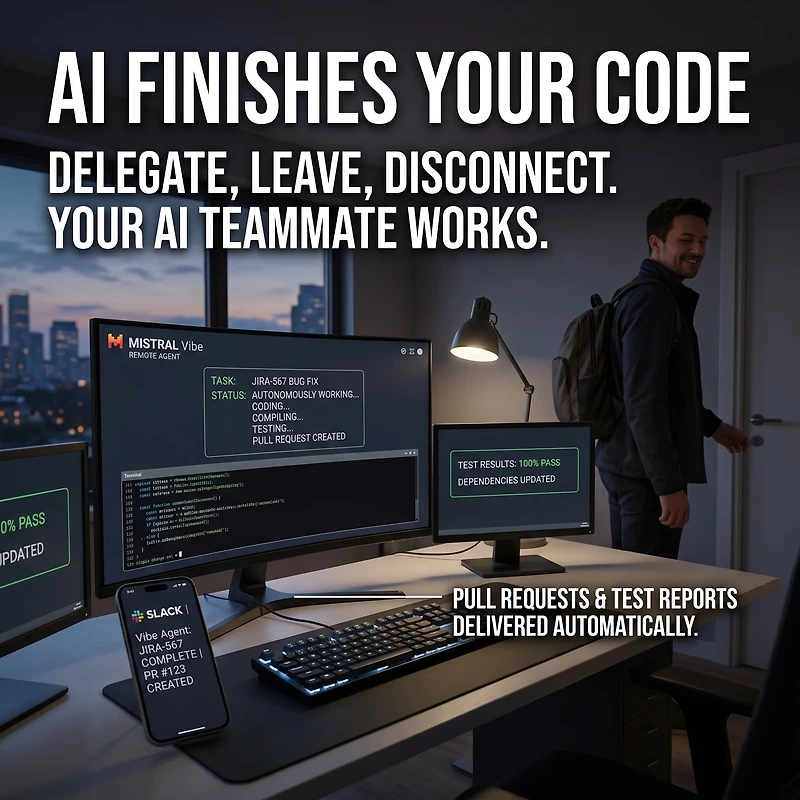
Mistral AI's Autonomous Agents: Code Continues While You Sleep, Reshaping Developer Roles & ProductivityThe advent of advanced AI agents , such as Mistral's Vibe Remote Agents and Le Chat Work Mode , is...
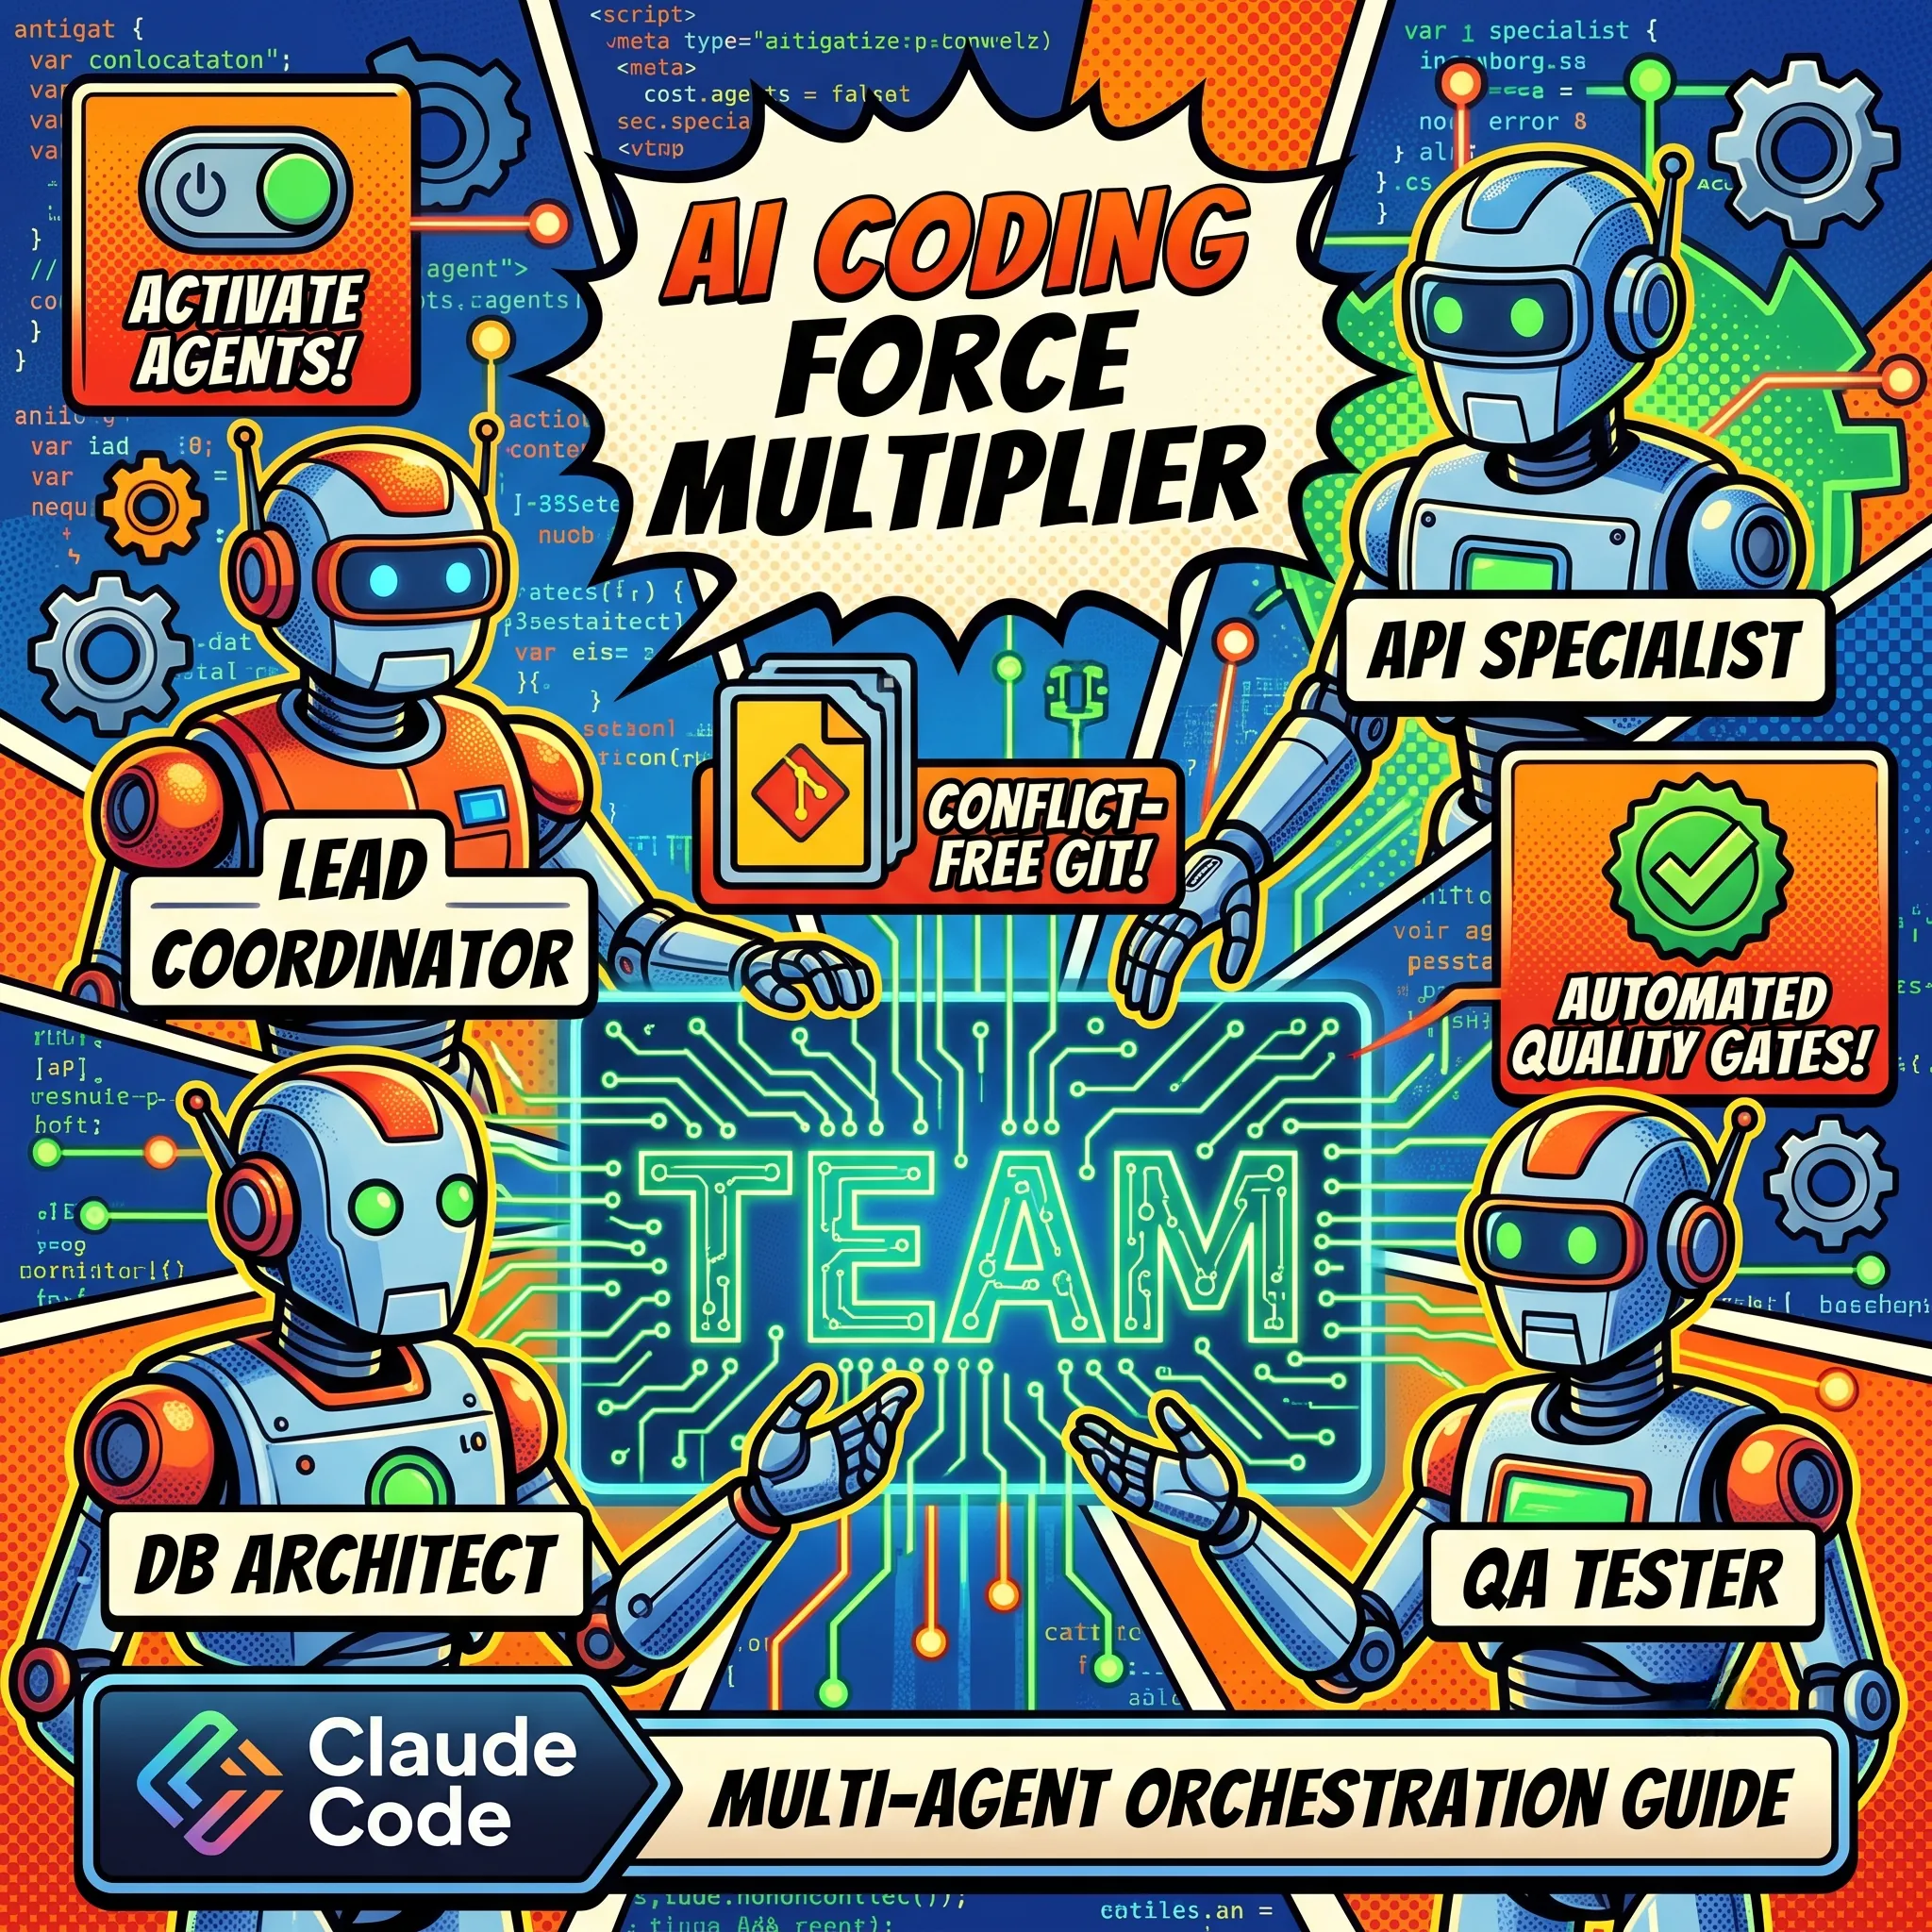
Claude Code Agent Teams: Configuration, Architecture, and Multi-Agent Orchestration GuideLearn how to configure Claude Code Agent Teams for multi-agent software development. Explore...